Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164893 stories
·
33 followers

Why Git Needs Help: Moving from Files to Systems for Source Control

1 Share

The shift to agentic reality

When Git was designed in 2005, Linus Torvalds solved a brilliant problem for humans collaborating over terminal windows by trading line-by-line diffs. Fast-forward to 2026: Autonomous coding agents don’t think in flat text files or line breaks. They reason across syntax trees, execution traces, call graphs, and type constraints. In my view, forcing an AI agent to engineer complex distributed systems through string matching is like handing a chief software architect a chisel and a stack of sticky notes.

File-centric versus system-centric paradigm shift

DimensionLegacy file-centric (Git)Agent-native system graph
RepresentationFlat Unicode text streamsTree-Sitter ASTs & CPG nodes
Mutation unitLine-by-line string diffsAST node transformations
Context overhead2,000+ line prompt context fillsSub-50 token targeted node payloads
State persistenceEphemeral model prompt windowsExecution ledgers & reasoning chains

Whenever I see engineers try to lock context-blind models into file-centric version control, I watch the consequences compound quickly. Context windows fill with irrelevant churn, API bills surge, and subtle, multifile structural breakages slip past basic syntax checks. Just as critically, standard Git discards the cognitive history of a change. The moment an agent session completes, its execution logs, compiler feedback, and discarded hypotheses evaporate into thin air.

Tactical illustration: renaming a distributed method signature

Consider updating a core helper signature across 40 dependent services. A traditional string diff forces the agent to read and mutate thousands of lines of surrounding boilerplate text, burning thousands of context tokens per file:

--- a/services/auth.py
+++ b/services/auth.py
@@ -42,7 +42,7 @@ class AuthManager:
     def validate_session(self, token: str) -> UserSession:
-        return fetch_user_by_token(token)
+        return fetch_user_by_token(token, include_metadata=True)

In contrast, an AST mutation node isolates the target function symbol, executing the change precisely without passing unneeded ambient text through the prompt window:

{
  "action": "mutate_node",
  "target_ast_id": "ast_node_89f2a41b",
  "symbol": "fetch_user_by_token",
  "update": {
    "add_argument": { "name": "include_metadata", "value": true }
  }
}

This exact bottleneck hit Anthropic in late 2026. As autonomous agent activity pushed monorepo merges beyond 30,000 per day, conventional Git infrastructure simply buckled under the load. To me, unlocking genuine agentic autonomy requires evolving source control along two complementary tracks: shifting to server-hosted, graph-aware architectures, and treating agent reasoning as a first-class, versioned artifact right alongside the code itself.

Why text diffs and ephemeral sessions create silent debt

Standard diff tools operate purely on raw Unicode strings. When an agent reorders functions or cleans up formatting, string diffs pollute context windows with noise while remaining blind to structural reality. If you modify a single method signature, Git won’t warn you about the dozen callers broken across separate modules. From my experience, feeding 2,000-line source files into prompts just to update a 5-line helper method degrades model attention, burns compute, and inflates overhead at scale.

Text diffs versus AST graph mutations

Metric / behaviorText diff (unified patch)AST graph mutation
Formatting resilienceBreaks on whitespace or line-ending changesImmune to syntax formatting shifts
Impact analysisPost hoc CI test failuresSub-second static call-graph resolution
Token consumptionO(file_size) per prompt iterationO(node_delta) per targeted change

Compounding this structural blind spot is what I consider our biggest waste: ephemeral session memory. Whenever an agent finishes a task or compacts its context window, its entire diagnostic history—failed attempts, shell outputs, and compiler warnings—disappears. The next agent assigned to the branch steps in completely blind, doomed to repeat the same diagnostic dead ends and burn unnecessary tokens.

Agent-native architectures in practice

In my view, next-generation version control must replace raw file trees with Tree-sitter parsers and code property graphs (CPGs). Instead of editing lines on disk, agents mutate specific syntax nodes directly, executing sub-second edits and running immediate dependency impact checks across the codebase. Moving control back to the server eliminates the massive I/O bottlenecks caused by checking out heavy working trees onto virtual machines, allowing agents to query and update code over fast graph end points.

Practical implementation: server-side microdiff stream

Below is an example payload representing an atomic microdiff layer executed directly on a server-hosted code property graph, bypassing local file checkouts entirely:

{
  "commit_id": "c_9011f4a2",
  "parent_graph_version": "v14.2.0",
  "operations": [
    {
      "op": "replace_node_property",
      "node_uri": "cpg://auth_service/ast/Node_441",
      "property": "return_type",
      "value": "Promise<UserSession>"
    }
  ],
  "validation_hash": 
  "sha256_e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855"
}

This structural shift pairs naturally with stacked microdiffs—atomic, dependent layers verified sequentially in isolated virtual workspaces to prevent merge races. I was particularly impressed seeing the real-world impact of this pattern with Anthropic’s Scion architecture. Faced with object-store locks and clone latencies as daily merges scaled 10x, Anthropic built a server-centric SCM that streams code graphs on demand, slashing infrastructure overhead by 200x while enabling near-instant workspace initialization.

Versioning reasoning and system memory

I strongly believe code changes alone rarely capture full intent. Modern SCM must link model reasoning traces, prompt chains, and decision graphs directly to commit nodes, preserving architectural context for future debugging and audits. Persisting build outputs, compiler logs, and linter runs in execution ledgers attached to commit trees allows subsequent agents to inspect prior test results instantly rather than rerunning identical test suites.

System memory schema: reasoning and execution ledger

To prevent model sessions from repeating diagnostic dead ends, execution ledgers append structured reasoning and compiler feedback directly to commit nodes:

{
  "agent_session_id": "sess_88190c2a",
  "target_commit": "c_9011f4a2",
  "hypothesis_tree": {
    "attempt_1": { "approach": "In-memory caching", "status": "REJECTED", 
    "reason": "Memory limit exceeded in integration test" },
    "attempt_2": { "approach": "Redis backing store", "status": 
    "VERIFIED", "execution_time_ms": 142 }
  },
  "compiler_ledger": {
    "linter_passed": true,
    "type_check_errors": 0
  }
}

By explicitly recording abandoned branches and failed architectural hypotheses as structured metadata, we stop future agent sessions from reexploring invalid paths. I argue that capturing thought streams alongside code transforms source control from a passive text archive into an active memory system.

The hard engineering trade-offs and counterarguments

I won’t pretend making this transition is easy; it comes with steep engineering trade-offs. Existing developer tooling, from LSPs to build pipelines and IDEs, expects standard local file trees. Replacing checkouts with server-hosted graphs requires building heavy compatibility layers or redesigning workflows. Furthermore, human reviewers still digest code line by line, creating a natural tension with pure graph mutations, while storing continuous thought streams drives up storage and compliance costs. During early refactoring, syntax is often broken and unparseable, forcing systems to temporarily fall back to raw text. Overcoming Git’s decades of deep ecosystem lock-in remains a major operational hurdle we cannot ignore.

Trade-off matrix: architectural migration challenges

ChallengeSystemic bottleneckMitigation strategy
IDE & tooling lock-inLSPs expect local file system layoutsVirtual FUSE layers streaming AST nodes on demand
Storage overheadPersisting continuous reasoning logs increases storage 10xCompacting execution ledgers into summary trees
Broken syntax statesAST parsers fail during active multiline refactoringFallback to temporary text buffer zones during edits

Bottom line

Git was designed for humans reviewing text, but agentic scale demands server-centric, graph-aware source control. Code property graphs stop token bloat and prevent silent structural breakages. Versioning reasoning traces and execution histories alongside code keeps agents from repeating past mistakes. And stacked microdiffs offer a clean, isolated path for autonomous agents to ship code safely at scale.


Read the whole story
alvinashcraft
17 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Beyond 12 Columns: Designing Layouts With Personality

1 Share

Too many websites look alike. They use familiar layouts, repeat the same patterns, and often leave little impression once you’ve moved on. Andy Clarke explores how understanding a company’s story can lead to more distinctive designs, using modular and compound grids to create layouts with character.


Beyond 12 Columns: Designing Layouts With Personality originally handwritten and published with love on CSS-Tricks. You should really get the newsletter as well.

Read the whole story
alvinashcraft
35 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

CNCF Recognizes Cloud Native Champions in 2026 Community Awards

1 Share

Annual awards honor leaders, maintainers, and documentarians building open source infrastructure

Key Highlights

  • CNCF recognized 11 contributors across four Community Awards at KubeCon + CloudNativeCon North America in Salt Lake City, with winners honored at the November 12 ceremony.
  • Lifetime Achievement honorees Julius Volz, co-creator of Prometheus, and Rita Zhang, chair of Kubernetes SIG Auth, spent over a decade building the observability and security foundations the community relies on to meet two of its biggest challenges in the age of AI.
  • Top Committer Antonio Ojea advanced Kubernetes networking and testing, from IPv6 dual-stack support to DRANET, which extends Dynamic Resource Allocation to network resources.
  • From Istio release engineering and core Kubernetes controllers to documentation for Kubernetes, HAMi, Cilium, and eBPF, this year’s winners highlight the behind-the-scenes work that keeps projects dependable as organizations scale AI and cloud native workloads.

KUBECON + CLOUDNATIVECON NORTH AMERICA, SALT LAKE CITY – November 12, 2026 – The Cloud Native Computing Foundation® (CNCF®), which builds sustainable ecosystems for cloud native software, today announced the winners of the CNCF Community Awards at the annual KubeCon + CloudNativeCon North America.

Since 2016, the CNCF Community Awards celebrate key contributors across CNCF projects and Technical Advisory Groups (TAGs). These awards honor leaders committed to the cloud native ecosystem, maintainers dedicated to the vitality of their projects, documentarians who enhance usability, and behind-the-scenes contributors essential to our community. Winners were recognized and received their trophies during the event’s award ceremony.

“This year’s award recipients show what it takes to keep this community running year after year,” said Chris Aniszczyk, CTO, CNCF. “From maintaining critical infrastructure, security updates, to writing the docs that make projects usable, to showing up for their local communities, these contributors do the gritty work that keeps our projects dependable. Thank you to every winner for the care they bring to the community.”

Lifetime Achievement Award

The Lifetime Achievement Award is presented to longtime contributors who have significantly influenced cloud native technologies and demonstrated sustained commitment to the ecosystem. This award honors individuals whose efforts over the past decade have been instrumental in shaping and supporting the Kubernetes and CNCF communities. This year’s recipients built tools the community relies on to meet two of its biggest challenges in the age of AI: seeing what’s running in production, and securing and governing it.

This event’s recipients are:

“The Lifetime Achievement Award honors the people whose sustained work keeps this community strong and moving forward,” said Jonathan Bryce, CNCF Executive Director. “Julius Volz and Rita Zhang spent over a decade building the observability and security infrastructure this community depends on every day. From Prometheus to Kubernetes security tooling, their work ensures the enduring health of the entire cloud native community for years to come.”

Top Committer Award

The Top Committer Award, also known as the Top Cloud Native Committer Award, recognizes an individual for incredible technical skills and notable achievements across one or more CNCF projects as a maintainer. This accolade highlights sustained, collaborative development that benefits CNCF-hosted projects as a whole. The award honors those who demonstrate deep technical impact whose work reflects dedicated contributions essential for the ongoing vitality of the cloud native ecosystem. This year’s winner has advanced Kubernetes networking and testing, from IPv6 dual-stack support and the KIND testing infrastructure to DRANET, which extends Dynamic Resource Allocation, Kubernetes’ way of assigning specialized hardware, to network resources.

This event’s winner is:

Chop Wood Carry Water Award

The Chop Wood Carry Water Award recognizes the essential, behind-the-scenes community work that keeps the cloud native ecosystem healthy and long-lived. This accolade honors contributors who spend countless hours completing often mundane but critical tasks, such as supporting documentation, organizing meetups, and maintaining project infrastructure. This year’s winners include contributors who manage Istio releases and infrastructure, maintain core Kubernetes controllers, and lead community mentorship across projects.

This event’s winners are:

Lorem Ipsum 

The Lorem Ipsum award, previously known as the Top Documentarian award, recognizes excellence in documentation contributions made to the CNCF and its hosted projects. Recipients are honored for their efforts to enhance usability and inclusion across CNCF projects. This year’s winners maintain and improve documentation for Kubernetes, HAMi, Cilium, and the eBPF ecosystem.

This event’s winners are:

CNCF encourages the community to participate in ongoing initiatives that strengthen the cloud native ecosystem. Technologists are invited to join the CNCF End User Community to collaborate with peers and contribute to the influential group of organizations harnessing cloud native architectures to solve real-world problems. 

Check the CNCF calendar for details on local events and register for KubeCon + CloudNativeCon Europe.

About Cloud Native Computing Foundation

Cloud native computing empowers organizations to build and run scalable applications with an open source software stack in public, private, and hybrid clouds. The Cloud Native Computing Foundation (CNCF) hosts critical components of the global technology infrastructure, including Kubernetes, Prometheus, and Envoy. CNCF brings together the industry’s top developers, end users, and vendors and runs the largest open source developer conferences in the world. Supported by nearly 800 members, including the world’s largest cloud computing and software companies, as well as over 200 innovative startups, CNCF is part of the nonprofit Linux Foundation. For more information, please visit www.cncf.io.

Media Contact

The Linux Foundation

pr@cncf.io

Read the whole story
alvinashcraft
44 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Should You Actually Add AI To That? A Four-Question Audit For Product Teams

1 Share

A product team at a large health insurer wants to add AI that writes the full written determination for benefits appeals specialists. The technology works as specified. However, the specialists stop using it, and the ones who keep using it take longer on each case than the ones who ignore it.

A short evaluation with the specialists surfaces the problem fast: reading an AI-written determination carefully enough to sign it takes about as long as writing one, and the specialist also has to check for mistakes they would never have made themselves. The feature adds work to a task these people had already mastered.

Rescoping the release fixes it. A second version surfaces the policy provisions and prior decisions relevant to each appeal and leaves the writing to the specialist. The search step disappears, review time drops, and the part of the job the specialist is good at stays where it was.

The technology is identical in both versions, and the difference is which part of the task the AI handles.

Finding The Break-even Line

Every interface change costs the user something before it pays anything back. They have to rebuild their picture of how the tool works, learn where things are now, and decide how far to trust what the AI hands them. Nelson Cowan’s review of working memory research (2001) put the limit at about four items held in mind at once. All three of those jobs draw on the same small supply.

An AI feature in an enterprise software setting requires more from the user than a redesigned menu, because it changes what they do all day. Hand the synthesis to an AI and the user becomes a checker. Give it the recommendation too, and the job shrinks to signing off. Either change costs user attention, and for people whose training is their standing at work, either one can feel like a demotion. For example, in one study, Sophia Ackerhans (2025) and colleagues found that physicians asked to sign AI-assisted decisions reported a more serious threat to their professional identity, and explanations of the AI’s reasoning raised both trust and that threat together.

An AI feature earns its place when what it returns beats what it costs the user to adjust, for one user doing one task.

We can call that the break-even line. Returns to users come in three forms:

  • Effort the feature removes,
  • Errors it catches that the person would have missed, and
  • Consistency across people doing the same work.

For example, an AI-powered fraud screening tool shows the errors-caught form at work, since the analyst reviews flags they would never have raised themselves, which costs attention, and the catch rate pays for it. That puts the feature above the break-even line.
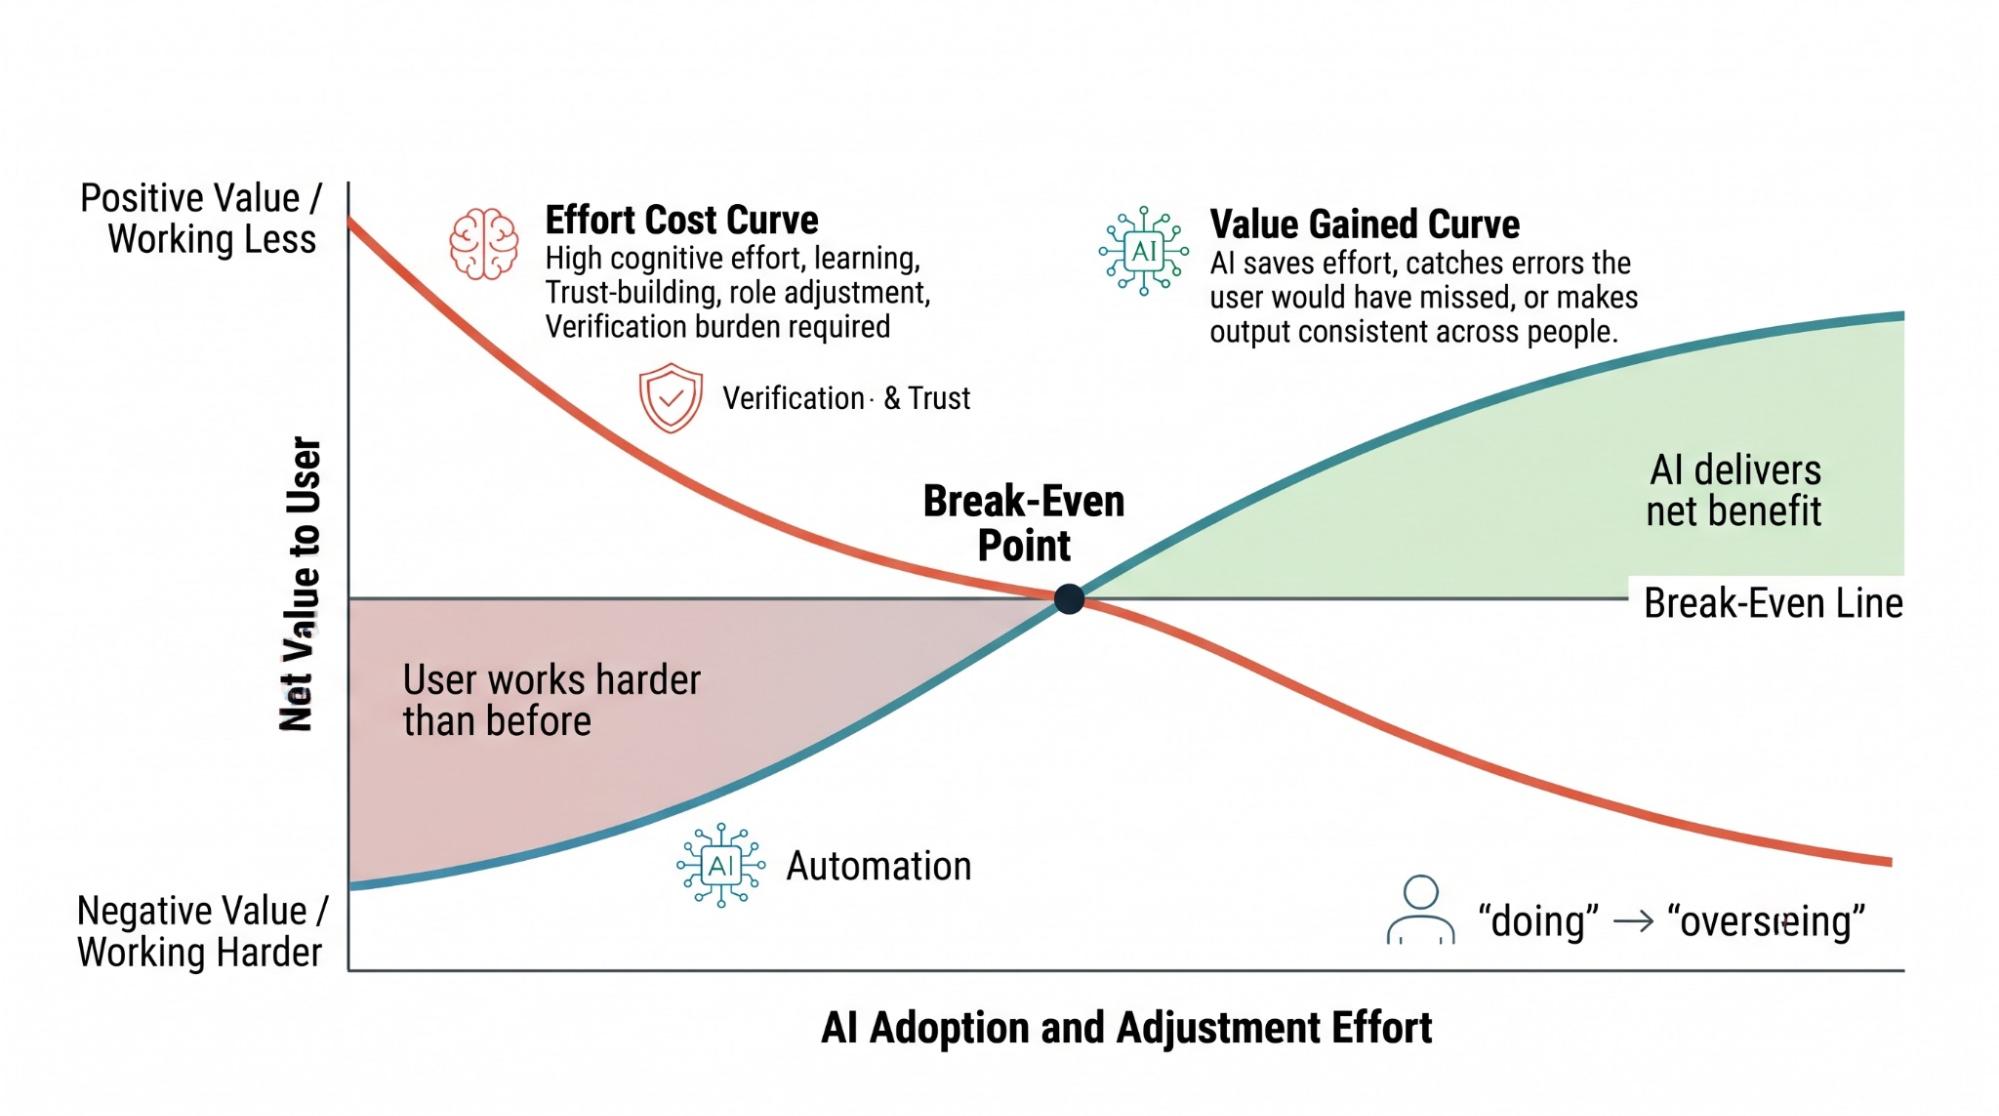
Four questions can help your team locate the break-even line before design work starts. Each one produces a design condition the brief can act on.

These questions do not replace the build decision. Funding, strategy, and existing commitments all weigh on that, and four questions cannot see any of it.

Run through all four questions together, since no single question settles the issue alone. Do it while the feature is still a proposal, before anyone sinks weeks into design. You will also need at least one person who does the task for a living, such as a loan officer, analyst, or benefits specialist. They do not have to sit in the roadmap meeting, and a short conversation tells you where the mental effort actually sits and whether the feature would help or add work.

Question 1: Does This Reduce The Total Effort The Task Takes For This User?

Count everything the task asks of the user: the thinking, the clicking, and the checking they will owe once AI is involved. Fewer clicks proves nothing on its own, because a feature can cut clicks and still leave the person working harder. Write down the cost even when it goes up, since Question 2 may find a return that pays for it.

A loan officer reading 40 financial disclosures to find the three that conflict with lending policy is thinking hard, and AI that surfaces those conflicts cuts that demand directly. Compare that with typing a loan number into a tracking system, which costs a few seconds and almost no thought. Pre-filling that field relocates the cost instead of removing it, because the officer now checks what the machine entered. Conventional wisdom says to automate the repetitive and monotonous tasks, and the pre-filled field is where that advice misfires. In this example:

  • When AI fills in a field, the user takes on checking it.
  • The original task requires a short keystroke sequence and no sustained attention.
  • The automation trades a low-effort action for a high-attention one.

You can find the tasks worth automating by comparing total effort before and after. Count the checking the user inherits on the after side.

Who the user is matters as much as what the task is. One feature can clear the line for a junior analyst and fall short for a senior one. Hand a junior analyst an AI-drafted risk summary, and they gain a starting point they lack the pattern library to produce on their own. A senior analyst, however, reads that same summary against the analysis already formed in their head, spends four minutes doing it, and learns nothing.

A finding like that tells you who to ship to. Scope the addition to the group it serves.

Design condition: Name the user segment the addition serves, and design an exit for the other segments.

Question 2: Does This Beat The Way The User Does The Task Now?

Compare the AI approach against the user’s current method, including the spreadsheets and workarounds they built for themselves. Genuine ambiguity is one reason AI comes out ahead when someone explores options, produces a starting point, or looks for patterns too numerous to spot by hand. Scale, speed, and consistency across a group of people doing the same job are three more. A fourth is catching what the current method reliably misses, which is how the fraud screening tool earns its place. The advantage disappears once the user has a practiced route to a known answer.

For example, an HR team building a succession planning tool finds the answer running both ways inside one product. Using AI to surface internal candidates whose skill combinations nobody would think to search for wins on ambiguity and scale together, since no single right answer exists and manual review of that search space would take weeks. Drafting the notification email after someone picks a candidate loses to the method already in place. The format is familiar, the writing takes two minutes, and the person sending it holds firm opinions about tone. The candidate search earns the addition. The email draft layers an interaction onto a task that runs fine without one.

The nature of the input and the shape of the output are separate decisions. A task can hold genuine ambiguity and still call for a structured visual result instead of a conversational one. Pair this audit with a modality evaluation for the output side.

Design condition: Remove AI from any step where the user’s current method already reaches the answer quickly and reliably.

Question 3: Can The User Catch The Errors?

Every AI system makes mistakes. The question is whether your user will notice. Start with how visible the error is. Then weigh what it costs when nobody catches it, and whether the user still has the skill to catch it. Question 1 asks what checking costs. This one asks whether checking is even possible.

Error visibility varies enormously, and product teams tend to estimate it badly. For example, an AI trip planner that suggests a museum on the day it closes produces an invisible error, because nothing in the output looks wrong. The traveler finds out while standing outside a locked door in Tokyo. Compare that with a suggested flight that departs before the connecting flight lands, where the contradiction sits right there on the screen.

Automation bias makes the invisible cases worse. Raja Parasuraman and Dietrich Manzey (2010) reviewed decades of human factors research showing that people defer to automated output even when that output is wrong, across aviation, medicine, and process control. Trust climbs fast, and rarely as a conscious decision. Once it does, users stop applying the scrutiny that would catch the mistake.

Map the error surface, meaning the ways this feature can be wrong, before design work starts. List the three likeliest error types. Rate each one on visibility to the user and consequence if it slips through. Any combination of low visibility and high consequence becomes a design requirement.

Show users where the output came from and how the system produced it. That is provenance, and it is what lets trust settle at the right level. People who can see the source, the data behind it, and when it was pulled catch errors more often. Tell the traveler that a restaurant’s hours came from a page cached in March and they know what to check. A confident-sounding paragraph with no source attached leaves them guessing.

Design condition: Any addition with a high-consequence, low-visibility error surface ships with provenance display and verification prompts, or it does not ship.

Question 4: After A Year Of Using This, Can The User Still Tell When The AI Is Wrong?

Letting the routine work go is a real benefit of adding AI. Nobody needs to protect a specialist’s ability to format a citation or an analyst’s ability to total a column by hand, and arguing to preserve skills the technology has absorbed wastes everyone’s time.

Still, the judgment that catches the machine’s mistakes stays exempt from replacement. That judgment makes every other delegation safe, and disuse degrades it like any other skill.

Research in radiology shows how fast a suggestion can override a reader’s own judgment. In a 2023 experiment, Thomas Dratsch and colleagues had 27 radiologists read mammograms alongside what they were told was an AI system (a simulation created solely for the experiment). The radiologists worked through a 10-image training set where the suggested category was always correct, then 40 more mammograms with incorrect suggestions planted in 12 of them. The result showed how incorrect AI suggestions damaged diagnostic accuracy at every experience level. The most experienced readers, averaging 15 years, assigned the correct category 82.3% of the time when the suggestion was right and 45.5% of the time when it was wrong, while the least experienced group fell from 79.7% to 19.8%. Experience softened the effect without preventing it. A year of deferring to the same system, with the judgment it replaced sitting unused, leaves a reader in a weaker position than the one these radiologists started from.

Question 3 looks at your user today. Extend the same test 12 months forward and you arrive at Question 4. Teams that answer the first and skip the second read the resulting failures as a quality problem in the model, when the cause is the human judgment they took out of daily use.

Ask whether this user could judge the quality of the output 12 months from now if the feature vanished tomorrow. When the answer is no, the design needs a mechanism that keeps verification skill in use. Periodic blind review works well and costs little, with the user forming a judgment before seeing what the AI produced. Rotating a share of cases off AI assistance does a similar job, as does a weekly comparison between machine output and a human-produced version.

Design condition: Name the mechanism that keeps verification skill in use, and build it into the workflow itself. A slide in the training deck will not do it.
A decision Matrix

Table 1 below gathers the four questions, the signals pointing each way, and the condition each one produces.

Audit question AI earns its place when… AI costs the user when… Design condition
Does this reduce the total effort the task takes for this user? The task demands synthesis across large or varied inputs, and judgment calls create the bottleneck The task follows a known procedure with a fast manual path, or verification costs as much as the original work Name the segment served, and give other segments an exit
Does this beat the way the user does the task now? The AI approach wins on ambiguity, scale, speed, consistency, or catch rate against the method the user has now The user’s current method already reaches the answer quickly and reliably Remove AI from steps the current method already handles well
Can the user catch the errors? Errors appear on their face, stakes stay low, correction is cheap Errors stay subtle, stakes run high, or verification needs the skill being delegated Provenance display and verification prompts, or no build
After a year, can the user still tell when the AI is wrong? AI absorbs volume while the user keeps making the judgment calls AI absorbs the judgment calls with no feedback on quality A named mechanism that keeps verification skill in use

Table 1: The AI Addition Decision Matrix. Clear answers across all four questions point toward building the feature as proposed. A poor answer on Question 1 calls for a design condition or a change in scope, unless Question 2 finds a return that covers the cost. Questions 2 and 4 work the same way without that exception. A poor answer on Question 3 can stop the build.

Put the conditions in the design brief, where they become project requirements. Teams reduce AI features to yes or no because roadmap reviews demand it, and that throws away everything the audit found. A feature that answers well on Questions 1 and 2 and poorly on Question 3 proceeds only with provenance built in. Write that in on day one. Requirements that arrive at the end read as polish, and teams cut polish when timelines slip.

Running The Audit On The Appeals Scenario

Let’s return to the insurer scenario from our opening. The first version of the tool fails Question 1. Writing a determination takes sustained thought, and the AI that produces the draft moves that effort into verification without reducing the total. An hour with the four questions would surface that before the first version reaches design.

Question 2 points in the same direction. Appeals determinations follow a familiar structure, and specialists reach the answer through a practiced route. The ambiguity in the task sits earlier, in finding which provisions and prior decisions apply.

Question 3 raises the stakes. A wrong determination affects someone’s medical coverage, and an error buried in fluent prose stays invisible until the next appeal arrives. That answer produces the provenance requirement in the second version, which cites the source document and retrieval date for every provision it surfaces.

Question 4 explains why the second version holds up. Specialists still write every determination, so the judgment that evaluates the retrieved material stays in daily use. Keeping version one would train specialists for a year to approve text they no longer have the practice to assess.

The Same Audit On Meeting Summaries

AI-generated meeting summaries sit inside products that millions of people open every day, and the audit reaches a different answer for them.

On Question 1, a summary removes the work of writing notes and adds the work of checking whether it attributed a decision to the right person. Total effort drops for the participant who never took notes. For the person who always took the notes and circulated them, the trade is closer, and the verification lands on them. That split is exactly what Question 1 is built to surface.

Question 2 compares the summary against someone typing while half-listening, which produces patchy notes. A summary beats that on completeness and on consistency from meeting to meeting, so the feature clears this question for most teams.

A summary that assigns a commitment to the wrong person looks exactly like a correct one, and nobody rereads the transcript to check. On Question 3, low visibility and real consequence together turn into a requirement for a linked source timestamp behind every action item.

The feature clears Question 4, and the design needs no mechanism. Nobody loses a skill worth protecting by giving up meeting notes, and the participants keep making every decision the summary records.

Two clear answers, one segment finding, and one condition. The timestamps ship with the feature, and the habitual note-taker is the segment the team checks after launch.

The 60-minute Version Of The Audit

You can run this before the next AI feature reaches your roadmap.

  • State the task specifically (10 minutes). Write it at the level of one user in one sitting. For example, help a mid-level financial analyst find the three highest-risk items in a 40-page due diligence report inside a two-hour review window. A task described as helping users summarize documents is too loose to evaluate.
  • Answer the questions with someone who does the work (25 minutes). Their read on where the effort actually sits beats any product team estimate. Ask which parts of the task they find hard, listen for whether the proposed feature touches those parts, and ask what they would lose the ability to check if the feature made the judgment calls for a year.
  • Map the error surface (15 minutes). Identify the three likeliest error types, each rated on visibility and consequence. Low visibility plus high consequence becomes a build requirement. For instance, a medical diagnostic tool suggesting a treatment plan with a high mortality rate if incorrect requires strict provenance and verification triggers, while a scheduling assistant proposing the wrong meeting time is easier to spot and repair.
  • Write the conditions into the brief (10 minutes). Provenance display, verification prompts, segment scoping, and skill mechanisms belong in the brief that goes to design, in the same document as the feature description.

Everett Rogers (2003) called this pro-innovation bias, the assumption that new capability means progress before anyone verifies the benefit, and competitive pressure turns a rival’s announcement into an internal mandate. An hour of structured questions gives your team a way to answer that pressure.

Bringing The Results Into The Room

Audit results land badly when a designer presents them as reasons the feature should not exist. The conditions are the useful output, so bring those into the product review.

Start by naming the segment the feature serves, which makes the answer a yes for someone. Hand over the error surface as a requirement with a cost attached. A product manager can act on a request for timestamps behind every attributed decision, and nobody can act on a worry that users might not trust the output. Then offer the change in scope without waiting to be asked. A version that surfaces the provisions instead of writing the determination is a smaller build with a better adoption story, and that framing moves a roadmap conversation forward.

A sentence that works out loud: We think this clears the bar for junior analysts and adds a verification step for senior analysts, so we would scope it to onboarding and revisit the rest next quarter.

The attention a person can spend in a working day stays fixed no matter how good your model gets. Before the next feature reaches design, write down what it will cost the person doing the work and which of the three returns pays for it. With both answers in hand, your team can walk into the roadmap review with a scope to propose.

References


Read the whole story
alvinashcraft
50 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

See what AI looks like in production at Microsoft Ignite

1 Share

If you’re deciding which AI pilots to move into production, Microsoft’s Satya Nadella and Judson Althoff’s opening keynote at Microsoft Ignite will show you where the company is taking the tools you’ll use to build and run those agents. They take the stage at 10 a.m. Pacific on Tuesday, November 17. 

After the opening keynote, you can experience how customers put AI into production at scale, see where Microsoft is taking the tools those customers use, and compare notes with industry colleagues already doing the work. The breakout sessions (and hallway networking) offer the opportunity to double-click into results after an actual deployment. 

With the rapid advancement of AI tools and resources, the best playbook is often the one your peers have already tested. Microsoft Ignite gives leaders a place to compare deployment strategies and lessons learned face to face, with organizations just getting started and others already getting results from AI in production. 

Microsoft tells The New Stack that over four days, more than 100 organizations will take the stage across keynotes, breakout sessions and theater stages.

Microsoft tells The New Stack that over four days, more than 100 organizations will take the stage across keynotes, breakout sessions and theater stages. The organizations span AI startups such as Replit and Harvey, financial firms including Morgan Stanley and BNY, and companies such as Toyota and Siemens. If you’re choosing a first project (or deciding which pilot deserves more budget), the range at Ignite should give you a chance to gauge how teams with different goals are making those same decisions you’re facing. 

How Microsoft AI solutions work together 

Microsoft calls its approach Frontier Transformation. It starts with what people want to accomplish, the information AI agents need to help them, and finally, the controls an organization needs once AI is in use.  

For employees, Microsoft 365 Copilot puts AI into tools they already use, including Teams and Word. Microsoft Fabric brings business data and analytics together, and Microsoft IQ gives Copilot and agents context, pulling from in-house data, workplace activity, documents, and the web. Developers can use GitHub and GitHub Copilot to write and review code, then use Microsoft Foundry to build, test, and deploy agents on Azure infrastructure. Finally, Agent 365 gives IT teams a place to see which agents are running, monitor their activity, and set policies. 

Customer stories will also be a big part of each of the four innovation sessions. 

Where should your AI actually run? Mark Russinovich and Pavan Davuluri will lead “AI Infrastructure From Cloud to Edge,” with examples of Microsoft using its own tech as “Customer Zero” (what Microsoft calls its high-stakes version of dogfooding). PricewaterhouseCoopers will appear in person, and OpenAI, Adobe, and Replit will share featured videos in this session. If you’re deciding what to run in Azure vs. closer to users, this session will offer the insight you need. 

Microsoft reports that more than 40,000 people at Lilly use Copilot

How do you get people using agents in their everyday work? Lilly’s Bryce Williams is scheduled to join Microsoft’s Jacob Andreou in person for “Expanding What’s Possible: How AI Is Redesigning Work.” Microsoft reports that more than 40,000 people at Lilly use Copilot, and that more than 150 agents support work across research, clinical trials, and operations. If your team is rolling out Copilot, Lilly will showcase what helped its teams adopt it at scale.  

How do you ensure your agents are working from the right information? In “Harnessing Your IQ With a Continuously Improving Agent Platform,” Arun Ulag and Jay Parikh will look at how agents use company data and knowledge, with planned spotlights on AEMO and NTT Data. You’ll hear how teams decide what an agent should be able to see and how they test whether it’s drawing on the right information. 

How will you know your agents are working once they’re rolled out? Charles Lamanna and Hayete Gallot will lead “Observability at Every Layer for Every Role,” with planned videos from Royal Philips and KPMG, plus an onstage interview with the Bank of England. The Bank says nearly all of its employees use Microsoft 365 Copilot each week. Some agents that started as experiments are now in wider use, including one that answers staff questions about leave and pay. If you’re curious how to tell when an agentic system is trusted and ready for prime time, you’ll find out here. 

If you’re curious how to tell when an agentic system is trusted and ready for prime time, you’ll find out here. 

Between sessions, you can explore demonstrations in Moscone South, where planned customer installations include Alaska Airlines, Unilever, and more, with technical experts on hand. Theater sessions and lightning talks will also offer more time for questions. 

There’s also a reason to step outside onto Howard Street between Third and Fourth streets, where plans include NFL and Premier League installations and a Mercedes-AMG PETRONAS Formula One car display.  

If you’re heading to San Francisco, there’s still time to register for Microsoft Ignite and browse the session catalog. If you’re following from home, you can use the same registration page to get a free digital pass. 

How to watch Microsoft Ignite 2026

Tune in to Live at Microsoft Ignite at 10 a.m. Pacific (1 p.m. Eastern) on Tuesday, November 17, to watch the opening keynote from Nadella and Althoff in full. The broadcast continues over the next three days with demos, customer stories, and executive interviews. The New Stack‘s own Jennifer Riggins will join the anchor desk throughout the show to talk through what the announcements mean for teams building and running AI in production. 

Alysa Taylor, Microsoft’s Commercial Chief Marketing Officer, says to “Come with a challenge you’re excited to solve, whether that’s bringing ambition into the flow of work, connecting intelligence across your organization with the right data and context, or scaling AI innovation to drive meaningful business impact.

“Take in what you see on stage, then go deeper with the builders, customers, and leaders who are working through these same opportunities. The real value is connecting inspiration to action, and leaving with ideas you can put to work.” 

Leave some time for networking after your sessions, too. If someone just described an agent you could imagine running in your organization, ask what it costs to scale, which metrics they are watching, or how they got their colleagues to adopt it. 

The post See what AI looks like in production at Microsoft Ignite  appeared first on The New Stack.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Node.js 27.0.0-alpha.0.1.0 (Alpha)

1 Share
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories