Endpoint administrators need to keep elevated access accountable at scale. Security teams also need a clearer view of expert-led protection and a simpler way to deploy SQL Server protection in Azure Government. As AI agents gain access to business data and tools, organizations need ways to limit their authority and adapt protection as risk changes. This month’s Microsoft Intune and Microsoft Defender updates introduce capabilities across these areas, alongside new Secure AI capabilities for agent access. A recent Secure Now update in Microsoft Security Exposure Management also connects information on recent threats to focused initiatives for reducing exposure.
Here’s what’s new:
Limit agent authority to the task with Dynamic Permissions
Give agents task-scoped authority and adapt access as risk changes
As agents gain access to business data and tools, organizations need ways to manage what each agent is allowed to do. Dynamic Permissions provides an agent its own permissions and authority, scoped to its current task and for only as long as the task requires. As the agent works, Dynamic Agent Risk assesses whether the agent’s authority aligns with changing behavior and context. Dynamic Conditional Access can then respond proportionately by narrowing permissions, restricting access to resources, or requiring human approval for higher-impact actions. Together, these capabilities are designed to help organizations tailor agent authority before an agent acts and adjust access as risk changes. See how security can respond when an agent steps outside its task.
Contain local AI agents with Microsoft Execution Containers
Apply least-privilege boundaries to help limit access on Windows
Microsoft Execution Containers (MXC), now generally available, gives organizations an operating system-enforced containment layer for AI agents, designed to limit what an agent can access. Rather than relying on the agent to behave within intended boundaries, MXC applies least-privilege controls across files, networks, processes, and user interactions, with additional isolation options for higher-risk scenarios. Organizations can tune and validate policies before enforcing them broadly, while upcoming integration with Microsoft Intune, Microsoft Entra, and Microsoft Agent 365 is intended to extend governance and attribution across the enterprise. Discover more about this policy-driven containment for AI agents.
Scale least privilege with Microsoft Intune Endpoint Privilege Management
Expand least-privilege scenarios with new system settings support and simpler tenant onboarding
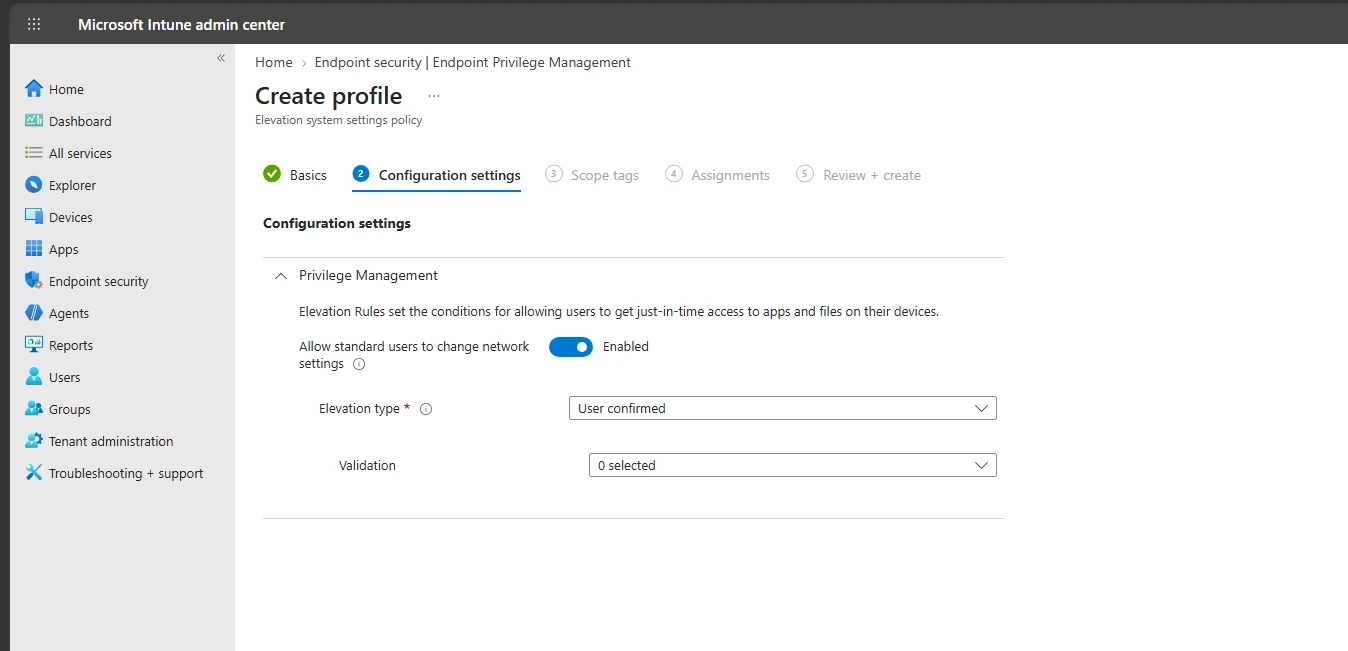
Microsoft Intune Endpoint Privilege Management continues to expand the tasks standard users can complete without broad administrator rights. With new system settings support, standard users can change IPv4, IPv6, and DNS server values on their device’s network adapters through Endpoint Privilege Management, while administrators determine how those changes are elevated. For user-confirmed changes, administrators can require a business justification, Windows authentication, or both before the change is applied. Along with tenant onboarding updates, these improvements support organizations as they get started with and expand their use of Endpoint Privilege Management. Explore how to get started with system settings support in Endpoint Privilege Management.
Simplify security operations with Defender Experts
See what Defender Experts are investigating in a consolidated experience
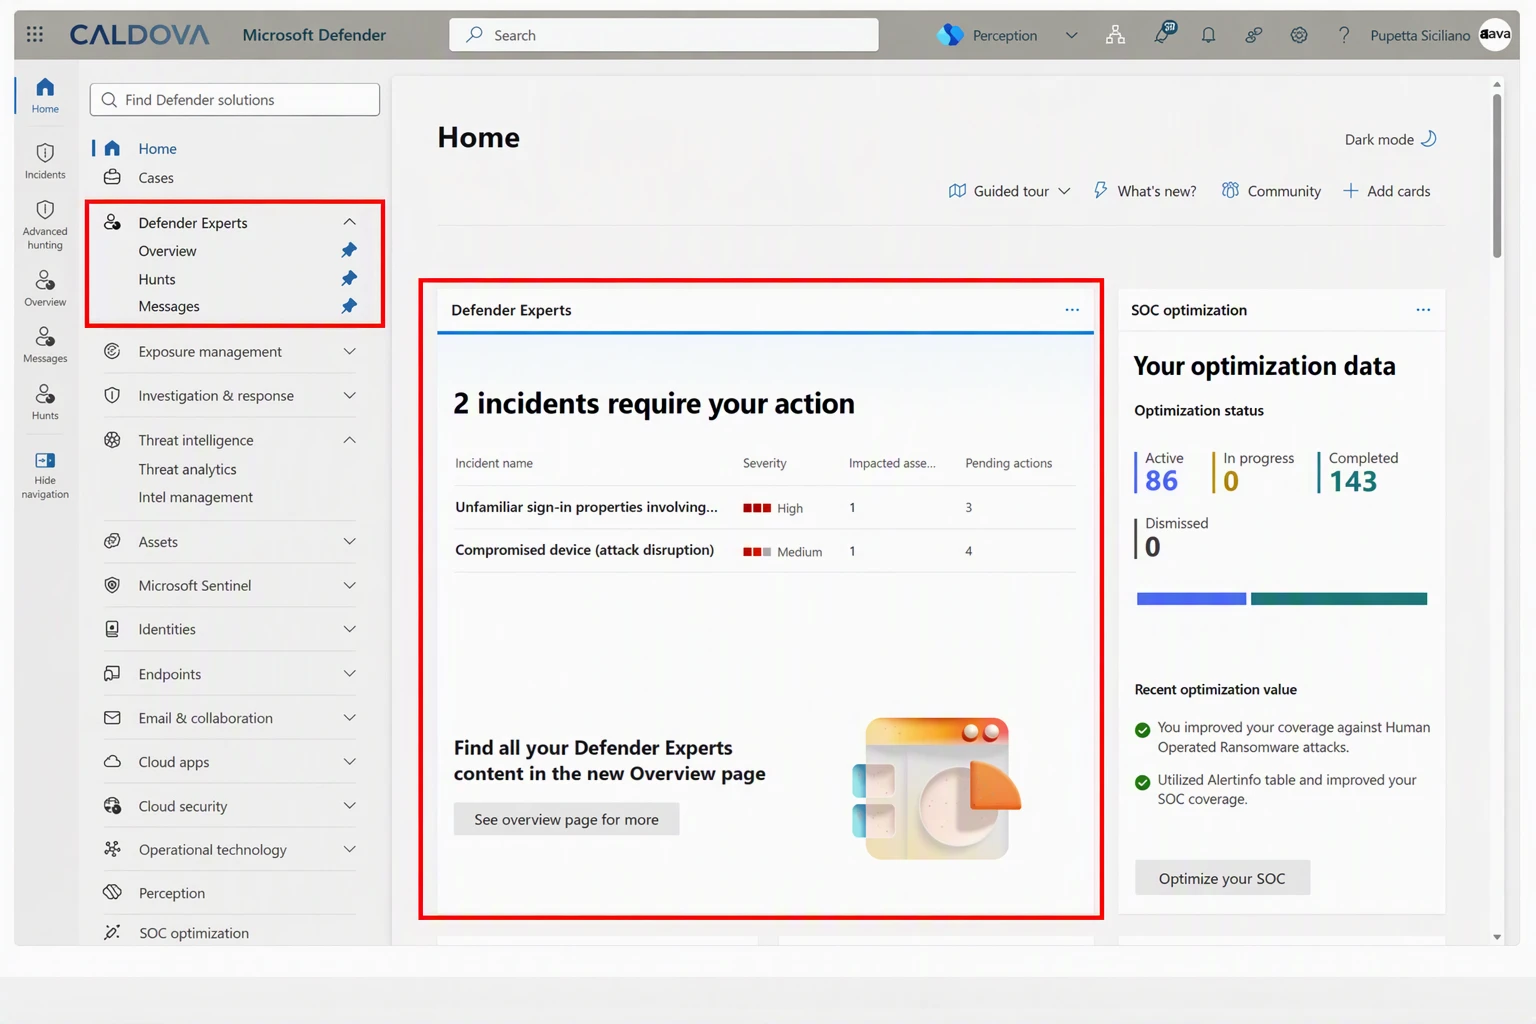
As threats move faster and security environments grow more complex, security teams need to quickly understand what matters and when to act. New Microsoft Defender Experts MDR experiences in the Microsoft Defender portal bring ongoing expert work into focus with a consolidated overview page with updated navigation and visibility into hunts. Teams can review active and completed hunts, see findings from Defender Experts, and identify items that may require follow-up. Learn more about the new Defender Experts MDR experiences.
Extend protection and discover local agents with Microsoft Defender
Simplify deployment and expand SQL protection
The enhanced agent for Defender for SQL Servers on machines is now generally available for resource- and subscription-level enablement in Azure Government cloud. The enhanced agent uses existing SQL infrastructure, eliminating the need to deploy the Azure Monitor Agent for this scenario. Security teams can spend less time on deployment and extend protection across their SQL Server environments. Learn more about the enhanced agent and how to get started.
Discover local AI agents and their configured MCPs on Windows and macOS
On endpoints, Microsoft Defender is extending discovery capabilities for supported local AI agents and their configured model context protocols (MCPs) across Windows and macOS. Now generally available, Defender discovers more than 50 supported local AI agents by observing their activity and brings the agent, device, account, and configured MCP context together to help security teams understand local AI agent activity in their environment. Learn more about local agents.
Improve security posture with Microsoft Security Exposure Management
Prioritize foundational security controls with Secure Now
AI-enabled attacks can take advantage of familiar weaknesses, including excessive permissions, unprotected authentication flows, and exposed systems. Secure Now now pairs information about recent threats with focused initiatives across security domains. Security teams can use that context to identify foundational controls that need attention, review the recommended actions, and prioritize work intended to reduce exposure. The update helps connect information about observed attack patterns with security improvements teams can consider in their own environments.
Learn how to address agentic AI’s security challenges
From agentic inventory and observability to stopping AI runtime threats
An inventory is only the starting point for managing Al agent risk. Organizations also need to consider ownership, limits on what agents can access, how risk is reassessed as agents operate, and protections against emerging threats. “Don’t Leave AI Exposed” provides security professionals, IT administrators, and developers with actionable guidance on managing risk across the agent lifecycle. Download the guide for considerations spanning agent inventory, ownership, access, monitoring, and runtime protection.
Stay in the Loop
Security teams need a clear account of what is changing across the portfolio and where those changes can strengthen their operations. In the Loop brings together the latest Microsoft Security updates and their implications for your security strategy. Explore earlier editions and check back for the next drop.
See Microsoft Security innovations in action at Microsoft Ignite, November 17-20, 2026, in San Francisco or online.
To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.
Formal methods for everyday software. PDD Kit helps you turn your intent into a formal spec, then proves the code your agent writes for every input and uses tests where a proof can’t reach. It takes formal methods beyond niche, specialist work to engineers without a formal methods background and to everyday applications, like the full-stack web app shown here.
Exhaustive line-by-line human review can become difficult to scale asAIagents generate increasingly large amounts of code. The plan is supposed to be the contract between you and a coding agent, but nothing actually forces the agent to follow it. The tests it writes usually check what it built, rather than what you asked for.
PDD Kit makes the agent keep the plan. It works with you to turn your intent into a formal specification in Verus (opens in new tab), proves the agent’s code meets that spec for every input, and falls back to tests where a proof can’t reach.
We tried it on a full-stack web app. Inside GitHub Next’s Chopin (opens in new tab), we used PDD Kit to formally verify the login logic of Pet Store, a Rust (opens in new tab) storefront. Verus hardened the code and uncovered existing bugs, proving the absence of login bugs with respect to the specification. The developer reviewed the intent and never read the generated code line-by-line.
The plan is the contract the agent should follow, but nothing constrains the agent to follow it.
Coding agents now ship whole features in one sitting often spanning tens of thousands or hundreds of thousands of lines of code. As a result, reading every line of the pull request doesn’t scale to this new way of work. Now, most teams invest in the plan and relevant testing instead: describe to an agent what they want, go back and forth until the plan and proposed tests look right, and hand them off to the agent for implementation.
This plan or natural language spec is meant to be the contract that an agent holds. However, in practice, the agent can drift from it. It implements something slightly different, then writes tests that pass for its implementation rather than the code you intended it to write. Continuous integration (CI) grows due to a profusion of low quality and high quantity of tests, coverage looks healthy, and the gap between what you asked for and what shipped stays hidden until a bug report or a nasty edge case shows up.
So, how do you reliably scale review as agents generate increasingly large amounts of code? Agent code fails in two ways a careful reviewer would usually catch: it leaves out something obviously necessary, or it does something obviously wrong. Tests alone don’t close that gap, because they only exercise a tiny slice of what a program can do. Closing it needs a different kind of machinery, which is where proofs come in.
Review asks “does this look right?” A proof answers “is this right?” A mathematical proof shows that code meets its specification for every input, including the ones your test suite can miss. That provides stronger assurance for specified properties than testing alone, especially when line-by-line review isn’t practical.
Proofs used to be too expensive for everyday software. You needed specialists, unfamiliar languages, proofs many times larger than the code, and proofs took years to develop, but two things have changed since. First, recent advances in coding agents have made it increasingly practical for them to help generate formal proofs from well-defined specs. Secondly, agents can now better help you write formal specs. We call this new software development paradigm Proof-Driven Development (PDD). PDD Kit is our toolkit for it.
How PDD Kit works
PDD Kit is to formal methods roughly what Spec Kit (opens in new tab) is to Spec-Driven Development. It runs as a partner inside Chopin (opens in new tab), GitHub Next’s real-time, multiplayer planning environment, where a team and agents can plan in one shared document.
The workflow has two halves (Figure 1). First, team members review intent in plain language. PDD Kit asks the questions a careful reviewer would ask, explains the relevant code as it goes, and records the answers in an intentartifact, a document that bridges the user’s intent with the formal specification or tests. The parts of the user’s intent that can be formalized are converted into formal specifications and the rest, which must be taken on trust, are converted to informal specifications for tests. PDD Kit automatically generates proofs that the code satisfies the derived formal specs and high-quality tests for the informal specs. You don’t need a formal methods background for any of it.
Figure 1. Proof-Driven Development with PDD Kit. Team members settle intent. Verus and the test suite hold the code to it.
Consequently, every result in PDD Kit says which kind of verification it rests on:
Formal verification is a mathematical proof that code satisfies its specification for every possible input, checked by a tool called a verifier. For PDD Kit today, that verifier is Verus (opens in new tab), a proof language for Rust co-developed by Microsoft Research, Carnegie Mellon University, VMware Research, ETH Zurich, MPI-SWS, UNSW Sydney, the University of Texas at Austin, the University of Michigan, the University of British Columbia, the University of Wisconsin–Madison and the Weizmann Institute of Science.
Empirical verification checks code by running it and observing what it does. It covers what a proof can’t reach, such as a third-party cryptography library or a user interface. It uses unit and end-to-end tests, terminal automation, browser agents, and computer-use agents for anything a browser can’t drive. A passing test only shows the code worked on the inputs it tried, so PDD Kit labels it as evidence rather than proof.
The line between the two is the Trusted Computing Base (TCB): the code that the proof assumes behaves as described. PDD Kit makes that line explicit and asks you to sign off on each piece.
For brevity in this blog, we focus on formally verifying the login logic of the app, but the same process can be used to verify functional correctness of the entire app. PDD Kit recommends starting with the most sensitive parts of your application and incrementally verifying your application. A login bug can hand an attacker a customer’s account or an admin’s controls, so that’s where proof effort pays off first. The developer’s whole request in Chopin was two sentences:
Verify the login logic in backend/src/handlers/auth.rs. Here are my requirements:
You only get a token with the right password.
Only admin accounts get admin tokens.
We kept the request rough on purpose. Capturing the intent of the user and turning the user request into something a proof can check is PDD Kit’s job.
Step 1: Questions before code
PDD Kit’s planning workflow, pdd-plan, reads the code and comes back, before writing anything, with questions in a Decisions tab. When a question depends on how the code works, the card explains that part first: the goal, how the pieces fit, and the exact function involved, so you can answer without opening the source.
Figure 2. The first decision card. “Only with the right password” on its own is also met by a login that refuses everyone. Proving both ways rules that out.
The question looks pedantic, but it matters. “You only get a token with the right password” rules out the bad case, a wrong password getting a token, and a login that refuses everyone keeps that promise perfectly. “The right password always works” is the half that rules it out. Formally, the first is an implication (token ⇒ right password) and the second is its converse. Together they make an “if and only if.” An agent left alone would pick one without telling you, but here the developer picked both ways.
Step 2: A human readable intent map
As the conversation goes on, PDD Kit keeps a rough work section at the top of the plan current, so a user can keep track of important concepts without having to scroll back through a long chat to find what was agreed. It includes a flowchart of the login being specified, a spec landscape of what will be proved and what will be trusted, and, when a picture helps, a mental model. For login, PDD Kit drew a ticket desk (Figure 3).
Figure 3. PDD Kit’s mental model for login. The field you send picks the window, the window picks the table and with it the role, and nothing prints until the password matches.
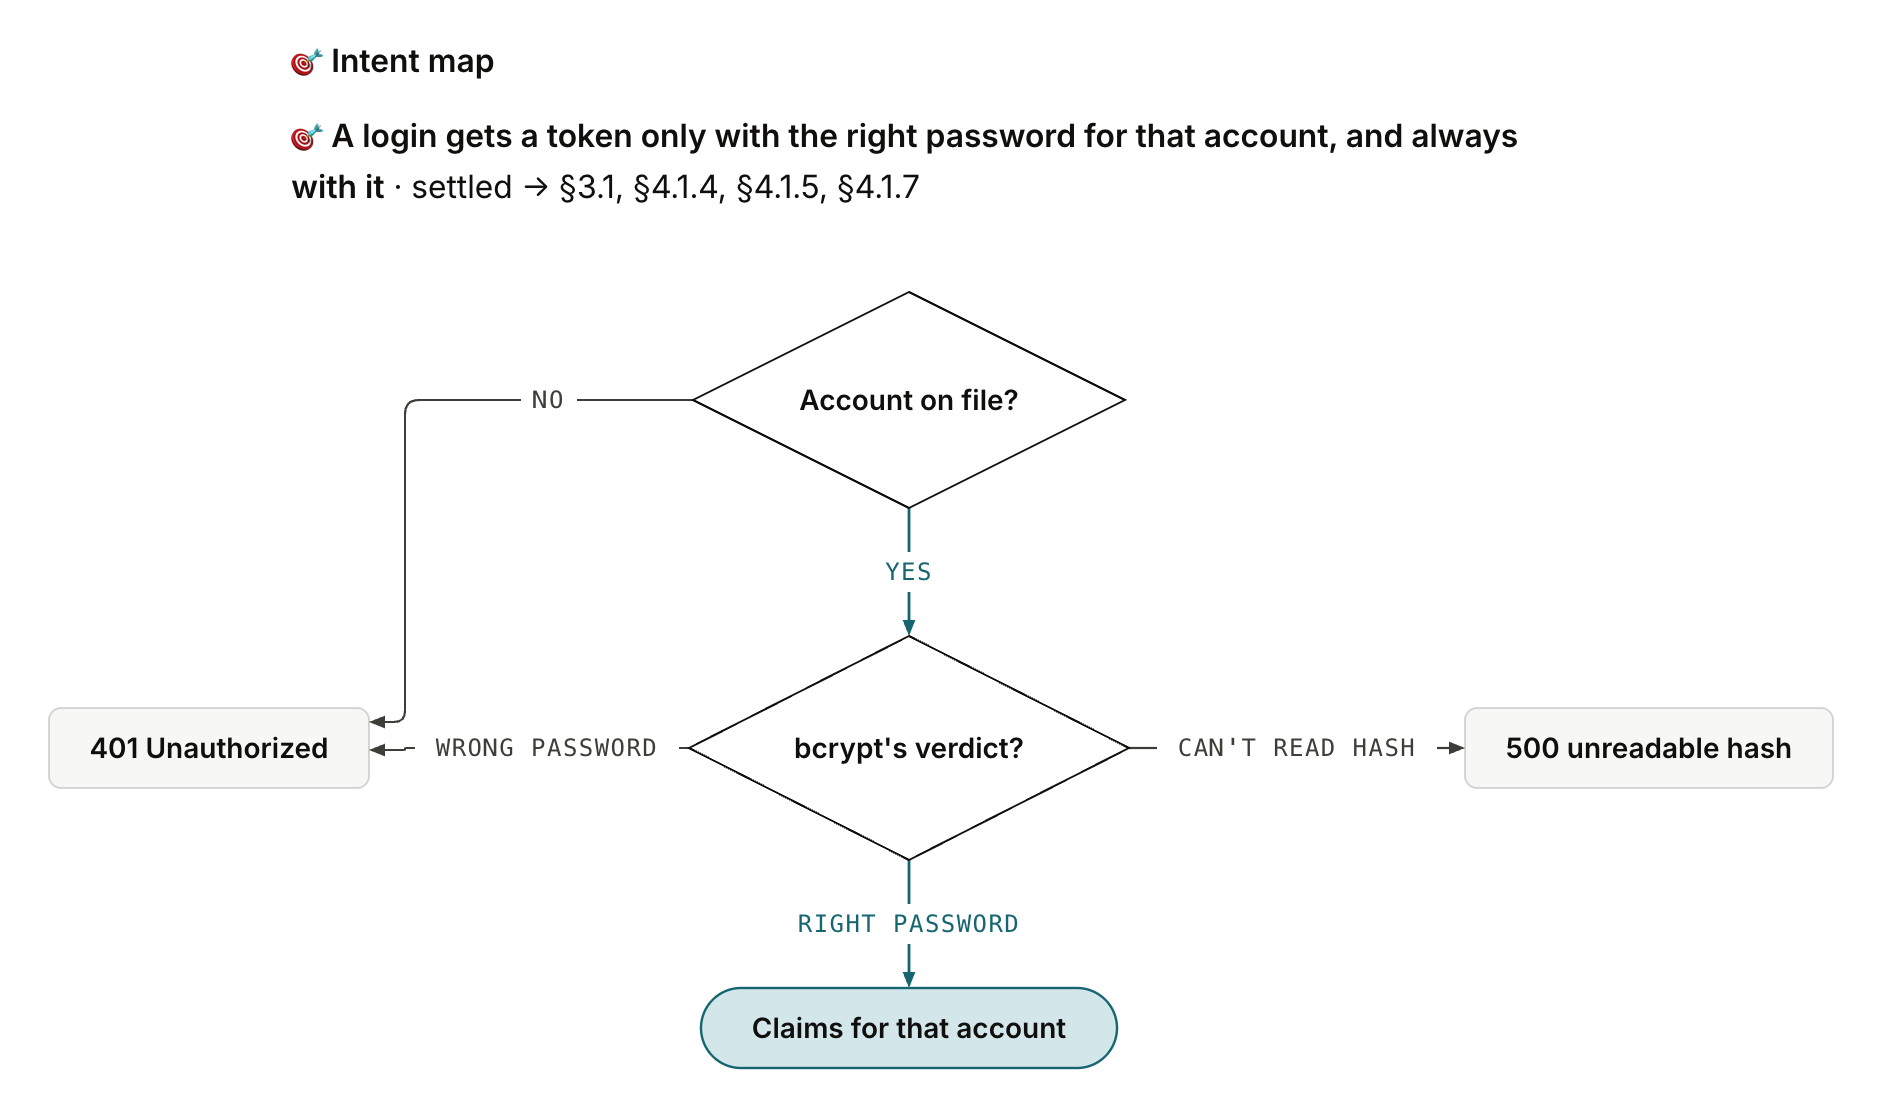
Below it, the intent map ties each requirement back to the developer’s own words and records how it was settled (Figure 4). Each entry links to the section of the formal spec that models it and to the tests that cover it, and the spec section shows snippets of the Verus contract, annotated so the developer can see how the formal spec models their intent.
Figure 4. An intent map entry after the decision: a login gets a token only with the right password for that account, and always with it. The flowchart shows every way the password check can end.
The decision card in Figure 2 is the kind of ambiguity an agent would otherwise settle silently. Figure 5 shows how small the difference looks on paper: the two readings disagree in a single cell, a right password that gets no token.
Figure 5. Two readings of the same sentence. They differ in one cell, and that cell changes what the proof has to establish.
Step 3: Proving the login function
Before anything gets built, PDD Kit asks the team to sign off on the plan as a whole. Its first draft proved the decision at the center of login, picking the table and gating on the password, and kept the handler around it trusted and tested. That’s a sensible default, and it’s what PDD Kit recommended, but the developer wanted more. The handler is where the lookups get awaited and the token gets signed, and that glue is exactly where a refactor can quietly swap two lines. So at intent review the developer chose to give the login handler its own async spec, so the proof covers that glue too instead of trusting it (Figure 6).
Figure 6. Proving more of login means trusting more small wrappers. The card says so before the developer chooses.
That choice moved almost everything into the proof and left the login handler with nothing to do but unpack the request. A new async function, login_flow, carries the contract from the request’s fields all the way to the token or the HTTP error. PDD Kit then brought the revised plan back for a fresh sign-off, because matching your intent isn’t proof, and it doesn’t approve new trust or a wider scope.
Step 4: Where proof stops
There are plenty of things you can’t prove about a program, and login runs into most of them:
Code the verifier can’t see. bcrypt’s hashing, sqlx’s queries and jsonwebtoken’s signing live in other crates, outside the proof.
Facts about the outside world. What SQLite holds right now and what time the clock says are inputs to the program, not something its code can establish.
Whether, and how fast, something finishes. The spec says what you get if login answers. A hung query, or a slow one, breaks nothing in it.
Anything a person has to judge, like whether an error message helps or a screen makes sense.
Whatever nobody wrote down. A proof covers its spec and says nothing about requirements outside it.
That’s where empirical verification comes in. PDD Kit spells out the trusted boundary, the part of the TCB this proof leans on. It wraps each trusted piece in a small function with an assumed contract, using Verus’s #[verifier::external_body] or external_fn_specification, asks the developer to accept each one on its own, and writes a test for every assumed clause into the plan. For login, the developer signed off on six pieces:
The two lookups, Customer::find_by_email and Admin::find_by_username. Each awaited, successful lookup returns exactly the row its own table holds for that email or username, or none.
check_password, a thin wrapper around bcrypt::verify. It errors only on a stored hash bcrypt can’t read, and Ok(true) means exactly the right password.
generate_token, which signs exactly the claims it is given under the configured secret and reports a signing failure as a 500.
expiry_from_now, which reads the clock and writes an expiry exactly 24 hours later.
database_error, which turns a failed lookup into today’s 500 with sqlx’s message.
The login handler shell, which unpacks the request and passes its fields to login_flow unchanged.
In the spec, a lookup keeps its code where it is and gets a contract from the outside with external_fn_specification:
/// Looks up a customer by exact email. /// Trusted, not proved: the SQL query runs in sqlx, which Verus cannot check. /// Every customer promise of `login_flow` rests on it. #[verifier::external_fn_specification] pub async fn ex_customer_find_by_email(pool: &sqlx::SqlitePool, email: &str) -> (r: Result
The clock is a small wrapper marked #[verifier::external_body]. Verus uses its ensures clause and never reads the body:
/// Reads the clock and computes a token's expiry 24 hours ahead.
/// Trusted, not proved: chrono's clock is outside the proof.
/// It panics if the time is out of range, as today's login does;
/// that panic is not promised against.
#[verifier::external_body]
pub fn expiry_from_now() -> (r: Expiry)
    ensures
        // The expiry is exactly 24 hours (86,400 seconds) after the clock reading.
        r.exp as int == r.now as int + 86_400,
{
    ...
}
Figure 7 puts the three layers together: what Verus proves, what people accept and tests check, and what nobody is promising.
Figure 7. Where the login proof stops. Verus proves the core for every input. People accept the trusted ring and tests check it. The plan lists what nobody is promising.
Figure 8 maps what gets proved and what gets trusted. Each trust decision is its own card. It shows the clauses Verus will take on faith, what the developer is accepting, and which promise falls apart if the assumption is wrong (Figure 9). Every assumed clause then gets an empirical check in the plan’s Empirical verification section, written as Given/When/Then scenarios before any test exists (Figure 10). An entry says planned until it has run, and then it records the command’s result and the commit it ran against.
Figure 8. What gets proved and what gets trusted in login. Green functions are proved by Verus for every input. Amber pieces are trusted, accepted by the developer, and checked by the planned tests in the plan’s §4.1.Figure 9. A trust card for check_password. Verus takes these two clauses on faith, so a person accepts them and two tests check them. Figure 10. A planned test for the trusted check_password, written before the test exists. The plan labels a passing test as evidence rather than proof.
The plan is just as explicit about what nobody is promising: that the login future ever completes, that an out-of-range clock won’t panic, anything about the timing or rate of attempts, and how other endpoints read the role.
Step 5: Reading the spec
The intent artifact is what the team reviews. It’s the plain-language version of the formal spec PDD Kit writes as Verus contracts. You might be wondering whether someone now has to read the proof instead of the code. Nobody does, because the coding agent writes the proof and Verus checks every step of it. If Verus accepts the proof, it holds whether or not anyone reads it. The spec is what the proof is held to, so that’s what people review, and this one is short enough to learn to read in a few minutes. Each function gets an ensures block: statements about its result, r, that must hold for every possible input. Verus checks them when you build, and if any clause could fail for even one input, the build fails and Verus points at that clause. Each clause reads as an if-then, and Figure 11 takes apart the clause for the developer’s first requirement.
Figure 11. The ensures clause on login_flow for “You only get a token with the right password.” The same account a appears on every line, which ties the password check to the token.
Notice that the same a appears on every line, which ties the password check to the token. For example, imagine a bug where login checks the password against one account but signs the token for another. Bob logs in with his own, correct password and gets back a token for Alice’s account. Each step looks fine on its own, but this clause catches it, because the password check and the token have to name the same account. That’s the kind of wiring bug a test suite rarely thinks to look for. The spec also has to talk about SQLite, bcrypt and JWTs without running any of them. It does that with uninterpreted functions, names with no body: customer_on_file(email) and admin_on_file(username) for the rows the database holds, bcrypt_verdict(password, hash) for what bcrypt would say, and token_claims(token, secret) for what a token carries. Verus knows nothing about them except what the trusted contracts from Step 4 promise. The proof says “whatever the database holds, login does the right thing with it,” and a trusted contract says “the lookup returns what the database holds.”
/// The customers row the database holds for
/// exactly this email, if any, when login looks.
/// Left abstract: only `Customer::find_by_email`'s
/// trusted contract says what it is.
pub uninterp spec fn customer_on_file(email: Seq) -> Option;
...
/// What bcrypt says about `password` against a
/// stored `hash`: Some(true) when it is the password
/// the hash was made from, Some(false) when it is
/// not, None when bcrypt cannot read the hash.
/// Left abstract: its meaning is bcrypt's, taken on trust through `check_password`.
pub uninterp spec fn bcrypt_verdict(password: Seq, hash: Seq)
    -> Option;

/// The password is the right one for the stored hash, by bcrypt's verdict.
pub open spec fn password_matches(password: Seq, hash: Seq) -> bool {
    bcrypt_verdict(password, hash) == Some(true)
}
On top of those, named_account(email, username) says which account a login names: the customers row for the email when one is sent, otherwise the admins row for the username, otherwise none. It’s written like Rust, but it’s a mathematical definition that never runs and only appears in contracts. Code like this is called ghost code, since the verifier checks it but the compiler erases it from the program. With it, the developer’s two-sentence request ends up as eight ensures clauses on login_flow (Figure 12).
/// The account a login names: the customers row for
/// the email when one is sent (role "customer"),
/// otherwise the admins row for the username (role "admin"), otherwise none.
pub open spec fn named_account(email: Option, username: Option)
    -> Option {
    match email {
        Some(e) => match customer_on_file(e@) {
            Some(c) => Some(NamedAccount {
                id: c.id@, password_hash: c.password_hash@, role: customer_role() }),
            None => None,
        },
        None => match username {
            Some(u) => match admin_on_file(u@) {
                Some(a) => Some(NamedAccount {
                    id: a.id@, password_hash: a.password_hash@, role: admin_role() }),
                None => None,
            },
            None => None,
        },
    }
}
Figure 12. The two-sentence request and the Both ways decision ended up as eight ensures clauses on login_flow. Four of them keep today’s refusals, so the storefront and the existing API tests keep working.
Here’s the whole contract, with its doc comment trimmed. Each clause has the plain-English comment above it that the intent artifact shows the team:
/// The whole login, awaited end to end: from the
/// request's fields to the token or the HTTP error.
/// ...
pub async fn login_flow(pool: &sqlx::SqlitePool, config: &Config,
    email: Option, username: Option, password: &str)
    -> (r: Result)
    ensures
        // Neither an email nor a username: 400 with today's message.
        email is None && username is None
            ==> (r matches Err(AppError::BadRequest(m))
                && m@ == missing_identity_text()),
        // A token only for the account the login names, with its right
        // password; it carries that account's id and its table's role.
        r matches Ok(t) ==> (named_account(email, username) matches Some(a)
            && password_matches(password@, a.password_hash)
            && token_claims(t@, config.jwt_secret@) matches Some(c)
            && c.sub@ == a.id && c.role@ == a.role),
        // The right password for the named account always gets a
        // token, unless a lookup or signing failure gives 500.
        (named_account(email, username) matches Some(a)
            && password_matches(password@, a.password_hash))
            ==> (r is Ok || r matches Err(AppError::Internal(_))),
        // A login naming an account nobody holds gets
        // 401, unless the lookup fails with 500.
        ((email is Some || username is Some) && named_account(email, username) is None)
            ==> (r matches Err(AppError::Unauthorized)
                || r matches Err(AppError::Internal(_))),
        // A wrong password for an account whose hash bcrypt
        // can read gets 401, unless the lookup fails with 500.
        (named_account(email, username) matches Some(a)
            && bcrypt_verdict(password@, a.password_hash) == Some(false))
            ==> (r matches Err(AppError::Unauthorized)
                || r matches Err(AppError::Internal(_))),
        // An account whose stored hash bcrypt cannot read gets 500 and no token.
        (named_account(email, username) matches Some(a)
            && bcrypt_verdict(password@, a.password_hash) is None)
            ==> r matches Err(AppError::Internal(_)),
        // The admin role only for an admins row
        // found by username, with no email sent.
        (r matches Ok(t) && token_claims(t@, config.jwt_secret@) matches Some(c)
            && c.role@ == admin_role())
            ==> (email is None && username matches Some(u)
                && admin_on_file(u@) is Some),
        // An email login's token always carries the customer role.
        (r matches Ok(t) && email is Some)
            ==> (token_claims(t@, config.jwt_secret@) matches Some(c)
                && c.role@ == customer_role()),
{
    unimplemented!()
}
The trusted boundary shows up in the code too. check_password is one of the functions whose body Verus doesn’t check. Its contract ties it to bcrypt_verdict, an uninterpreted model of bcrypt with no axioms:
/// Asks bcrypt whether `password` matches the stored `hash`.
/// Trusted, not proved: Verus cannot check bcrypt's hashing,
/// so this wrapper's contract is assumed.
/// Every password promise of `login_flow` rests on it.
#[verifier::external_body]
pub fn check_password(password: &str, hash: &str) -> (r: Result)
    ensures
        // bcrypt answers (Ok) exactly when it can read the stored hash.
        r is Ok <==> bcrypt_verdict(password@, hash@) is Some,
        // Its answer is its verdict: true for the
        // right password, false for any other.
        r matches Ok(b) ==> bcrypt_verdict(password@, hash@) == Some(b),
{
    bcrypt::verify(password, hash).map_err(|e| e.to_string())
}
The doc comment above it says what rests on it: every password promise of login_flow. Every login ends in one of a handful of places, and only one of them has a token (Figure 13). The proof covers all of them at once.
Figure 13. Every way a login can end, from the plan.
login_flow is async: it awaits a database query. Verus can put contracts on async functions, with one rule worth knowing (Figure 14). requires is checked when the call creates the future. ensures describes the value you get when you await it. Nothing promises the future finishes, so a hung query breaks no clause.
The doc comment on login_flow says so in as many words:
/// ... No promise the future completes.
pub async fn login_flow(...) -> (r: Result)
Figure 14. When a contract is checked, for a sync fn and an async fn.
login_flow stays short because it’s built from smaller proved pieces. lookup_target picks the table. login_core awaits the lookup and calls decide_login, the password gate. issue_token signs the token, or maps a refusal to today’s HTTP error. Each piece has its own contract, and Verus proves login_flow using only those contracts, without re-reading their bodies. Change the body of decide_login and only decide_login gets proved again.
Here’s the smallest piece, whole, and the start and end of the password gate:
pub fn lookup_target(email: Option, username: Option)
    -> (r: Result)
    ensures
        // An email, when sent, wins: customers are searched for exactly that email.
        email matches Some(e)
            ==> r == Ok::(LookupTarget::CustomerByEmail(e)),
        // With no email, a username sends the search
        // to admins for exactly that username.
        email is None && username matches Some(u)
            ==> r == Ok::(LookupTarget::AdminByUsername(u)),
        // With neither, the login is refused for missing an identity.
        email is None && username is None
            ==> r == Err::(LoginError::MissingIdentity),
pub fn decide_login(target: &LookupTarget, found: Option, password: &str)
    -> (r: Result)
    ensures
        // No row found: refused as Unauthorized,
        // the same answer as a wrong password.
        found is None
            ==> r == Err::(LoginError::Unauthorized),
        // Claims come back only for a found row
        // whose stored hash matches the password.
        r is Ok ==> found is Some
            && password_matches(password@, found->Some_0.password_hash@),
        // The right password for a found row always gets claims.
        found matches Some(a) && password_matches(password@, a.password_hash@)
            ==> r is Ok,
        ...
        // An admins-table search gives the role text "admin".
        r matches Ok(c) && target is AdminByUsername ==> c.role@ == admin_role(),
        // A customers-table search gives the role text "customer".
        r matches Ok(c) && target is CustomerByEmail ==> c.role@ == customer_role(),
An overview of login.rs
Figure 15 maps the whole spec file, verified/src/login.rs. It reads top to bottom in four layers: headers, imports and types Verus needs to know about, an abstract view of the outside world, the trusted contracts that connect that view to real code, and the five contracts the proof has to meet.
Figure 15. The parts of login.rs, in file order. Gray is header and types, purple is math that only appears in contracts, amber is trusted, and green is proven.
Here are two of the less obvious parts, abridged. external_type_specification introduces a type Verus didn’t define. The pool stays opaque, while a customers row keeps its fields visible:
/// The connection pool, opaque to the proof: only
/// the lookups' contracts say what it returns.
#[verifier::external_type_specification]
#[verifier::external_body]
#[verifier::reject_recursive_types(DB)]
pub struct ExPool(sqlx::Pool);
...
/// A customers row, with its fields visible to the proof.
#[verifier::external_type_specification]
pub struct ExCustomer(Customer);
And LoginError keeps the decision separate from the HTTP response, which is what lets issue_token pin each refusal to today’s status code:
/// Why a login gets no token.
pub enum LoginError {
    /// Neither an email nor a username was sent: 400 Bad Request.
    MissingIdentity,
    /// No such account, or the password does not match: 401 Unauthorized.
    Unauthorized,
    /// bcrypt could not read the stored hash, with its message: 500 Internal.
    UnreadableHash(String),
    /// The lookup query failed: 500 Internal, with sqlx's message.
    Database(sqlx::Error),
}
Before the plan comes back to you, two reviewer agents poke holes in the derived formal spec from the intent artifact to ensure a high-quality translation, so that the spec matches what you asked for and doesn’t promise more than a proof could show. The spec refinement runs in the background and takes live user feedback, iterating until reviewers agree that the spec is sound.
Step 6: Prove, check, close the gaps
Signing off on the spec is where the developer’s review ends. Everything after it, the implementation and the proof, is checked by machines, which is why this post spends its time on the spec and not the proof. Once the developer signs off, a Build plan stage (Figure 16) hands the approved plan to pdd-prove, which turns it into a small task graph (Figure 16). For login, that’s seven tasks: get login.rs building under Verus inside the backend crate, prove the decision, the token and the whole flow, then write the tests for the trusted wrappers and the end-to-end login.
Figure 16. Build plan turns the approved spec into seven tasks on a development machine. The first gets login.rs building under Verus without changing what any contract promises, and stops to ask rather than weaken a contract.
Each task runs the same loop:
A coding agent writes the implementation and the proof, and Verus checks them against the derived formal spec.
Anything in the trusted boundary gets the tests the plan called for.
An LLM verifier reads the plan, the specification and the results side by side, and looks for gaps: requirements with no proof and no passing check. Gaps go back to the coding agent until none remain. If the specification itself has a gap, such as two requirements that contradict each other, it comes back to the developer as a decision.
A proof is only as good as its spec, so pdd-prove checks the spec too. When a model writes its own spec, or is tuned to produce proofs, it tends to land on weak invariants: clauses that verify but rule out almost nothing. They prove something, just rarely the thing you care about. We call that “vibe verification.” That’s why it’s so important to make sure your intent is aligned with the agent and what PDD Kit is great for.
The loop is strict about not moving the goalposts. If an async construct can’t be expressed in the pinned Verus, the task stops and asks the team instead of switching to a non-async helper or weakening a contract.
How does PDD Kit remove classes of bugs? The mutation check is how PDD Kit guards against vibe verification. pdd-prove plants one bug per ensures clause in a scratch copy of the code, like refusing everyone or checking the username before the email, and Verus has to reject each mutant on the clause it targets. A mutant that gets through means that clause constrains nothing, and it comes back as a gap.
Step 7: Review intent alongside verified code
When the tasks pass, pdd-prove opens pull requests. They add a verified/ crate with login_flow, its pieces, their proofs, and the trusted wrappers with their tests, and route the real login handler through login_flow, keeping the existing HTTP status codes. Your verified logic integrates with and hardens your production login path, not a copy of it.
The developer was able to merge without relying on exhaustive line-by-line review of the generated code. The review had already happened on the intent artifact this whole time, where the team has the final say. We shifted more of the review focus from code review to intent review. The pull request works as a receipt, and its description marks every login requirement as either formally verified or empirically checked.
Merging is where the proof joins the team’s normal workflow. PDD Kit’s pdd-ship workflow adds the Verus check to CI next to the empirical tests, so every later change to login, by a person or an agent, has to keep proving against the same spec, and a broken proof fails the build like a failing test. And because a proof covers every input, PDD Kit prunes tests that only re-check what’s already proved, such as example-based tests of the password gate, and keeps the ones that guard the trusted boundary, so CI gets stronger and leaner at the same time.
What the proof does and doesn’t say
“Fully verified” is easy to oversell, so here’s exactly what we’re claiming.
Proved. The bodies of login_flow, login_core, lookup_target, decide_login and issue_token meet their contracts for every input. Login picks the right table, compares the request’s password against the stored hash of the account it names, issues a token with that account’s id and the role its table gives, and refuses everything else with today’s 400, 401 or 500 and no token.
Trusted and tested. The two database lookups, check_password over bcrypt, the clock, token signing, the database error message and the handler’s request unpacking sit outside the proof, each behind an assumed contract the developer accepted. Tests against the real bcrypt, the real SQLite schema and the real router cover them.
PDD Kit only verifies Rust today, since that’s the language Verus works on. If your codebase is already Rust, there’s nothing to migrate. Code in other languages can be ported to Rust and checked against the same spec, and non-Rust projects can call verified Rust through bindings.
There’s also a less obvious upside. Once reliance on exhaustive line-by-line review has been reduced, readability stops being the main reason to pick a language. You can pick one for speed and safety, and optimize as hard as you want, because any change that breaks the spec fails the proof.
What to Expect from PDD Kit
PDD Kit is a research prototype, and it only verifies Rust today since that’s the language Verus works on. Code in other languages can be ported to Rust and checked against the same spec, and non-Rust projects can call verified Rust through bindings. Proofs still take real effort, mostly in producing the proof itself, and a clear spec is what keeps that effort down, which is why so much of PDD Kit is about getting intent right first. We’d start where a bug costs the most, such as login, payments, or permissions, and verify the rest of a codebase one piece at a time.
Pet Store’s login is one piece of one app: a spec anyone can read, a Verus proof that the code matches it, and tests for everything the proof takes on trust. We want to be upfront about the weakest links. The guarantees are only as strong as the six trusted pieces, and two carry most of the weight: check_password for every password promise, and the two lookups for every promise about which account a token names. Tests support them, but nothing proves them. We expect that trusted boundary to shrink significantly over time, so a growing share of the code can be formally verified, and we want to find out how far this scales.
What we’re really changing is what people review. Instead of relying mainly on line-by-line review of agent-generated code, a team reviews what it meant, in plain language, and a proof holds the code to it. The plan was always supposed to be the contract, and now the agent actually has to keep it.
Acknowledgments
This work is a collaboration between the Microsoft Research Catalyst Lab, GitHub Next, and the Research in Software Engineering (RiSE) group. We would like to thank Maggie Appleton and Krzysztof Cieślak of GitHub Next for their collaboration on Chopin, and Nikhil Swamy, Lef Ioannidis, Janardhan Kulkarni, and Shuvendu Lahiri for their feedback and discussions on formal verification and intent formalization. We also thank the F*/Pulse and Verus teams for their support. Finally, we thank Idan Gazit of GitHub Next for supporting this collaboration.
FAQ
You do, and yes, it would. A proof shows the code meets the spec, not that the spec is what you meant. That’s why PDD Kit is built around existing research in intent formalization. The pdd-plan workflow reads your code, asks questions before writing anything, and turns your answers into a Verus spec plus a plain-language plan you approve, flagging ambiguity instead of guessing. Two reviewer agents check the spec, and the pdd-prove workflow plants one bug per clause to catch clauses that verify but rule out nothing. A wrong spec is still possible, which is why PDD Kit emphasizes making requirements explicit, identifying ambiguities, and keeping developers involved in reviewing and approving the spec before verification begins.
The difference is what holds the code to the plan.
Approach
What checks the code
Spec-Driven Development
Nothing enforces the spec
Test-Driven Development
Tests on a sample of inputs, often written to match what was built
Agent checks its own work
The same model that wrote the code
Proof-Driven Development
Verus automatically verifies the proof that your code satisfies the spec your approved
PDD keeps the planning loop from SDD and still uses tests where a proof can’t reach. A test checks some inputs, while a proof establishes that the code satisfies specified properties for all inputs covered by the formal model, under its stated assumptions.
The proof is Rust code annotated with Verus constructs, checked mechanically by Verus using the Z3 solver. It runs wherever your Rust builds: the pdd-prove workflow runs it while proving, and the pdd-ship workflow adds it to your build and CI so a broken proof fails the build. The check is deterministic, with no model involved. Models write the spec, code, and proof, but only a deterministic Verus run decides whether it passed. How long the check takes varies with the size of the code and how hard the proofs are: usually seconds for a small module, up to minutes for a larger codebase.
PDD Kit shifts more of the review process toward validating what the code should do, while using formal verification to provide additional assurance that the implementation meets those requirements. Developers review the natural-language plan, the formal spec, and the trusted components that fall outside the scope of the proof. The resulting pull request documents what was formally verified, what was tested, and where additional review may be needed. On the Pet Store full stack web app, this approach reduced reliance on exhaustive line-by-line review of the generated code.
We chose Verus because it allows us to verify Rust code directly, aligning with PDD Kit’s focus on integrating formal verification into existing Rust development workflows. Other proof languages (e.g., Lean, F*, Rocq) take different approaches to formal verification, each with its own tradeoffs. The techniques behind PDD Kit could help put them to work as well.
Accessibility work often lives in issue trackers, contribution guidelines, audit reports, team knowledge, and conversations with users. When that information has no predictable home, people who encounter a barrier must search for it, and maintainers lose context as contributors and project ownership change.
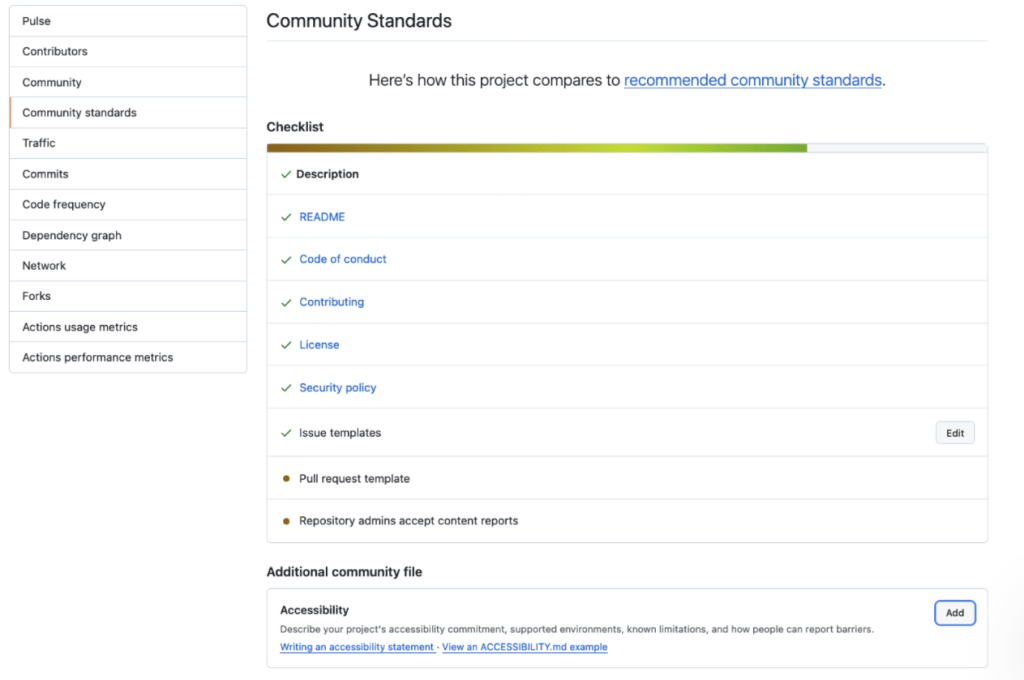
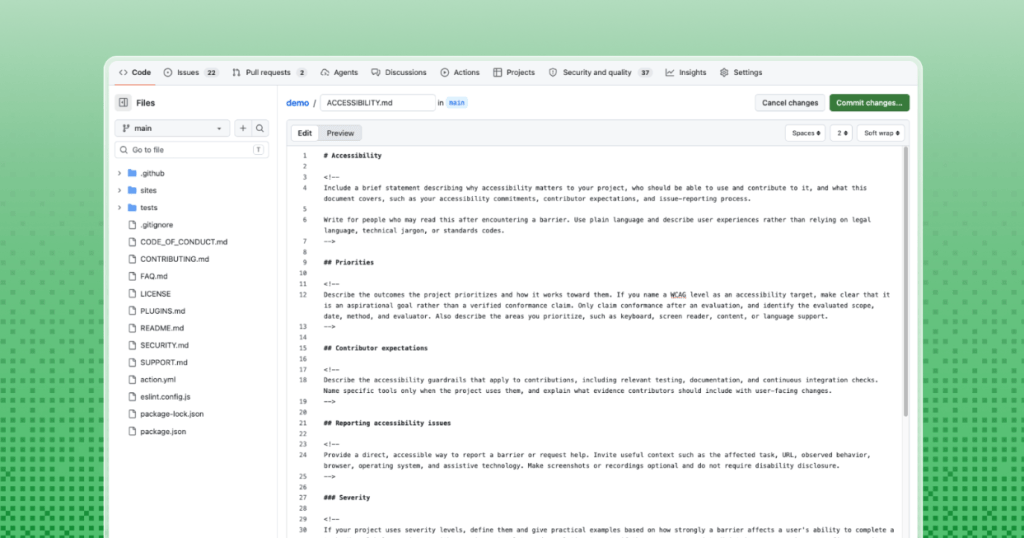
An ACCESSIBILITY.md file, now visible on repository overview pages, gives a project one durable place to explain its accessibility goals, contributor expectations, supported environments, known limitations, and process for reporting barriers.
GitHub makes accessibility statements easier to find
GitHub now recognizes the ACCESSIBILITY.md file in the repository’s root, .github/ directory, or docs/ directory. A repository can also inherit a statement from its organization’s .github/ repository. For public repositories, maintainers can add or propose a statement from Insights > Community Standards using a concise starter document.
GitHub’s community health files help people understand how a project works:
Contribution guidelines explain how to propose changes
Codes of conduct establish expectations for participation
Security policies explain how to report vulnerabilities
Recognizing ACCESSIBILITY.md gives accessibility information a dedicated place alongside that guidance.
New repositories also include an accessibility issue label by default. The statement explains how to report a barrier and what to expect next, while the label helps maintainers organize and track the resulting work.
Accessibility statements make project practices visible
GitHub CLI’s accessibility statement, for example, documents settings, known barriers, and workarounds. It explains why table output can be difficult to follow with a screen reader and provides a command that prints pull request numbers and titles one per line instead. It also asks contributors changing prompts or output to show the results with relevant accessibility settings enabled. Developers using the CLI get a specific workaround; developers contributing to it get clear expectations for their changes.
The GitHub Annotation Toolkit’s accessibility statement documents a limitation of its Figma library: annotations use canvas position, connecting lines, and matching numbers to visually convey relationships. Access to individual canvas objects does not necessarily communicate what those relationships are.
The statement gives collaborators a concrete alternative: provide a structured text description that identifies each annotated element, its intended semantics and behavior, and any relevant ordering. For developers preparing or receiving a design handoff, this explains what information needs to accompany the visual annotations.
The file also explains how to report accessibility barriers and explicitly states that the library has not undergone keyboard-only or screen-reader testing. Readers get both practical guidance and clear limits on what the project has verified. Showing this information in the repository overview makes it easier to find alongside the project’s other documentation.
Document what the project can maintain
There is no one fixed format for an ACCESSIBILITY.md file. A small library, command-line tool, documentation site, and large web application have different users, risks, and maintenance capacity. Start with accurate information that the project can keep current.
Priorities and goals: Explain why accessibility matters to the project and which user experiences receive attention.
Contributor expectations: Describe the accessibility checks, evidence, or review practices expected for changes, including instructions for human contributors and coding agents.
Reporting accessibility barriers: Provide a direct, accessible reporting path. Do not require disability disclosure, screenshots, or recordings.
Response process: Explain how maintainers acknowledge, triage, track, and communicate about accessibility issues. If the project uses severity levels, let maintainers assign or confirm them during triage.
Supported environments: List the platforms, browsers, input methods, and assistive technologies the project supports or has tested.
Known limitations: Describe barriers in terms of the affected experience, include available workarounds, and link to tracked remediation work.
Ownership and maintenance: Name the team, role, or maintainer responsible for keeping the statement and related practices current.
Feedback and improvements: Explain how users and contributors can suggest changes to the statement or the project’s accessibility practices.
Keep in mind that a project can name a Web Content Accessibility Guidelines version and level as a target. A target does not establish verified conformance. A conformance claim requires an evaluation and should identify the evaluated scope, date, method, and evaluator.
What the most useful ACCESSIBILITY.md files contain
The most useful accessibility statements serve people who arrive after something has already gone wrong. Plain language, descriptive links, and a clear reporting route matter more than legal or standards-heavy language.
Useful reporting guidance invites relevant context, such as the affected task, page, observed behavior, browser, operating system, and assistive technology. It makes screenshots and recordings optional and avoids asking someone to prove a disability.
The statement should also set expectations that maintainers can consistently meet. That can include acknowledgement, status updates, available workarounds, expected timelines, and an opportunity for the reporter to verify a fix.
GitHub’s Community Standards workflow provides a shorter starter with prompts that projects can replace with their own information. The goal is not to produce a perfect policy before publishing the file. Start with accurate information, name the gaps, and update the statement as the project’s accessibility practices mature.
Adding an accessibility statement makes accessibility work more discoverable to users, contributors, and maintainers. Normalizing that practice across open source projects helps make accessibility part of how communities plan, build, report, and improve their work.
Fixing a bug starts with understanding what your code is doing at runtime: reading the program state, following the call stack, or tracking down a slow function. RustRover 2026.3 makes that work easier to follow, whether you do it yourself or with an AI agent. It also ships with JetBrains Air, a new layer for running coding agents and reviewing their work in the IDE.
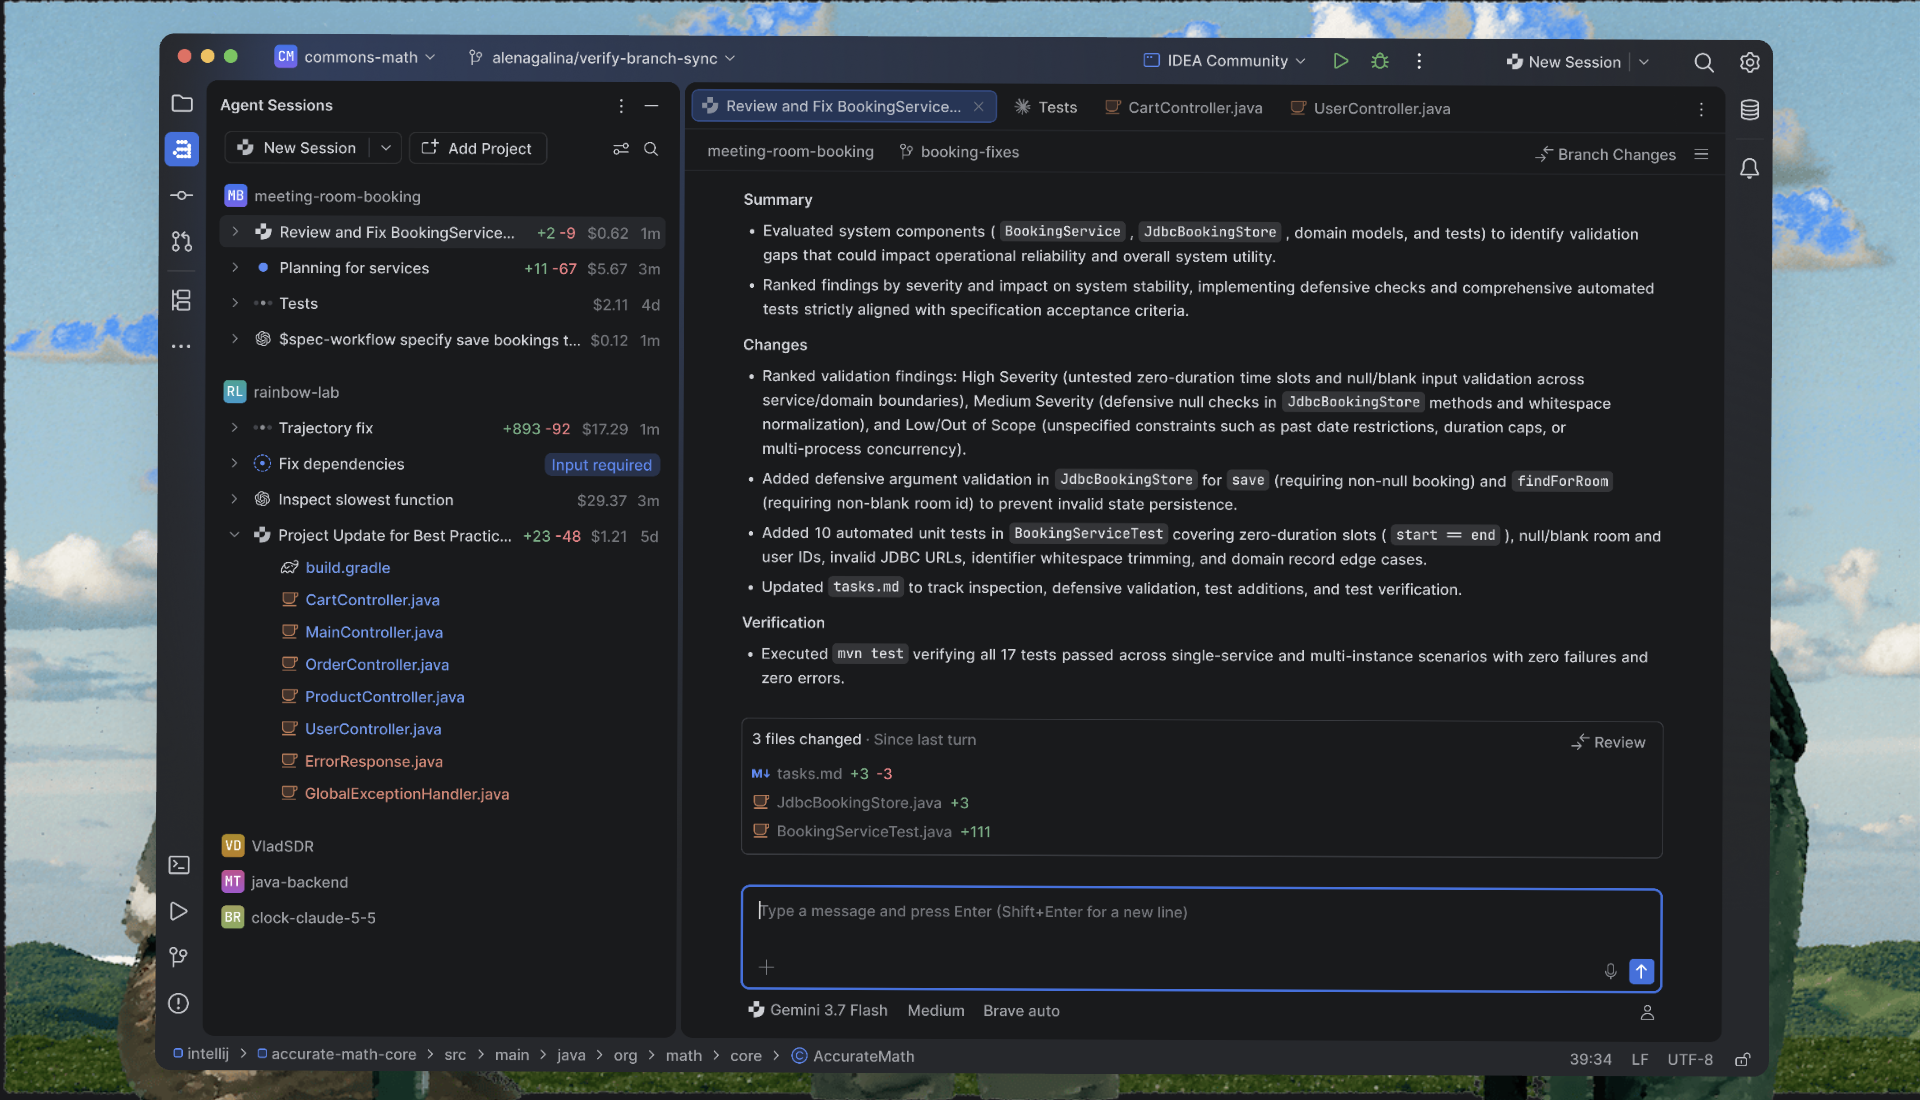
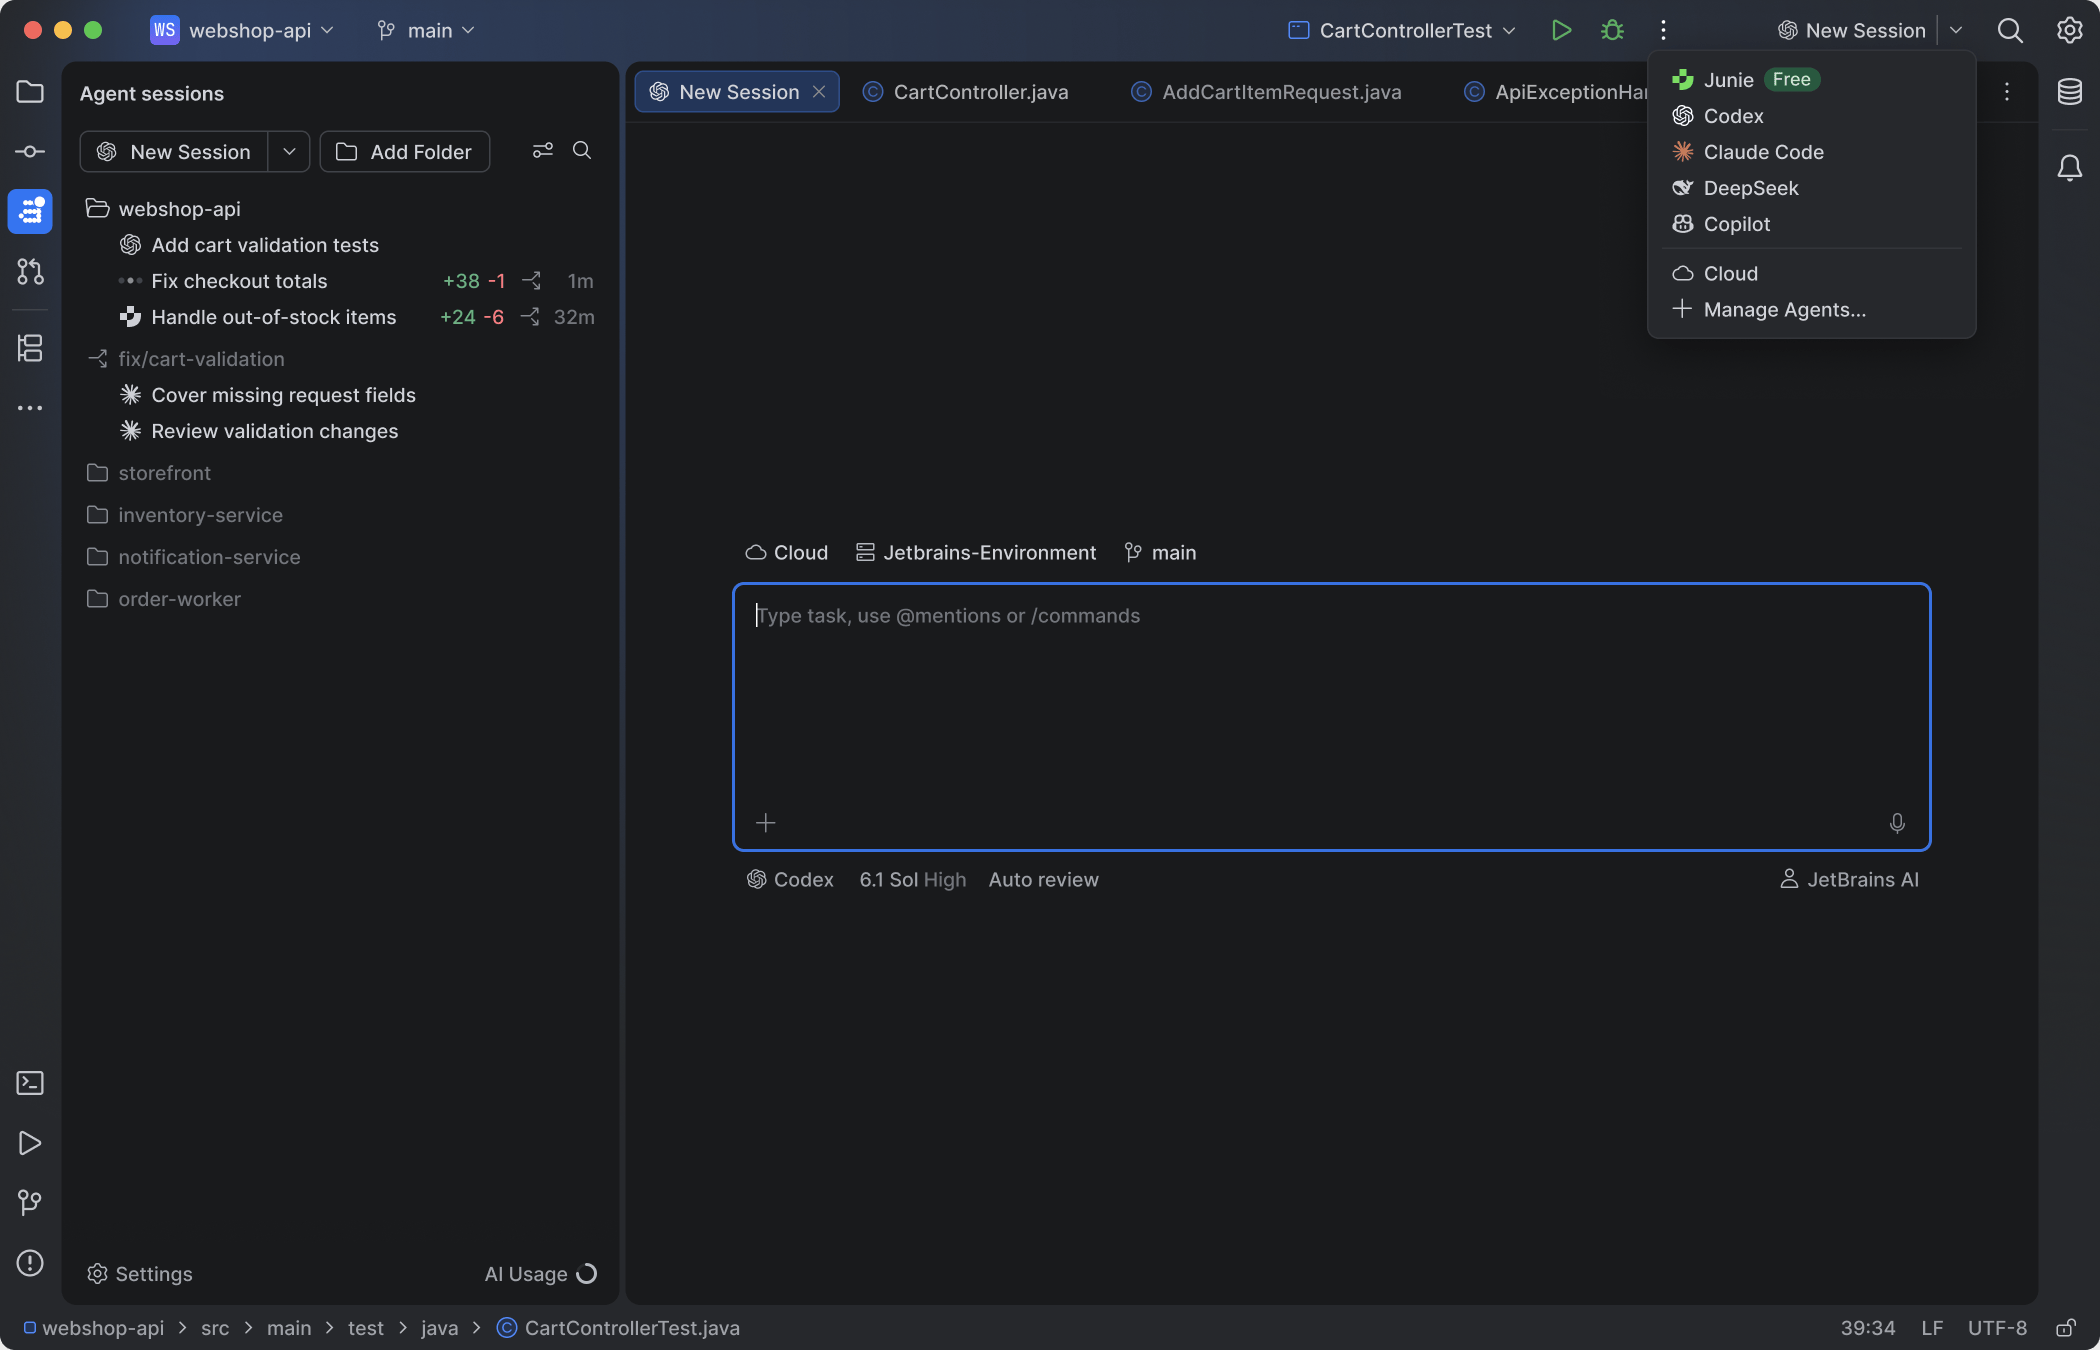
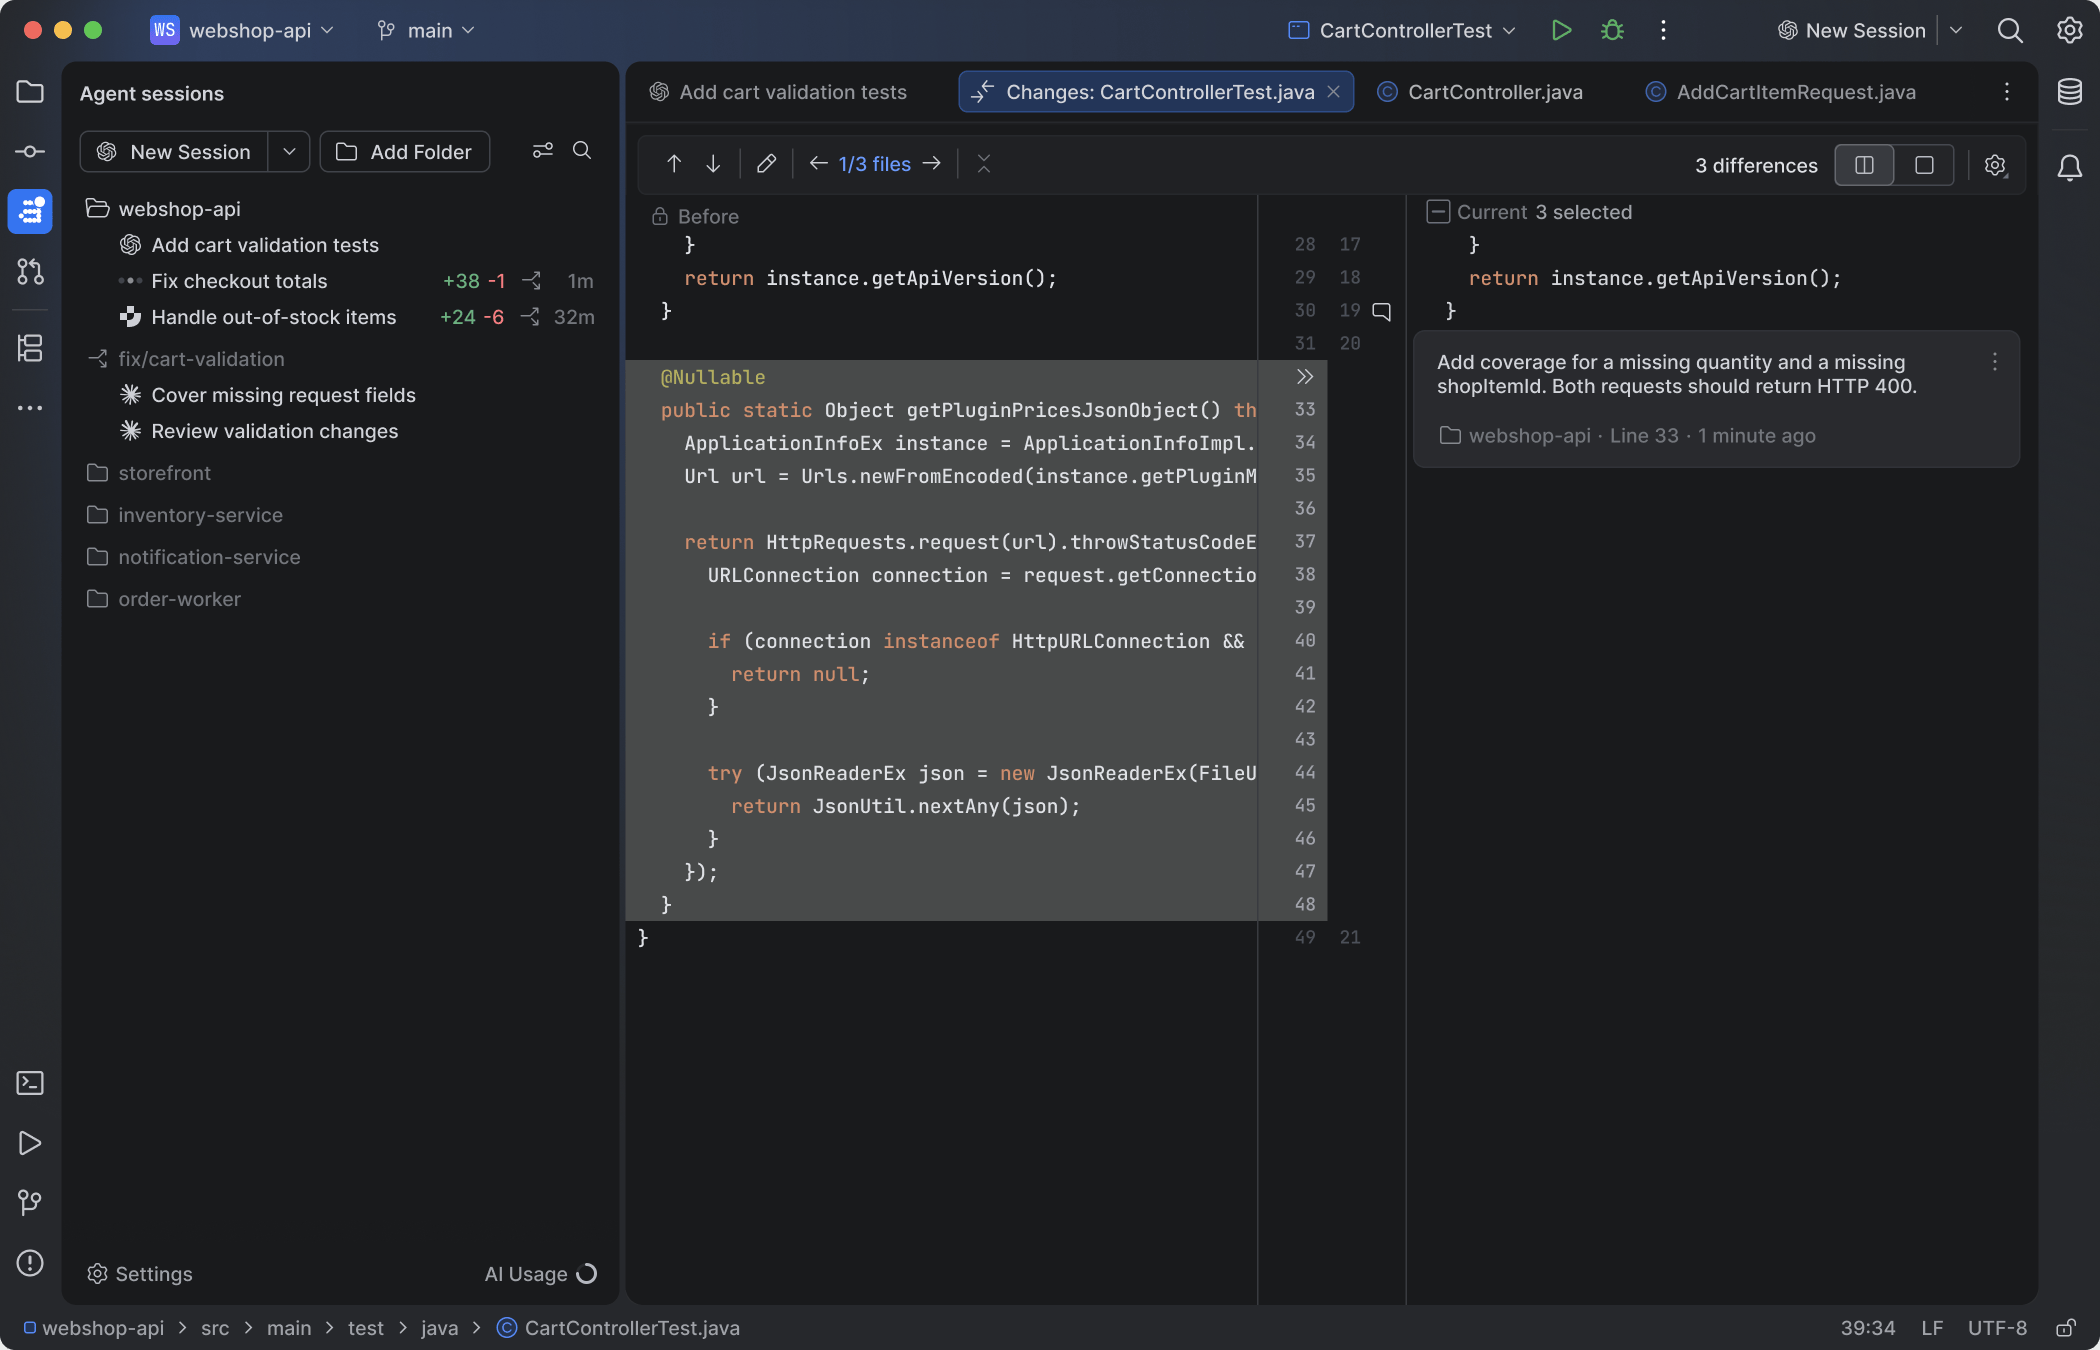
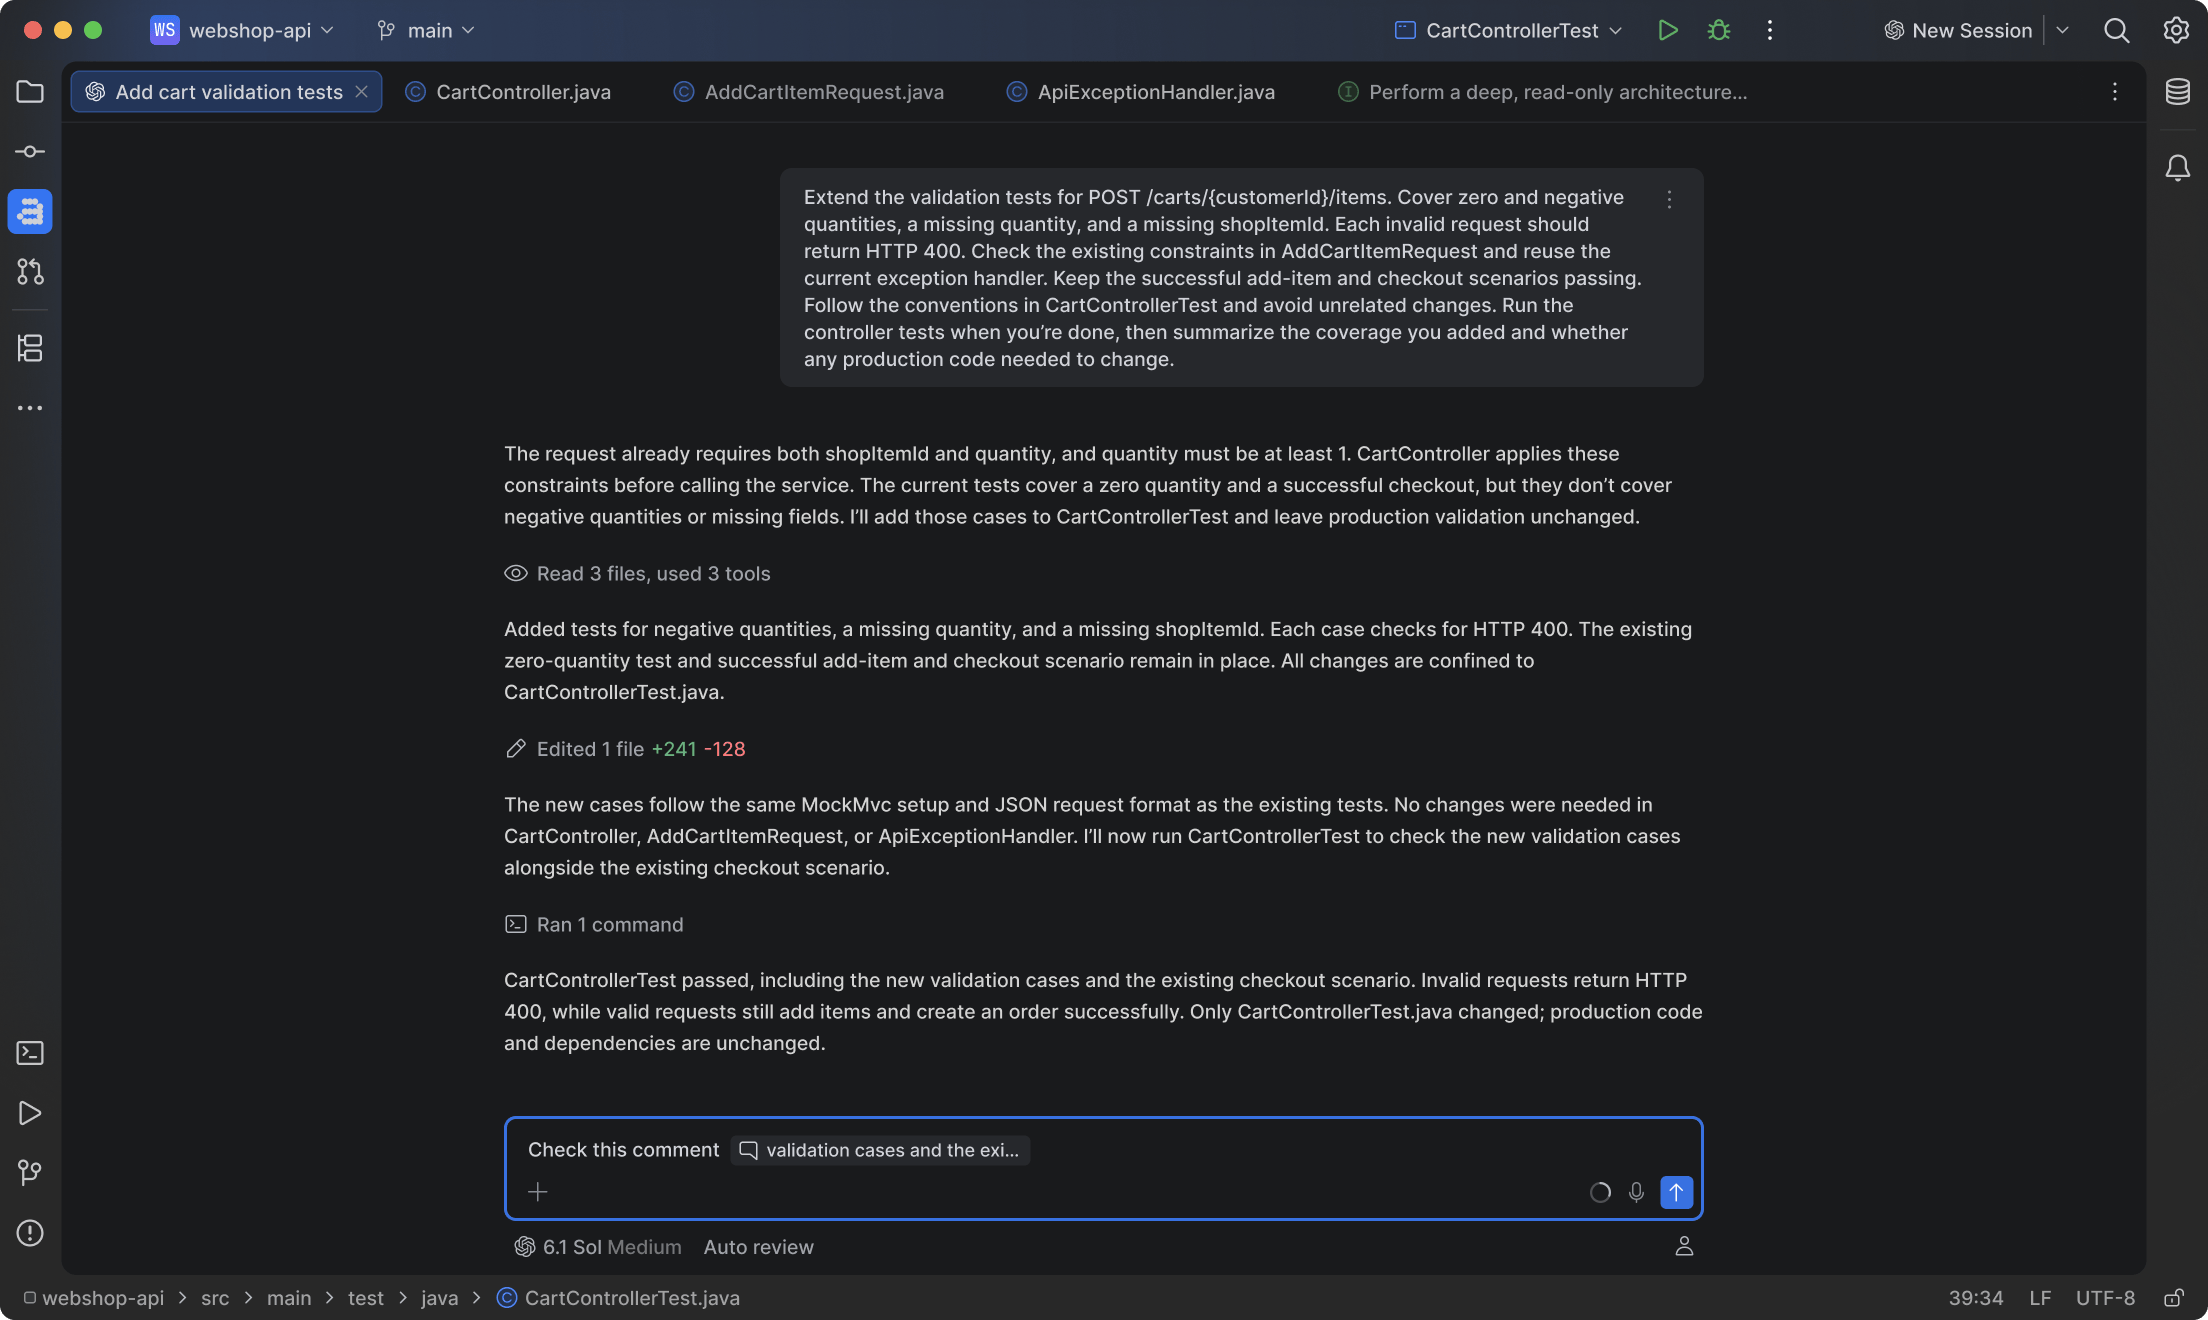
JetBrains Air works with the agents you already use, including Claude Agent, Codex, Gemini, GitHub Copilot, Junie, OpenCode, and other ACP-compatible agents. Your existing subscriptions and API keys carry over, with no JetBrains AI subscription required. Junie Lite gives you a free agent with just a JetBrains Account, and Junie can also work with models running locally through Ollama or LM Studio. When an agent makes changes, you can review them with the surrounding code in view and anchor notes to specific lines in the diff, so the agent knows exactly what to fix.
Read debugger views at a glance
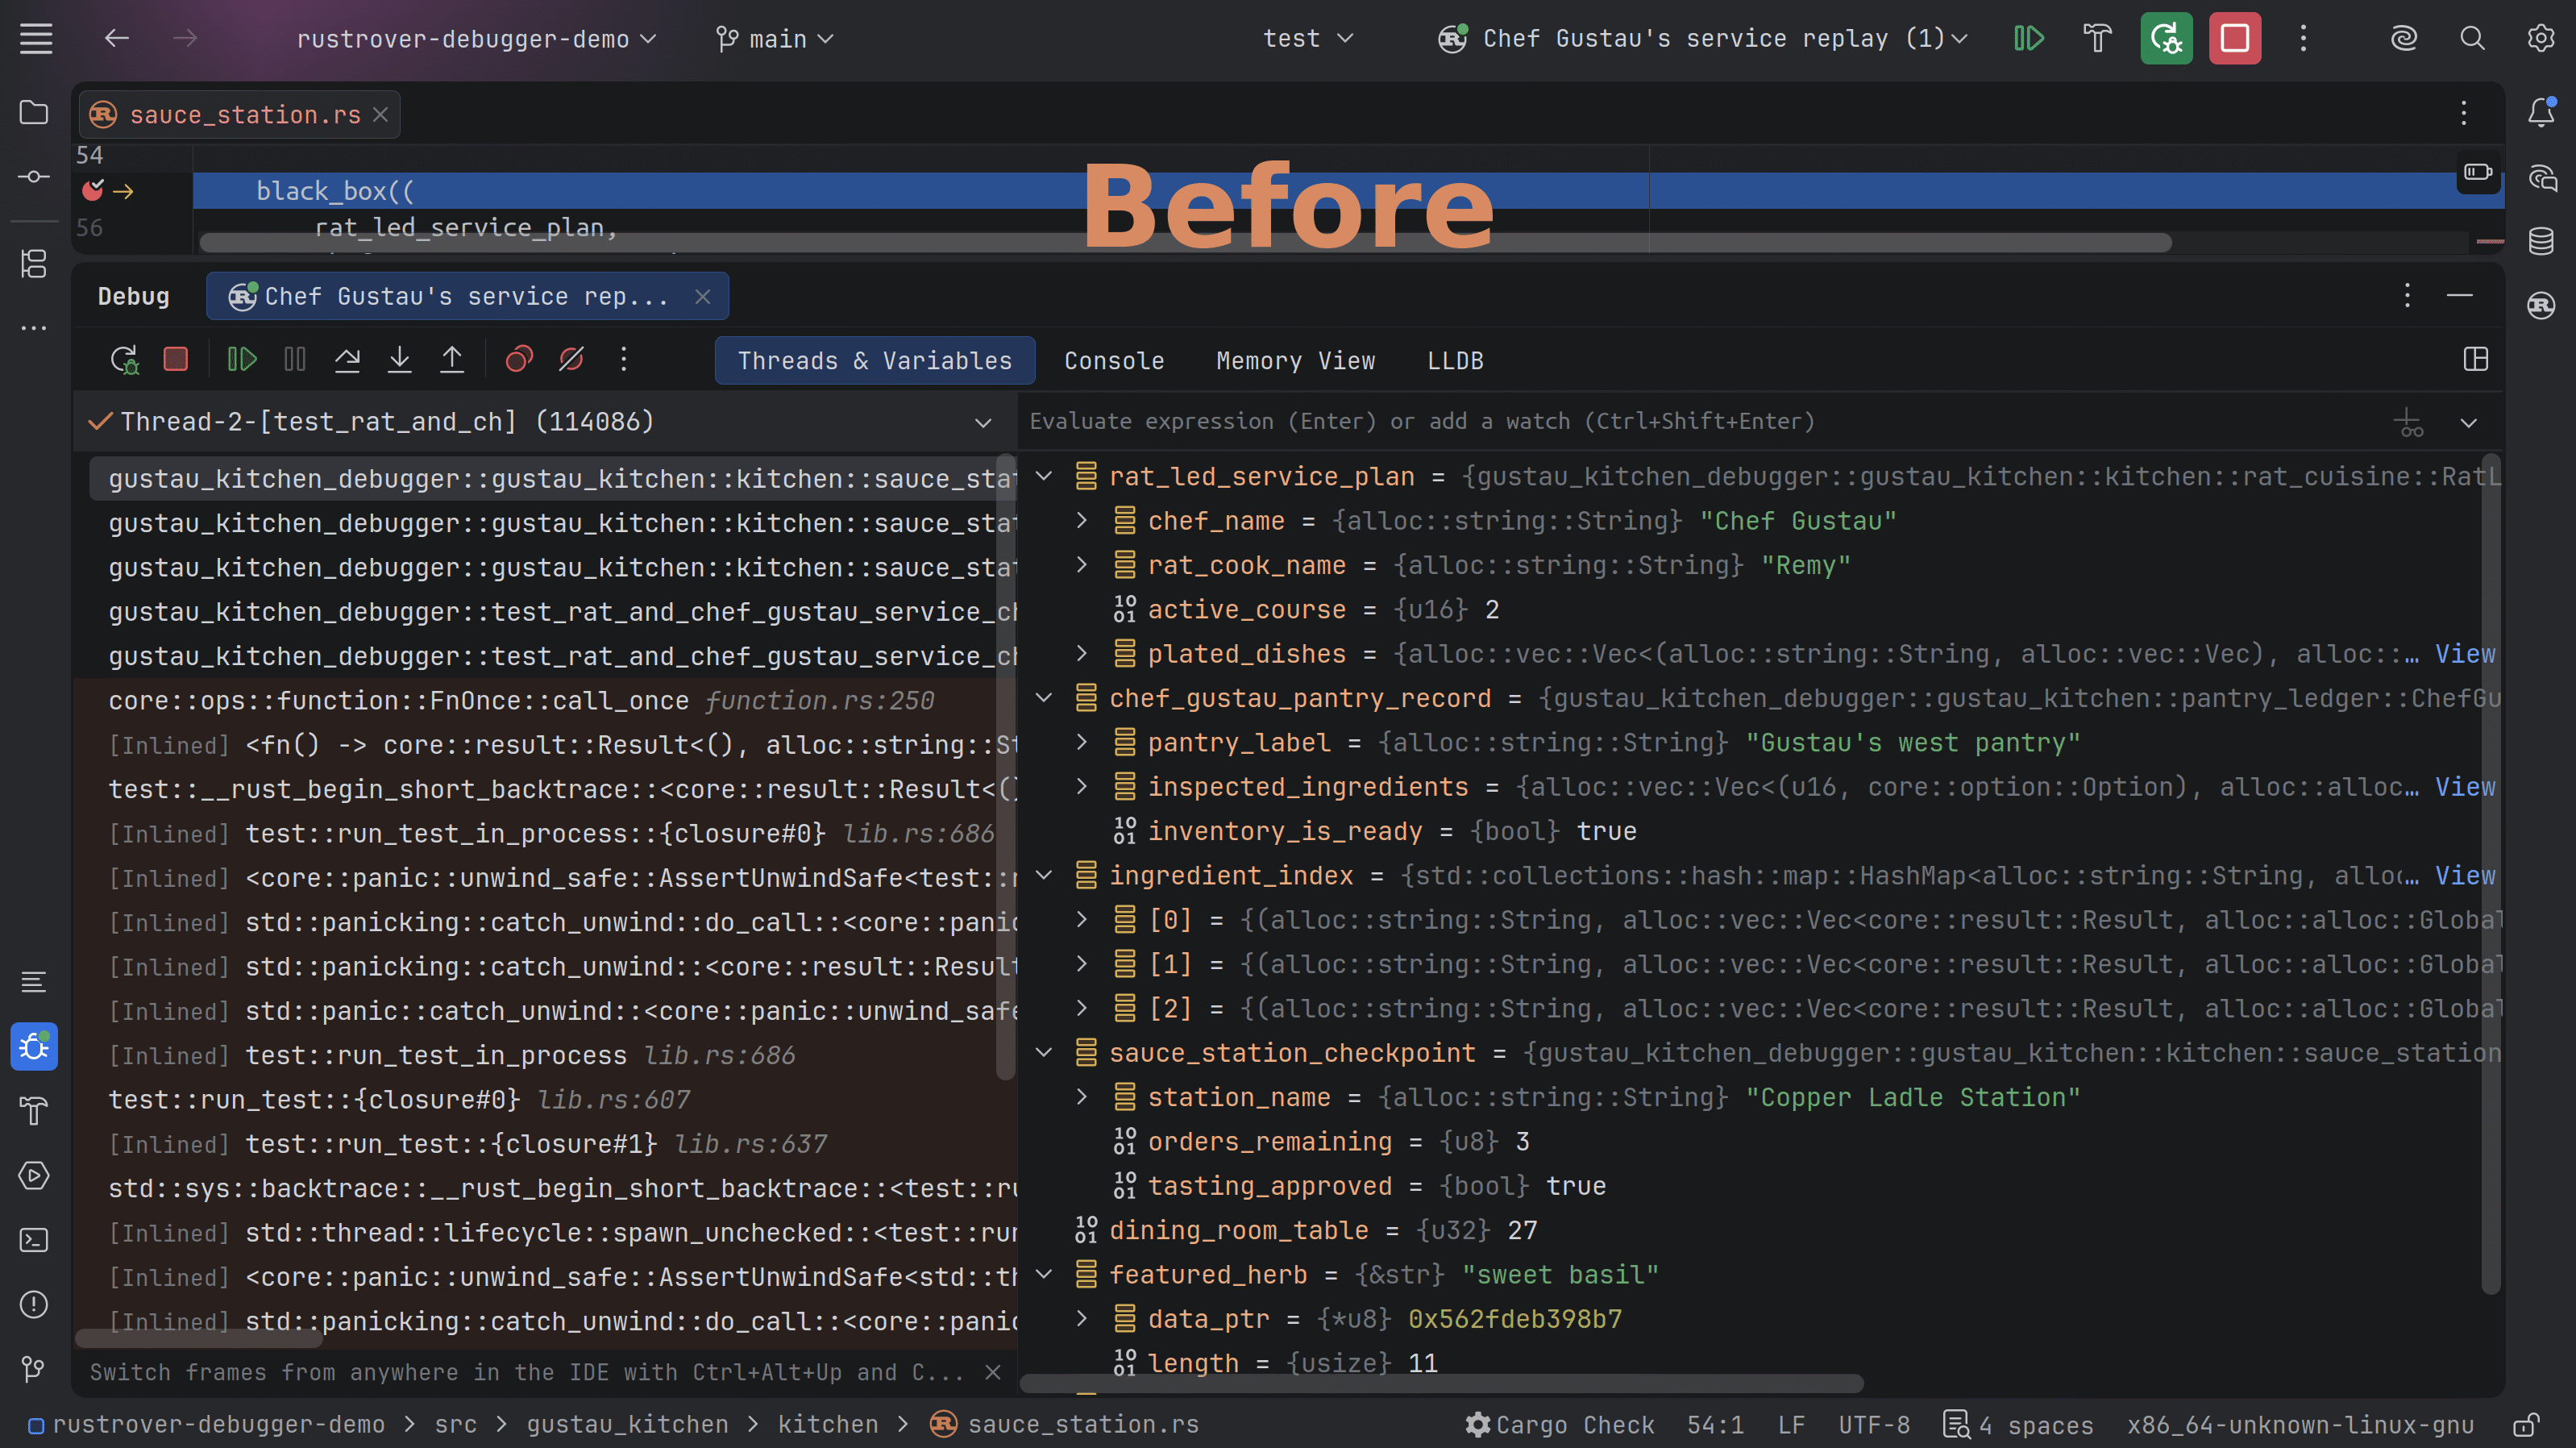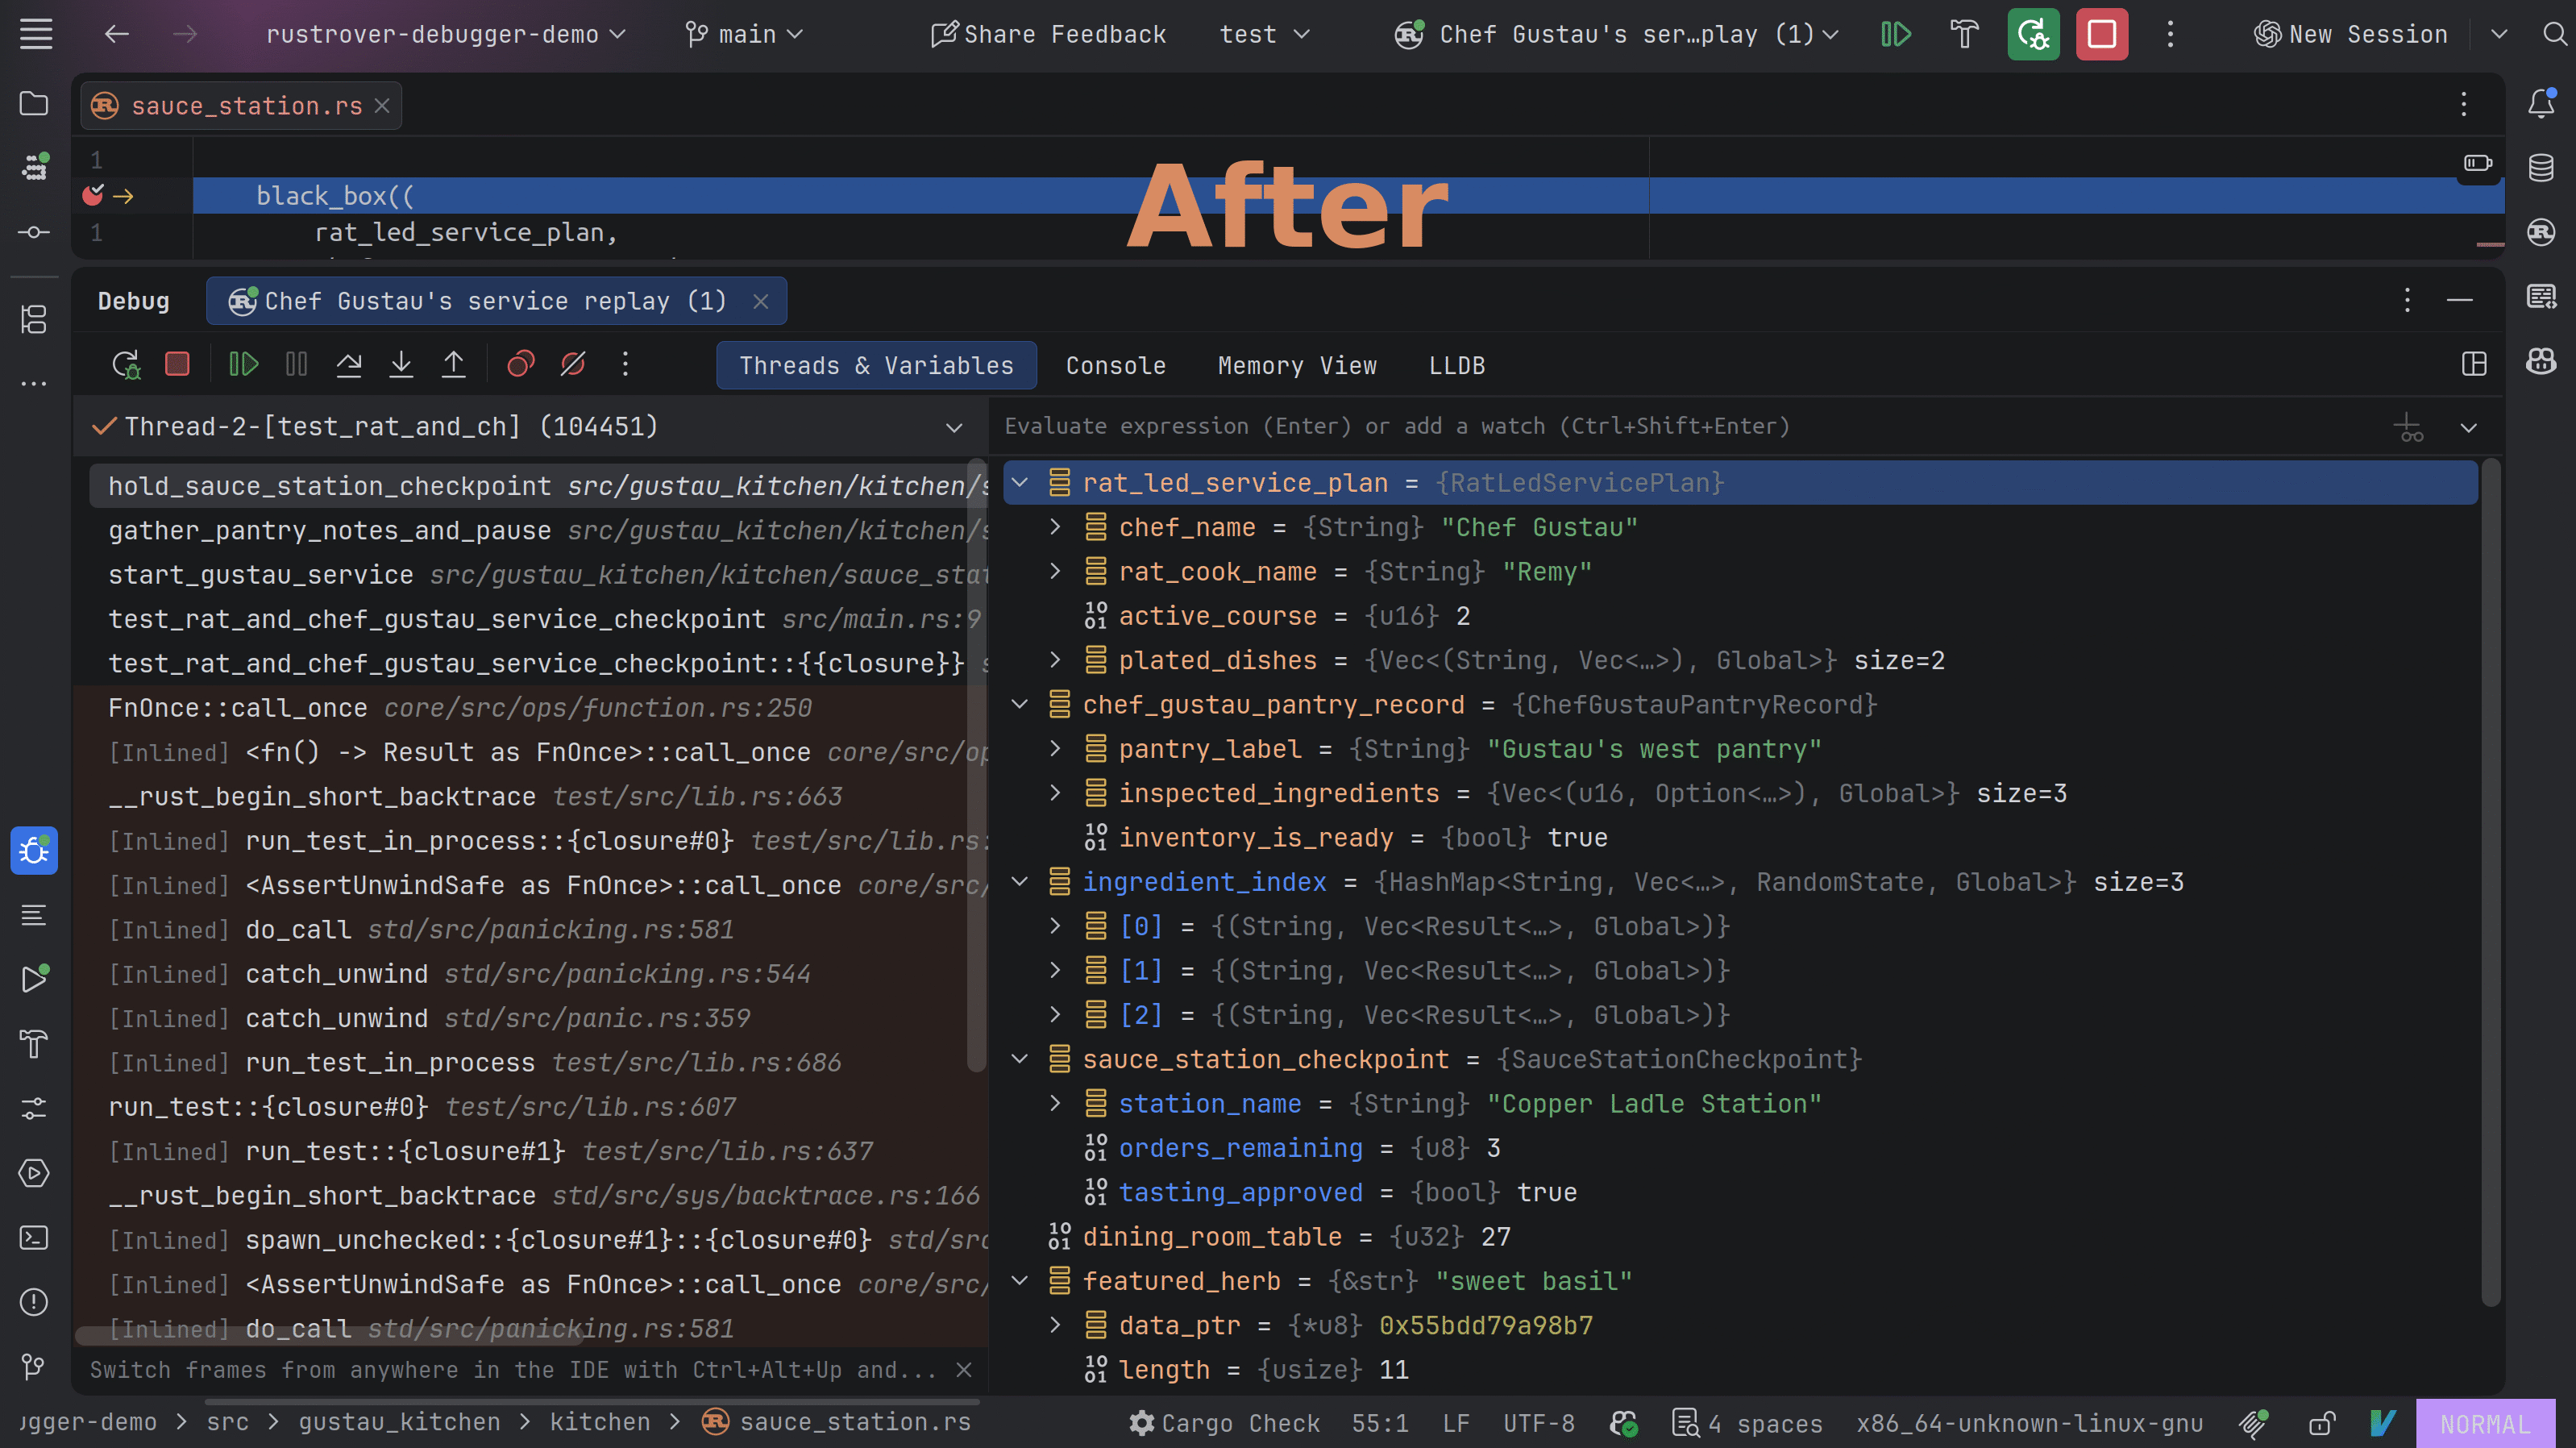
Long, fully qualified Rust names can crowd the debugger. RustRover now shortens type names in the Variables and Watches views and symbol names in the Frames view, so the program state and the call stack are easier to scan. Shortening is on by default, and you can turn it off in the settings.
Go from profiler results to the code behind them
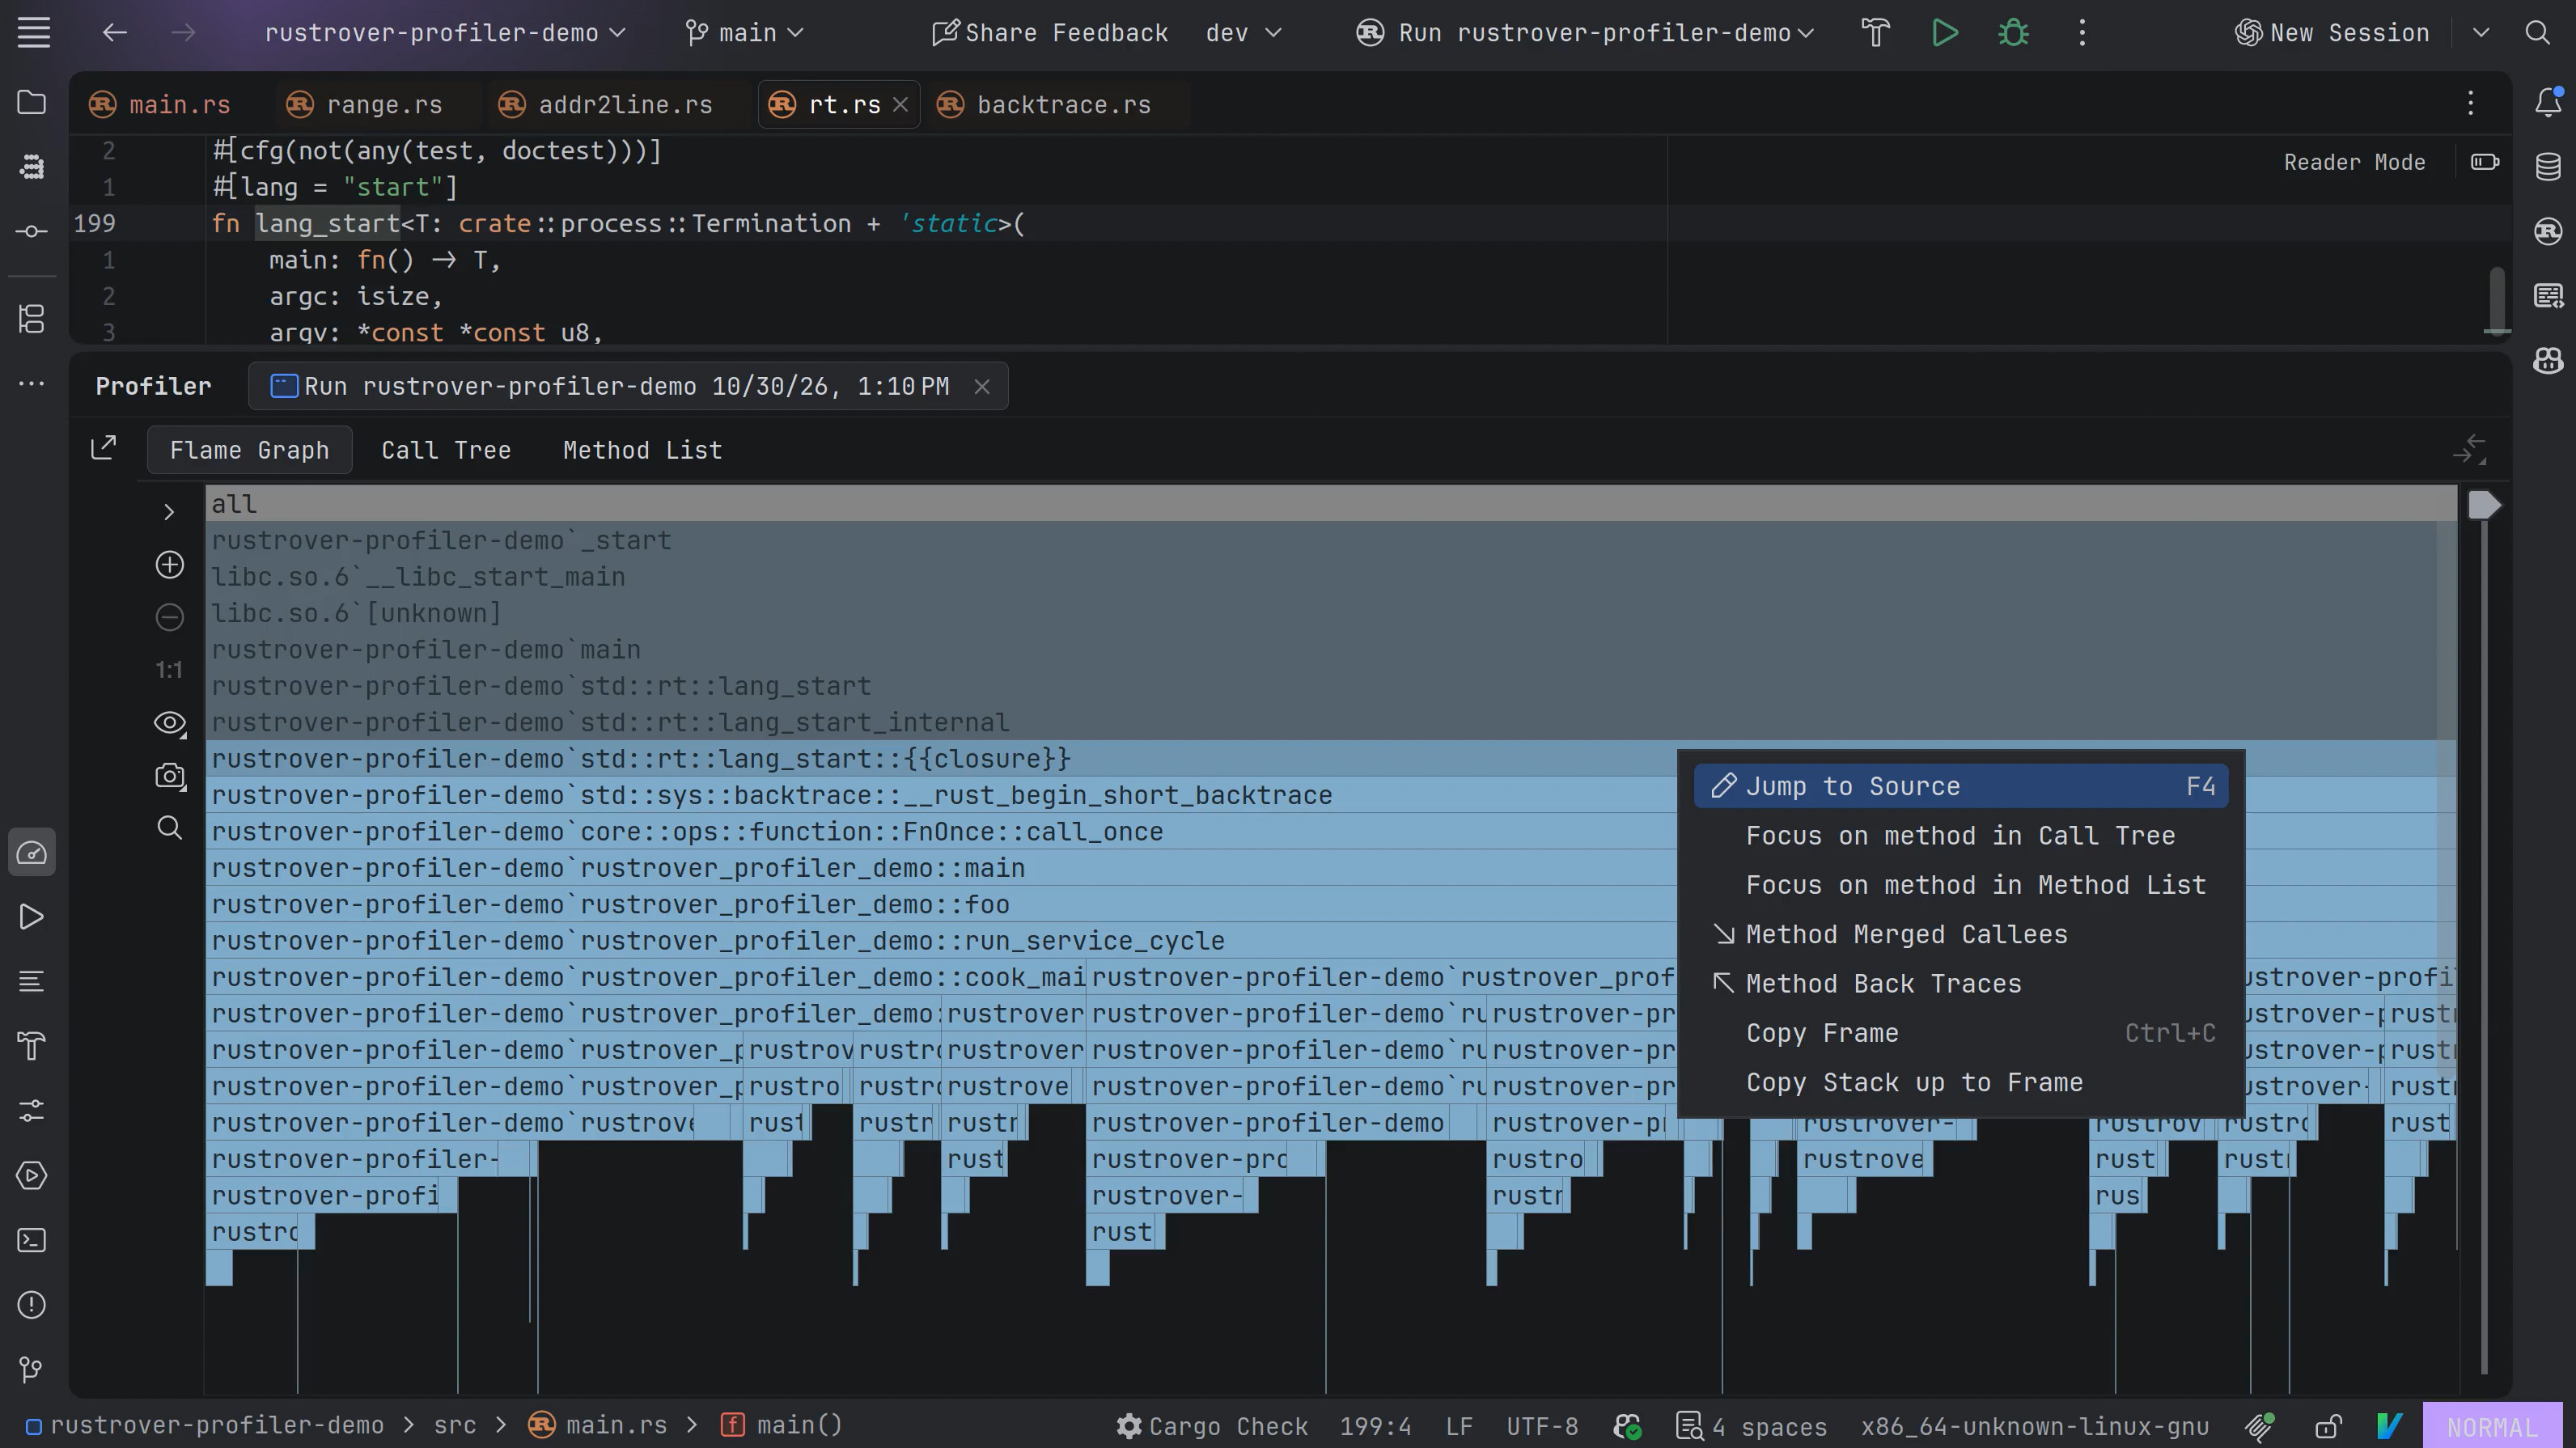
When profiler results point you to a hot spot, Jump to Source now opens the Rust function behind it instead of reporting Declaration not found. Function names in the results are readable instead of mangled. Both improvements work with perf on Linux and DTrace on macOS.
Let agents use the debugger
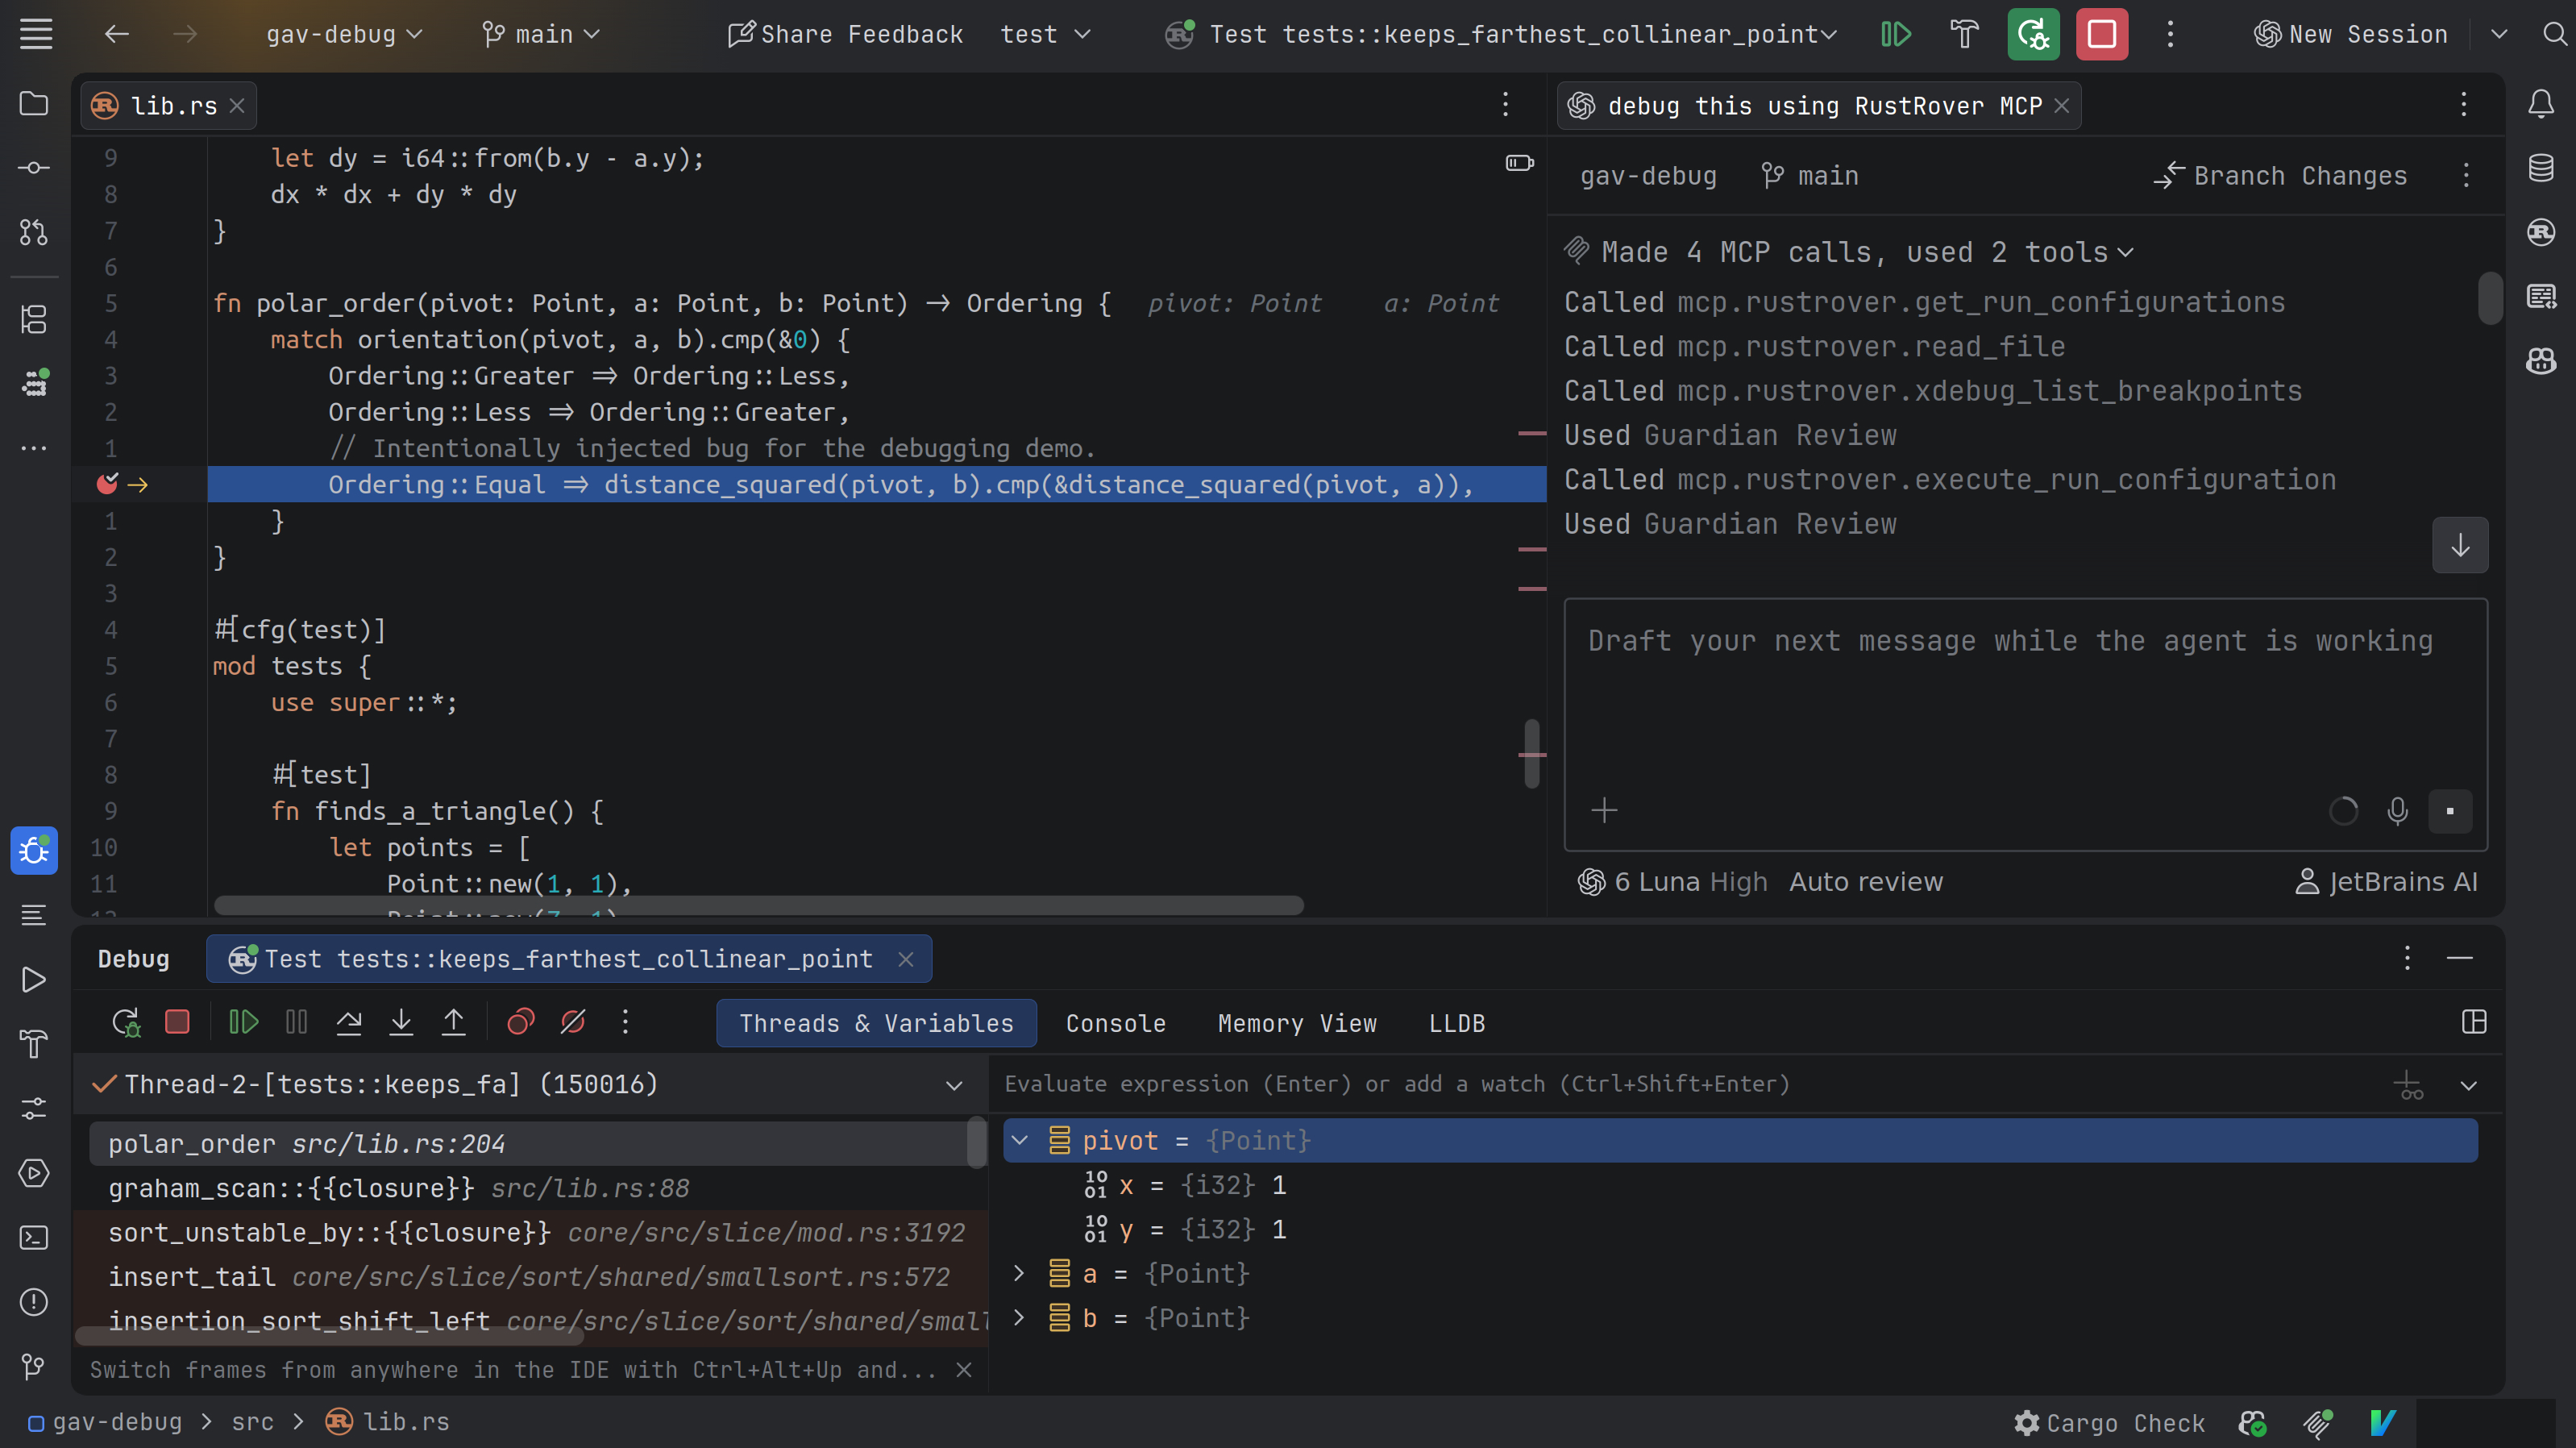
RustRover now provides a debugger MCP server and a rustrover-debugger skill that teaches agents how to use it. Instead of stepping through the code yourself, you describe the problem in natural language and let the agent collect the runtime evidence: set breakpoints, step through code, inspect variables, and evaluate expressions. This helps you find issues that are hard to spot from the source code and logs alone, such as a value that’s wrong only at runtime. The agent drives the regular RustRover debugger, so you can follow the session and take over at any point.
To get started, enable the MCP server, then enable and install the rustrover-debugger skill for RustRover or your agent of choice. You’ll find the corresponding settings in Settings | AI.
Work on remote machines without leaving RustRover
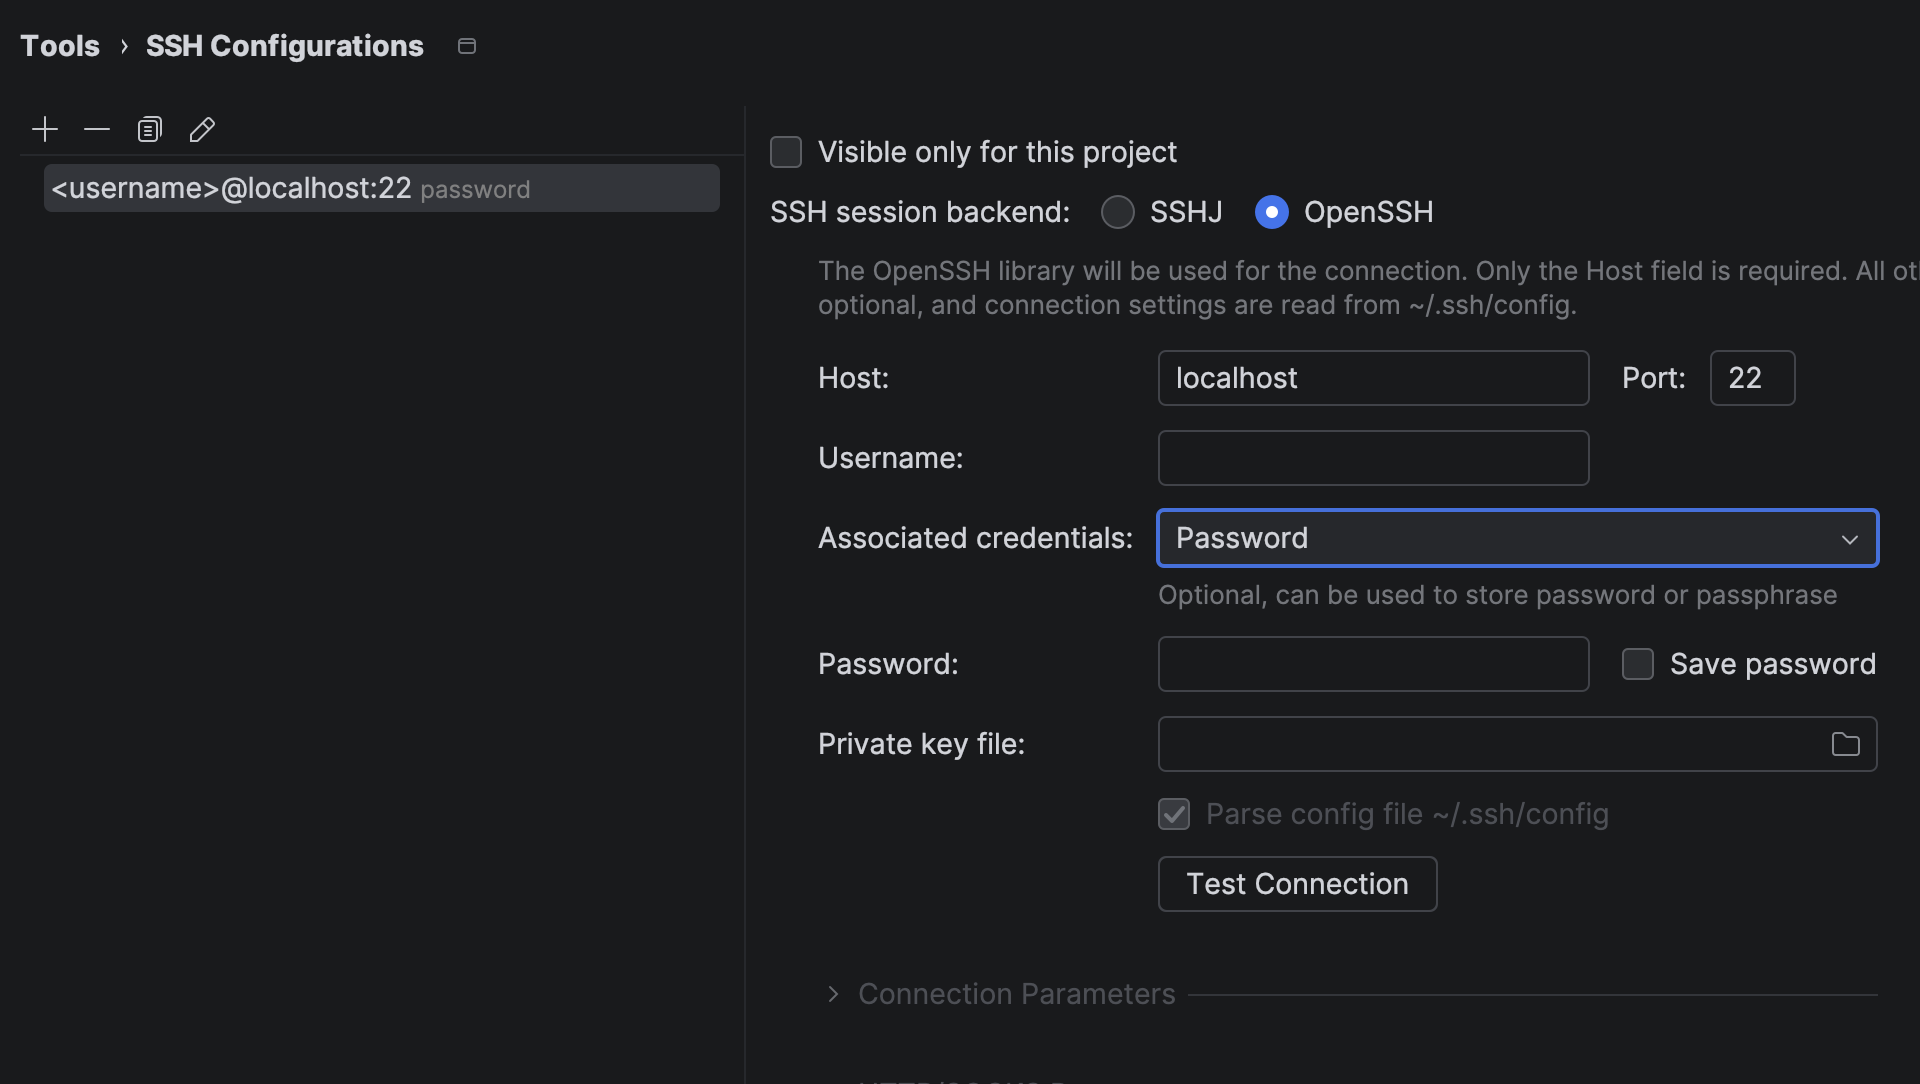
You can now work on projects hosted on a remote machine directly from RustRover. Connect to a host over SSH, start a development session, and reconnect to it later, all from the IDE. RustRover now uses native OpenSSH, so it works with the authentication methods your team already relies on, including certificate-based authentication, hardware security tokens such as YubiKey, and ProxyJump.
Help us fix what interrupts your work
RustRover 2026.3 automatically sends error and UI freeze reports to JetBrains, so we can prioritize fixes based on their real impact. Reports contain only technical data, and personal details such as file paths, URLs, and usernames are removed before they leave your machine. You can turn automatic reporting off in the settings. For more details, see the FAQ.
More in this release
RustRover 2026.3 also brings these IntelliJ Platform updates:
Sound cues: RustRover can now play sounds when builds, tests, and other background tasks finish, and screen reader users get audio cues for editor line marks. Learn more from this blog post.
Git worktrees: new worktrees now get a copy of your local project configuration.
Plugins page: installed and Marketplace plugins now appear in a single view.
Terminal: the terminal now uses the Ghostty emulator by default for better compatibility with modern CLI tools and terminal-based agents, and you can open terminal tabs in the editor, right next to your code. Learn more from this blog post.
The full list of changes is on the What’s New page.
Try RustRover 2026.3
Update to RustRover 2026.3 or download it from our website, and let us know what you think. Share your feedback in the comments below or in our issue tracker.
At the center of this release is JetBrains Air – a new layer for agentic development. It lets you run, track, and verify multi-agent workflows directly inside your IDE, with code intelligence keeping agents on track and complete review tools in your hands. This release also brings workspaces that adapt terminals and consoles to individual subprojects, initial support for Python 3.15 lazy imports, interactive FastAPI dependency graphs, and deeper Pydantic inspections, and so much more.
Check out an overview video by our developer advocate William Vincent:
Now, let’s take a closer look at the key highlights.
JetBrains Air in PyCharm – One place to run your agents and verify their work
As of this release, JetBrains IDEs ship with Air, a new layer for agentic development. Work with the coding agents of your choice, and run, track, and verify multi-agent workflows inside your IDE, where code intelligence helps agents make fewer wrong turns and gives you the tools to review every change before it ships.
Your agents, your models, your subscriptions – with Junie Lite for free
Air works with Claude Agent, Codex, Gemini, GitHub Copilot, Junie, OpenCode, and other ACP-compatible agents. It detects the agents already installed on your machine so you can connect them in a click, and you can add more from the agent registry.
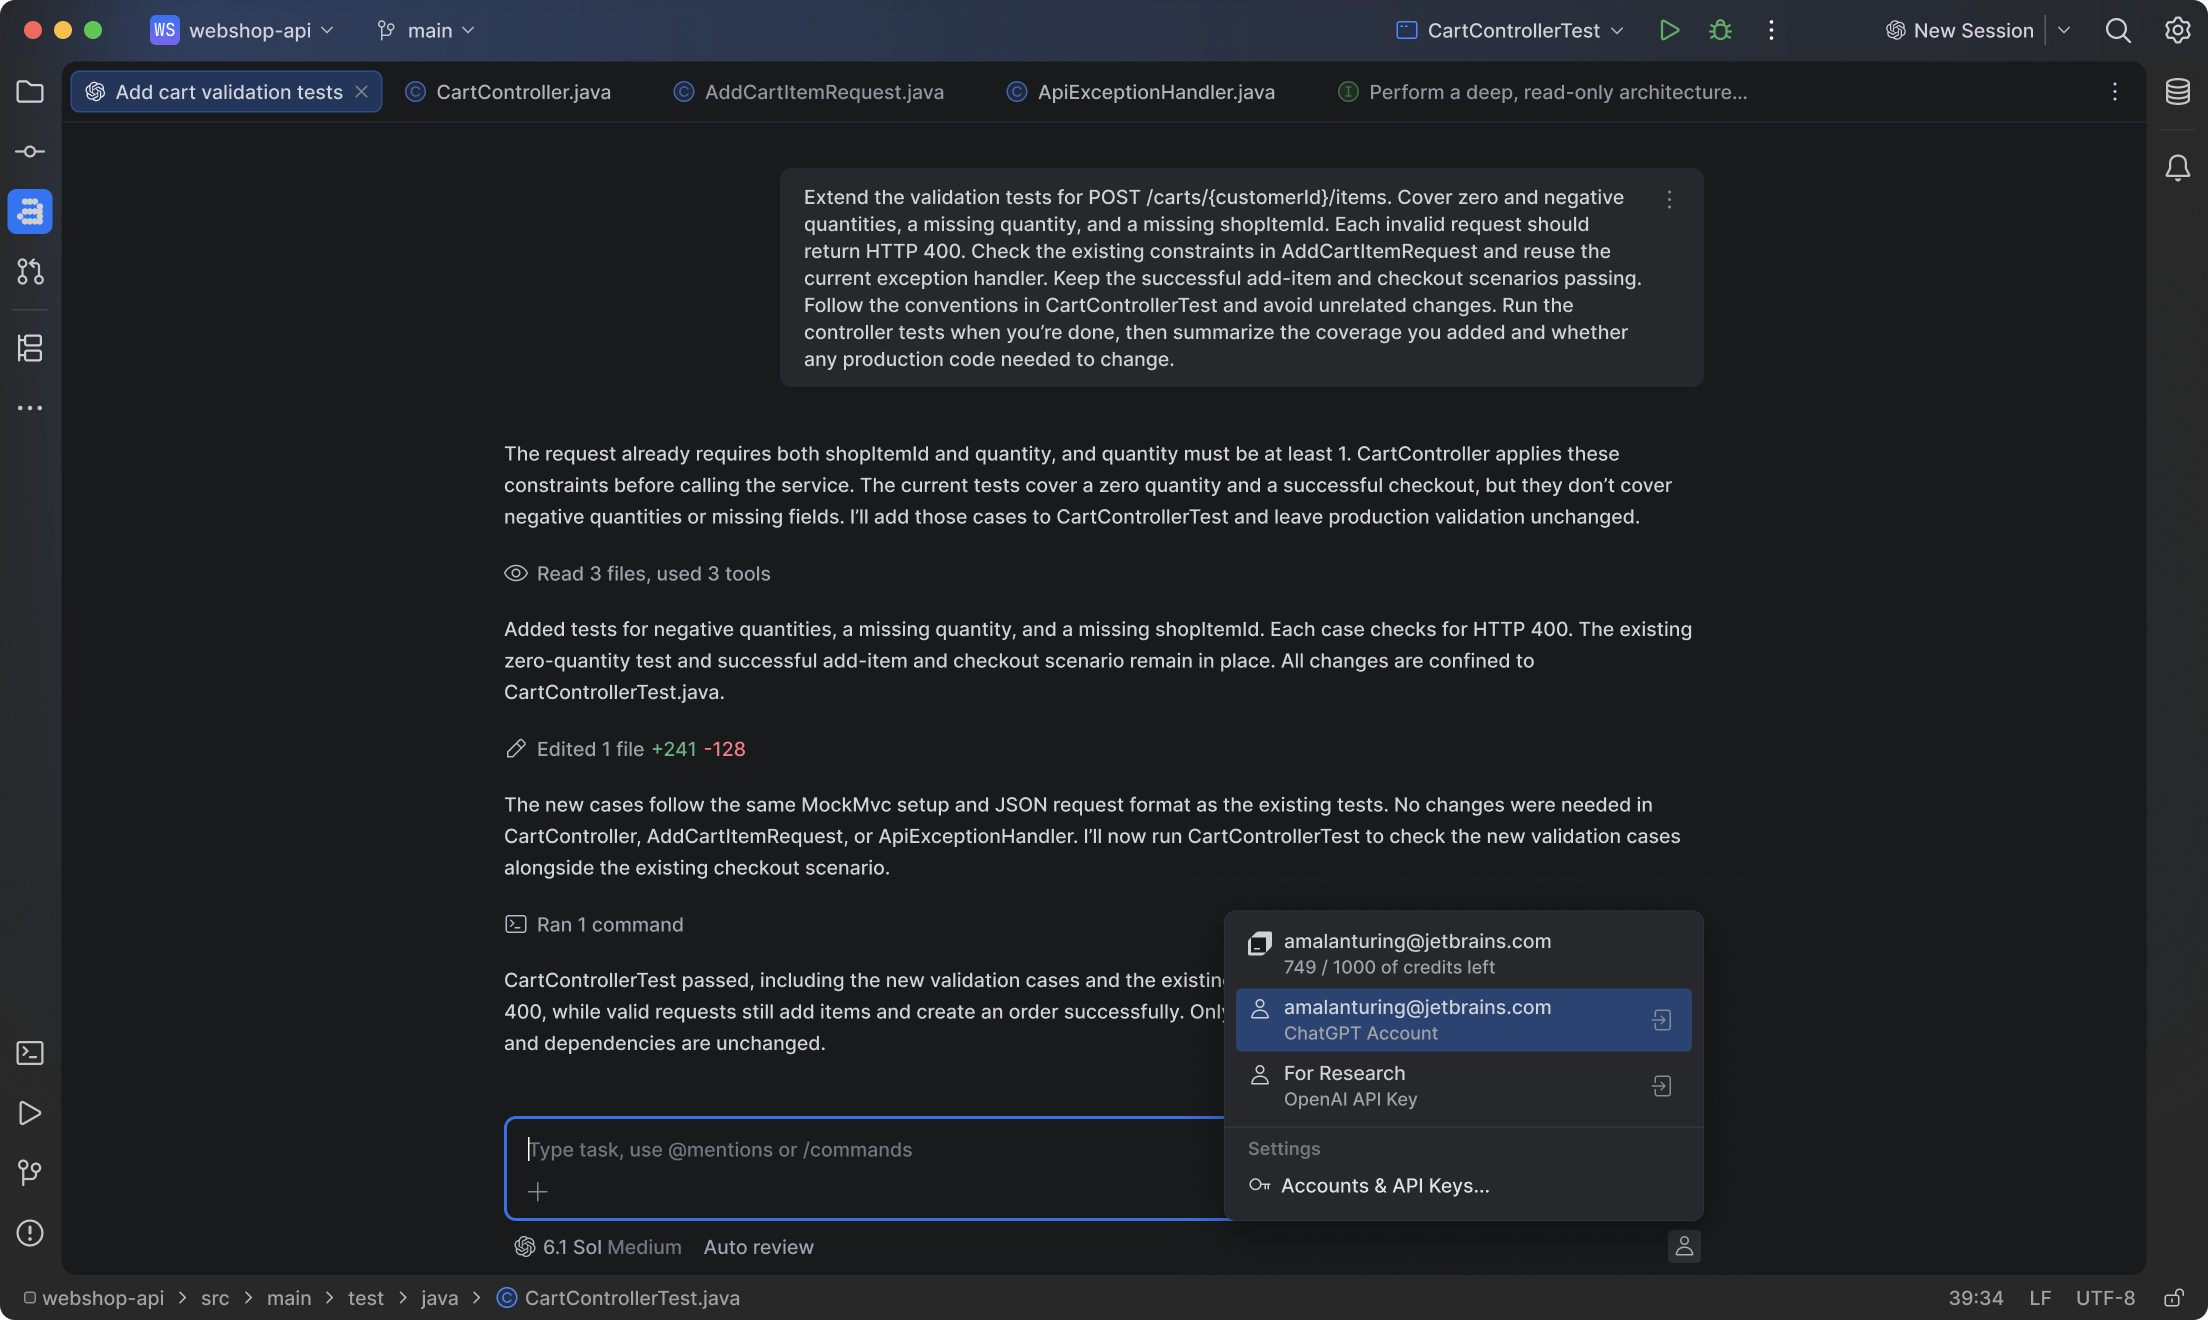
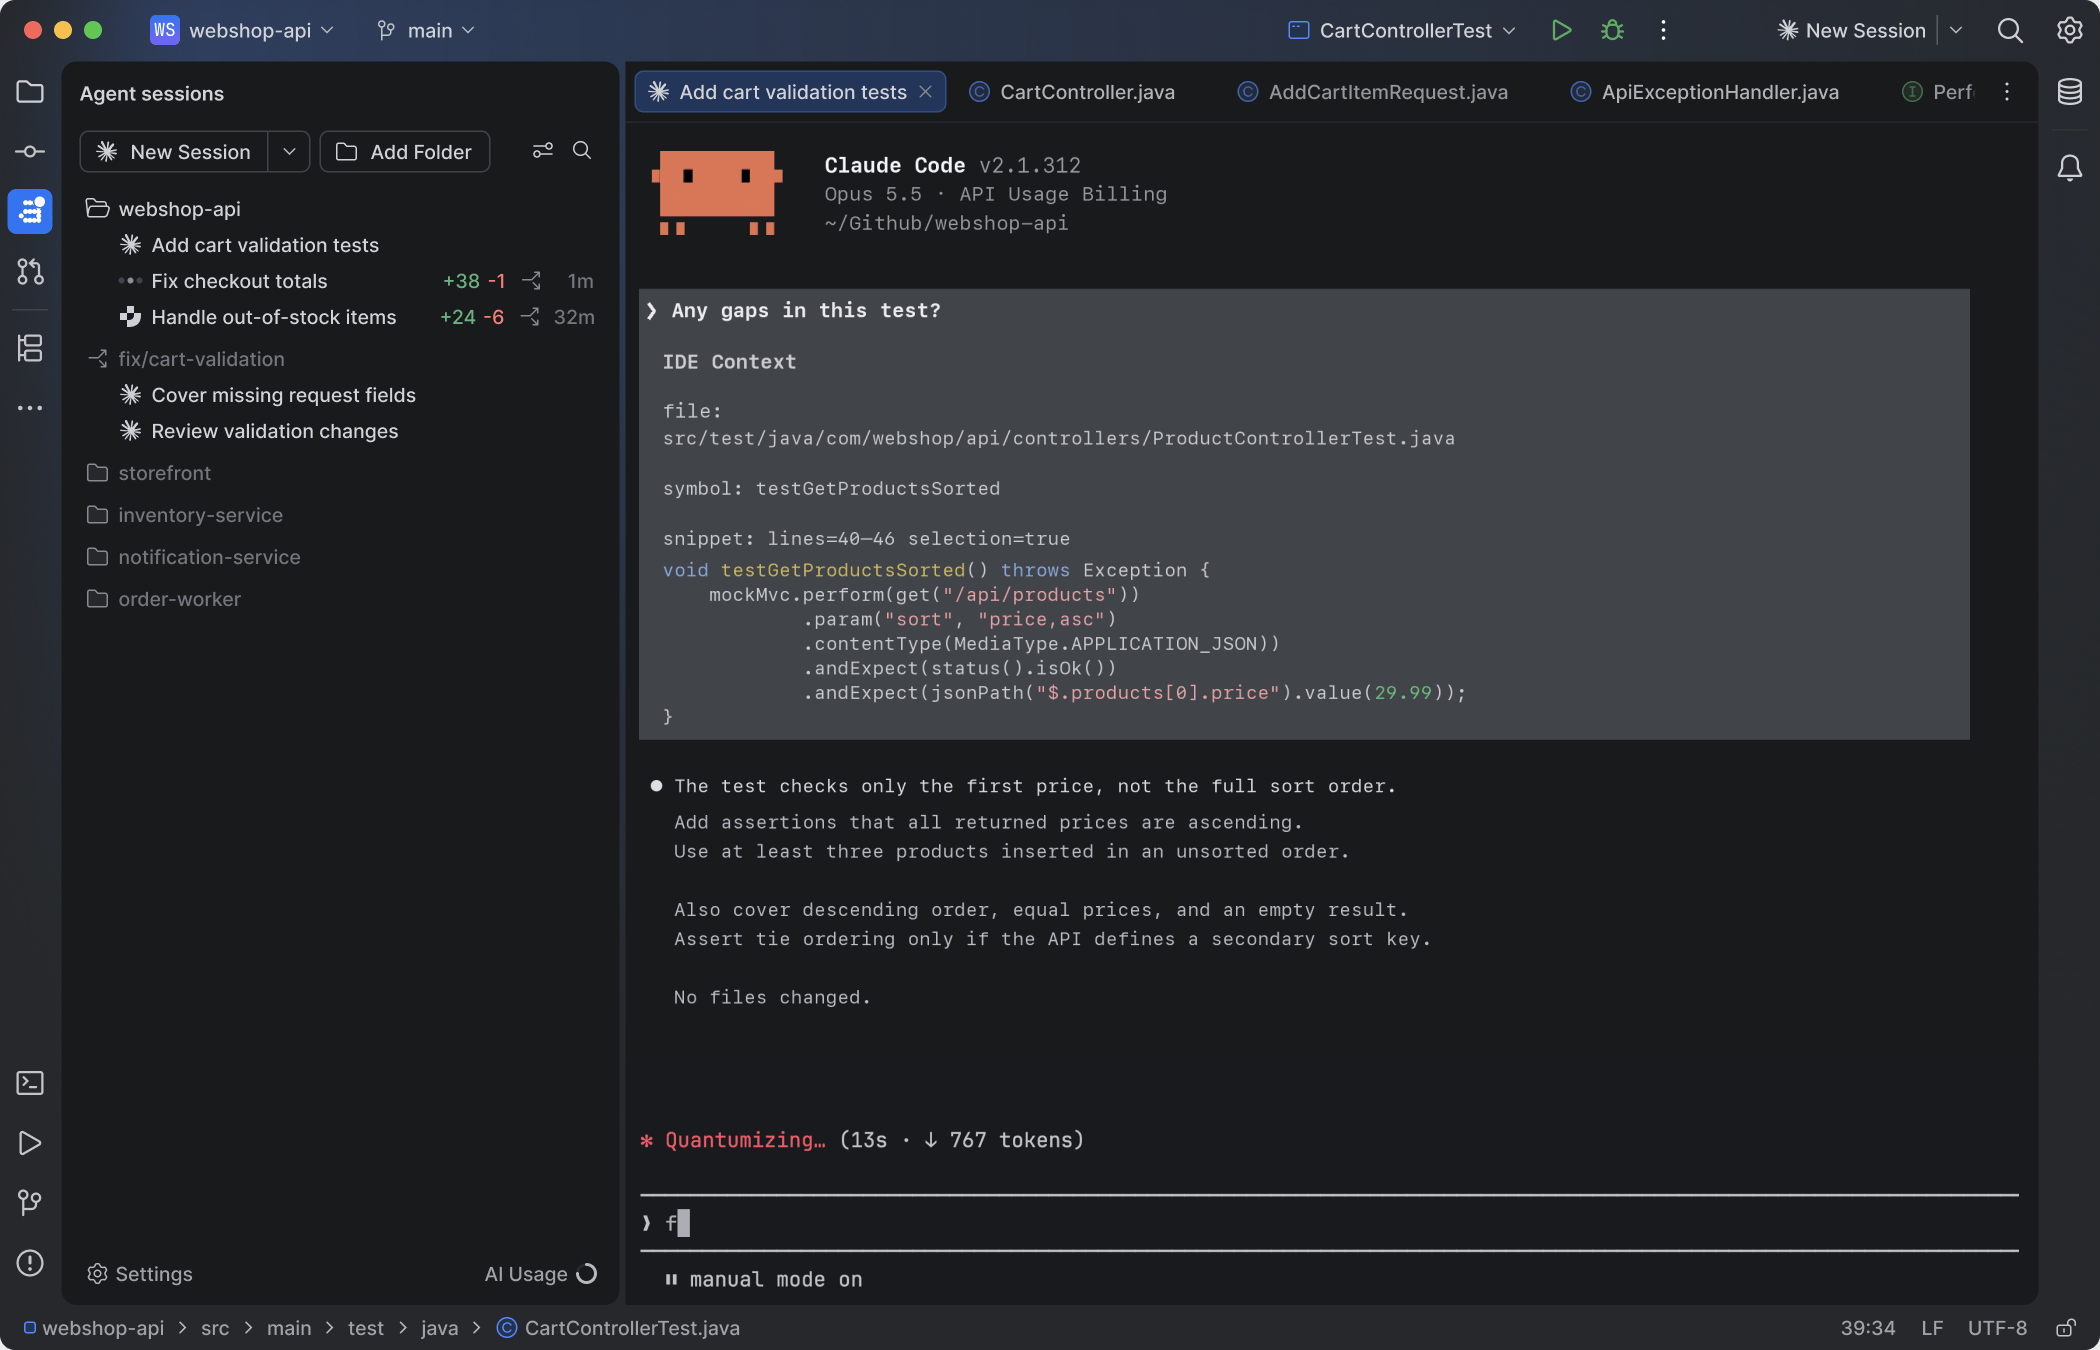
Your existing setup carries over, too: provider subscriptions, API keys, and even a custom base URL all work, with no JetBrains AI subscription required. Run Claude Agent on your Claude subscription in the terminal or in a full-screen IDE tab, use other agent subscriptions in the chat or terminal, and switch between subscriptions at any moment, even mid-session.
Air includes free AI with the Junie Lite configuration, so you can use an agent without a subscription. You only need a JetBrains Account.
A central workspace to review changes and guide the agent
Review an agent’s changes with the surrounding code and your project tools in view, and send feedback straight back to the agent. Anchor a note to a specific line in the diff, or comment directly from the code, so the agent gets concrete context about the change you want. Work in the chat or the terminal, whichever suits you.
Still using AI Assistant? A notification will offer you a trial of Air. Moving to Air hides AI Assistant, if you wish to return to AI Assistant follow the steps outlined here. Air automatically migrates your IDE skills, MCP configuration, agents installed through ACP, authentication, and chat history. Chat mode history isn’t migrated.
Workspace support
A console and terminal for each subproject
Each subproject has its own Python console and terminal running in its own environment, so you run code against the dependencies that subproject actually uses. In uv workspaces, the console uses the workspace environment and adds the subproject root to sys.path.
Right-click a subproject and select Open in | Python console to start a console for it.
Open a terminal while a subproject file is in the editor to run commands in that subproject’s environment.
Subproject creation and conversion
You can add a new subproject or convert an existing folder from the Project tool window context menu. The subproject is initialized using uv, Hatch, or Poetry, and automatically added as a workspace member to your root pyproject.toml in uv workspaces.
Python 3.15 lazy imports
PyCharm now supports the lazy import syntax introduced in Python 3.15. A lazy import defers loading a module until it’s first used, which can noticeably cut startup time in applications and scripts with heavy dependencies. PyCharm parses and resolves lazy imports like regular ones, so you can adopt the syntax without giving up code insight on the names you import.
An endpoint can depend on a chain of Depends() and Security() calls spread across many files. PyCharm draws that chain as a graph for any endpoint. Each dependency is marked as yield or return, and circular dependencies, which raise a RuntimeError at startup, are flagged in the editor. In the other direction, a dependency shows which endpoints rely on it, directly or through other dependencies.
You can open the graph from the gutter icon next to an endpoint or click the endpoint count above a dependency to see its usages.
Python interpreter widget
The redesigned Python interpreter widget in the status bar is built around the tools that manage your environments, such as uv, Poetry, Hatch, and conda. It detects the ones installed on your machine and lists the environments each one manages for your project.
Environments created from the command line also appear under their tool. To start working in one, open the widget, select the tool, and pick the environment. To recreate it with a different Python version, choose Recreate Environment under Current Environment. If the Python version you choose isn’t installed, you’ll be prompted to download it.
Pydantic support
PyCharm now provides deeper editor support for Pydantic models. Field constraints, validators, and configuration are read from the model’s declaration and used across the editor.
Values passed to a model are checked against its Field() constraints, such as min_length, max_length, gt, and lt, with a warning displayed when one is broken.
A field name inside @field_validator('price') now resolves to that field’s definition, letting you jump straight to it.
Code completion suggests configuration options in a model’s class arguments, such as validate_by_name and validate_by_alias.
What you see here only scratches the surface of what is included in PyCharm 2026.3. From editing standalone files in the new Home window to full SQLAlchemy ORM support, automatic project configuration copy in Git worktrees, and remote development directly from the IDE via SSH – there is plenty more to explore across code insight, testing, environments, and version control.
Head over to the What’s new in PyCharm 2026.3 page to see the complete list of features, performance improvements, and fixes.
We would love to hear how JetBrains Air and the new workspace tooling fit into your day-to-day work – share your thoughts in the comments below or submit feedback directly in our issue tracker.
 Log in