Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162042 stories
·
33 followers

Assessing Your AI Needs

1 Share

Deciding on an AI solution starts with two factors: where the capability should live and how much freedom it needs while running. Use this guide to assess your needs.

An AI feature may need repeatable instructions or access to internal knowledge, and it may also need tool use or a multi-step workflow. Those requirements describe what the feature must do without settling how we should build and deliver it.

Teams often use skills and plugins interchangeably with hosted AI assistants and systems, and they may call the same AI capability an agent. These terms describe different parts of the design: how we package and deliver the capability as well as how much discretion it has at runtime.

In this article, we’ll evaluate these options by asking where the experience must live and what we want to reuse, then deciding what we would want to control and whether we can define the steps in advance.

Ownership & Runtime Behavior

Our first decision is about packaging and ownership: what we create and how people access it.

  • A skill packages instructions and supporting resources for a repeatable workflow.
  • A plugin packages skills and tools for distribution through a supported AI host.
  • A hosted AI assistant packages a configured conversational experience that people can use directly through an existing AI platform.
  • An AI system places the model inside an application we build and operate, giving us ownership of the interface and backend as well as data access and controls.

Runtime behavior is a separate decision about how much discretion the software needs while completing a task. Because runtime behavior is separate from packaging, these options can overlap within the same solution.

A system can load a skill that an agent follows, and a hosted AI assistant can use uploaded knowledge and tool connections within a product surface we don’t own.

OptionPrimary decision it answersStrong fitWhat we ownMain constraint
SkillHow do we reuse a method?A repeated workflow in an existing AI hostInstructions and supporting resourcesThe host still supplies the interface and runtime
PluginHow do we distribute skills and tools?An installable capability for a supported AI hostInstructions and tool connections; optional UIThe host still supplies the product surface and runtime
Hosted AI AssistantHow do we share a configured experience?An internal assistant or a quick pilot in an existing AI platformConfiguration and uploaded knowledge; conversation starters and connectionsThe host owns the product surface and runtime
SystemHow do we ship an AI capability in our product?A feature tied to product users and permissioned dataExperience and backend; permissions and operationsWe carry the engineering and operating cost
AgentHow should the software choose its next step?Work whose path changes as new information arrivesTools and limits; approval points and the execution loopGreater latency and cost with more failure paths

The diagram below maps these options across ownership and runtime behavior, showing where they can overlap within the same solution.
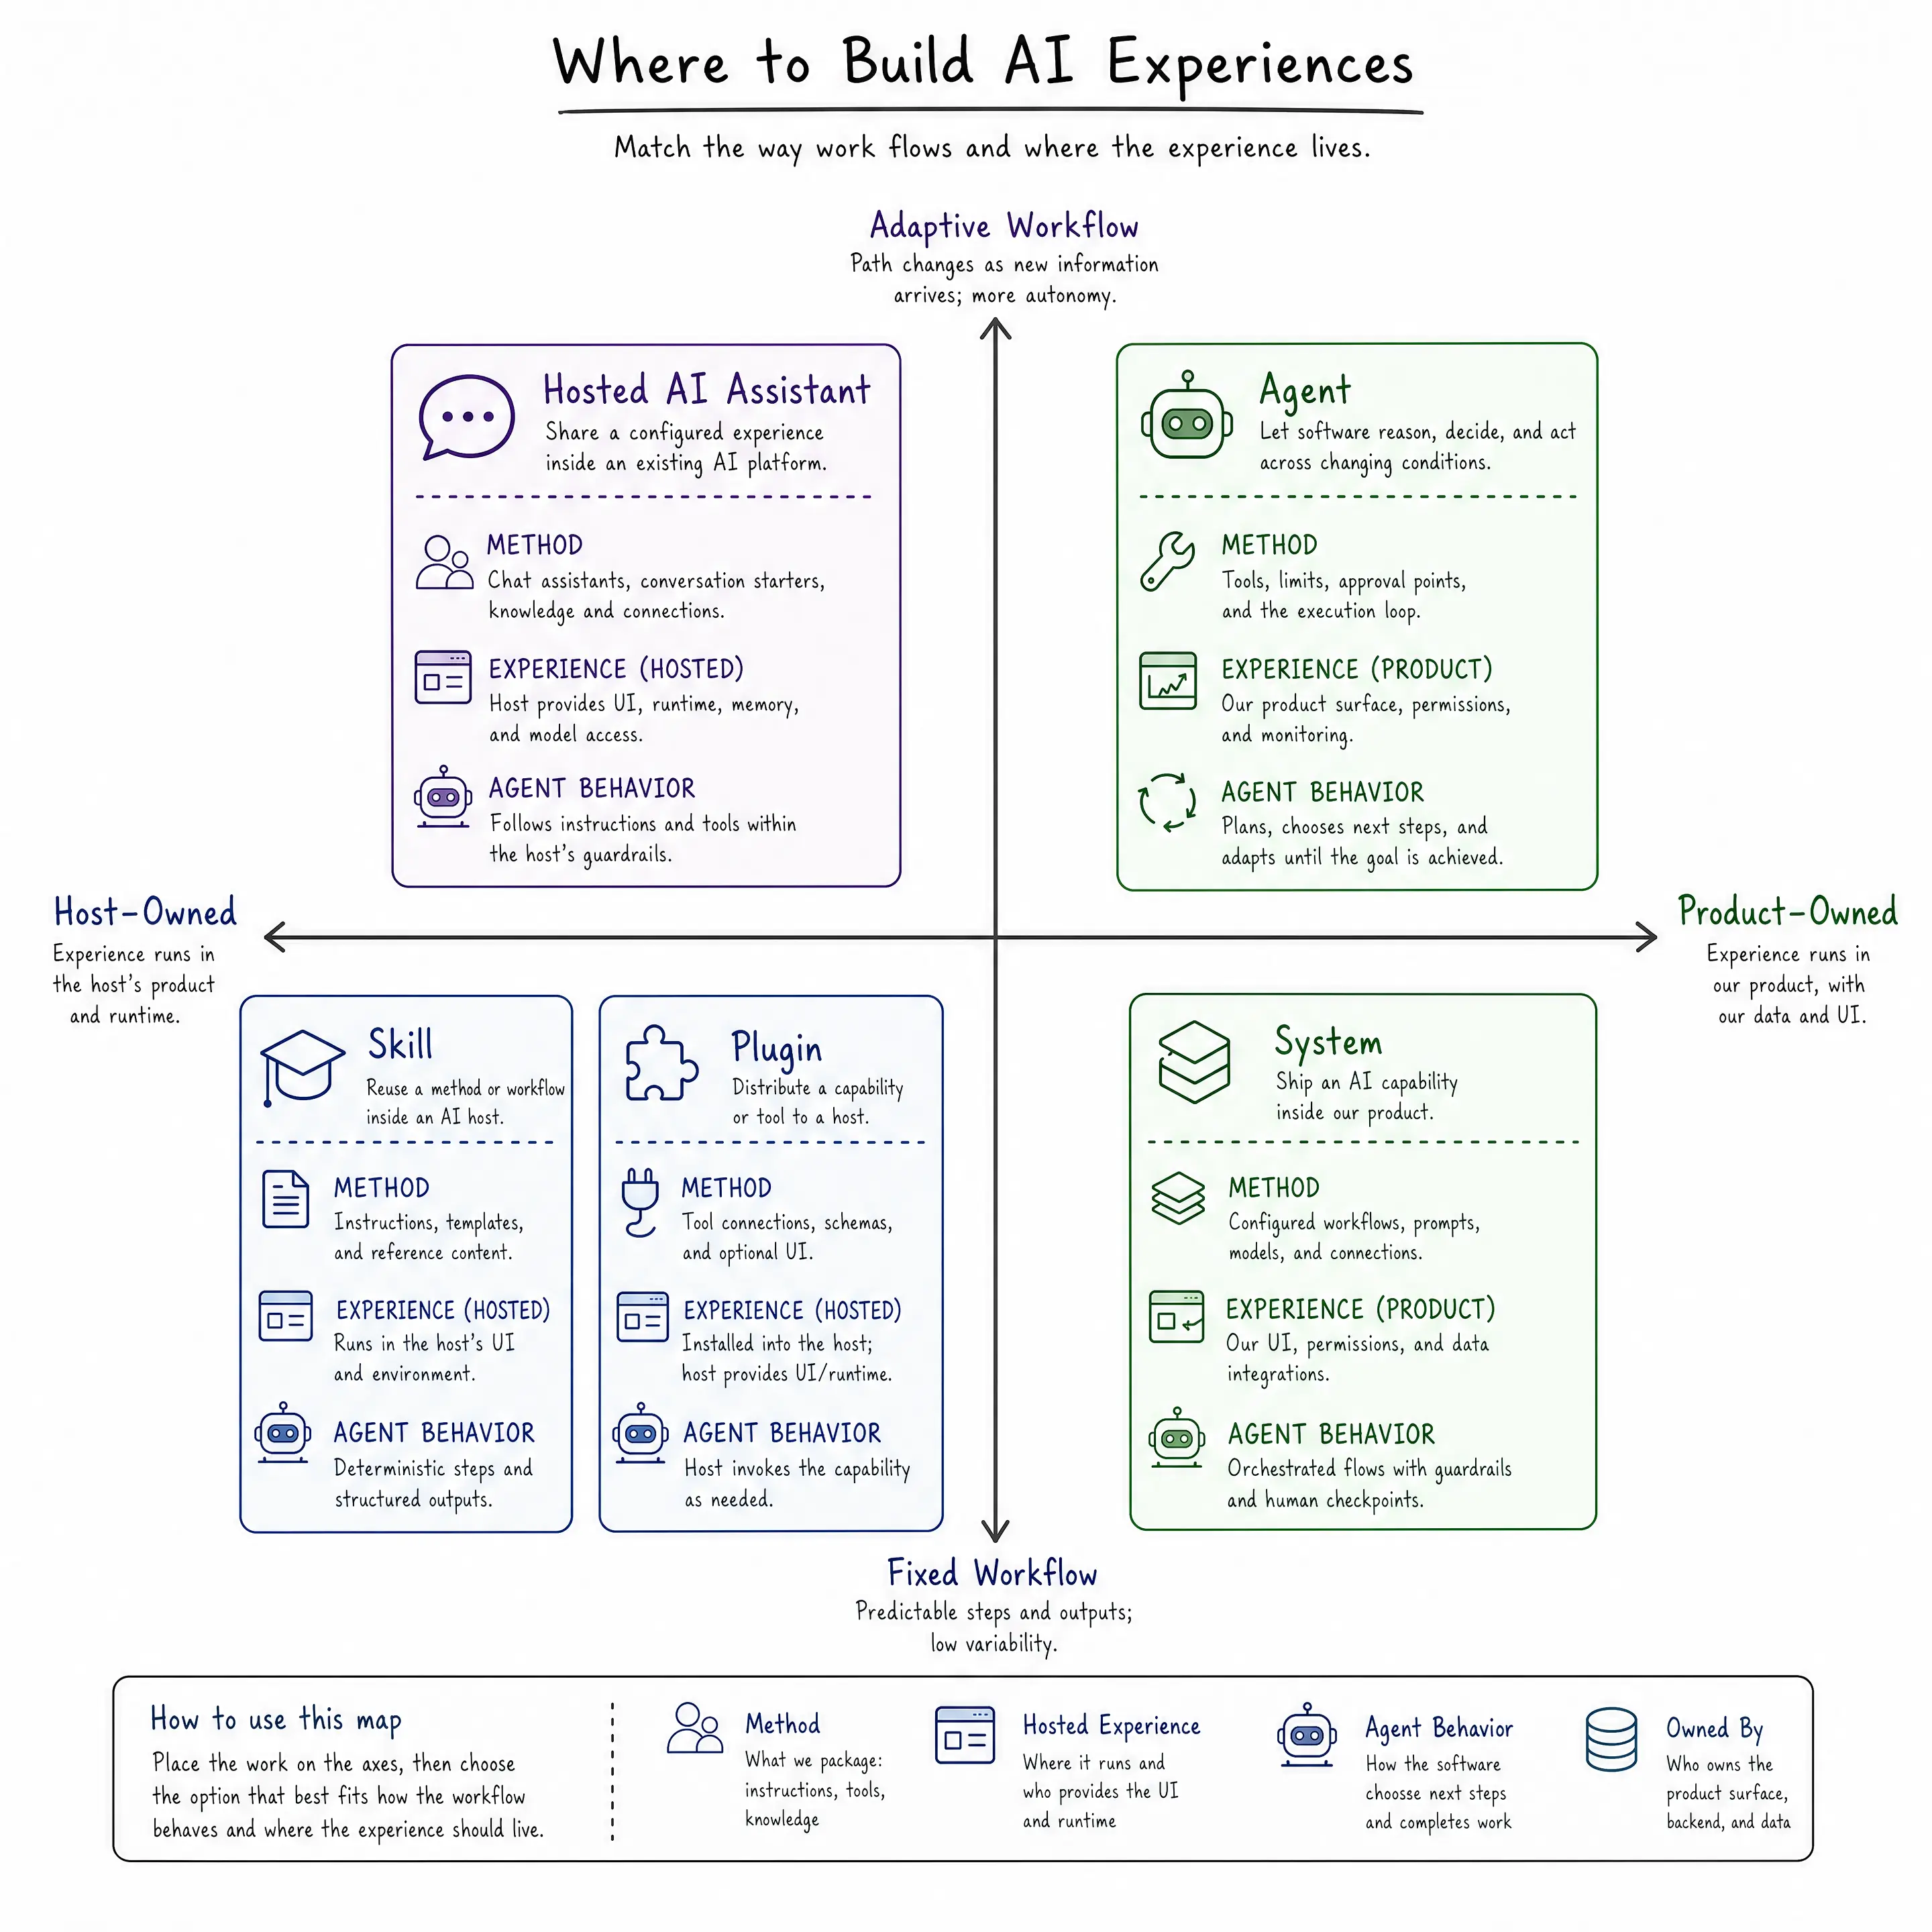
Diagram comparing ownership and runtime behavior across AI solution types

When a Skill Is Enough

A skill fits when the part we need to reuse is the procedure itself, such as a team’s method for summarizing pull requests into release notes or reviewing a component for accessibility. Without a shared procedure, we have to rewrite the instructions for each request, which wastes time and produces uneven results.

Skills can package instructions and references alongside scripts and templates, although the exact structure varies by host. If the workflow needs to be installed in a compatible AI platform, a plugin can distribute the skill with any tool connections required for external services or data.

When a Hosted AI Assistant Fits

A hosted AI assistant is well-suited when people need a shared conversational experience within an existing AI platform. Within that experience, we can configure instructions and reference files alongside capabilities and approved service connections.

For an onboarding assistant, the team can upload a handbook and set the expected tone before sharing the assistant in its workspace, creating a usable pilot without requiring a chat UI or model infrastructure.

The tradeoff is control because the provider runs the experience and its policies govern sharing and service connections. Once the capability becomes part of our application, our authentication model and release process become necessary, along with telemetry and support. Those requirements call for a system we operate.

When We Need a System

We need a system when the AI capability belongs to our product because our backend must authenticate the user and gather permissioned context before calling the model and validating its response. The interface becomes part of that boundary because it handles streaming and source citations alongside approvals and error states.

The surrounding components matter as much as the model call: retrieval keeps answers grounded in current content and guardrails block invalid actions. Evaluation checks whether changes improve the feature while observability records which sources and tools shaped a production response.

A billing assistant may need to explain a charge using account data and current policy. The feature must enforce the billing product’s access rules, and support engineers need a trace they can inspect when an answer is disputed. Even with one model call, a product-owned system keeps those checks and traces in code our team operates.

A system like this can remain deterministic: the billing assistant gathers the relevant policy and charge data before drafting an explanation, and plain application code orchestrates the known path with less variability than an agent loop would introduce.

When to Add Agent Behavior

Agent behavior becomes useful when we cannot specify the full path before the work starts. With agents, a task often has four characteristics:

  • The input describes an outcome for the software to complete.
  • The software must choose among tools or information sources.
  • An intermediate result can change the next step.
  • The workflow continues until it completes the task or reaches a stopping condition such as an approval checkpoint.

An incident investigation has this shape because the first log query may point toward a deployment or a third-party outage. As each result changes what the system should inspect next, an agent can select the next tool and evaluate the result before revising its plan.

This flexibility creates more work around the loop because tools need narrow permissions and validated inputs. Expensive or hard-to-reverse actions need approval checkpoints, and every run needs a decision trace and a stopping condition.

A Decision Sequence

To decide which option fits, we can work through the following questions in order, starting with product ownership and ending with runtime behavior.

  1. Where must the experience live? An existing AI host may already reach the intended users, so a reusable package or hosted AI assistant may be sufficient. An experience that belongs inside our application calls for a system we control.

  2. What are we trying to reuse? A repeatable procedure points to a skill, which can be packaged as a plugin if the procedure needs to be installed with tools. A configured conversational experience points to a hosted AI assistant.

  3. What must we control? A hosted AI assistant’s service connections remain within the host’s product and governance model. Product-owned authentication and permissioned customer data point toward a system, as do audit records and release management.

  4. Can we define the steps ahead of time? A known path belongs in normal application orchestration; a changing path that requires tool choice and recovery may justify agent behavior inside that system.

An AI system can include retrieval and memory as well as tools and evaluation without making every step adaptive. We can add a narrow agent only where an uncertain part of the workflow requires it.

How the Options Combine

A single capability may combine several options: a coding team can store its pull request review method as a skill and package that skill as a plugin when a wider group needs to install the workflow in a compatible AI platform.

A customer support feature can combine a chat interface with retrieval over permissioned documentation; tools can read account state and an evaluation set can cover common requests. Within that system, a skill can hold the support procedure, and agent behavior can handle the narrow investigative portion where each tool result may change the course of the work.

Wrap-up

Choosing an AI solution starts with two decisions: where the capability should live and how much freedom it needs while running.

A skill captures a repeatable method, and a plugin makes that method installable with tools. A hosted AI assistant delivers a configured experience through an existing platform, and a system gives us ownership of the product boundary. Both can support agent behavior when the route cannot be known in advance, allowing the software to choose and revise steps as the work progresses.

For more on building AI-powered applications and agents with Progress, check out the following resources:

Read the whole story
alvinashcraft
35 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Introducing DxTimingCaptureLibrary

1 Share

Today we released DxTimingCaptureLibrary, an open-source C++ library for DirectX developers. It is available on GitHub under the MIT license, and it works on all versions of Windows 10 and 11.

DxTimingCaptureLibrary makes it easier to understand DirectX ETW events and bring their rich information into tools such as in-engine game profilers.


What is DxTimingCaptureLibrary?

ETW (Event Tracing for Windows) is a Windows feature for collecting detailed system and application events with low overhead. DirectX components such as the D3D12 runtime, DXGI, and the DirectX kernel emit ETW events when important activity occurs.

DxTimingCaptureLibrary helps game developers interpret these events and turn them into actionable insights. It handles the complex work of interpreting and correlating ETW events from multiple sources, and then it makes simple callbacks into application code so that developers can use the information however they need.

The library includes samples that show how to configure ETW sessions and how to use DxTimingCaptureLibrary.

We created DxTimingCaptureLibrary by extracting code from PIX Timing Captures and moving it into a standalone project. All DirectX data shown in the PIX Timing Capture UI is available through DxTimingCaptureLibrary.


What can the library do?

The library exposes information such as:

  • GPU timing data.
    • Includes top-of-pipe and bottom-of-pipe timestamps for each command-list work item.
    • Timestamps are populated by the driver through D3D history buffers.
  • API object creation and destruction.
    • Includes timestamps, object size, parameters, and debug names.
  • Residency and paging events.
    • Shows when the DirectX kernel moves objects between video and system memory due to paging or eviction.
    • It also shows migration failures, for example due to VRAM fragmentation.
  • DirectStorage events.
    • Includes read and status requests.
  • D3D runtime failure logs.
  • Pipeline state compilation events.
  • Monitor VSync events.
  • WinPixEventRuntime events/markers on both the CPU and GPU timelines.
  • PIX custom counter data, via the WinPixEventRuntime counter APIs


How do I get started?

The README in the GitHub repository has the latest getting-started instructions. At a high level, you need to:

  1. Create and configure an ETW session with the appropriate DirectX ETW events.
    • The various samples (below) show how to do this.
  2. Configure the ETW session’s event handler to call DxTimingCaptureLibrary’s event handler.
  3. Implement any DxTimingCaptureLibrary callback interfaces that are relevant to your scenario.
  4. Wait for DxTimingCaptureLibrary to invoke your callbacks when the appropriate events occur.


What are the samples?

The library includes several samples:

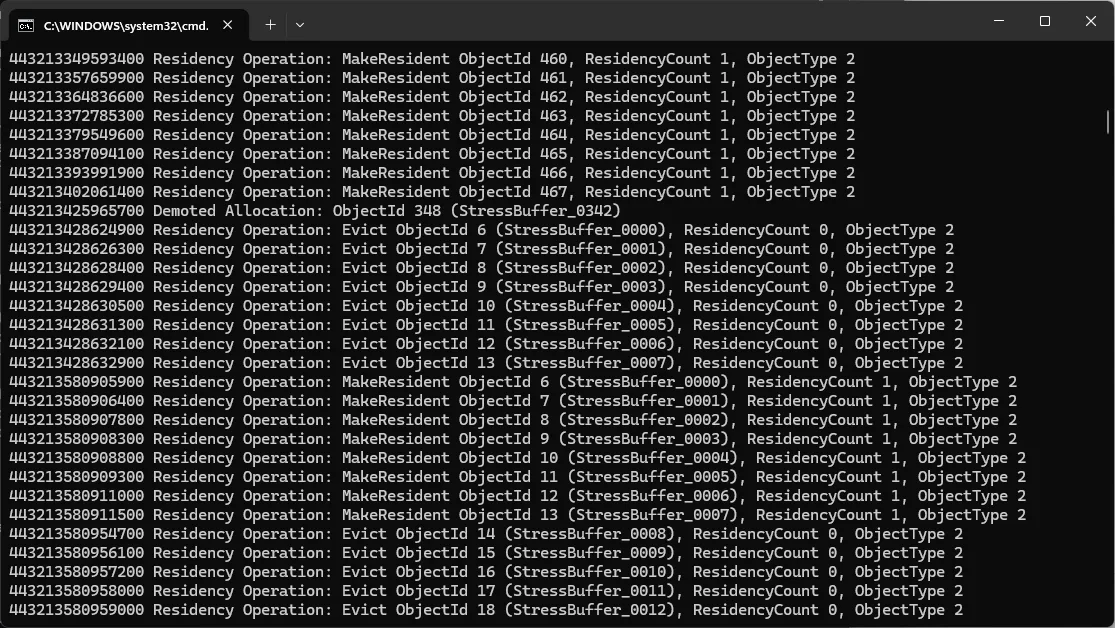
Basic Residency Logging: This barebones sample provides printf-based implementations of each DxTimingCaptureLibrary callback, which log event data to the console output window. It has an optional mode to only log DirectX residency/paging events, including MakeResident/Evict, Paging In/Out, and migration failures. This sample is a good place to get started with the library.

Command prompt window of the DxTimingCaptureLibrary sample


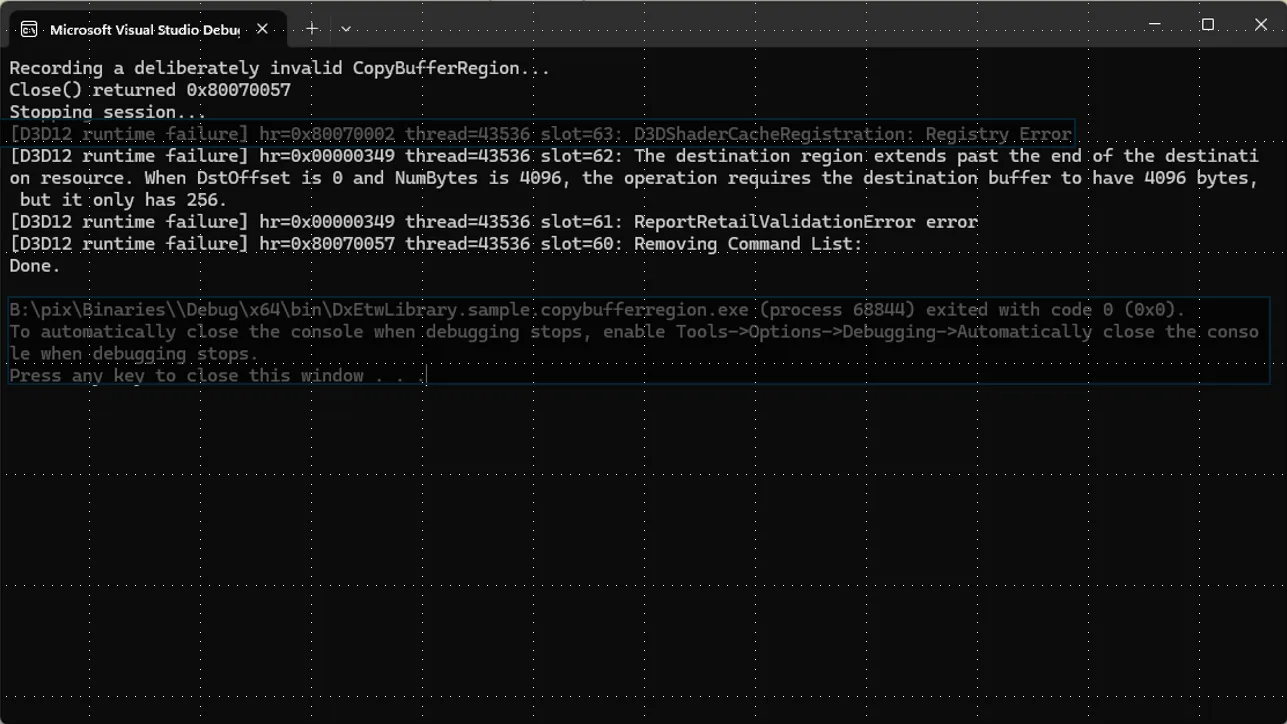
D3D12 Journal Entries: This sample implements the D3D12 Journal callbacks in DxTimingCaptureLibrary to receive a notification when an error occurs in D3D12 code. For example, the sample intentionally makes an invalid D3D12 API call by closing a command list that contains an invalid CopyBufferRegion() call. DxTimingCaptureLibrary reports this through the journal callback. The callback provides less detail than the D3D12 debug layer but it provides more detail than the regular D3D12 APIs – and it works in retail D3D12 environments!

Command prompt window of the DxTimingCaptureLibrary sample


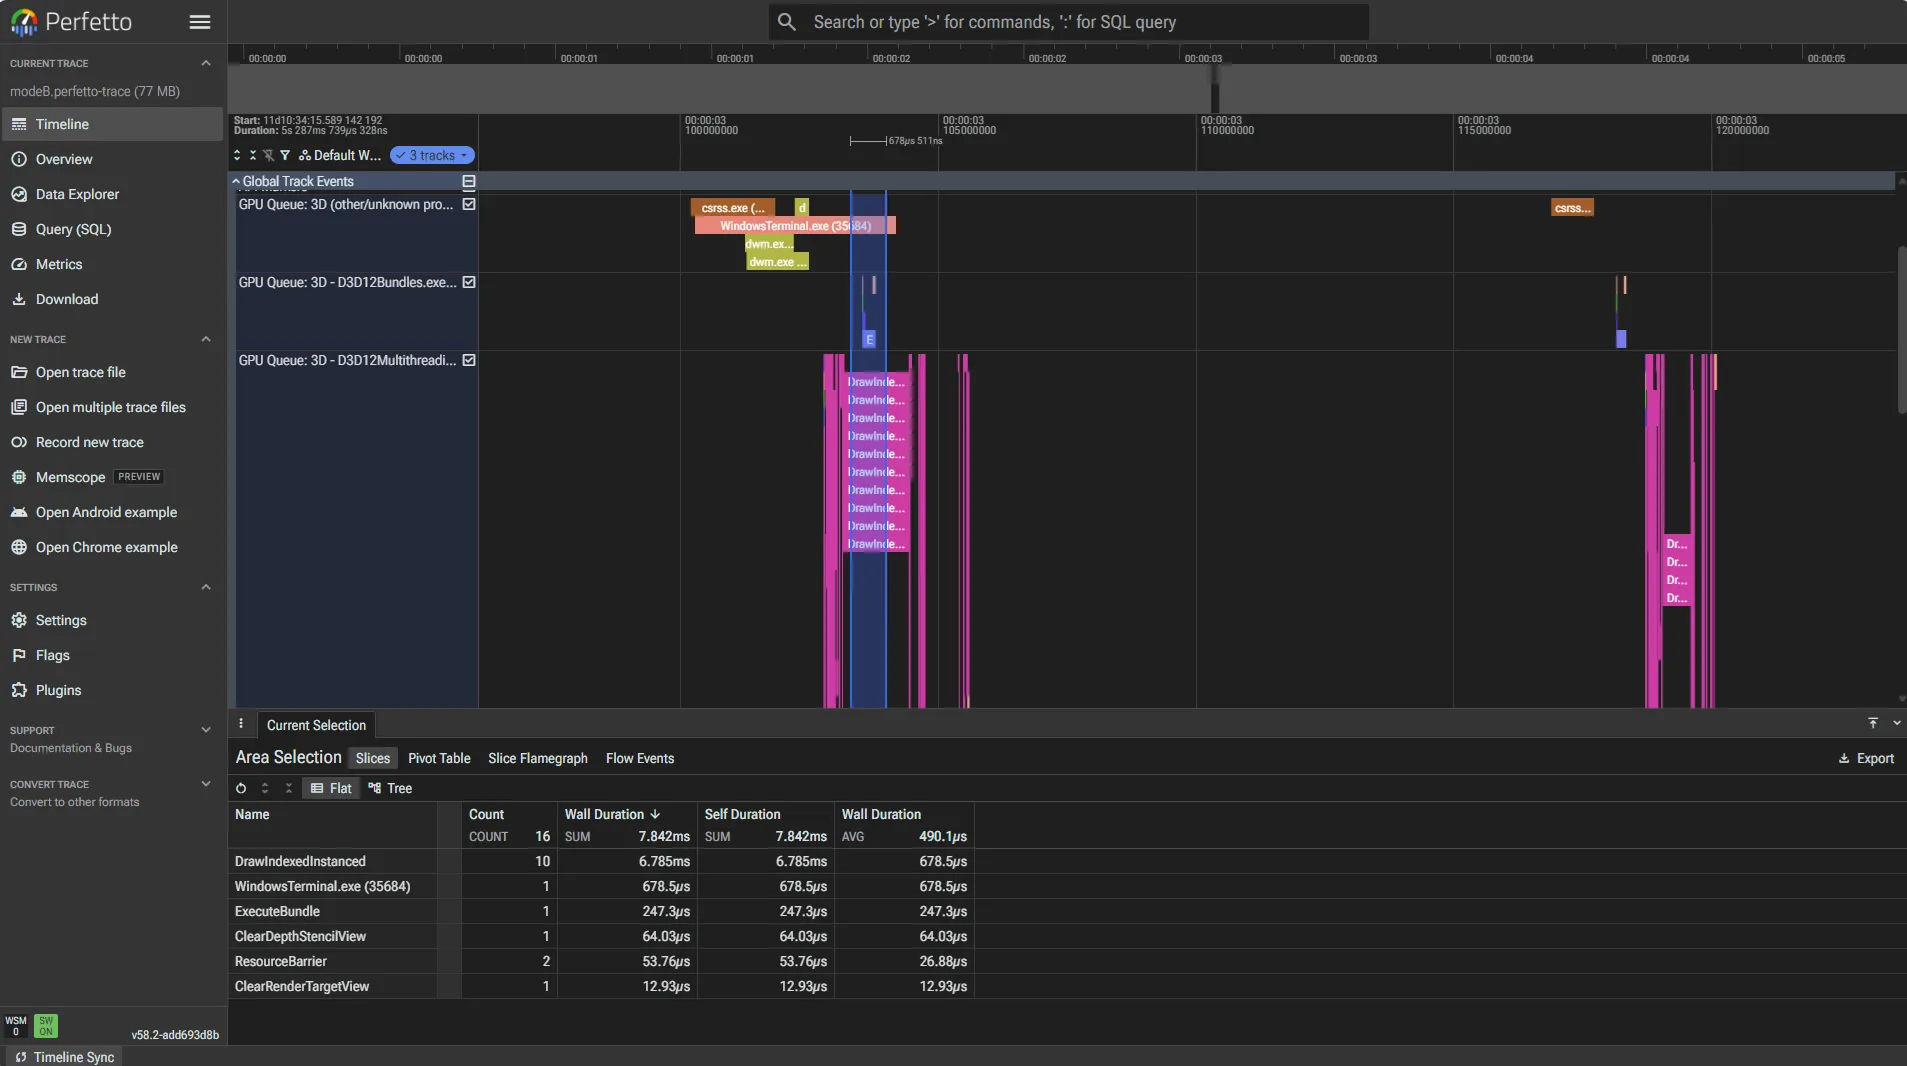
Perfetto: This sample implements the GPU timing data callbacks in DxTimingCaptureLibrary and uses them to generate a Perfetto trace file. The trace shows each command list event’s top-of-pipeline and end-of-pipeline timestamp on the GPU timeline, and it connects the data to a marker on the CPU timeline showing when the command list event was recorded. It also shows you other processes’ GPU work and how they might be interferring with your process.

perfetto sample image
Perfetto Sample Screenshot


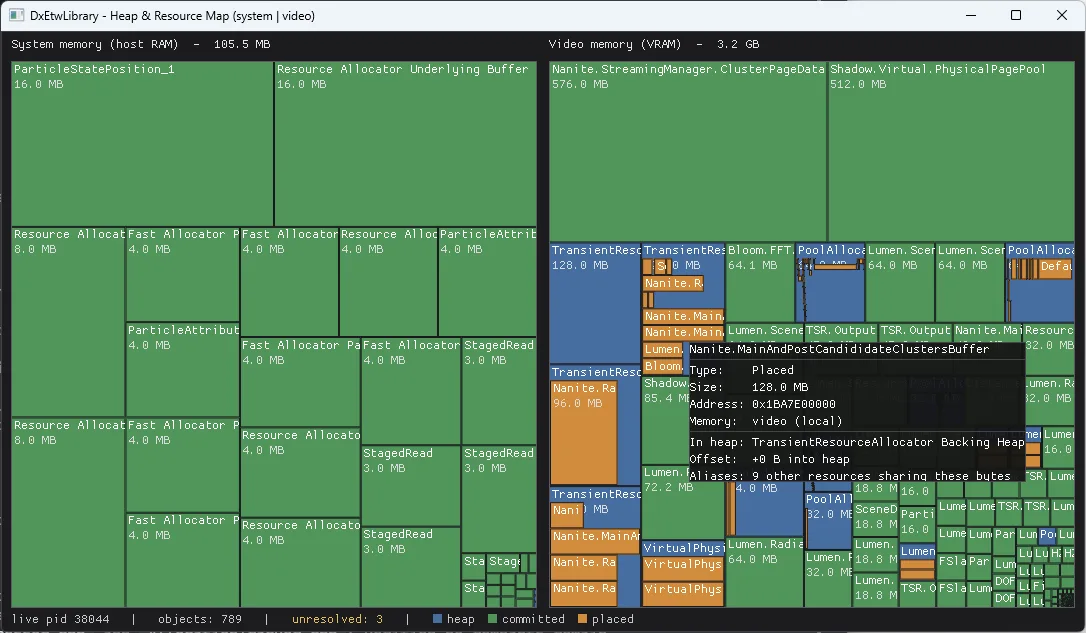
Memory Treemap: (work in progress) This sample listens to the resource creation and residency event callbacks in DxTimingCaptureLibrary. It uses that data to populate two treemaps showing resource and heap usage in system memory and video memory, while taking paging and residency events into account.

Screenshot of the DxTimingCaptureLibrary sample


The post Introducing DxTimingCaptureLibrary appeared first on DirectX Developer Blog.

Read the whole story
alvinashcraft
40 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Thinking About AI ... with AI

1 Share

is an economic historian of the near future - one of the few people with the gift of seeing around corners. I follow him to try and understand the current moment in AI, the economy, and society.

What does an agentic future hold for us? How will jobs look like in the future? Are people ever coming back to the office, now that our agents are working in the cloud?

and I will be hosting Dror for a session next week. This time, he’ll be playing with open cards and share not just his insights, but also how he researches and analyses and thinks ... using AI.


Read the whole story
alvinashcraft
50 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Why Coding-Agent Governance Needs More Than Approval Gates

1 Share

Human approval is an important control for coding agents, but it cannot carry the full weight of governance. Effective governance also limits agent access, enforces rules during execution, manages exceptions and preserves a record of what happened.

Your most productive engineer this quarter might not be a person. Point Claude Code or GitHub Copilot’s coding agent, for example, at an issue and it reads the repository, writes the code, runs the tests and opens the pull request in minutes.

That speed can break the review cycle. Someone who used to read one 200-line diff a day now faces 10 agent-authored pull requests before lunch. As volume increases, so does the risk that a developer approves a change without fully reviewing it, relying on tests the agent may have written itself. This is where governance comes in.

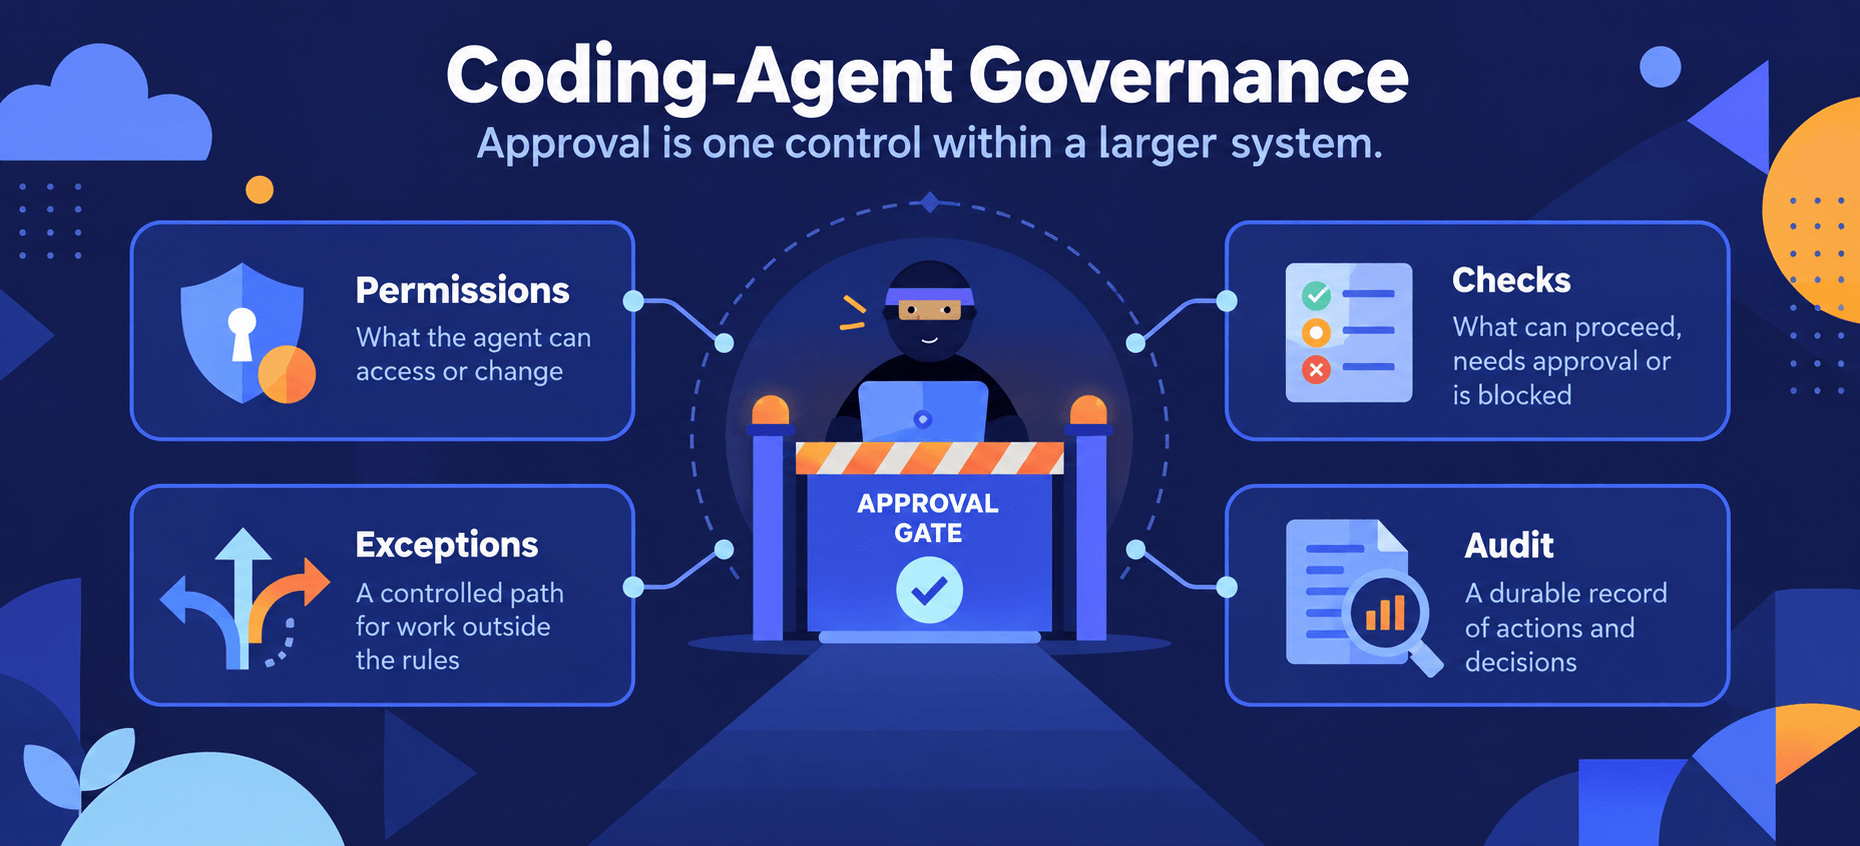
Governance defines what an agent is allowed to do on its own, where human judgment is still required and what evidence must remain afterward. A coding agent needs four types of control:

  • Permissions: The repositories, branches, files and deploy targets the agent can access or change
  • Checks: Runtime rules that inspect each action and determine whether they should be allowed, require approval or be blocked
  • Exceptions: A documented, expiring path for legitimate work that falls outside those rules
  • Audit: A record of what the agent did, under which identity, with whose approval

coding agent governance: permissions, exceptions, checks, audit
Image generated with ChatGPT

These controls do not need to live in one place to be effective. Permissions may be enforced through identity and access controls, checks through CI, exceptions through existing approval workflows and audit through pipeline and system logs.

What matters is whether those controls work together well enough to answer a few basic questions: What could the agent do? What did it actually do? Which actions required human approval? And can you demonstrate that after the fact?

That is the foundation of coding-agent governance: not another approval step, but a system of boundaries, checks and evidence that can keep up with the speed of automated development.

Permissions Define What the Agent Can Touch

A coding agent should only have access to the exact systems and actions it needs for the specific task it’s doing—nothing more.

If an agent is updating documentation, for example, it may need permission to edit the docs/ folder on a feature branch. It does not need permission to push directly to main or fire the production deploy.

The problem starts when teams give agents credentials with much broader access than the task requires. The OWASP Top 10 for LLM Applications calls this excessive agency: more permission or autonomy than the task requires.

Coding agents can make mistakes. They can generate a destructive command, misunderstand an instruction or follow malicious content hidden in an issue, comment or README. This isn’t a model-quality problem, and a smarter model only argues more persuasively for the wrong command. But a bad instruction can only cause serious damage if the agent has permission to carry it out.

So limit access based on the task, not the tool:

  • Give the agent its own identity rather than using a developer’s credentials.
  • Limit access to only the repositories, files and actions the task requires.
  • Allow specific actions the work needs (read files, run the test suite, open a pull request) instead of raw platform access.
  • Use a disposable branch like agent/issue-482, and protect main with a rule the agent’s identity can’t bypass.

Security teams call this “least privilege,” which NIST defines as granting only the privileges a task needs. You already apply it to people. The difference with coding agents is speed and autonomy. Because they can take actions on their own, limiting what they are allowed to touch becomes even more important.

Checks Assess Risky Actions Before They Run

Permissions define what an agent it capable of doing. Checks decide whether a specific action should actually be allowed.

A check is a rule evaluated during the agent’s work and can allow the action automatically, require human approval or block it entirely.

For example, file reads and a sandboxed npm test might auto-approve. Dependency manifests and environment files may require human approval, and so does any arbitrary shell command. Force-pushing a shared branch or touching production may be blocked.

The mechanisms already exist in tools you run. In Claude Code, for example, hooks and permission settings allow Bash(npm test) while prompting on Bash(git push*), and most agent CLIs expose an equivalent. On the CI side, a GitHub Actions environment with required reviewers holds a deploy job until a named person approves it, and GitLab and Azure Pipelines do the same.

The goal is not to put a human approval step in front of every action. If developers are asked to approve routine behavior constantly, they will eventually stop reviewing those requests carefully.

Checks work best when they match the level of risk: low-risk actions proceed automatically, higher-risk actions require review and unacceptable actions are blocked. That keeps human attention focused on the decisions where it actually matters.


Pro Tip: Watch the ratio of approvals to denials per agent. A gate that never denies anything is either perfectly scoped or never actually read.


Exceptions Need an Owner

A policy that can only say “no” won’t survive real work. Governance rules need a controlled way to handle legitimate work they were not designed to allow. An exception is documented, time-boxed permission to proceed despite a blocking rule, with a named person responsible for approving it. An exception should not remove the rule entirely.

Say the agent must bump a pinned dependency to patch a CVE, but the rule guarding package-lock.json blocks the edit. Don’t delete the rule. Grant a 48-hour exception from a named owner for that one file on that one branch.

Record who asked, what got unblocked, why and when it expires. Once the work is complete, the extra permission should disappear automatically.

Exceptions should also be reviewed over time. If teams repeatedly request the same exception, that may be a sign that the underlying policy needs to change. If the policy system itself fails, the agent should not treat that as permission to continue. It should fall back to stricter rules or stop until the check can be completed.

The goal is to make exceptions possible without turning them into permanent loopholes.

The Audit Is the Receipt

Governance is not just about stopping risky actions. It’s also about keeping reliable evidence of what the agent did and who approved it.

Where checks try to prevent unsafe actions, audit logs create a record showing what actually happened. Log every action: the identity that ran it, the prompt behind it, the tools that fired and the human who approved any sensitive steps. A receipt you can’t edit is the only one worth keeping.

Most of it already exists. A workflow run records who ran what and who approved, and the pull request timeline records the merge. Ship both to an append-only store so they outlive your retention window.

Regulators want that traceability: Article 14 of the EU AI Act requires effective human oversight of high-risk systems, and NIST’s AI Risk Management Framework and ISO/IEC 42001 ask for documented evidence.

Good audit records, from a governed workflow, let you answer questions with evidence rather than relying on someone’s memory.

Build the Gate into the Workflow

The strongest gates are structural. A per-action prompt interrupts one action, but a phase boundary between planning and implementation stops everything downstream and is harder to click past. Reading the plan before any code exists means approving intent, and wrong intent is cheaper to fix than a bad merge.

Progress built its Forge CLI, one example of an agentic SDLC tool, around that shape. Its task flow keeps planning separate from the code it produces, so the human checkpoint lands between phases instead of mid-run.

What matters is that the agent’s pull requests take the path your human changes do: the same protected branches and peer review, secret scanning included. An agent that can merge around that path just breaks your own rules faster than anyone can catch it.

Four Questions Before You Scale Coding Agents

Before expanding the use of coding agents, ask:

  1. Can you list everything the agent’s credential can reach? If it lives in a spreadsheet someone maintains, the scope is wider than the task.
  2. Which actions wait for a human? If nothing does, or the prompt fires so often nobody reads it, you’ve trained a rubber stamp.
  3. Who owns the exceptions? If the answer is “whoever is on call,” the exceptions own you.
  4. Can you produce the receipt? If you can’t show who approved a change and when, the agent is running ahead of its controls.

Coding agents can execute software work at a speed that makes manual oversight alone difficult to scale. Governance is what lets coding agents run at full speed.

The goal of governance is to put controls at the right layers: constrain authority with permissions, classify actions with checks, route unusual cases through managed exceptions and preserve the evidence through audit. Then use human approval where human judgment actually adds value.

Governance should be repeatable, documented and built into the development environment rather than dependent on individual memory. Whether you buy an AI governance platform or wire the four controls from tooling you own, build it once as configuration in the repository, not tribal knowledge.

That is what makes coding agents easier to scale safely: the next agent starts with the same boundaries and controls already in place.


Learn More About Progress Forge Orchestration

If you’re ready to move from isolated AI coding tasks to repeatable engineering workflows, Progress Forge (formerly Progress Agent Harness) is designed for exactly that shift. It orchestrates the AI coding agents your team already uses through structured workflows with visibility, governance and human review built in.

Explore the Progress Forge Early Access Program to see how it can help you put these ideas into practice.

Request a Demo

Read the whole story
alvinashcraft
56 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Build Fast, Scalable React Data Grids for Large Datasets Using Virtualization [Webinar Show Notes]

1 Share

How to Handle Large Datasets in React Data Grid with Virtualization [Webinar Show Notes]

What happens when a React Data Grid needs to display 100,000 records?

The challenge isn’t always the amount of data itself. Rendering thousands of rows and cells in the browser can create unnecessary DOM work, especially when users can see only a small portion of the dataset at a time.

This is where virtualization and paging strategies become important. Virtual scrolling, paging, and DOM virtualization address different parts of the large-data problem, and they can also work together to keep data-intensive applications responsive.

In this webinar,  Syncfusion® Software Engineer Prabhavathi Kannan demonstrates these approaches using local and remote datasets, including a 100,000-record example.

This blog summarizes the key concepts, demos, and guidance from the session.

What you’ll learn

In this webinar, you’ll learn how to:

  • Distinguish data size from rendered DOM size.
  • Use DOM virtualization to render only the rows needed for the current viewport and buffer.
  • Combine virtual scrolling or paging with DOM virtualization.
  • Separate remote data operations from browser rendering concerns.
  • Choose an appropriate approach based on how users need to explore large datasets.

How do virtual scrolling, paging, and DOM virtualization differ?

These approaches solve different problems when working with large datasets.

  • Virtual scrolling provides continuous scrolling through a large dataset.
  • Paging divides data into smaller pages for structured navigation.
  • DOM virtualization limits the number of row elements rendered in the browser at a time.

These approaches can also work together. For example, a grid can use paging to retrieve a portion of a remote dataset while DOM virtualization limits how many rows from that page are rendered.

Watch the webinar

Want to see these techniques in action? Watch the full webinar below to follow the local- and remote-data demos.

Timestamps

[00:00] Introduction

[01:32] Large dataset rendering challenges

[02:14]: DOM size vs. data size

[03:04] Understanding DOM virtualization

[03:38] Virtual scrolling vs. paging

[06:26] Local-data demo

[09:49] Configuring virtualization

[13:36] Scaling to 100,000 records

[16:53] Remote-data demo

[19:21] DataManager and UrlAdaptor

[20:44] DOM virtualization with remote data

[25:36] Paging vs. DOM virtualization

[26:06] Choosing an approach

[27:05] Key takeaways

[28:34] Q&A

Demo highlights

Local data with virtual scrolling

The first demo starts with 100,000 locally generated order records. Instead of rendering every row in the DOM, the React Data Grid uses virtual scrolling and DOM virtualization to render the content needed for the current view.

The demo also shows how row reuse and virtualization work as the dataset size changes.

Additional grid features demonstrated include:

  • Custom templates
  • Frozen columns
  • Sorting
  • Filtering
  • Dialog editing

Learn more about virtual scrolling and DOM virtualization in React Data Grid.

Remote data with paging

The second demo moves from local data to a remote API. The React Data Grid connects to the API using DataManager and UrlAdaptor.

The demo shows how remote paging, sorting, and filtering work with 100,000 records. It also demonstrates DOM virtualization within a page, showing how data retrieval and browser rendering can be handled separately.

Which approach should you use?

There isn’t one approach for every large-data scenario. The right choice depends on how users need to explore the data and how the application retrieves it.

Approach Useful when Example scenarios
Virtual scrolling Users need continuous exploration of a large dataset Logs, activity feeds, transaction histories
Paging Users need defined pages and predictable navigation Reports, audit views, reference data
DOM virtualization The grid could render more rows than users can see at once Large local or paged datasets

DOM virtualization is not necessarily an alternative to virtual scrolling or paging. It can complement either approach by limiting the number of row elements rendered in the browser.

Frequently Asked Questions

What is the difference between virtual scrolling and DOM virtualization in a React Data Grid?

Virtual scrolling provides continuous scrolling through a large dataset, while DOM virtualization limits the number of row elements rendered in the browser at a time. They address different aspects of large-data handling and can be used together.

When should I use paging instead of virtual scrolling for large datasets?

Paging is useful when users need clear page boundaries, predictable navigation, or report-style browsing. Virtual scrolling is useful when users need continuous exploration of a large dataset.

How does Syncfusion React Data Grid handle local and remote large datasets?

The webinar demonstrates a 100,000-record local dataset using virtual scrolling and DOM virtualization. For remote data, the React Data Grid can connect to APIs using DataManager and UrlAdaptor to support operations such as paging, sorting, and filtering.

Key takeaway

Large datasets do not always require rendering large numbers of DOM elements at the same time.

Virtual scrolling and paging address different data-navigation needs, while DOM virtualization limits the amount of content rendered in the browser. Choosing the right combination can help keep React Data Grid interactions responsive as dataset size grows.

Related resources

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Fabulous Adventures in Data Structures and Algorithms (Manning)

1 Share
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories