Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164543 stories
·
33 followers

Where is the line between AI-clone and inspired-by?

1 Share

Hello and Welcome, I’m your Code Monkey!

Lots of stuff happening this week! Here's some quick news:

  • My Demo: It's doing very well! Median Play time is 27 minutes which is quite a lot! I'm glad people enjoy the game! Now I just wait for Steam to review the build to hopefully launch on the 12th and finish the How to Publish your Game on Steam course.

  • Unity Game Jam: It is live right now and running until the end of this week Nov 14, are you joining? Theme is Lucky Number! I'm curious to see how many AI submissions they will have.

  • Steam Awards: Are kicking off on November 23! If you think your game has a shot at one of the awards then use this as a nice marketing beat.

  • Unity Buyout? There are reports that Unity is supposedly in talks to be aquired by private equity. The future of Unity with 7 is looking insanely bright, I really hope we're not about to experience Runtime Fee 2.0

  • The Elder Scrolls 6: Sentinel! We have a name! Wohoo! It's crazy how this game was announced with just a quick teaser in 2018!


Game Dev

Where is the line between AI-clone and inspired-by?

Imagine receiving an email saying someone has recreated your game using AI... and asking whether you’re okay with them releasing it, that's weirdly unexpected.

That happened to Mark Brown from Game Maker’s Toolkit. Two developers made a game (using AI) closely following his game Word Play, they built upon it by adding extra features, and asked him if he was okay with that. His video about the situation raises a fascinating question: where exactly is the line between inspiration and cloning?

Mark acknowledges that his own game was inspired by Balatro and several other games. And those games like Balatro were inspired by other games like Luck be a Landlord, Slay the Spire and more. That's how any type of media is made, it is inspired by or built upon what came before. But combining different influences into something new feels different from closely recreating one particular game and adding things on top. Where exactly is the line between something that is just "inspired-by" and something that is a "clone"?

Personally, I don’t think there is one simple answer. How different is different enough? Does adding features automatically make it your own? How many features do you need to add before it is something new? The topic of game cloning has existed since forever (especially on mobile) but the speed that AI can copy makes these questions even more important.

With all this AI-cloning conversation, indie devs like yourself need to ask a practical question: what should YOU do to protect your game? Should you just hide your game, don't do any marketing, and shadow drop it on release?

Chris Zukowski examined the needle-in-a-haystack cloning saga , and his advice is to keep marketing, not hide everything until release.

I very much agree with this for one simple reason. For most indie devs the biggest danger is NOT cloning, it is obscurity.

Showing your game creates a risk that somebody might copy it. But keeping everything secret means missing opportunities to attract players, collect wishlists, and build an audience. People can’t buy something they don’t even know exists!

So out of those two scenarios, risking getting cloned or risking obscurity, I still feel the latter is the worse option, so yes I recommend you keep marketing your games. The only practical change would be just be ready to launch your game quickly if you get viral success. So plan for the usual 3-6 month marketing cycle, but be ready to publish in 1-2 months if you get lucky and your game goes insanely viral.

I recently announced my game Cards: Tidy Up! and actually one of the comments was calling the game a clone which confused me. I've never seen a tidy up game using playing cards so I don't know what he thought I was cloning. It turns out for that person "genre" == "clone" so since I was making a game in an established genre apparently that's a clone. This just goes to show how the line is where you want it to be and how it differs from person to person.


Sponsored

Your game works on YOUR machine… but what about your players?

You test your game, everything works perfectly, and you publish it. Then a player tells you “the game crashed”… with absolutely no information about what happened. How are you supposed to fix that?

That's where Sentry comes in!

Sentry helps you track errors and crashes in your Unity games, so you can investigate what went wrong on your players’ machines, without even requiring the player to tell you something went wrong! You get stack traces to help identify the code involved, plus breadcrumbs like logs and scene changes to understand what happened before the error.

So instead of trying to guess what the player was doing, you have useful information to start debugging!

My recent video is all about this topic, how bugs in your games can cost you TENS OF THOUSANDS of dollars, so having good debugging tools (especially ones that don’t require the player to send you logs) are insanely valuable. Check out that video for more detail.

Spend less time guessing what broke and more time making your game AWESOME!

BONUS: Sentry is actually completely FREE for Solo Devs! That’s awesome! And if you work as part of a Team they have a FREE trial, so there’s no reason not to try it!

Check out Sentry HERE!


Tech

AI is forcing us to pay off 40 years of technical debt

More and more code is being written by AI these days, and from that the obvious worry is that we’ll end up with mountains of code nobody properly checked which will likely have tons of vulnerabilities. But there is another side to this: AI is helping expose vulnerabilities in software that have existed for YEARS!

Recently there was PHP2Shell. AI-assisted researchers demonstrated serious vulnerabilities in PHP, including attacks against WordPress installations (which is running on a massive amount of websites). Technically an earlier audit had already uncovered part of the problem, but nobody had demonstrated a working attack at the time because it was too difficult to do manually, but that changed with AI.

Then this week there was SSHole, whose discoverer says AI agents helped uncover a decade-old login bypass affecting particular Linux configurations.

Even MS Paint has recently disclosed a remote-code-execution vulnerability, on this one they didn't specifically mention AI helped them discover it but I assume it helped.

And OpenAI reports that its research pipeline produced 948 working Linux privilege-escalation exploits!

This whole thing is both fascinating and scary. AI can produce sloppy code, but it can also help uncover the problems already sitting inside human-written software. Perhaps we are finally being forced to confront decades of technical debt.

On the other hand, all of these vulnerabilities being found and fixed might actually lead to a future with more robust software. So AI is simultaneously helping write sloppy code, and helping audit and fix sloppy code (whether it was human slop or AI slop)

I find it quite interesting to see this happening considering how one year ago the talk was "AI code will have tons of vulnerabilities!" and now AI is helping uncover bugs that have existed in human-made software. It goes to show how fast this field is moving!


Affiliate

FREE 2D Chars! Bundle 80% OFF

My Code Monkey Bundle is BACK to celebrate the End of Summer with 80% OFF!

You’ve got 12 of my courses covering C#, Problem Solving, Multiplayer, DOTS and tons more, plus 9 of my Steam games and 1 month of my Game Dev Practice Lab to put those skills into practice!

Grab the whole bundle 80% OFF with coupon SUMMER2026. Get it HERE!

The Publisher of the Week this time is LAYERLAB, publisher with tons of really nice characters, UI packs and icons!

Get the FREE 2D Minimal - Character Maker which lets you mix and match over 400 parts to create your own 2D fantasy characters, complete with animations. Perfect for filling your RPG with heroes and NPCs!

Get it HERE and use coupon LAYERLAB at checkout to get it for FREE!

There’s an awesome HumbleBundle! packed with Unity tools and assets!

You’ve got Gaia for Unity 6 to build your worlds, Love/Hate for NPC personalities and relationships, plus tools for Vehicle Physics, Water, Lighting and VFX. On top of that you get Characters, Environments, Props and more!

62 tools and assets in the full bundle, all at 99% OFF! Get it HERE!


Fun

Can you sketch the suspect?

Here is a really fun game! You get clues and it’s up to you to draw the suspect!

It’s a really silly awesome idea that actually works pretty well.

I suck at drawing but I still had a good time! Fun game idea! Could this be a Steam game?


Get Rewards by Sending the Game Dev Report to a friend!

(please don’t try to cheat the system with temp emails, it won’t work, just makes it annoying for me to validate)

Thanks for reading!

Code Monkey

Read the whole story
alvinashcraft
14 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Ghostty's Shared Terminal Engine libghostty-vt Reaches 1.0 With Adoption in JetBrains IDEs

1 Share

The terminal library extracted from Ghostty has reached 1.0 with a binary compatibility guarantee. JetBrains adopted it early in its 2026.3 IDEs, improving keyboard input and display behavior, and standalone releases make the engine available to other development tools.

Key points

  • Release highlights: libghostty-vt 1.0 ships with a C ABI compatibility guarantee and standalone distribution.
  • IDE changes: JetBrains adopted libghostty early in its 2026.3 release series, improving Shift+Enter handling and support for nearly 50 control sequences.

Read the full article on Joho no Todai · Japanese original

Read the whole story
alvinashcraft
16 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Microsoft built a native WinUI Registry Editor that makes Windows 11’s regedit look like Windows 95, and I tried it

1 Share

Windows Latest found a native WinUI 3 version of Registry Editor in Microsoft’s open-source Microsoft.UI.Reactor repository, and I compiled it and ran it on my Windows 11 PC. It actually reads the real Windows Registry and makes regedit.exe look like a relic.

Microsoft has only mentioned “a registry editor” in passing, in an October developer blog post that promised a tour of its sample apps “next month.” The tour hasn’t happened yet, which makes this the first look at the app running on a PC. It’s a developer sample, though, and Microsoft hasn’t announced plans to replace Registry Editor in Windows 11.

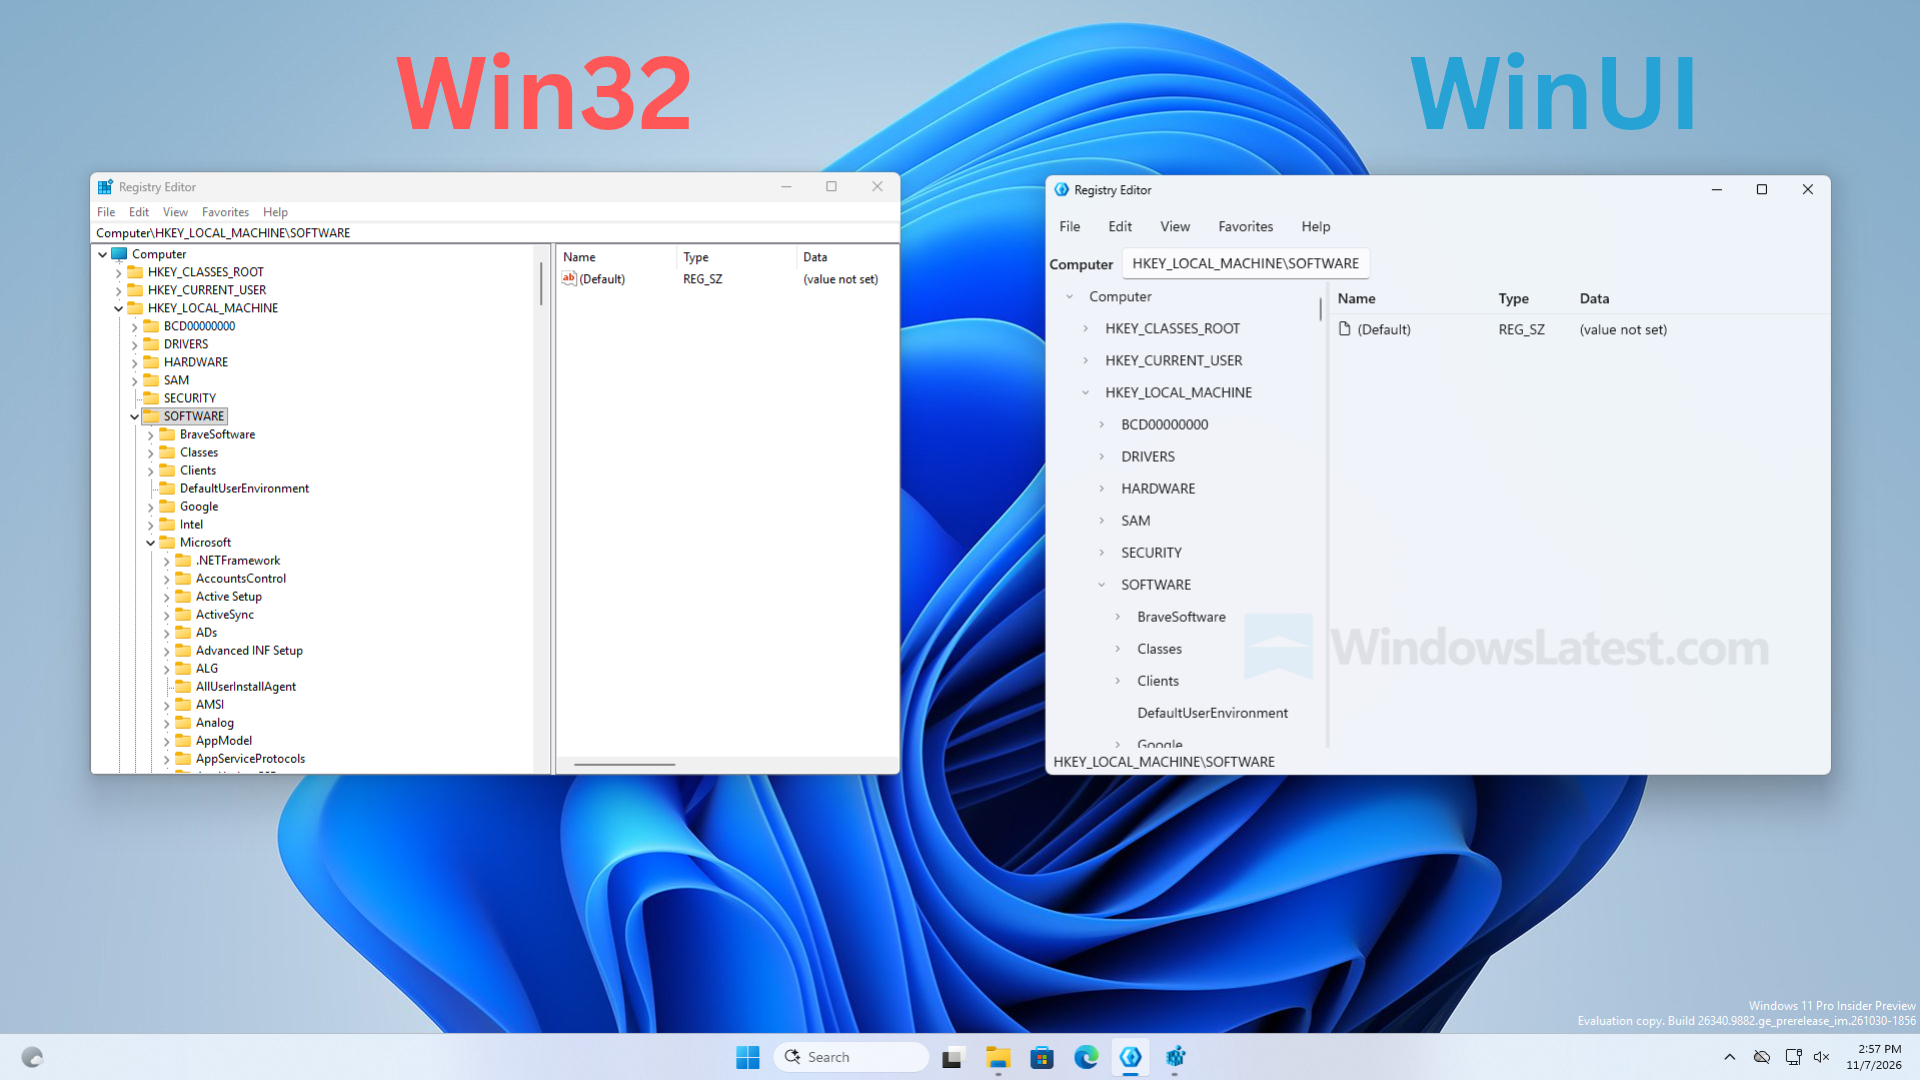
Windows 11's legacy Registry Editor (left) next to Microsoft's WinUI Registry Editor sample (right)
Windows 11’s legacy Registry Editor next to Microsoft’s WinUI Registry Editor sample. Credit: Windows Latest

Microsoft’s new WinUI Registry Editor looks nothing like the Windows 95-era original

Registry Editor still uses the two-pane layout it got in Windows 95, with keys on the left and values on the right. Apart from the address bar added in the Windows 10 Creators Update, its yellow folders, cramped menus, and tiny text have barely changed in three decades.

The WinUI version keeps the same layout, and it’s a good idea; power users would not stop criticizing Microsoft for making them relearn regedit, which hasn’t changed for so long.

But what I like is that Menus have more breathing room. The tree drops the yellow folders, but I hope there would be some newer-looking folder icon when or if this WinUI regedit comes to fruition. The address bar is a WinUI text box, and a status bar at the bottom shows the current path, which may be unnecessary. Like I said, this is a developer sample, and things may change a lot.

On my PC running Build 26340.9882, the app opened quickly and felt as fast as regedit. However, expanding HKEY_CLASSES_ROOT showed a brief “Loading…” placeholder before listing keys like .386, .3gp and .7z, and HKEY_LOCAL_MACHINE\SOFTWARE showed the keys and values regedit showed. Menus open with WinUI’s fluid animations, and resizing the window is smooth.

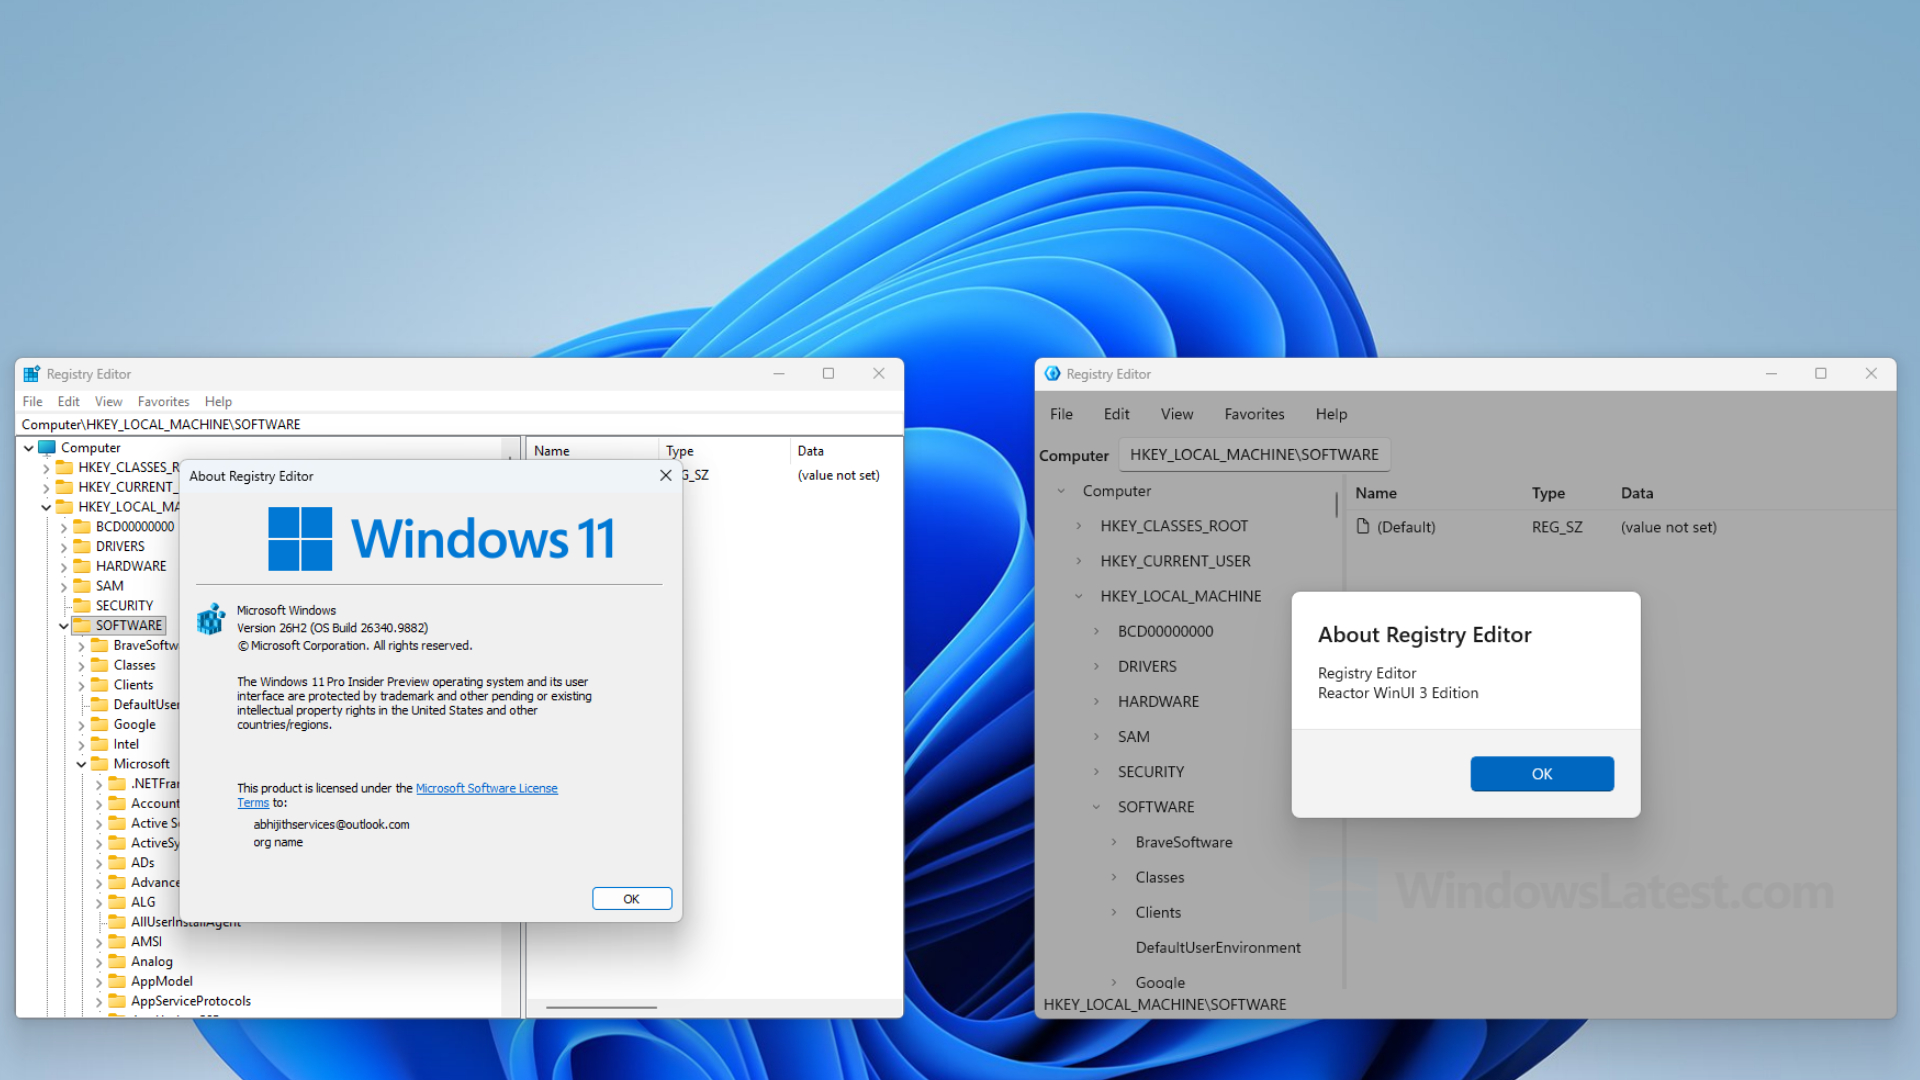
Help > About confirms it’s not a mock-up, as the dialog shows “Registry Editor Reactor WinUI 3 Edition.”

The About dialogs of the legacy Registry Editor and the WinUI sample
The About dialogs of the legacy Registry Editor and the WinUI sample. Credit: Windows Latest

Microsoft uses WinUI 3 and a React-like C# framework to rebuild Registry Editor

Microsoft calls Reactor “an experimental C# framework that brings the MVU (Model-View-Update) pattern to WinUI desktop apps.” In a developer blog post, Principal Software Developer Engineer Alexandre Zollinger Chohfi says the goal is “to find out how far MVU can go on WinUI.”

Reactor is “not a new UI platform,” as Microsoft puts it. Every menu, tree and dialog in the app is a real WinUI control, with no HTML, Electron, or WebView2 involved. The only change is the way developers write the app.

  • The UI is written in C#, without XAML pages, code-behind or ViewModels.
  • Apps are built from components, with React-style hooks like UseState and UseEffect. It’s still C#, not JavaScript React.
  • When state changes, Reactor updates only the controls that changed.
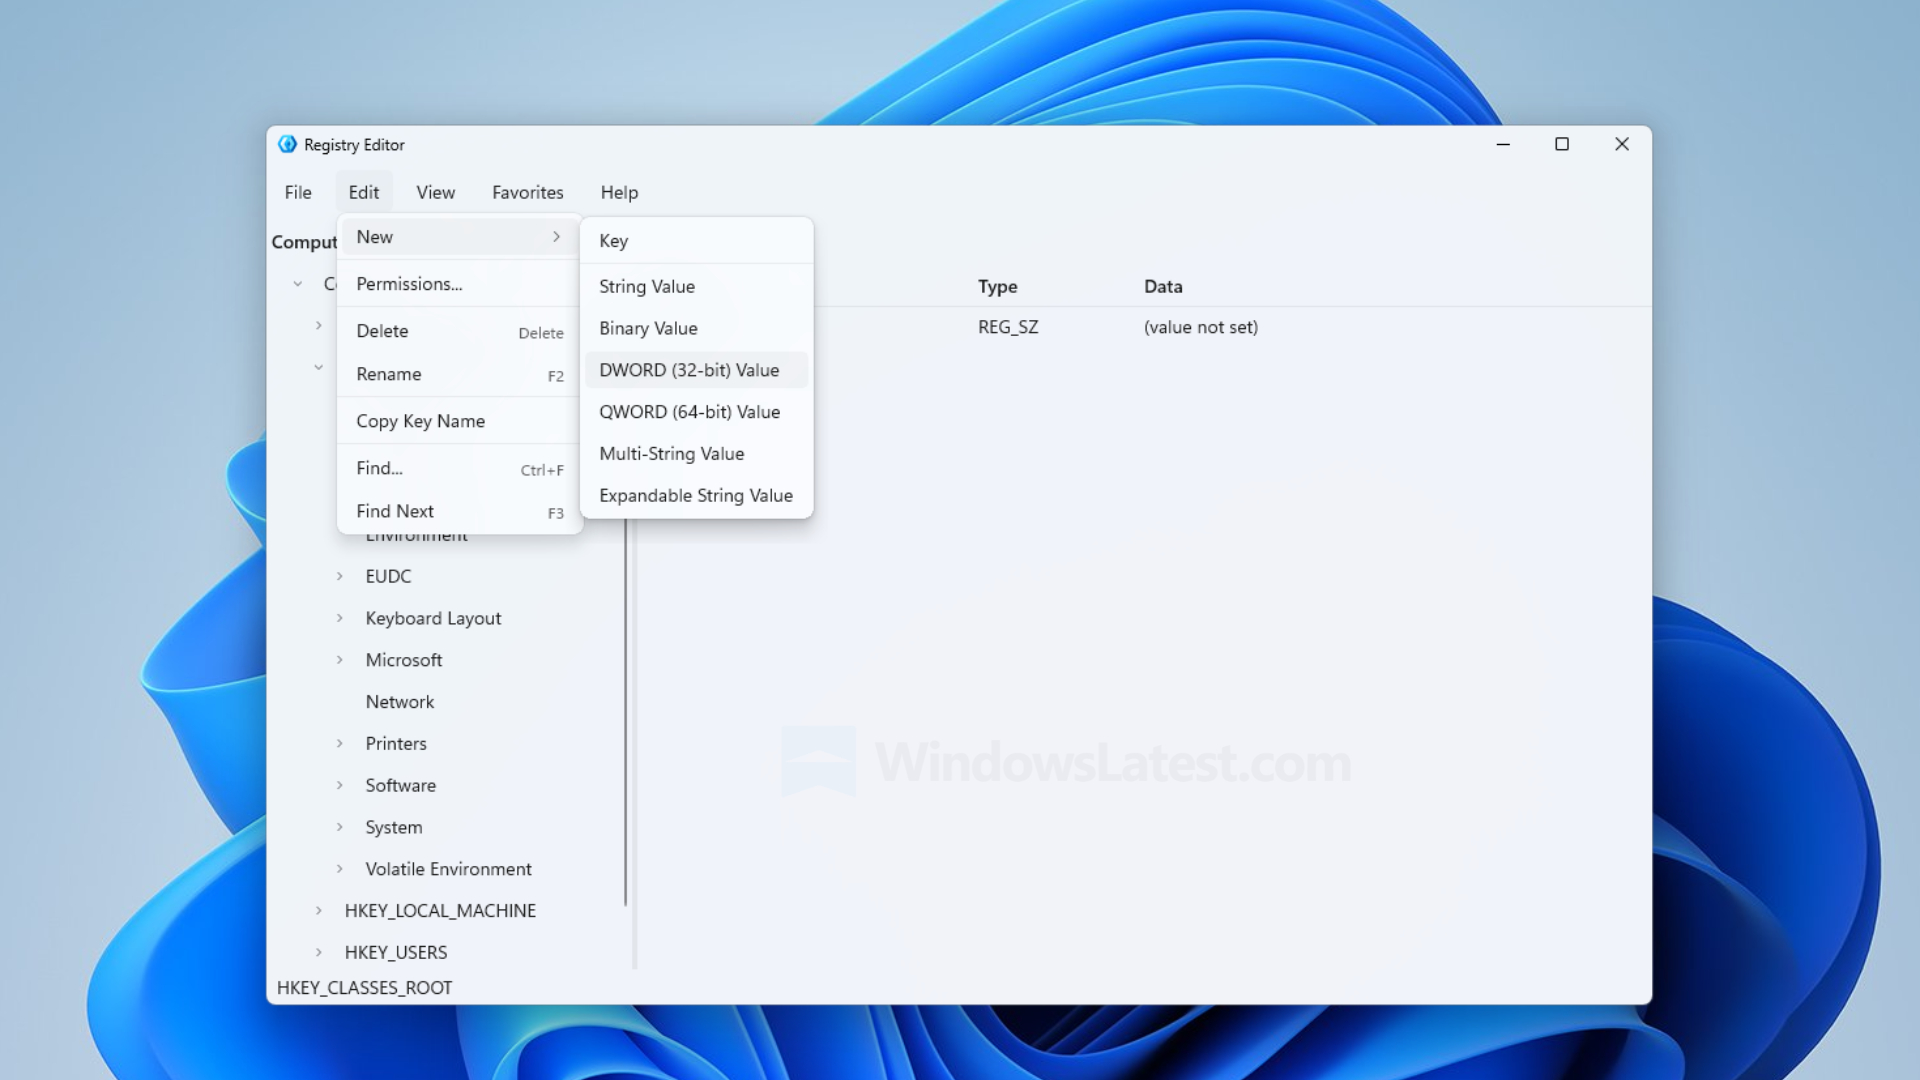
Edit menu in WinUI Regedit sample
Edit menu in WinUI Regedit sample. Credit: Windows Latest

I appreciate that Microsoft didn’t just wrap regedit.exe in a modern window. In the sample’s source code, a separate RegistryService class reads and writes the Registry using .NET’s Microsoft.Win32 APIs and catches permission errors so a protected key doesn’t crash the app. The window also uses Windows 11’s Mica backdrop, which “only samples the desktop wallpaper once” to keep apps fast.

XAML isn’t going anywhere, as Microsoft says “WinUI is the foundation,” and ideas that prove themselves in Reactor could make it into WinUI too. When we covered Reactor, Microsoft pitched it as an easier way to build native apps, including with AI coding tools.

The Registry Editor sample works, but several features are still unfinished

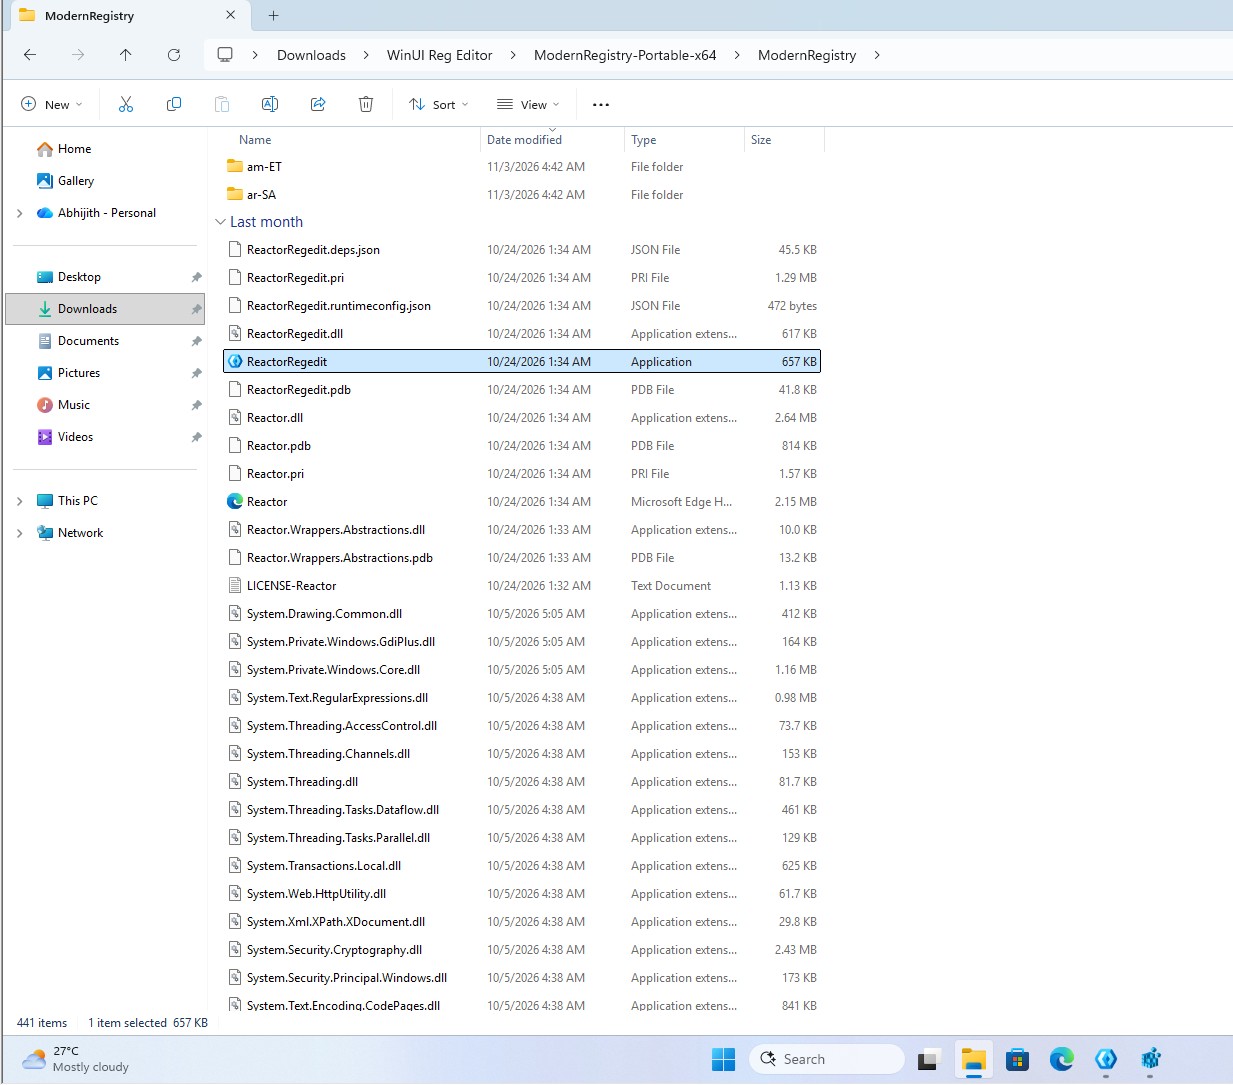
I didn’t write or change any of Microsoft’s code. I only changed the build settings to bundle .NET and the Windows App SDK, which turned the sample into a portable folder that runs without me having to instal anything.

Microsoft's Registry Editor sample compiled into a self-contained portable folder with ReactorRegedit.exe
Registry Editor sample compiled into a self-contained portable folder with ReactorRegedit.exe. Credit: Windows Latest

Microsoft’s code can create, rename and delete keys, add String, Binary, DWORD, QWORD, Multi-String and Expandable String values, and search with Find (Ctrl+F). Since one wrong edit can break Windows, if you’re going to try this, do it in a virtual machine, like I did.

Feature Status in Microsoft’s code
Favorites Not saved after you close the app
Import and export Clipboard only, no .reg file picker
Export All Exports only HKEY_LOCAL_MACHINE
Permissions Menu item does nothing
Load Hive and Unload Hive Placeholders
Network Registry and Print Empty

A comment in the code says Permissions is “out of scope for initial implementation.”

Microsoft’s WinUI modernization is reaching even the oldest Windows tools

Again, the sample doesn’t mean regedit.exe is getting replaced, but Microsoft is thinking about it. On a podcast in August, Marcus Ash, Microsoft’s CVP of Design and Research for Windows, said “even things like Regedit and some of the tooling, we’ve already started to look at.”

Registry Editor would join a growing list.

Microsoft’s design team says more ancient dialogs are next, though Control Panel isn’t going away yet. It’s also cutting WinUI’s RAM usage, so new apps don’t end up heavier than the ones they replace.

The WinUI version is the first time Registry Editor has felt like a Windows 11 app. It still needs Permissions, proper .reg files, and plenty of testing, but if Microsoft ever ships a new Registry Editor, I’d be happy if it looked like this. Would you switch?

The post Microsoft built a native WinUI Registry Editor that makes Windows 11’s regedit look like Windows 95, and I tried it appeared first on Windows Latest

Read the whole story
alvinashcraft
16 hours ago
reply
Pennsylvania, USA
Share this story
Delete

Prompt Management in TypeScript: LangSmith vs Git vs 3 Open-Source Registries

1 Share
Prompt Management in TypeScript: LangSmith vs Git vs 3 Open-Source Registries

null

Continue reading Prompt Management in TypeScript: LangSmith vs Git vs 3 Open-Source Registries on SitePoint.

Read the whole story
alvinashcraft
16 hours ago
reply
Pennsylvania, USA
Share this story
Delete

How Flutter’s Material and Cupertino Decoupling is Changing Cross-Platform UI Development

1 Share

Flutter has long enabled developers to build Android and iOS applications from a shared codebase while supporting platform-specific interfaces through Material and Cupertino widgets. However, because these design libraries were bundled with the Flutter SDK, even minor framework-provided UI improvements could require a complete SDK upgrade, potentially introducing unrelated changes and additional regression testing.

In August 2026, Flutter 3.47 addressed this limitation by introducing independently versioned material_ui and cupertino_ui packages. Officially announced in September 2026, this architectural change allows Flutter’s design libraries to evolve separately from the core framework, with implications for platform-specific UI updates, custom design systems, and long-term application maintenance.

How Decoupling Changes Cross-Platform UI Development

For developers, the change affects more than package updates. It also influences how platform-specific interfaces evolve, how custom design systems are built, and how UI dependencies are managed across applications.

1. Faster Adoption of Platform-Specific UI Changes

Google’s Material 3 Expressive and Apple’s Liquid Glass introduce new visual treatments and interaction patterns. Flutter’s standalone design libraries let teams implement these evolving design systems without waiting for the next Flutter SDK update.

Applications maintaining separate Android and iOS interfaces can incorporate supported design updates through the relevant package, subject to SDK and dependency compatibility. This gives teams greater control over when to adopt new platform conventions without requiring coordinated changes to both UI libraries.

However, decoupling does not automatically deliver native UI behavior. Material and Cupertino remain Flutter-rendered widget libraries, and developers must still implement appropriate platform conventions and validate accessibility, animations, and interactions.

2. Better Foundations for Custom Design Systems

Flutter’s lower-level widgets library historically lacked certain reusable UI capabilities, forcing custom design system developers to recreate components or rely on design-specific implementations.

Alongside decoupling, the Flutter team is addressing gaps in its style-neutral widgets library to provide more reusable building blocks. As more foundational functionality becomes available, developers may be able to reuse common UI behavior without depending on either design library.

Note: These improvements remain ongoing and are not automatically available through the standalone packages.

3. More Explicit UI Dependency Boundaries

Independent design libraries make it more important to identify where reusable components depend on Material or Cupertino APIs. Shared widget packages that expose design-specific classes through public interfaces can become difficult to maintain when applications and third-party dependencies use incompatible library implementations.

As Material and Cupertino evolve independently, these dependencies become more visible, reinforcing the importance of clear boundaries between shared UI components and platform-specific implementations. This separation can help contain the impact of future design-library changes on the wider application architecture.

What Should Developers Consider Before Migrating to Standalone Packages?

Before migrating to standalone Material and Cupertino packages, Flutter app development teams should evaluate their application’s dependencies, UI architecture, and compatibility requirements. The following checks can help reduce migration risks:

1. Audit Third-Party UI Dependencies

Identify packages that expose Material or Cupertino types through public APIs. Dart treats identically named classes from the bundled and standalone libraries as distinct types because they have different library identities. This can cause compilation errors when third-party APIs expect legacy types. Check whether critical dependencies support the standalone packages, and consider deferring migration where compatible versions are unavailable.

2. Assess Shared Widgets and Design-system Dependencies

Review reusable components, theme configurations, and internal UI packages for direct references to legacy Material or Cupertino types. Coordinate updates across shared libraries to prevent incompatible interfaces.

3. Plan for Mixed-library Compatibility

Where legacy and standalone widgets must coexist, evaluate Flutter’s compatibility bridges for inherited theme and localization context. These bridges cannot resolve Dart type mismatches in public APIs, which require compatible package implementations.

4. Update Localization and Validate UI Behavior

Review localization delegates and test navigation, theming, accessibility, animations, and platform-specific interactions after migration. Include widget, integration, and visual regression tests where applicable.

For applications with compatible dependencies, developers can use Flutter’s automated migration command, dart fix — apply — code=migrate_design_widgets, and ensure the standalone packages are added to the project’s dependencies.

For larger applications, developers should first migrate compatible internal packages and verify whether third-party dependencies expose legacy design-library types. Where mixed-library usage is unavoidable, proceed with migration only across tested compatibility boundaries. Applications dependent on incompatible public APIs may need to defer adoption until those packages are updated.

Refer to the official Flutter migration guide for implementation instructions.

Ending Note: A More Modular Future for Flutter UI Development

Flutter’s Material and Cupertino decoupling represents a shift toward independently maintained design systems and more flexible cross-platform architectures. While this creates opportunities for faster UI updates and greater customization, it also introduces new considerations around dependency compatibility and long-term maintenance.

For businesses, the immediate priority is to evaluate whether their existing applications are ready for this transition and where architectural changes may be necessary. Whether the migration is handled internally or with support from experienced Flutter developers, the focus should remain on maintaining application stability while preparing for Flutter’s evolving design-system architecture.


How Flutter’s Material and Cupertino Decoupling is Changing Cross-Platform UI Development was originally published in Flutter Community on Medium, where people are continuing the conversation by highlighting and responding to this story.

Read the whole story
alvinashcraft
16 hours ago
reply
Pennsylvania, USA
Share this story
Delete

LLMs are terrible at designing AI systems

1 Share

LLMs don’t know how to design software that uses LLMs. They’re comfortable writing normal programs, but if you throw an AI-shaped problem at them, they will usually screw it up. Why is that?

Going down the symbolic rabbit hole

For example, this post describes an attempt to vibe-code a memory tool that would flag when one memory contradicted another1. This is a great instance of a task that was virtually impossible five years ago but is now relatively trivial due to LLMs. You can simply task a LLM with scanning for contradictions, either in a big batch or pairwise2.

However, when asked for the “state of the art” approach3, the AI agent in this case did not recommend LLMs. It started building a bewilderingly complex symbolic system to convert the memory items into structured logical atoms, then mechanically compare them with a solver. This, of course, did not and could not work, because there is no analytic way of determining whether any two natural-language sentences express the same proposition.

The LLM knew this was impossible! When the user eventually lost patience and said “hey, why isn’t this working”, Claude immediately explained that this was a known 130-year-old problem with no solution. And yet it happily went around and around for weeks iterating on a dead end.

I’ve run into this myself. When I was building Autodeck (AI-generated spaced repetition cards) my agents would routinely try to categorize cards by regex or keyword search instead of just making another LLM call.

Why can’t LLMs use LLMs correctly?

Why would this be happening? I have two obvious explanations and one deeper one.

The first obvious explanation is that most training code is pre-LLMs. Assuming the labs aren’t feeding the current avalance of slop repositories directly into the models4, the vast majority of the code that models learn from was written before LLMs were an option. So it would make sense that they’d reach for non-LLM approaches, in the same way that they’d reach for jQuery over modern vanilla JS, or Backbone.js over React, right? Wrong, actually! LLMs don’t choose jQuery and Backbone. Whatever part of the training process pushes them towards up-to-date knowledge in other areas isn’t successfully pushing them towards LLMs, so this can’t be the whole story.

The second obvious explanation is that RLVR is not a good environment to write code that calls LLMs. Much of the time LLMs spend training is spent in reinforcement learning environments where an automatic grader determines their performance (for instance, by running some code they wrote and checking the outputs). I don’t know this for a fact, but I would be surprised if these environments contained the credentials and API access for a LLM to call other LLMs5. So even if the pretrained LLM was comfortable writing that kind of code, the reinforcement learning process might discourage6 it from doing so.

The third explanation, which I like the most, is that current AI agents are just not very good at software design. On this explanation, picking a doomed symbolic approach instead of simply calling a LLM is not a weird aberration but a normal instance of AI agents picking the wrong tool for the job. I’ve seen this behavior from LLMs in other contexts too: trying to build complex (and doomed) consensus algorithms instead of tolerating stale data, introducing synchronous checks in event-driven systems, and so on. In the past I’ve chalked these up to alignment, but I’m open to the idea that they’re just ordinary errors of software design.

Conclusion

One lesson I learn over and over again is that I can’t judge a LLM by the standards of a human. Any human programmer who was capable of implementing a sophisticated symbolic solver would know that it wouldn’t work, and so if they suggested that approach I’d assume7 they had a good reason. Only a LLM could be both smart enough and dumb enough to make this mistake.

I write a lot about the skills that are involved in working effectively with LLMs. I still stand by what I wrote in February 2025:

Using LLMs well involves extracting value from what they’re good at and avoiding wasting time at what they’re bad at.

This is surprisingly hard, because of the point above. LLMs are good and bad seemingly at random: they will work hard for hours but sometimes be shockingly low-effort, they will draw on inhumanly broad expertise but fail to apply the most basic common-sense, they can successfully rewrite enormously complex programs but will often make very silly errors in design.

If you can predict where they will do well or badly ahead of time, you can get enormous value from LLMs; if you can’t, you will likely waste a lot of time and tokens going down hopeless approaches.


  1. Here’s another example where the user “implied” that Opus 5.5 should use a judge model and it instead constructed a series of regex checks.

    ↩
  2. Here I’d probably reach for a decision model.

    ↩
  3. In hindsight, this was probably the key mistake, though I don’t know how you’d turn that into advice for non-technical vibe-coders. Never asking the agent about the state of the field is a mistake too. Put one more notch on the LLMs reward expertise belt.

    ↩
  4. A fair assumption, I think: even though training on low-quality synthetic data clearly isn’t catastrophic for LLMs, it can’t be great.

    ↩
  5. It would be expensive, slow, and risky.

    ↩
  6. This theory also explains why LLMs are great at prompting other LLMs as subagents, or on training LLMs from scratch: they’re likely directly RL-ed and evaluated on that, unlike on writing code that calls LLMs.

    ↩
  7. Well, okay, I wouldn’t — I’m arrogant enough to ask anyway — but I’d at least expect a good reason.

    ↩
Read the whole story
alvinashcraft
16 hours ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories