 Log in

How I got a .NET MAUI CollectionView to scroll behind the iPhone Duo's disappearing title bar without hiding its first item.

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|

Pennsylvania, USA


Browse tools.simonwillison.net by tag
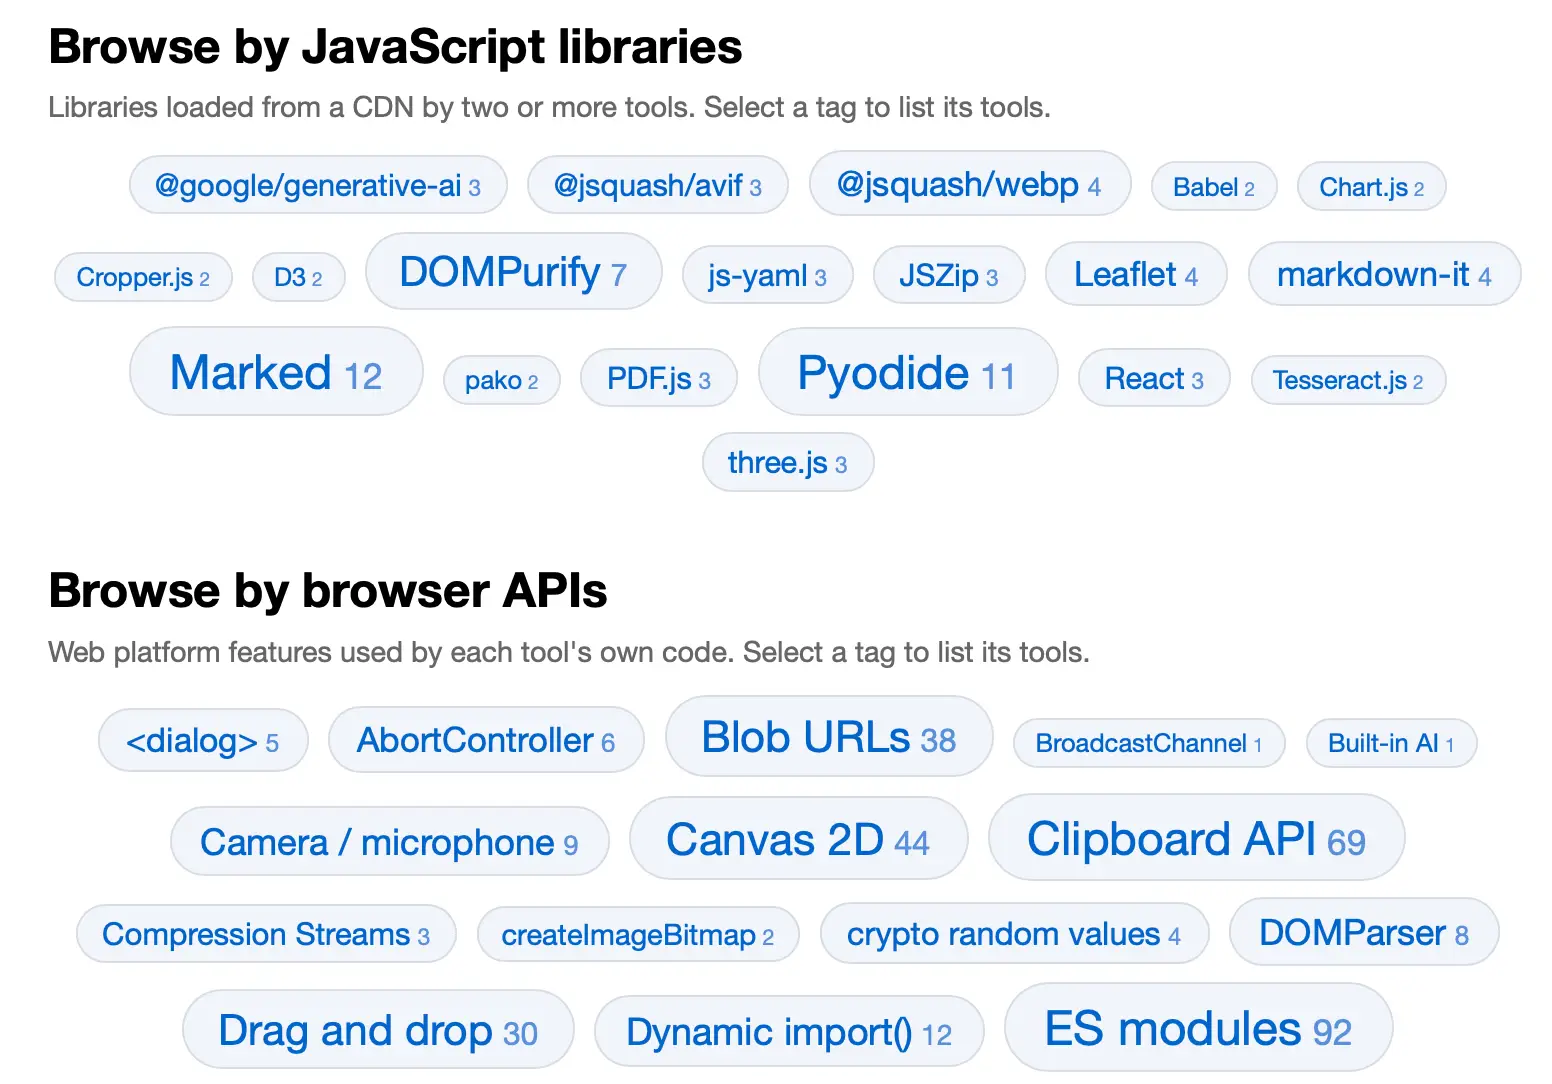
I've been wanting a better way to browse my collection of vibe-coded tools (244 and counting) for a while. I had a few Fable 5.2 credits left over before my weekly reset so I set it to work using tree-sitter to analyze the code for JavaScript APIs, libraries, and web API hosts used by each tool.The homepage now features tag clouds for browsing by each of those categories of tag:
Tags: javascript, tools, ai, generative-ai, llms, claude, vibe-coding
Pennsylvania, USA

.NET MAUI 11.0.10 Release Notes
.NET MAUI 11.0.10 introduces significant improvements across all platforms with focus on quality, performance, and developer experience. This release includes 370 commits with various improvements, bug fixes, and enhancements.
Ai Agents
Animation
-
Fix AnimationManager.Dispose — retained ticker keeps disposed manager and callbacks alive by @HarishwaranVijayakumar in #37639
-
Fix AnimationExtensions.Insert — disposed non-starting manager leaves callback statically rooted by @KarthikRajaKalaimani in #37572
API
Architecture
-
Support consistent XAML type references by @StephaneDelcroix in #39890
Blazor
-
[Windows] Enable external file drops in BlazorWebView by @danroth27 in #37904
-
[BlazorWebView] Fix dispatcher exception propagation by @jfversluis in #37974
-
[Android] Configure image drag support for BlazorWebView by @danroth27 in #37975
-
Fix problem with null VirtualView in BlazorWebViewHandler on iOS by @JimmyPun610 in #38141
-
Fix for handler leaks by traversing non-IView Shell nodes in DisconnectHandlers() by @BagavathiPerumal in #38022
-
[Android]Fix for Android BlazorWebView crash when opening image links in a new window by @BagavathiPerumal in #38195
-
[inflight/current] Fix BlazorWebView root component subscriptions on disconnect (#39247) by @kubaflo in #39252
-
Fix iOS BlazorWebView callbacks after disconnection by @sheiksyedm in #39430
-
[WPF] Fix BlazorWebView disposal hanging when cleanup awaits JS interop by @sheiksyedm in #39497
BlazorWebView
Border
- ContentView and Border: hidden content shouldn't take up space by @FullDevStudio in #39560
Button
-
[Android] Fix ImageButton not rendering when CornerRadius is larger than half its size by @KirkPatrickJunsay in #39344
-
[iOS/Mac] Fix Button with gradient Background ignores CornerRadius by @HarishwaranVijayakumar in #39484
-
[Android]Fix for Android ImageButton Border Visibility and Update Test Snapshots for Issue by @BagavathiPerumal in #39526
CollectionView
-
[Windows] CarouselView: Fix mouse-wheel snapping by @jfversluis in #37387
-
Fix grouped CollectionView EmptyView on iOS by @jfversluis in #37959
-
[Android] CollectionView: Fix grouped EmptyView updates by @jfversluis in #37954
-
[iOS] Horizontal CollectionView jumps to beginning by @SubhikshaSf4851 in #37307
-
[iOS] CollectionView2: Fix layout for dynamically rebuilt item content by @jfversluis in #37437
-
[iOS] Fix CollectionView Label Truncation with MeasureFirstItem by @devanathan-vaithiyanathan in #38338
-
[Android] Prevent CollectionView EmptyView crash after handler disconnect by @Shalini-Ashokan in #38653
-
[Inflight/Candidate] [iOS] Fix for CollectionView layout issue after iOS device rotation by @kubaflo in #38815
-
[inflight/candidate] [iOS] Fix CarouselView template selector crash during cell reconfiguration by @kubaflo in #39254
-
[inflight/candidate] [iOS] Fix CollectionView items disappearing after orientation change by @kubaflo in #39322
-
[inflight/candidate] [Android] Backport grid spacing regression fix for #38925 by @kubaflo in #39335
-
[inflight/candidate] Fix iOS CollectionView selection during Shell navigation by @github-actions[bot] in #39327
-
[inflight/candidate] Fix Windows CollectionView selection crash by @github-actions[bot] in #39329
-
[Inflight/Candidate] Stabilize Looped CarouselView Collection Override Device Test by @HarishwaranVijayakumar in #39217
-
[inflight/candidate] [Mac] Fix blank content in RefreshView with CollectionView during scrolling by @kubaflo in #39357
-
[inflight/candidate] [Android] Fix CollectionView selection with pointer gestures (#37952) by @kubaflo in #39387
-
[Inflight/Candidate][iOS] Fix for unnecessary arrange passes in CollectionView2 by @BagavathiPerumal in #39396
-
[Windows] Fix CollectionView CV2 retention after dynamic removal by @sheiksyedm in #39543
-
[Windows] CollectionView: keep the header in the logical tree on update by @FullDevStudio in #39590
-
[Windows][CV2][Net11] Fix CollectionView exception thrown when ItemsSource is set to Null by @devanathan-vaithiyanathan in #39554
-
[Windows] Fix CollectionView Scrolling with Animate Scroll Disabled by @Vignesh-SF3580 in #39500
-
[net11][Test failure] [Windows]Fix CollectionView2 selection crash during handler disconnection by @BagavathiPerumal in #39706
-
[Inflight/Current] [iOS]Fix for CollectionView layout issue after iOS device rotation by @BagavathiPerumal in #38771
-
[Windows] Fix doubled CollectionView item spacing by @jfversluis in #38960
-
[Android] Fix O(n²) layout cost in CollectionView GridItemsLayout (SpacingItemDecoration + ObservableGroupedSource) by @unrateddi in #38969
🔧 Fixes- [Android] CollectionView with GridItemsLayout: SpacingItemDecoration walks all positions for every cell — ItemsSource assignment and scrolling take seconds to minutes, ANR on fling (regression in 10.0.100)
- [Android] CollectionView GridItemsLayout: span lookups over uncached positions are O(position) per cell, O(position²) when grouped — ScrollTo last group takes ~38 s for 10 000 items, scrolling up after a jump stutters
-
[inflight/current] [Mac] Fix VoiceOver announcement for actionable CollectionView items by @kubaflo in #39012
-
[Android] CollectionView GridItemsLayout: resolve span index and row from the items source instead of walking every position by @unrateddi in #39063
-
[Android] Keep CarouselView Position when CurrentItem isn't in the ItemsSource by @MykhailoDav in #39151
-
[Android] Prevent unnecessary CollectionView item recreation on Header/Footer updates by @SuthiYuvaraj in #38808
-
[Android] Keep EmptyViewAdapter view types from matching the items adapter's by @MykhailoDav in #39193
-
[iOS] Fix vertical CarouselView Position synchronization by @SubhikshaSf4851 in #39377
-
[Windows] Fix excessive blank space between CollectionView grid items by @Shalini-Ashokan in #39429
-
[iOS/MacCatalyst] Fixed CollectionView: Preserve visible position when item spacing changes by @KarthikRajaKalaimani in #37032
-
[iOS/Mac] Fix CollectionView2 height not updating when ItemsSource changes by @SyedAbdulAzeemSF4852 in #38441
-
[Windows] Fix EmptyViewTemplate not displayed when ItemsSource is set to Null by @devanathan-vaithiyanathan in #39513
-
[Windows] Avoid CollectionView GroupHeaderStyleSelector accumulation by @sheiksyedm in #39525
-
[iOS] Collapse CollectionView group headers when their content is hidden by @carloshenriquecarniatto in #39533
-
[iOS] Fix Label truncation after item text updates in CollectionView by @devanathan-vaithiyanathan in #39558
-
[Windows] Fix Compatibility CollectionView compilation on inflight/candidate by @sheiksyedm in #39662
-
[iOS, Catalyst] Fix IndicatorView not visible when applying RTL FlowDirection with IndicatorTemplate by @devanathan-vaithiyanathan in #39501
-
[inflight/Candidate]Fix CollectionViewItemSafeAreaEdgesShouldBePreservedWithShadow UI test failure by @devanathan-vaithiyanathan in #39698
-
[Inflight/Candidate][Revert] [iOS] Fix for CollectionView layout issue after iOS device rotation #38771 by @TamilarasanSF4853 in #39707
-
[NET 11][Windows] Fix CollectionView crashes when multiple CollectionViews share the same ObservableCollection by @devanathan-vaithiyanathan in #39760
-
[iOS/Mac][Revert] CollectionView2 height-update fix (#38441) by @SyedAbdulAzeemSF4852 in #39856
-
[main] [iOS/MacCatalyst] Fix RTL CollectionView item positioning after rotation by @github-actions[bot] in #39894
Core Lifecycle
-
[Windows] Mark MauiWinUIApplication properties obsolete by @jfversluis in #37957
-
[inflight/candidate] Revert deferred Android Loaded event (#38769) by @kubaflo in #38784
DateTimePicker
-
[iOS] Fix TimePicker forcing en-US culture on iOS instead of device culture by @SyedAbdulAzeemSF4852 in #37797
Docs
-
Use country/region consistently in Locale documentation by @jfversluis in #39980
-
[docs] Explain workload set and Visual Studio insertion handoff by @rmarinho in #39977
Drawing
-
[Windows] Fix GraphicsView crash during repeated drawing by @jfversluis in #37419
-
[Windows] Fix Border clipping for transformed content by @jfversluis in #37424
-
Use SkiaSharp arc drawing API by @jfversluis in #37955
-
[iOS, Mac] Fix GraphicsView drawable shadows ignoring FlowDirection by @SyedAbdulAzeemSF4852 in #39544
-
Fix TransformGroup memory leak with shared TransformCollection by @SyedAbdulAzeemSF4852 in #38738
-
Fix GeometryHelper flatteners generating NaN points when segment count truncates to 0 by @HarishwaranVijayakumar in #38814
-
Fix PathFigure memory leak with shared PathSegmentCollection by @devanathan-vaithiyanathan in #38744
-
[Android] Fix Shape clipping after display density changes by @HarishwaranVijayakumar in #39249
-
[iOS] Fix SafeAreaEdges on a CollectionView/CarouselView item template root is ignored when the root has a Shadow by @KarthikRajaKalaimani in #39255
-
Fix Rectangle Rendering as a Thin Line for Small Heights by @Dhivya-SF4094 in #37319
Editor
-
[Windows] TextBox: Cache template ScrollViewer by @jfversluis in #38027
-
[Android] Fix Material 3 Editor expanding to MaximumHeightRequest by @Shalini-Ashokan in #38587
-
[inflight/candidate] [iOS] Editor can't be scrolled after rotating simulator. by @github-actions[bot] in #39318
Entry
-
[Windows] ScrollView: Prevent automatic Entry focus by @jfversluis in #37428
-
[Testing] Refactoring Feature Matrix UITest Cases for Entry Control by @LogishaSelvarajSF4525 in #37111
-
[Android] Fix numeric Entry decimal-point input in comma-decimal cultures by @sheiksyedm in #39286
Essentials
-
[Android] Use typed API 33 Parcelable overload by @jfversluis in #37956
-
[Android] Geolocation: Select providers explicitly on API 34 by @jfversluis in #37976
-
[Android] MediaPicker: Stop overwriting picked source files by @mattleibow in #38029
-
[iOS] Migrate deprecated Browser, FilePicker, and font APIs by @jfversluis in #38025
-
[Android] Validate physical paths returned by pickers by @mattleibow in #38127
-
[iOS] Fix OrientationStateTrigger updates on iOS 27 by @sheiksyedm in #39709
-
[iOS] DeviceDisplay: Track scene geometry and display handoffs by @jfversluis in #39870
Essentials Devicedisplay
Frame
General
-
Fix GradientBrush memory leak with shared GradientStops by @SyedAbdulAzeemSF4852 in #37893
-
Fix ARGB value for MediumPurple color by @TomasGnG in #39077
Gestures
-
[Controls] Remove unused DropResult property by @jfversluis in #37401
-
[Windows] InputTransparent: Respect wrapper view hit testing by @jfversluis in #37392
-
[iOS/MacCatalyst] Fix for TapGestureRecognizer.NumberOfTapsRequired is not reactive at runtime by @SuthiYuvaraj in #38551
-
[Android] Don't throw when a PanUpdated handler removes the view as the pan starts by @MykhailoDav in #39153
Grid
- Fix Grid definition and nested-grid position invalidation by @mattleibow in #39409
Hybridwebview
-
[Testing] Refactoring Feature Matrix UITest Cases for HybridWebView Control by @HarishKumarSF4517 in #39179
-
[NET11] [Android][Test Failure] Fix HybridWebView remains attached to its parent after handler disconnect by @KarthikRajaKalaimani in #39695
-
[iOS]Fix for HybridWebView JavaScript Evaluation Exceptions and Incomplete Requests by @BagavathiPerumal in #39469
Image
-
[iOS/Mac] Fix Image not enlarging to explicit HeightRequest/WidthRequest by @SyedAbdulAzeemSF4852 in #37267
-
Fix app crash when loading large URI images by @jonathanpeppers in #38204
-
[Android] Fix blurry Material 3 images when scaled by @SubhikshaSf4851 in #38362
-
[leak scan] Fix image-source service collection retention leak by @SubhikshaSf4851 in #38743
-
[Windows] Fix Image AspectFit when the bitmap is already decoded by @Empiree in #39343
-
[Graphics] PlatformImage: Read PNG dimensions from IHDR by @Nacl-HCl in #39378
-
[Candidate-TestFailure][Windows] Render registered toolbar font icons through the image service by @sheiksyedm in #39750
Label
-
[Android/iOS] Fix Label background not clearing when set to null by @Shalini-Ashokan in #37182
-
Fix SetDynamicResource does not update the Background property of the Label by @KarthikRajaKalaimani in #38063
-
[release] Derive prerelease labels and SR stabilization from source branches by @kubaflo in #40042
Layout
-
Fix effective visibility propagation by @jfversluis in #37546
-
Fix irregular placement of views with margins by @SyedAbdulAzeemSF4852 in #37080
-
[inflight/candidate] [iOS 27] Fix TitleView sizing before navigation bar layout (#39285) by @kubaflo in #39389
-
[iOS] Use window scene display for layout decisions by @jfversluis in #38911
-
Handlers: Add opt-in initialization attribution by @StephaneDelcroix in #37836
-
[Android] Fix popup centering when content and margins exceed layout bounds by @sheiksyedm in #39561
-
[inflight/current] [iOS] Use window scene display for layout decisions by @kubaflo in #39595
-
[Test failure] Restricted the windows Issue38059_UntemplatedHorizontalGridLayout cv1 by @Ahamed-Ali in #39875
-
Add delayed BindableLayout context coverage across XAML inflators and Mac Catalyst by @rmarinho in #39986
-
[Testing] Update Mac Layout screenshot baselines and exclude crash-prone tests by @Ahamed-Ali in #40017
Listview
-
[iOS] Don't update a disconnected image handler when a cancelled load fails by @MykhailoDav in #39149
Localization
-
[inflight/current] Fix culture-dependent FontSize design-time validation by @noiseonwires in #39694
-
Reenable remaining localization tests with hermetic Helix inputs by @rmarinho in #39976
Map
-
[iOS/MacCatalyst] Map bicycling navigation to cycling directions by @jfversluis in #37942
Mediapicker
-
[Windows] MediaPicker: Apply EXIF orientation only once by @jfversluis in #38591
-
[Android] Fix MediaPicker launcher disposal after garbage collection by @sheiksyedm in #39710
Modal
- [Net11][Android][Test Failure] Fix modal dismissal race during entrance animation by @SyedAbdulAzeemSF4852 in #39731
Navigation
-
[iOS] Fix NavigationPage and Shell: Respect back-button handling for interactive pop gestures by @Dhivya-SF4094 in #38071
-
[Android] Fix SafeArea navigation insets and keyboard test polling by @kubaflo in #38665
-
Throw a clear exception when a Shell route doesn't create a Page by @MykhailoDav in #39186
-
[Android] Don't throw an IllegalArgumentException for every page popped from a NavigationPage by @MykhailoDav in #39183
-
[Android] Don't throw when a modal NavigationPage is dismissed while it's navigating by @MykhailoDav in #39181
-
[Android] Fix stretched Shell back button icon when IconOverride is not square by @KirkPatrickJunsay in #39366
-
[iOS] Prevent NavigationRenderer pop continuation from accessing a disposed renderer by @sheiksyedm in #39458
Navigationpage
-
[iOS] Read NavPage once in SetStatusBarStyle so the null guard is effective by @tomcurran in #38154
Packaging
-
[inflight/current] Fix workload packaging targeting-pack restore by @kubaflo in #38594
-
Add versioned Controls package upgrade skills prototype by @jfversluis in #39272
Performance
-
Fix memory leak in VisualDiagnostics.VisualTreeChanged by backing the static event with WeakEventManager by @Shalini-Ashokan in #37382
-
Fix memory leak when removing VisualState state triggers by @Shalini-Ashokan in #38444
-
[inflight/candidate] Fix Resizetizer System.Memory compatibility for SVG filters and text by @kubaflo in #39388
-
Fix leak-fixer evidence filtering before bot trust evaluation by @kubaflo in #39457
-
Fix [leak-scan] VisualStateGroupList.Clear — removed groups keep triggers attached by @KarthikRajaKalaimani in #38439
-
[leak scan] Fix handler collection retention memory leak by @Shalini-Ashokan in #38768
-
[leak-scan] Fix VisualState trigger lifecycle when states are added or removed by @Vignesh-SF3580 in #38550
-
[Leak scan] Fix MauiHotReloadHelper.currentViews — disabled unregister leaves views rooted by @SubhikshaSf4851 in #38657
Picker
-
Fix Picker memory leak caused by ItemsSource collection subscription by @devanathan-vaithiyanathan in #37813
-
[Android] Fix Material 3 - Picker editor field ignores Material 3 styling by @Dhivya-SF4094 in #39551
-
Select a Picker SelectedItem that was set before its ItemsSource by @MykhailoDav in #39175
ProgressBar
Refreshview
-
[iOS, Mac] Fix RefreshView pull gesture when IsRefreshEnabled is false by @SyedAbdulAzeemSF4852 in #39486
Resizetizer
- [Resizetizer] Reenable integration tests by @jfversluis in #37973
SafeArea
-
[iOS] Fix for ScrollView SafeAreaEdges="Container" Double Safe-Area Reservation Causing Phantom Scroll Range by @BagavathiPerumal in #37765
-
[Android] Fix incorrect top padding when translating views offscreen by @devanathan-vaithiyanathan in #37772
-
[Android] Route Issue36543 to SafeAreaEdges UI tests by @jfversluis in #38097
-
[Android] Fix for safe area flicker during keyboard dismissal by @BagavathiPerumal in #37935
-
[inflight/candidate] Backport Android safe-area resize fix (#36474) by @kubaflo in #39336
-
[Android] Enable native edge-to-edge and fix dynamic system bar icon colors by @praveenkumarkarunanithi in #36226
-
Revert "[net11] Fix Android screenshot cropping using reported status… by @Ahamed-Ali in #39748
ScrollView
-
[iOS] ScrollView: Complete every superseded or dropped scroll request's task by @albyrock87 in #37666
-
[Android] Prevent vertical scroll in horizontal ScrollView by @Shalini-Ashokan in #37880
-
[Testing] SafeArea Feature Matrix Test Cases for ScrollView by @TamilarasanSF4853 in #38299
-
[iOS] Fix Infinite Measure Looping on iOS by @HarishwaranVijayakumar in #38197
-
[Inflight/Candidate] [Windows] Fix ScrollView handler leak in device test by @Vignesh-SF3580 in #39060
-
[inflight/candidate] Fix iOS PageSheet ScrollView flicker by @github-actions[bot] in #39330
-
[inflight/candidate] Fix Android WebView blocking parent scrolling by @github-actions[bot] in #39326
-
[inflight/candidate][iOS] Fix ScrollView PageSheet detection without reverting the flicker fix by @kubaflo in #39472
-
[Android] ScrollView: Apply runtime padding updates immediately by @Dhivya-SF4094 in #38985
-
[Android] Fix ScrollToAsync UI-thread livelock caused by the MapRequestScrollTo retry loop by @philipag in #39213
Searchbar
- [Testing] Refactoring Feature Matrix UITest Cases for SearchBar Control by @NafeelaNazhir in #38191
Setup
-
[net11.0] Remove bundled Tizen support by @rmarinho in #39531
-
Fix misleading MA002 warning text about implicit package references by @Ahmed-Manai in #39858
Shapes
-
Minimize CI workflow failures and pipeline start comments by @kubaflo in #39564
-
docs: fix Helix queues and device-test pipeline path in DevelopmentTips by @ZainnQureshii in #38850
-
Fix PathGeometry leak with shared PathFigureCollection by @SyedAbdulAzeemSF4852 in #38946
-
[api] Ship remaining public API baselines on main by @kubaflo in #39857
-
Enable MAUI Labs in the official release pipeline by @rmarinho in #39978
Shell
-
[leak-scan] Fix: ShellContent.Content shared Page.PropertyChanged retains prior ShellContent instances by @SubhikshaSf4851 in #37390
-
[Android] Add native element registrations for DevFlow by @morning4coffe-dev in #36835
-
Fix BackButtonBehavior.Command CanExecuteChanged memory leak by @devanathan-vaithiyanathan in #37771
-
[Android]Fix Navigation stops working when changing Window[0].Page from Shell by @devanathan-vaithiyanathan in #38159
-
[leak-scan] Routing.s_implicitPageRoutes — cancelled Shell push retains the page by @SubhikshaSf4851 in #38404
-
[iOS] Fix modal page content not shown on subsequent navigation for singleton lifetime pages by @HarishwaranVijayakumar in #38402
-
[Android] Restore native theme colors instead of hardcoded defaults for Shell/TabbedPage appearance under Material 3 by @SuthiYuvaraj in #37147
-
[Windows]Fix TabBar transition animation not completing by @SubhikshaSf4851 in #38637
-
[iOS] Center FontImageSource glyphs on iOS 26 without changing font metrics by @kubaflo in #39230
-
[inflight/candidate] Backport iOS Shell More re-evaluation fix (#39264) by @kubaflo in #39320
-
[inflight/candidate] Fix Shell flyout VisualState hang by @github-actions[bot] in #39331
-
Shard Shell UI tests into two CI lanes on all platforms by @Ahamed-Ali in #39359
-
Fix Leak Fixer validation shell permissions by @kubaflo in #39475
-
Fix CI-fixer empty-queue PowerShell module discovery by @kubaflo in #39522
-
[.NET 11] [iOS/Android] Shell: Render gradient backgrounds on bottom tab bars by @Dhivya-SF4094 in #37137
🔧 Fixes -
[Android][Material 3] Fix Shell navigation bar background color not applied by @HarishwaranVijayakumar in #39660
-
[Testing] Android shell renderer lane by @Ahamed-Ali in #39427
-
[net11] [Test Failure] [Android] Fix Android device test failure for Root Replacement During Flyout Construction Publishes Latest Root by @Vignesh-SF3580 in #39692
-
[net11] [Test Failure] [Android] Fix Shell UI test failure caused by incorrect icon colors by @Vignesh-SF3580 in #39697
-
[Material3] Fix tab selection indicator color on theme change by @SyedAbdulAzeemSF4852 in #38445
-
Fix ShellItem.MenuItem memory leak caused by implicit wrapper by @devanathan-vaithiyanathan in #38804
-
[iOS] Ignore a pending Shell back navigation after the section renderer is disposed by @MykhailoDav in #39152
🔧 Fixes -
[Windows] Shell: Apply TabBarDisabledColor to disabled tabs by @Dhivya-SF4094 in #35885
-
[iOS] Fix iOS 26 blank page on rapid Shell tab re-selection by @SubhikshaSf4851 in #39360
-
[Android] Fix SearchHandler toolbar icon tint when Shell.ForegroundColor is set on a TabBar, Tab, or ShellContent by @edgiardina in #39346
-
[Windows] Fix crash when clicking a tab with sub tabs in the Shell TabBar overflow menu by @Empiree in #39412
-
[Android] Fix Shell Renderer Content Layout in RTL Locked Mode by @Vignesh-SF3580 in #39462
-
Fix Shell Flyout item ordering when CurrentItem is set in XAML by @SubhikshaSf4851 in #39541
-
[Net11][iOS][Test Failure] Fix missing Shell top tab after navigation appearance reset by @Shalini-Ashokan in #39752
-
[Net11] Resaved ShellColorsResetOnNavigation Mac image by @TamilarasanSF4853 in #39766
-
[Windows] Shell: Port SR13 disabled-foreground crash fix to main by @kubaflo in #39833
-
[TestFailure] [iOS] Fix Shell badge color UI test failures by @Vignesh-SF3580 in #39829
-
[Windows] Prevent duplicate Shell startup navigation from stale tab selection events by @sheiksyedm in #39887
Single Project
-
[iOS] Fix splash screen image not appearing by @SubhikshaSf4851 in #39426
SwipeView
-
Fix SwipeView memory leak when Content is shared across instances by @SyedAbdulAzeemSF4852 in #38101
-
Fix SwipeItemView Command Memory Leak by @devanathan-vaithiyanathan in #38316
-
Fix SwipeMenuItems were rendered to the full width of the SwipeView instead of their measured width on Android, iOS, and macOS by @KarthikRajaKalaimani in #38271
-
Wait for SwipeView command result before UI assertion by @kubaflo in #39092
-
[Testing] Refactoring Feature Matrix UITest Cases for SwipeView Control by @LogishaSelvarajSF4525 in #38193
-
[Android] Fix SwipeItem tap with fixed-width SwipeView content by @Shalini-Ashokan in #39314
-
[Android] Fix xUnit2031 warning in Android SwipeView device test by @HarishwaranVijayakumar in #39375
-
Resave the image of VerifyCollectionViewContentWithIconImageSwipeItem in iOS 18.5 by @KarthikRajaKalaimani in #39827
Switch
TabbedPage
-
Fix Windows TabbedPage back-nav crash when tabs are shared (fixes #26214) by @jshield in #38280
🔧 Fixes -
Fix default styles for derived NavigationPage and TabbedPage by @SubhikshaSf4851 in #38593
-
[Android] Fix TabbedPage: Selected tab icon loses SelectedTabColor after rebuilding Children by @SubhikshaSf4851 in #38801
-
[iOS 26] Fix TabbedPage tab bar layout by @SyedAbdulAzeemSF4852 in #38659
Templates
-
[A11y] Fix VoiceOver does not announce project description when navigating project cards by @KarthikRajaKalaimani in #37385
-
[A11y] [Windows] Fix CollectionView items announcing internal type name instead of item content in Narrator by @praveenkumarkarunanithi in #37421
-
Bumps Syncfusion.Maui.Toolkit dependency to version 1.0.11 by @PaulAndersonS in #38393
Titlebar
-
[Mac] Fixed the Issue with the TitleBar TrailingContent not being properly aligned by @Ahamed-Ali in #36541
Toolbar
-
[iOS/MacCatalyst] Fix NavigationRenderer toolbar items losing custom tint on IsEnabled changes by @praveenkumarkarunanithi in #39062
-
[inflight/candidate] [iOS] Make toolbar items ready for vertical presentation by @kubaflo in #39321
-
[Windows] Fix font toolbar icons when text is present by @jfversluis in #39685
Tooling
-
[Android] Remove obsolete XA4218 workaround by @jfversluis in #37941
-
[iOS/Mac Catalyst] Add native element registrations for DevFlow by @morning4coffe-dev in #36821
-
[net11] Fix culture-dependent FontSize design-time validation by @noiseonwires in #39691
-
[XAML] Refresh implicit styles after incremental Hot Reload setter edits by @StephaneDelcroix in #39928
WebView
-
[Windows] Fixed : WebView CanGoBack Returns true when it Shouldn't by @SubhikshaSf4851 in #37648
-
[Android] Fix off-screen WebView crash without changing generic view handlers by @kubaflo in #38467
-
[Windows] WebView: Guard failed WebView2 initialization by @jfversluis in #38569
-
[Windows] Fix WebView rendering alongside HybridWebView by @sheiksyedm in #39512
Window
-
Fix and Re-enable "Window Does Not Leak" and "Does Not Leak" Memory Leak Device Test by @BagavathiPerumal in #37310
-
[Android] Prevent fragment crashes during Shell and FlyoutPage root replacement by @kubaflo in #38214
-
[Mac] Fix window freeze during repeated resizing by @Vignesh-SF3580 in #38398
Xaml
-
Fix MauiXaml will generate source for every xaml file without respect to its condition by configuration/target by @KarthikRajaKalaimani in #37176
-
Fix race in WeakEventProxy field access by @baaaaif in #37568
-
[XAML SourceGen] Make compiled bindings null-tolerant for intermediate members by @simonrozsival via @Copilot in #36444
-
[Xaml] Fix static C# expressions using global usings by @StephaneDelcroix in #34926
-
[XAML] Fix unmatched OnPlatform default handling in XamlC and SourceGen by @praveenkumarkarunanithi in #38158
-
Keep one DynamicResource registration per specificity by @otretiak in #38152
-
Fix MultiBinding Strong Target Reference Leak by @devanathan-vaithiyanathan in #38315
-
Trim unused XAML runtime code from linked apps by @simonrozsival in #38613
-
[XSG] Infer generic type for OnIdiom markup extensions by @simonrozsival in #38661
-
Fix compiled binding generation for null-conditional SetBinding calls by @Shalini-Ashokan in #38651
-
[Candidate Failure]Fix x_Array_Parsed test Failure by @SubhikshaSf4851 in #38840
-
[inflight/candidate] Fix runtime XAML trimming regression by @github-actions[bot] in #39328
-
Make CodeBehind generator incremental to fix EnC rude edits on x:Name changes by @StephaneDelcroix in #39281
-
[net11.0][XAML] Preserve whitespace-padded names in runtime field lookups by @kubaflo in #39568
-
[CI] Reduce build and Windows XAML warnings by @rmarinho in #38735
-
[Windows] Restore native binding metadata baseline to fix maui-pr by @kubaflo in #39622
-
Improve error message xaml sg by @pictos in #38712
🔧 Fixes -
[XSG] Make global xmlns generation deterministic by @noiseonwires in #38842
-
Fix typed bindings invoking generated getters with missing ancestor sources by @jfversluis in #39470
🔧 Infrastructure (41)
-
Bump the aspnetcore group with 3 updates by @dependabot[bot] in #36865
-
Fix stale StatesChanged subscription when replacing VisualStateGroupList item by @devanathan-vaithiyanathan in #37340
-
[iOS] Remove obsolete environment variable workaround by @jfversluis in #37939
-
[inflight/candidate] [Mac]Fix initial blank page in I6_Vertical_Item_Spacing_Page on iOS 27 by @github-actions[bot] in #39319
-
[main] Update dependencies from dotnet/xharness by @dotnet-maestro[bot] in #39452
-
[CI-Improvement]Retry only failing UI-test categories across all platforms by @Ahamed-Ali in #39421
-
[net11.0] Update dependencies from dotnet/android by @dotnet-maestro[bot] in #39480
-
[ci] Remove unused SDK insertion templates by @kubaflo in #39519
-
[ci] Retry pre-test setup up to five total attempts by @kubaflo in #39549
-
[CI-Improvement]Retry only failed individual UI tests across all platforms by @Ahamed-Ali in #39509
-
Bump the aspnetcore group with 3 updates by @dependabot[bot] in #39683
-
Fix memory leak when replacing IndicatorView.IndicatorTemplate by @devanathan-vaithiyanathan in #39353
-
Create CI fix PRs directly without scan issues by @kubaflo in #39711
-
Bump the windowsappsdk group with 1 update by @dependabot[bot] in #39745
-
[net11] Restore promotion builds and native test coverage by @kubaflo in #39779
-
Bump the skiasharp group with 1 update by @dependabot[bot] in #39804
-
Bump cake.tool from 4.0.0 to 6.3.0 by @dependabot[bot] in #39809
-
Bump api-tools from 1.3.5 to 1.4.1 by @dependabot[bot] in #39808
-
Bump Magick.NET-Q8-AnyCPU from 14.15.0 to 15.0.0 by @dependabot[bot] in #39810
-
Bump Markdig from 0.31.0 to 1.5.0 by @dependabot[bot] in #39811
-
Bump Microsoft.DotNet.Build.Tasks.Feed from 11.0.0-beta.26514.118 to 11.0.0-beta.26531.101 by @dependabot[bot] in #39816
-
Bump Microsoft.VisualStudio.DesignTools.Extensibility from 17.5.33428.366 to 17.10.34916.79 by @dependabot[bot] in #39820
-
Bump Mono.ApiTools.MSBuildTasks from 0.4.0 to 0.6.0 by @dependabot[bot] in #39821
-
Bump powershell from 7.4.0 to 7.6.9 by @dependabot[bot] in #39822
-
Bump Microsoft.CodeAnalysis.BannedApiAnalyzers from 4.14.0 to 5.6.0 by @dependabot[bot] in #39813
-
Bump Microsoft.DotNet.Arcade.Sdk from 11.0.0-beta.26514.118 to 11.0.0-beta.26531.101 by @dependabot[bot] in #39815
-
Bump microsoft.maui.cli from 0.1.0-preview.10.26274.3 to 0.1.0-preview.14.26531.2 by @dependabot[bot] in #39818
-
Bump Microsoft.DotNet.Helix.Sdk from 11.0.0-beta.26514.118 to 11.0.0-beta.26552.106 by @dependabot[bot] in #39843
-
Bump Microsoft.DotNet.Build.Tasks.Feed from 11.0.0-beta.26531.101 to 11.0.0-beta.26552.106 by @dependabot[bot] in #39842
-
Test direct CI scanner validation reconciliation by @PureWeen in https://github.com/dotnet/maui/pull/39740
-
[ci] Prepare main for .NET 11 SR1 and retire net11 merge routes by @kubaflo in https://github.com/dotnet/maui/pull/39805
-
[CI] Include Build Insights reports in test-review context by @PureWeen in https://github.com/dotnet/maui/pull/39735
-
Bump microsoft.maui.cli from 0.1.0-preview.14.26531.2 to 0.1.0-preview.14.26553.1 by @dependabot[bot] in https://github.com/dotnet/maui/pull/39869
-
[ci] Move MacCatalyst UI tests to ACES Tahoe by @kubaflo in https://github.com/dotnet/maui/pull/39876
-
Bump Microsoft.DotNet.Helix.Sdk from 11.0.0-beta.26552.106 to 11.0.0-beta.26553.104 by @dependabot[bot] in https://github.com/dotnet/maui/pull/39868
-
Bump Microsoft.DotNet.Build.Tasks.Feed from 11.0.0-beta.26552.106 to 11.0.0-beta.26553.104 by @dependabot[bot] in https://github.com/dotnet/maui/pull/39867
-
[ci] Fix dependency ownership and stale post-promotion checks by @kubaflo in https://github.com/dotnet/maui/pull/39886
-
Bump Markdig from 1.5.0 to 1.5.1 by @dependabot[bot] in https://github.com/dotnet/maui/pull/39908
-
Update Magick.NET to 14.17.2 while preserving screenshot comparison scores by @dependabot[bot] in https://github.com/dotnet/maui/pull/39897
-
Bump microsoft.maui.cli from 0.1.0-preview.14.26553.1 to 0.1.0-preview.14.26555.4 by @dependabot[bot] in https://github.com/dotnet/maui/pull/39955
-
Reenable FileVersion tests using Arcade build metadata by @rmarinho in https://github.com/dotnet/maui/pull/39982
🧪 Testing (2)
- [net11] Fix CollectionView and MediaPicker recovery device-test failures by @praveenkumarkarunanithi in https://github.com/dotnet/maui/pull/39665
- [Testing] [macOS] Fix screenshot masking and scaling for Retina (high-DPI) displays by @Ahamed-Ali in https://github.com/dotnet/maui/pull/39912
📦 Other (62)
-
[Testing] Refactoring Feature Matrix UITest Cases for IndicatorView Control by @NafeelaNazhir in https://github.com/dotnet/maui/pull/38399
-
[Android] Prevent AppBar lift target crash under GC pressure by @simonrozsival in https://github.com/dotnet/maui/pull/38636
-
Controls: Remove Regex from ShadowTypeConverter by @simonrozsival in https://github.com/dotnet/maui/pull/38615
-
[Testing] Fixed Test case failure in PR 38782- Candidate - 1 by @NafeelaNazhir in https://github.com/dotnet/maui/pull/38843
-
[Inflight/Candidate][Android] Fix for Android page disconnection during Loaded root replacement by @BagavathiPerumal in https://github.com/dotnet/maui/pull/39279
-
[inflight/candidate] [Android][Windows] Fix blank page after restoring Window.Page by @kubaflo in https://github.com/dotnet/maui/pull/39381
-
[Testing] Fixed Test case failure in PR 38782- Candidate - 2 by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39361
-
[iOS] Reconstruct MAUI view peers from native handles by @jfversluis in https://github.com/dotnet/maui/pull/39422
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39482
-
September 22nd, Candidate — .NET 10 SR12 (10.0.120) by @kubaflo in https://github.com/dotnet/maui/pull/38782
-
Add 10.0.120 to bug report version dropdowns by @kubaflo in https://github.com/dotnet/maui/pull/39494
-
Update PatchVersion from 120 to 130 by @kubaflo in https://github.com/dotnet/maui/pull/38778
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39489
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39508
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39520
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39547
-
Add iPhone Duo support to Controls.Foldable by @jfversluis in https://github.com/dotnet/maui/pull/38915
-
[net11][Android] Temporarily revert native edge-to-edge by @kubaflo in https://github.com/dotnet/maui/pull/39579
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39578
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39587
-
Fix duplicate-detector MCP gateway startup by @kubaflo in https://github.com/dotnet/maui/pull/39589
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39592
-
Add /review expert-review GitHub workflow by @kubaflo in https://github.com/dotnet/maui/pull/39325
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39594
-
[net11] Fix Android screenshot cropping using reported status bar height by @Ahamed-Ali in https://github.com/dotnet/maui/pull/39545
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39613
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39636
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39653
-
[Testing] Launch UI fixtures directly instead of navigating through the gallery by @kubaflo in https://github.com/dotnet/maui/pull/39621
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39686
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39687
-
[Revert] [Testing] Launch UI fixtures directly instead of navigating through the gallery by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39723
-
[net11] [Revert] [Testing] Launch UI fixtures directly instead of navigating through the gallery by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39724
-
[iOS] Replace managed KVO observers with a Swift-owned observation to fix a crash in -[UIView dealloc] on iOS 17 by @albyrock87 in https://github.com/dotnet/maui/pull/38662
-
Address contextual PoliCheck findings by @dalexsoto in https://github.com/dotnet/maui/pull/39532
🔧 Fixes -
[inflight/current] Add iPhone Duo support to Controls.Foldable by @kubaflo in https://github.com/dotnet/maui/pull/39596
-
Avoid redundant boxing in coerceValue lambdas for value-type by @pictos in https://github.com/dotnet/maui/pull/39576
-
[Android] SafeArea: let empty insets reach tracked views so SoftInput padding resets by @kevin68 in https://github.com/dotnet/maui/pull/39672
-
[Revert][inflight/Candidate][Testing] Launch UI fixtures directly instead of navigating through the gallery by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39730
-
[Testing] Fixed Test case failure in PR 39597- Candidate - 1 by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39664
-
Use GPT-6.1 Sol for test failure reviews by @PureWeen in https://github.com/dotnet/maui/pull/39738
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39734
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39744
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39754
-
[Net11][Windows]Restore WrapperView preservation during Windows handler reconnect by @SuthiYuvaraj in https://github.com/dotnet/maui/pull/39756
-
[net11] Fix test failures on .NET 11 by @Ahamed-Ali in https://github.com/dotnet/maui/pull/39673
-
October 23rd, Candidate — .NET 10 SR13 (10.0.130) by @kubaflo in https://github.com/dotnet/maui/pull/39597
-
Add 10.0.130 to bug report version dropdowns by @kubaflo in https://github.com/dotnet/maui/pull/39769
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39768
-
[automated] Merge branch 'main' => 'net11.0' by @github-actions[bot] in https://github.com/dotnet/maui/pull/39781
-
[net11.0] Promote .NET 11 to main for SR1 by @kubaflo in https://github.com/dotnet/maui/pull/39688
-
[Revert] Bump Magick.NET-Q8-AnyCPU from 14.15.0 to 15.0.0 (#39810) by @NafeelaNazhir in https://github.com/dotnet/maui/pull/39846
-
Only treat On as a RelayCommand method prefix when CommunityToolkit strips it by @MykhailoDav in https://github.com/dotnet/maui/pull/39840
-
[main] Backport release/11.0.1xx test fixes by @kubaflo in https://github.com/dotnet/maui/pull/39853
-
Remove obsolete IL6001 warning suppression by @rmarinho in https://github.com/dotnet/maui/pull/39987
-
[release] Automate versioned cuts, SR stabilization, and next lanes by @kubaflo in https://github.com/dotnet/maui/pull/39913
-
[release] Clarify PR routing and repair release preparation by @kubaflo in https://github.com/dotnet/maui/pull/40049
-
[release] Ignore abandoned candidate integrations after reset by @kubaflo in https://github.com/dotnet/maui/pull/40059
-
[Release candidate] 11.0.1xx SR1 by @kubaflo in https://github.com/dotnet/maui/pull/40070
-
[release] Make SR1 identical to main without rewriting history by @kubaflo in https://github.com/dotnet/maui/pull/40106
-
[release] Make SR1 identical to reviewed release staging by @kubaflo in https://github.com/dotnet/maui/pull/40119
-
[Release candidate] 11.0.1xx SR1 by @kubaflo in https://github.com/dotnet/maui/pull/40040
Full Changelog: 11.0.0...release/11.0.1xx-sr1
Pennsylvania, USA

PRISM: a Couchbase reference architecture for governed document intelligence
The question that breaks RAG
Ask a retrieval-augmented generation (RAG) system a lookup question about a document and it usually does well. Analytical questions are where the cracks show first. Ask one over a stack of 200- to 500-page SEC filings and things fall apart. Consider a simple-sounding question:
“What was 3M’s quick ratio at the end of the third quarter of 2022?”
(The quick ratio is a liquidity measure of how well current assets cover short-term obligations.)
The textbook pipeline is familiar: chunk the PDFs, create embeddings, build a vector index, pull the top 10 chunks, and let an LLM answer. For this question, that pipeline fails three separate ways.

- Scope failure. Which company? Which filing? Which period? Unless the system resolves the right 10-Q before it searches, the top 10 chunks can come from the wrong filing, quarter, or company. Similarity search will happily return a convincing answer from a document you never asked about.
- Evidence failure. The phrase “quick ratio” does not appear in the filing. A filing prints line items such as total current assets, inventories, and total current liabilities. The question has to be translated into the printed terms before retrieval can find them, and a purely semantic search is poor at matching exact printed labels.
- Interpretation failure. Even with the right numbers in hand, there is more than one defensible formula for a quick ratio. Some conventions subtract inventory from current assets, others build the numerator from cash, receivables and securities. Depending on the convention, the same balance sheet can land on either side of a “healthy” threshold. Somebody with authority has to decide which definition counts.
Vector-only RAG is not enough for analytical questions. Answering them reliably takes four things: scope resolution, hybrid search, deterministic calculation, and governed learning. PRISM is a reference architecture that puts those four things together on Couchbase.
They are not the only areas the architecture helps. Resolving the right document, matching the labels a filing actually prints, and tying every figure to its row, column, and page make a plain lookup answer more trustworthy too. The extra machinery, including approved formulas, deterministic calculation, and review of ambiguity, only comes into play when a question needs a number computed or a judgment made.
The core idea: divide the work by who is good at what
The most important design decision in PRISM is about responsibility, not technology. Each participant does only what it can be trusted to do
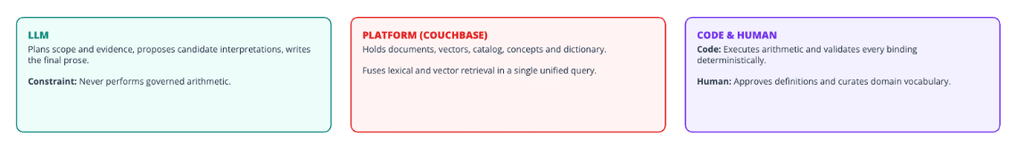
- The LLM plans the scope and the evidence, proposes candidate interpretations, binds figures to the places they were found, and writes the final prose. It never performs governed arithmetic.
- The platform (Couchbase) holds the documents, vectors, catalog, vocabulary, and approved definitions in one place, and fuses lexical and vector retrieval in a single query.
- Code and humans close the loop. Code executes the arithmetic and validates every number deterministically. Humans approve definitions and curate the vocabulary.
The consequence is simple: language models are excellent at reading and writing, but are unreliable calculators. So PRISM lets the model read and write, and makes sure the numbers can be verified.
Five artifacts
PRISM organizes everything it knows into five artifacts, in two groups.

Data artifacts describe the corpus:
- Catalog: Which document? One record per source document: company, form type, fiscal period, and source filename.
- Docs: What does it say? The chunks themselves, with tables, embeddings, and page-level provenance.
Knowledge artifacts describe the domain:
- Skills: How are these documents built? Industry-wide domain conventions, such as how filings are structured. They ship with the system and are written by domain experts, with no code involved.
- Concepts: What do people call it? Your users’ vocabulary mapped to the terms printed in the documents. They are specific to a corpus.
- Dictionary: What does it mean? Approved formulas and thresholds. Humans approve every entry, and the dictionary starts empty.
The fact that the dictionary starts empty matters. PRISM does not need to be taught the domain before it is useful. When asked about a concept nobody has defined, it can still bind figures and compute candidate interpretations, labeled as candidates. When those candidates disagree in a way that changes the conclusion, PRISM declines to give a verdict and surfaces the ambiguity instead. A human then approves one convention, making the answer deterministic. The system learns through governed corrections instead of silently guessing.
Why a catalog? Why not just put the metadata on every chunk?
Good question. Each chunk could simply carry its company, form type, and period. Here are some reasons to keep a separate record per document:
- Resolving the document is a lookup, not a similarity search. Finding “3M, 10-Q, Q3 2022” means having to choose among a few hundred small records. A catalog answers that exactly and cheaply. Once the document is known, retrieval becomes a precise filter on one filename instead of a hope that the right chunks float to the top.
- The facts are not on most pages. A filing prints its company, form, and period on the cover page. A middle chunk from a balance sheet has none of that. Stamping it onto every chunk means repeating the same facts thousands of times, and each copy has the potential to drift or be extracted inconsistently.
- One source of truth. If a period or filename needs to be corrected, you simply edit one catalog record. With metadata on chunks, you would have to rewrite thousands of chunks and refresh the index entries behind them.
- Ambiguity becomes visible. With a catalog, the planner can see which filings exist. If a question could mean two filings, the system can ask or say so, instead of quietly retrieving from the wrong one.
- Chunks stay lean. Chunks carry only what is true at the chunk level: page, row and column, and document ID. A smaller payload on every chunk keeps the vector index leaner and the documents simpler.
In short, the catalog answers “which document?” before any chunks are retrieved. The chunks then only need to answer “what does it say?”
From PDF to searchable evidence
PRISM starts with the filings as PDFs stored in Amazon S3. It deliberately does not parse or chunk them itself. That work belongs to a Couchbase AI Data Plane workflow, which reads the PDFs from S3, parses text, tables, and page metadata, splits them into chunks, and generates dense vector embeddings with a deployed embedding model. It also keeps provenance, including page numbers, row and column coordinates and document IDs. The results land in Couchbase Capella. At query time, the same embedding model embeds user queries, so documents and questions live in the same vector space.

A separate, lightweight pass reads each document’s first pages to build its catalog record: company, form, fiscal period, and filename. It needs no layout analysis, so it is fast. Finally, a hybrid search index is created over the chunks, combining BM25 lexical search with kNN vector search, with structured metadata filters alongside.

Hybrid retrieval in one query
This is where Couchbase does the most work. Analytical questions need two different kinds of search at the same time:
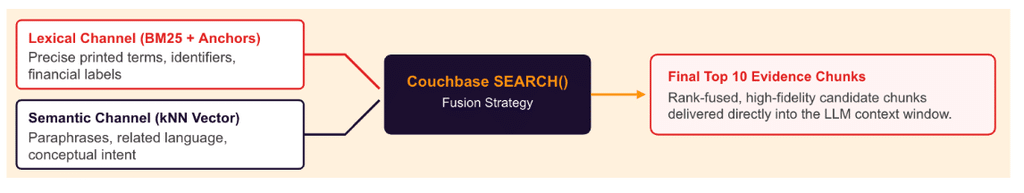
- The lexical channel (BM25 plus anchors) catches precise printed terms, identifiers, and financial labels. “Total current liabilities” must match “Total current liabilities”, not a nearby paraphrase.
- The semantic channel (kNN vector) catches paraphrases, related language, and conceptual intent, such as a user’s own words for a metric.
Couchbase 8.5 (coming soon) runs both channels in one SEARCH() call and fuses their results on the server, so the application does not have to stitch two result lists together. The fused list becomes the final top 10 evidence chunks that reach the LLM.
How the two lists are combined is a query-time choice, and there are several strategies:
| Strategy | Formula / process | Key benefit | Limitation / implementation |
| Additive Fusion | Weighted lexical score plus weighted vector score | Simple and highly backward-compatible | Raw score scales are often not comparable |
| Native RRF (Reciprocal Rank Fusion) | Sum of weight / (rank constant + rank) | Ignores scale mismatches and rewards agreement between channels | Server-side, in a single Couchbase SEARCH() |
| Native RSF (Relative Score Fusion) | Min-max normalize each channel, then combine weighted scores | Preserves relative local score magnitude | Sensitive to outliers; native SEARCH() execution |
| Application RRF | Retrieve the lists separately and merge ranks in PRISM | Exposes all sub-chan | Adds application logic and an extra network trip |
Two knobs shape the result. Channel weights (the top-level query boost and the kNN boost) control how much lexical versus semantic evidence matters. The candidate window controls how many results from each channel take part in fusion.
The takeaway is that fusion is a query-time decision. It is not another index to build or another ingestion pipeline to run. You can change strategy, weights, and window without re-ingesting a single document.
The governed flow, end to end
Here is how the pieces work together when a user asks the quick-ratio question.

Resolve and plan. The user’s prompt goes to the LLM together with the skills. The model works out which document type, year, and period are needed, and what to search for: subject words, the printed line items, and the candidate formulas. The catalog then turns that information into an exact filename. That is scope resolved.
Retrieve. The application enriches the search keywords using concepts, so the user’s vocabulary maps to the terms the filing prints. Couchbase then runs the hybrid query, scoped to the resolved document, and returns the top chunks.
Bind. The LLM reads the retrieved chunks and binds each figure to the specific row, column, and page it came from, with its entity, period, and units. This is the evidence trail, and every binding can be checked.
Validate. Now the dictionary comes in. If a human has approved a formula for this concept, that formula is the one that runs, and the LLM is not allowed to substitute its own. Code evaluates it deterministically over the validated bindings. If no definition has been approved, the system computes labeled candidate interpretations in code and checks whether they agree on the conclusion. When they straddle a threshold, the system declines to issue a verdict and records the ambiguity as a reviewable proposal.
Grounded answer. Only at this point does the LLM write the response, as prose built around numbers that have already been computed and checked. It explains; it does not calculate.
The same flow handles follow-ups such as “compare this with Q2.” The new question goes through the same plan, resolve, retrieve, and validate steps, so the answer is as grounded as the first.
Governance that scales
An architecture like this only works in an enterprise if the right people can make changes the right thing without breaking everything else. PRISM separates its artifacts by who owns them, how often they change, and how far a mistake spreads.
| Artifact | Owner | Expertise needed | Change cadence | Blast radius |
| Prompt rules | App developer | The whole downstream contract: fact binding, calculation, retrieval | Rare: only when the extraction mechanism changes | Every company, every industry, every question |
| Skills | Domain expert | Filing mechanics for one industry; no code | Occasional: as filing quirks surface | Every company in one industry |
| Dictionary | End user | Trusts a specific formula for a specific metric | Frequent: incremental | One metric |
| Concepts | End user | Their own company’s or vertical’s jargon | Frequent: incremental | One term |
The pattern is that the more often something changes, the smaller its blast radius. An analyst who approves a quick-ratio definition affects one metric. A developer who rewrites a prompt rule affects everything, and that is why it changes rarely and sits with the person who understands the whole contract. Governance is distributed, and core application mechanics are decoupled from end-user customization.
Why this belongs on one platform
Every part of this architecture needs a different data structure: documents, vectors, small catalog records, vocabulary maps, and approved definitions. In PRISM, they all live in Couchbase Capella, in one bucket and scope, and are queried with one SQL++ and search surface. Hybrid search needs no second system, and the catalog lookups and chunk retrieval sit next to each other. Embeddings and ingestion come from the Couchbase AI Data Plane, so the whole path from PDF to evidence stays inside one platform.
The lesson goes beyond SEC filings. Whenever answers must be scoped, evidenced, and defensible, such as financial reports, contracts, regulatory submissions, or clinical documents, retrieval alone isn’t enough. Resolve scope first, search with both lexical and semantic signals, let code do the arithmetic, and let humans decide the definitions.
Get started with PRISM
PRISM demonstrates how Couchbase Capella and the Couchbase AI Data Plane can transform complex PDF collections into governed, defensible intelligence. Explore the resources below to see the reference architecture in action, inspect the implementation, and start building on Couchbase Capella today:
- Watch the demo: See the complete setup and live architecture walkthrough in the PRISM Demo Video.
- Explore the code: Access the open-source reference implementation on GitHub.
- Learn about AI Data Plane: Discover how the Couchbase AI Data Plane automates parsing, chunking, and vectorization.
Try Couchbase Capella: Build your own governed search and AI applications with a Couchbase Capella Free Trial.
The post Why Vector-Only RAG Fails on Analytical Questions, and a Reference Architecture That Doesn’t appeared first on Couchbase.
Pennsylvania, USA

Vonage Video API 2.36 adds quality restriction insights, built-in publish retry, iOS 27 compatibility, and a security update for embedded root certificates
Pennsylvania, USA

A new release of the Microsoft build of Go including security fixes is now available for download. For more information about this release and the changes included, see the table below:
| Microsoft Release | Upstream Tag |
|---|---|
| v1.27.4-1 | go1.27.4 release notes |
| v1.26.11-1 | go1.26.11 release notes |
The post Go 1.27.4-1 and 1.26.11-1 Microsoft builds now available appeared first on Microsoft for Go Developers.
Pennsylvania, USA
Next Page of Stories