Months after revealing its Surface Laptop Ultra, Microsoft has announced that the Nvidia RTX Spark-equipped device will launch on October 16th. Pricing starts at $2,599 for the base configuration, featuring an 18-core CPU, 24GB of RAM, and 512GB of storage.
The Surface Laptop Ultra ships with a 15-inch HDR touchscreen display with up to 2,000 nits of peak brightness, along with a larger trackpad that supports haptic feedback. It uses Nvidia's new RTX Spark chip, an Arm-based processor with up to 128GB of unified memory. Both Microsoft and Nvidia are positioning RTX Spark laptops at the very premium end of the laptop market, designed for hig …
The Dev Box's flat, 3D-printed anodized aluminum chassis doubles as a heatsink and resembles the top vents on an Xbox Series X. It's launching alongside the new Surface Laptop Ultra and runs on Nvidia's Arm-based RTX Spark platform and 128GB of unified memory. With that much memory, along with a 100-watt thermal envelope and Nvidia's Tensor cores, you …
Microsoft has created a magnetic charging solution for its Surface Laptop Ultra that uses USB-C. After scrapping its proprietary Surface Connect magnetic charging on its smaller Surface devices last year, the Surface Laptop Ultra has a charging cable that attaches magnetically to the right-side USB-C port.
It's still a proprietary solution, but the USB-C port it slots into still works for video, data, and other USB-C connectivity like you'd expect. Microsoft is calling it Magnetic Connect, and I'm surprised the company hasn't shortened that to Mag-C.
Today, one in three pull requests on GitHub involves an AI agent. A year ago, that number was fewer than one in 10. If that pace holds, within the next two years, most of the code pushed to GitHub could be written by an agent. Much of it may never be fully read by a human.
If developers and agents move faster, we have a responsibility to ensure protection keeps up with the accelerated rate of code creation. That means preventing more leaks before they happen and making the response to exposures that remain less dependent on manual human effort.
This is a pivotal point for leaked secrets. Developers aren’t becoming more careless; they’re being outpaced. The tools that let developers create more software should also take on more of the work of protecting it.
In this essay, I share the nine quarters of data behind that claim. I also introduce the fine-tuned classifier we built with Microsoft Applied Sciences to extend push protection to unstructured secrets. The model assesses a whole set of candidate secrets in less than two milliseconds and could more than double the number of secrets that we can prevent.
Outpaced, not careless
A new secret appears in publicly visible code about once every two seconds, doubling yearly for the past three years. Public discourse is quick to jump to the idea that AI made developers careless.
Between Q2 2024 and Q2 2026, screened pushes grew 2.84 times while pushes carrying credentials grew 2.59 times. Across nine complete quarters of data, we found no statistically detectable trend regarding per-push prevalence. At the same time, we found data suggesting that, more than ever, developers understand the risk of accidental exposures and are less willing to accept that risk. Over the same period, the share of push-path blocks overridden by developers fell linearly from 6.63% to 3.93%. These figures challenge the common claim that agents are causing developers to become more careless.
More pushes, no clear rise in push prevalence
Public pushes
Push prevalence
202M
574M · 2.8×
0300M600M
0%0.5%1.0%
Q2Q3Q4Q1Q2Q3Q4Q1Q2202420252026
2026 Q2 · 574M pushes · 0.47% with secrets
Public pushes, Q2 2024–Q2 2026. Push prevalence is the share with a detected secret. Covers supported provider patterns, including GitHub’s own tokens.
At a fixed rate, doubling activity doubles expected exposures. If each exposure requires the same human response, the workload doubles too. The mean time to manually revoke a secret hovers around 40 days; roughly one in five took more than 90 days. We’re accelerating the creation of software while exposed credentials can remain usable for weeks or months, because human remediation can’t scale at the same pace as development.
Telling developers to be more careful cannot, on its own, solve that problem. As the amount of code grows, we must prevent more exposures and reduce human effort required by those that remain, if software development is to remain sustainable.
Prevention scales with compute
I’ve spent the past few years working on secret scanning at GitHub and the past year as product lead for the area. Our greatest impact has come from connecting the dots between detection to systems that can act.
GitHub’s catalog covers more than 150 technical partners through our secret scanning partnership program. Through our partner program, we work with participating secret issuers to build out detectors and report public exposures so they can respond. In Q2 2026, public scanning successfully reported an average of 26 credential matches a second, including repeat observations. Once notified, a large number of these partners immediately revoke the token: OpenAI API keys, Google Cloud account credentials, Slack webhooks, Hugging Face user tokens, SendGrid keys, etc. The owner may still need to replace the token, but revocation can happen without waiting for a developer to find and process a GitHub alert.
Push protection intervenes earlier. It stops recognizable credentials before it enters repository history, giving the developer or agent a chance to correct the change before there’s an exposure to investigate. We work with our technical partners to increase precision rates of their detectors as much as possible, until we’re confident enough to push-protect these secrets for the developer community by default.
Thanks to the efforts of our partners, in the past month, a secret was blocked by push protection at least once every second. When it comes to issuer-bound credentials, GitHub blocks more secrets than those which slip. I’m proud of how ordinary we’ve made that feel for developers.
Remediation scales with people
When including additional secret types, push protection stops about 30% of newly detected secrets before they enter repository history. We find the remaining 70% after the credential is, unfortunately, already lost. And:
Prevention scales with compute, but remediation still scales with people.
Refusing a push costs compute; cleaning up a secret already lost to visible history costs a developer’s time and attention.
As the amount of code grows, we must prevent more exposures and reduce the human effort required by those that remain, or else the volume of vulnerabilities introduced will become untenable.
Telling developers to be more careful cannot solve this imbalance. Recognizing more of these secrets, earlier in development flows, is work the platform must take on.
Solving the four-body problem
Before a secret crosses the push boundary, the cost of stopping it is small, and the decision is binary: block or allow. After it crosses, the same string can authenticate to a real system, and the cost is unbounded.
In many cases, our only detection clue may be the surrounding code and world context. A provider-issued token may have a recognizable prefix. An internal database password may be completely unstructured, with no identifying pattern at all. We were already using context to find these secrets post-push; the problem was balancing that context-aware judgement with other factors.
We refer to this as the “four-body problem” for secret protection: precision, latency, throughput, and cost are coupled constraints. Prevention must be worth a developer’s time. A finding suitable for later review may not justify blocking a push. A false positive interrupts a developer and makes the next block harder to trust. A check that is too slow, expensive, or difficult to scale limits how often it can run.
Protection at the push in under 2 ms
GitHub’s AI-powered generic secret detection model uses surrounding code context to block password-like values in a database URL, Kubernetes Secret manifest, and Dockerfile, while allowing the placeholder changeme.
Our new ModernBERT classifier assess candidate secrets in context, without generating code or prose. It’s not only more precise than existing LLM-based pipelines, but it’s incredibly fast, evaluating candidate batches in under two milliseconds. It’s also extremely cost efficient, enough to run at scale in the critical path.
The inclusion of our model in push protection makes it possible for us to more than double the number of secrets that we’re able to prevent. The feature is currently in private preview. Later this month, the feature will be available to organizations with GitHub Secret Protection across Enterprise Cloud and GitHub Teams. It will consume AI credits.
We’re also bringing the model to developer surfaces beyond the push.
Starting today, anyorganization with AI secret detectionwillbeautomaticallyupdated tothe new model. Alerts opened from these post-push scans remain included with an organization’s purchase of secret scanning at no additional cost.
Themodel will also ship with GitHub Enterprise Server 3.23in public preview, bringing AI-detected alerts to Secret Protection customers even in air-gapped environments.
We’readding the classifier to the /security-review command for the Copilot CLI and Copilot App, so Copilot users can address secrets before a push even without needing an organization’s GitHub Secret Protection plan. AI credit usage will be attributed to GitHub Secret Protection in your AI usage insights.
Looking forward
The future we want is one where developers can entrust more work to agents without supervising every request, and one where the number of people that an organization needs to keep its credentials safe no longer scales with the amount of code it writes. We owe the developer community the same progress in protecting software that we are delivering in producing it.
We want people to build more software. Our capacity to protect it should grow with our capacity to create it.
The mission of Microsoft Security’s Frontier Offensive Research & Generative Exploitation (FORGE) Lab is to advance the frontier of autonomous security engineering. We’re building a team that enables AI-native vulnerability research at Microsoft, pushing the boundaries of finding and fixing zero-day vulnerabilities. Four principles guide that work: autonomy over labor, defense through offense, building ecosystems over individual examples, and understanding over findings. This post reflects those principles in practice across Windows, the Linux kernel, and widely used open-source projects.
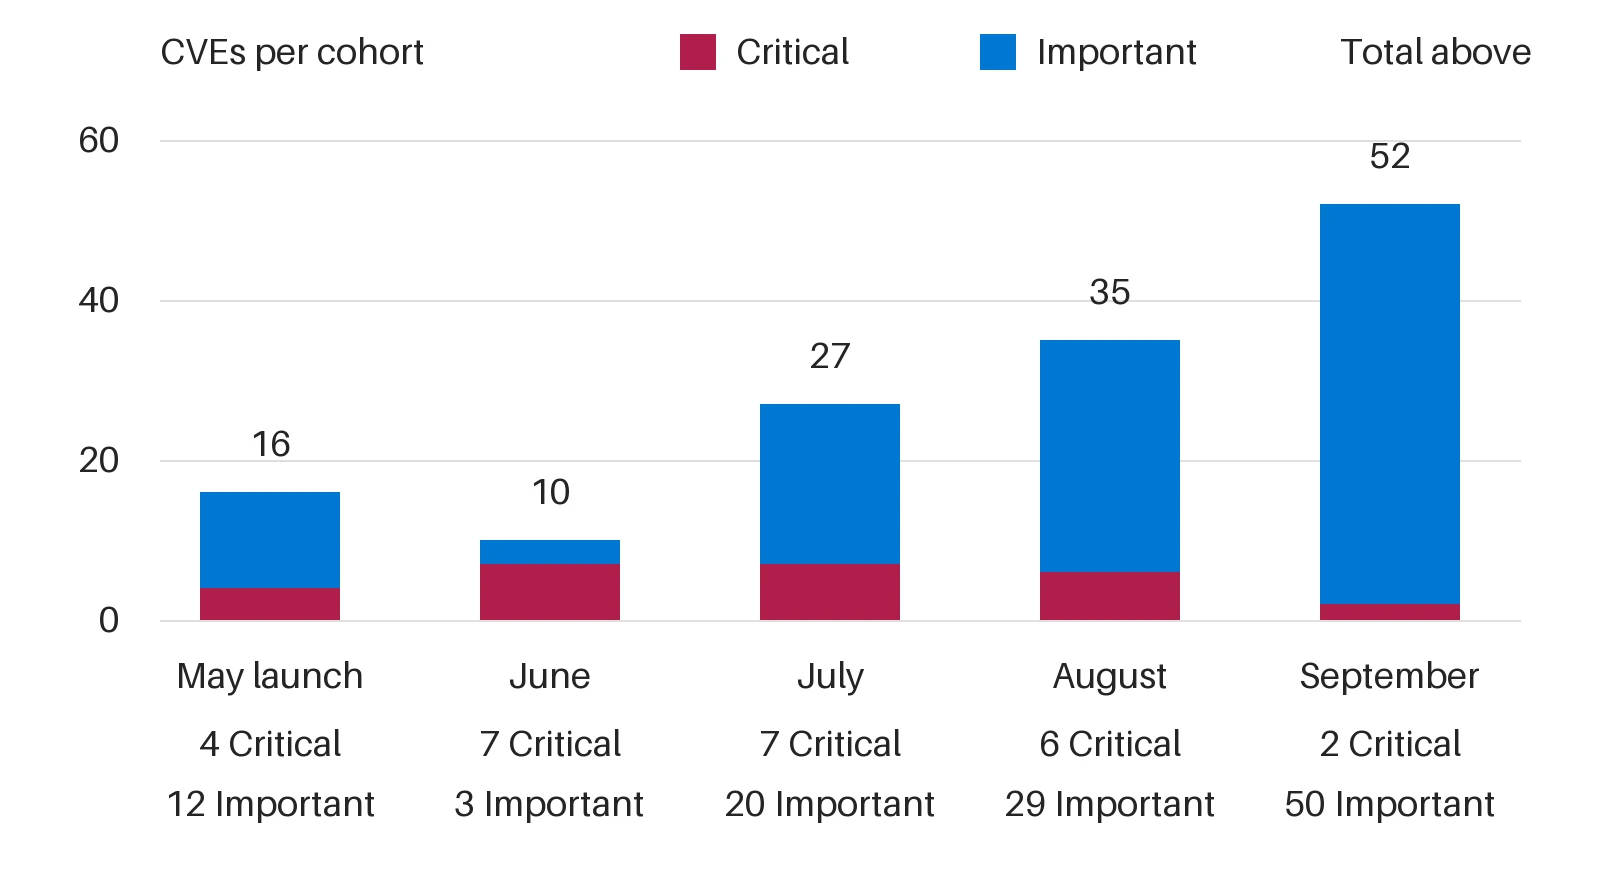
From May 2026 through September 2026, FORGE helped discover Windows vulnerabilities assigned 140 common vulnerabilities and exposures (CVEs), including 52 addressed in September 2026’s security release alone. The work reaches well beyond Windows. FORGE members submitted 155 internally validated reports across 23 open-source projects, including the Linux kernel. And through Akrites, a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software, one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel.
These results demonstrate that agentic discovery can operate at meaningful volume, but they also expose the next constraint. Finding a difficult vulnerability proves an agent’s frontier capability. Repeatedly converting such findings into security updates requires a different kind of system—one that can move credible work through validation, remediation, and release. Discovery creates security value only when validation and remediation can keep pace. For security leaders, the question is no longer only whether AI can find vulnerabilities, but whether an organization can validate and fix them as fast as they are found.
Three lessons follow, each marking a shift in how we approach vulnerability research:
From frontier capability to scale.
From token consumption to reasoning economics.
From isolated discovery to coordinated validation and remediation.
The scarce resource is not always model intelligence. It can be a working build and deployment, a reproducible trigger, or even an engineer’s time.
At FORGE Lab, we use the multi-model agentic scanning harness, codename MDASH, to organize this work. Our May 2026 introduction detailed its design, while the June 2026 update covered pipeline improvements and benchmark analysis. Here, we focus on what those experiences teach us about operating vulnerability research at scale—across Windows and open-source projects.
140 CVEs addressed through Microsoft Patch Tuesday since May 2026. Monthly totals reflect announcement and servicing cohorts, not discovery dates or scan throughput. Source: Microsoft FORGE Lab study, May 2026 to September 2026.
Shift 1. From frontier capability to scale
The frontier question is whether a system can find a bug that demands deep reasoning, as we explored in our early work on the CyberGym benchmark. The scale question is whether it can repeat that result across targets without rebuilding every environment, investigation, and review process from scratch. Better models still matter, especially for difficult or unfamiliar bug classes. But once discovery becomes repeatable, model capability is only one constraint on useful output.
Adding auditors can increase candidate volume without increasing the rate of validated findings or shipped fixes. If reports arrive faster than reviewers—in our case, Microsoft Security Response Center (MSRC)—can resolve them, the immediate result is a growing queue. A larger search budget can even reduce useful throughput when duplicate or poorly supported reports consume attention that stronger findings need.
The unit to optimize, therefore, is neither the scan nor the report. It is a reproducible finding that advances with enough evidence for the next stage to act. Reusable preparation, deduplication, and review capacity are therefore core components of the research system.
As agentic systems produce more candidates, the bottleneck shifts from discovery to determining which reports are real, reachable, and security-relevant. Project-specific automated provers—such as proof of vulnerability (PoV)/proof of concept (PoC) generators, harness builders, and trigger-input finders—turn plausible reports into reproducible evidence that engineers and maintainers can act on. By finding crashing inputs, confirming reachable execution paths, and producing regression-ready triggers within each project’s build and test environment, these tools can help reduce human triage, accelerate remediation, and make vulnerability research sustainable at scale. For example, by leveraging deterministic algorithms such as abstract syntax tree (AST), one of our internal projects reduced about 45% duplicate findings across multiple scans of the same code which reduced the load on the PoC generator and subsequently human triage effort.
More candidates do not create more throughput when the review queue grows faster than fixes ship.
Shift 2. From token consumption to reasoning economics
At scale, every repeated orientation, speculative branch, and redundant debate carries a cost. But minimizing tokens alone is the wrong objective. A short, ambiguous report may be cheap to generate yet expensive to investigate; a longer analysis that establishes the missing execution path may reduce total system cost.
The key question is where the next unit of reasoning will change a decision. If an index can identify callers, asking a frontier model to rediscover them wastes capacity. If the uncertainty is whether two lifetime conditions can coexist across callbacks, deeper reasoning may be warranted. If the question is whether an input triggers the failure, an executable check can provide evidence that more prose cannot.
MDASH combines frontier and distilled models, specialized auditors, and code-analysis tools, enabling work to be allocated by task. That flexibility does not guarantee optimal allocation. Routing routine work to cheaper models, reusing verified context, and escalating unresolved questions to stronger reasoning are hypotheses to test—not efficiency gains to assume.
A useful allocation policy starts by identifying what remains unknown: a caller, a build configuration, a reproducer, or a causal explanation. The next action should close that specific evidence gap. Repeating a review without adding evidence spends more tokens while preserving the same uncertainty. Early filtering can also discard real bugs, so any savings must be measured against coverage and missed findings.
Scan outcomes can also become training data. At scale, vulnerability scanning should become a training loop, not only a discovery pipeline. Each MDASH run produces signals that can improve future models: true-positive and false-positive verdicts, duplicate findings, failed reachability claims, reviewer feedback, verifier results, severity assessments, patch outcomes, and regression-test evidence. Capturing those signals with the code context and causal argument behind each candidate creates the dataset needed for reinforcement learning and fine-tuning specialized cyber models. The goal is for future models to learn not just what a vulnerability looks like, but which findings survive validation, which explanations help humans and provers act, and which patterns lead to useful remediation.
Spend reasoning to remove uncertainty, not simply to produce more analysis.
Shift 3. Validation and remediation as a continuous learning loop
Validation and remediation are not downstream cleanup; they are part of the discovery loop. Each candidate should move through automated verification, human review, patch development, and regression testing, with every stage returning evidence to the system. A reproducible trigger strengthens the report, guides the fix, and can seed a regression test. A failed validation is also useful when it records why: an unreachable path, missing precondition, incorrect build configuration, insufficient attacker control, duplicate report, or incomplete causal explanation.
That evidence is how the system improves. Project-specific provers, harnesses, and trigger generators accumulate operational knowledge about how each target builds, runs, fails, and accepts fixes. Remediation outcomes show the discovery pipeline which evidence changed a decision, which assumptions failed, and which bug patterns warrant more or less attention. The objective is to make every investigation leave reusable capacity behind: a validated trigger, clearer invariant, better harness, stronger regression test, or routing rule that prevents the same mistake.
Human attention remains essential, but it should concentrate where judgment has the highest leverage: assessing security impact, reviewing patches, and determining whether a change restores the component’s intended invariant. Automation can handle the repeatable work of establishing reachability, reproducing behavior, and preserving evidence. Over time, this loop converts individual findings into system knowledge—raising the quality of future discovery while shortening the path from credible report to shipped fix.
A reproducible defect is not yet a serviced fix. To shorten the path from discovery to remediation, MDASH needs to operate as part of the engineering loop: continuously scanning code, connecting findings to the builds and artifacts produced by continuous integration and continuous delivery (CI/CD), and feeding validation results back into development, as described in the Windows team’s blog post. Broad analysis can identify suspicious code paths, but component-specific proving needs the right binaries, symbols, configurations, harnesses, and runtime conditions to reproduce a candidate defect against the version that matters for customers and releases. Each handoff should be both owned and machine-usable: research supplies the candidate claim, causal path, and uncertainty; proving supplies execution evidence from the relevant build artifact; component teams assess the violated invariant, repair strategy, compatibility risk, and related variants; and servicing connects the approved change to release validation. A failed reproduction, rejected finding, incomplete patch, or regression result should feed back into MDASH as structured evidence, not simply move a ticket into another queue. The goal is not to remove human code review or release validation, but to automate the repeatable work around them—finding candidates, selecting artifacts, reproducing behavior, preserving evidence, suggesting related paths, and returning what was learned to the next scan.
The goal is to build an organization-wide system that automates repeatable work while preserving clear engineering accountability.
Transferring security research to help open source projects
In open source, all three constraints apply at once. Each project has its own setup costs, mix of analysis and execution work, and maintainer workflows and review capacity. Within Windows, vulnerability research connects to established component owners and servicing infrastructure. Across open-source projects, reusable methods can reduce repeated setup, but they cannot replace the technical and human context required to move a finding toward a fix.
Open-source vulnerability reporting snapshot
Over three months, FORGE members audited open-source projects spanning kernels, runtimes, networking libraries, container technologies, and media parsers. The team submitted 155 internally validated reports across 23 projects. At the time of writing, 93 reports across 14 projects or project families had documented maintainer acknowledgement or acceptance: apple/container, apple/containerization, curl, Escargot, FFmpeg, Hyperlight, Linux, llama.cpp, Node.js, PyRIT, Rust, SQLite, vLLM, etc.
Since the reports are at different stages of that process, only subsets are publicly disclosed today, such as curl’s CVE-2026-9545 and CVE-2026-13608, Node.js’s CVE-2026-56848, and Linux kernel CVE-2026-64563. Our public CVE index lists the CVEs currently cleared for disclosure, and you can find all our public channel Linux kernel reports through lore.kernel.org query.
Measured costs of automated validation
MDASH surfaced thousands of suspicious locations in the Linux kernel, and our validation agents produced supporting evidences for 627 findings. The figures below summarize automated validation costs for a subset of these efforts. Across 182 confirmed crash findings, generating a PoC averaged $3.61 in model cost and 21.5 minutes. For six selected cases, using automatic exploit generation (AEG) to test local privilege-escalation potential averaged $8.56 and 25.4 minutes.
Average model and time cost for Linux kernel automated validation. Per-case averages reflect all attempts for successful cases using GPT-5.5. Source: Microsoft FORGE Lab Linux kernel automated validation study, 2026.
These evaluations used GPT-5.5, without extensive task-specific tuning of either the model or the harness. These averages include all attempts associated with the successful cases shown, but exclude initial screening, candidates that failed or were filtered out, and human investigation and patch preparation. Within those limits, the results still strongly indicate that automated validation can produce useful results at practical cost and latency, even at Linux-kernel scale. Tighter co-design of models and agent harnesses could improve both validation yield and efficiency. If costs fell by another order of magnitude, for example, 10x or even 50x, the range of findings that could be economically validated would expand substantially, further reshaping vulnerability research.
FORGE OSS Bug Hunt Party: Human coordination at scale (Hackathon)
Looking back to those efforts, technical evidence was only part of the job. Getting it fixed also required understanding and respecting each project’s context and workflow: some required a patch while others did not; some preferred private disclosure while others used public channels; and maintainers sometimes differed on whether an issue crossed a security boundary. In practice, this meant adapting to each project’s submission requirements, working with maintainers to reproduce the issue, and, where applicable, refining and retesting a proposed fix. As AI-assisted discovery increases report volume, open-source security research can scale only if research teams absorb the resulting complexity rather than pass it on to maintainers.
Scaling this work also requires more developers who understand the full security workflow. At Microsoft’s annual Hackathon, we hosted the FORGE Open Source Software (OSS) Bug Hunt Party (Project Sunshine) as a forum where developers across Microsoft could exchange security research practices and gain hands-on experience with vulnerability investigation, validation, and responsible reporting. With MDASH and supporting guidance, 50 participants produced 39 reports across six projects, including Microsoft’s open-source Hyperlight project, Linux, vLLM, Gemini CLI, and llama.cpp. Those 39 reports are included in the 155-report snapshot above. Project Sunshine has continued beyond the Hackathon as a forum for open-source security collaboration within Microsoft.
Akrites: Coordinated effort to remediate vulnerabilities
Akrites is a Linux Foundation initiative that coordinates confidential remediation and disclosure for vulnerabilities in critical open-source software. FORGE has submitted nine Linux findings with internally assessed common vulnerability scoring system (CVSS) scores above 7.0. Together with submissions from other participants, including Google, these cases helped test and refine Akrites’ early Coordinated Vulnerability Disclosure (CVD) workflow. One of those reports was the first Akrites submission to result in a patch merged into the Linux kernel. FORGE will keep contributing to those responsible disclosure efforts.
The work also showed that a systematic approach is not just a larger scan. It is a repeatable path from a finding to an upstream fix and coordinated disclosure. Each case needs reproducible evidence, a clear causal explanation, a severity assessment, and an understanding of which downstream projects may be affected. The right owners and collaborators can then be brought in at the right time and on a need-to-know basis.
What’s next for FORGE Lab?
In a matter of months, FORGE Lab has helped discover Windows vulnerabilities and assigned 140 CVEs, including 52 in September 2026’s security release. Beyond Windows, FORGE submitted 155 internally validated reports across 23 open-source projects—93 of which had documented maintainer acknowledgement or acceptance at the time of writing—and one of our Linux reports became the first Akrites submission to result in a patch merged into the Linux kernel. Our Linux kernel results also indicate that automated validation can work at practical cost, with proofs of concept averaging $3.61 in model cost and 21.5 minutes per successful case. The lesson behind those numbers: once agents can find difficult bugs, progress depends on the system around them, how it scales, where it spends reasoning, and how quickly it turns discoveries into validated fixes.
These three lessons are becoming foundational guidelines for FORGE’s next phase of research:
Moving from frontier capability to scale means measuring the full pipeline, not just the number of findings: candidate arrivals, duplicates, rejected reports, validated defects, queue age, unresolved cases, and time through each stage.
Moving from token consumption to reasoning economics means evaluating model and execution cost alongside human review time, and asking whether each additional pass removes uncertainty, improves coverage, or produces independently validated findings.
Moving from isolated discovery to continuous validation and remediation means tracking reproduction success, patch rework, regression evidence, and elapsed time from validated defect to approved fix and release.
For security leaders evaluating AI-powered vulnerability discovery, these are useful measures too: count validated fixes, not just findings, and weigh model cost alongside the human review time it takes to act on them.
The next advance won’t come from a better model alone. It will come from research systems that combine frontier capability, systems engineering, and reasoning economics, focusing machine reasoning and human attention on turning credible findings into validated fixes.
To learn more about Microsoft Security solutions, visit our website. Bookmark the Security blog to keep up with our expert coverage on security matters. Also, follow us on LinkedIn (Microsoft Security) and X (@MSFTSecurity) for the latest news and updates on cybersecurity.
Harnessed Agentic RL: Microsoft Research Asia introduces a training paradigm in which the same agent harness used in deployment participates directly in reinforcement learning, removing the need to reimplement the agent inside the training framework.
Lightweight by design: Agent Lightning v1.0 delivers a complete agent RL control plane in roughly 3,500 lines of code.
Native Kubernetes support: agents run as standard Kubernetes jobs on self-managed clusters, cloud Kubernetes, or local infrastructure, with no dependency on paid commercial sandbox services.
Data-efficient training recipe: an end-to-end coding agent pipeline raised Qwen3.5-9B from 41.8% to 56.4% Pass@1 on SWE-bench Verified, a 14.6 percentage point gain, using only about 6,000 training samples based on open sourced dataset.
AI agents have evolved from single models to complex full-stack systems built from models, tools, and execution environments. Their capabilities increasingly depend on the agent harness that coordinates them from outside the model. Reinforcement learning (RL) is an approach where AI systems learn through trial and error, guided by rewards and penalties for their actions. RL can make those agents better, but most agent RL systems require developers to reimplement the agent inside the training framework. That is costly, and it means the agent being trained is not quite the agent that gets deployed.
To address this, researchers at Microsoft Research Asia have introduced the Harnessed Agentic RL training paradigm and open-sourced a fully rebuilt Agent Lightning v1.0 (opens in new tab). Compared with the original, Agent Lightning, v1.0 puts more emphasis on staying lightweight, on integrating with real harnesses, and on a complete, reproducible agent RL training pipeline.
Agent Lightning v1.0 was rebuilt around Harnessed Agentic RL, with key improvements:
Lightweight: the entire framework is about 3,500 lines of code. Agent Lightning v1.0 implements a complete Harnessed Agentic RL system in a codebase that is small and clear enough to understand, modify, and extend.
Training on a real agent harness: agents reach the model through the large language model (LLM) proxy in Agent Lightning v1.0, leaving existing harness code unchanged.
Native Kubernetes support: agents run directly as Kubernetes jobs, without external commercial sandbox services. Self-managed clusters and local infrastructure alike can support rollouts at scale.
A complete coding agent training example: an end-to-end pipeline built on Qwen3.5-9B raised Pass@1 on SWE-bench Verified from 41.8% to 56.4%, an absolute gain of 14.6 percentage points, using only about 6,000 training samples.
The limits of traditional agentic RL
Traditional agentic RL assumes the training framework owns the interaction loop with the environment. In a ReAct-style loop, the model generates an action, the environment returns an observation, the observation is appended to the context, and the model generates the next action, so the whole rollout maps onto one continuous token trajectory. Early RL systems such as verl, AReaL, and slime were built this way, which meant training an agent required rebuilding its loop inside the RL framework.
Real harnesses have outgrown that assumption. Coding agents such as mini-SWE-agent, OpenHands, OpenCode, Claude Code, and Codex each bring their own context management, tool protocols, execution logic, and dependencies, as do general-purpose agent systems. Rebuilding one for training is expensive, and the rebuilt agent may no longer behave in the same way as the deployed agent.
Agent Lightning takes a different route. It places an LLM proxy between the agent and the model. The agent continues to run as before: simply point the endpoint that previously called the model API at Agent Lightning, and the training framework can observe and record its model calls. In v1.0, the researchers go further and formally define this paradigm as Harnessed Agentic RL: whichever agent harness is used in deployment is the harness that takes part directly in reinforcement learning during training (Figure 1).
Figure 1. Traditional agentic RL compared with Harnessed Agentic RL. In traditional agentic RL, the training framework manages the environment and the agent loop. In Harnessed Agentic RL, the harness manages both.
Four challenges in training with real harnesses
A core difference between Harnessed Agentic RL and traditional agentic RL is that the environment interaction loop is handled by the agent harness rather than the training framework. The training system can only observe a series of LLM request and response pairs, so a single rollout may be split into a variable number of training samples. This brings four key challenges:
Retokenization and sample merging: Harnesses keep context as text, but RL training needs the token IDs sampled during the rollout. Passing text through the chat template and tokenizer again can shift token boundaries, so adjacent calls cannot always be merged into one sample.
Advantage calculation: Retokenization, subagents and context summarization can split one rollout into several samples. Computing baselines and advantages directly at the sample level causes rollouts that produce more samples to be counted repeatedly, which alters the original statistical relationships at the rollout level.
Loss normalization: Averaging loss by sample count gives more weight to rollouts that produce more samples. Since sample count is often just a product of harness behavior, loss normalization must also avoid being distorted by it.
Training backend scheduling: Sample count and length are known only after the harness finishes, while GPU counts and data/tensor parallel configurations are usually fixed. The backend has to map a variable workload into fixed resources.
PODCAST SERIES
The Shape of Things to Come
Join Microsoft’s Doug Burger and guests as they dig into the fundamental truths about AI and how it will reshape the future.
Building a complete agent RL control plane in 3,500 lines of code
In system design, Agent Lightning v1.0 treats simplicity as its first principle. The entire framework is about 3,500 lines of code, with three core components: the API Gateway, the Rollout Controller, and the Customized Trainer (Figure 2).
The API gateway stores rollouts, models, and events, and serves as an OpenAI-compatible LLM proxy. It links every model call from the harness to its rollout and records the prompts, responses, and log probabilities that training needs. The rollout controller starts and manages agent execution, either as local processes or as standard Kubernetes jobs, keeping agent execution separate from the trainer. The customized trainer, built on verl, creates rollouts, waits for them to finish, collects samples, and assembles the final training samples through a sample adapter. As a result, for an existing agent harness, simply pointing the model endpoint at the Agent Lightning proxy is usually enough to connect quickly to RL training.
Figure 2. The Agent Lightning v1.0 system architecture showing the API gateway, rollout controller, and customized trainer.
Collocated async RL
Rollout times vary widely across agents. Synchronous RL waits for the slowest agent in a batch and leaves GPUs idle, while fully asynchronous RL raises utilization but needs separate GPU pools for rollout and training. In response, Agent Lightning v1.0 introduces Collocated Async RL, which lets rollout and model updates share the same set of GPUs.
Once the system has collected enough rollouts, the update begins: the API Gateway pauses accepting new requests and waits for requests already in progress to finish, and rollout resumes after the update completes. The entire state transition is transparent to the external agent harness. In experiments, this approach achieved about a 2x end-to-end speedup over synchronous RL while using fewer GPUs than conventional asynchronous RL (Figure 3).
Figure 3. Synchronous RL, asynchronous RL, and Collocated Async RL compared. Collocated Async RL raises utilization while occupying fewer GPUs.
Running agents on Kubernetes
Collecting enough rollouts means running many agents at once, which consumes substantial CPU, memory, and compute resources. Other Harnessed Agentic RL frameworks often host those agents on commercial sandbox services such as Modal Sandbox or E2B, where cost climbs quickly with scale. Instead, Agent Lightning v1.0 runs them as standard Kubernetes jobs, reusing existing self-managed clusters, cloud Kubernetes, or local infrastructure (Figure 4). Existing compute resources are used more efficiently, large rollouts cost less, and the whole pipeline stays open source and reproducible.
Figure 4. The Rollout Controller in Agent Lightning v1.0 provides native Kubernetes support, running agents directly as standard Kubernetes jobs.
6,000 training samples, a 14.6-point performance gain
To test the approach, researchers built a full pipeline on SWE-smith, mini-SWE-agent, and Qwen3.5-9B, covering data cleaning, environment construction, reward-hacking safeguards, and RL training. The training set holds about 6,000 samples and needs no large-scale compute. RL training alone raised Qwen3.5-9B from 41.8% to 56.4% on SWE-bench Verified, a gain of 14.6 percentage points.
The coding agent experiments further confirm the earlier analysis of two challenges: advantage calculation and loss normalization. Compared with sample-level handling, rollout-level advantage combined with rollout-level normalization achieves a higher validation reward and keeps policy entropy more stable during training (Figure 5).
Figure 5. Pass rate and policy entropy for Qwen3.5-9B on the SWE-smith validation set.
 Log in