Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
161526 stories
·
33 followers

SQL is the worst DSL, except for all the other ones

1 Share

Share Episode         
         
From your feedback, we know that on-call issues, especially those that arise at the database layer are always the most challenging to solve. This episode builds on our Grafana Observability episode as we go deeper into the challenge of data ownership in data lakes. Apache Druid creator, previous Yahoo Distinguished Engineer, Fellow at Splunk, and currently the Chief Architect as Imply, Eric Tschetter joins us to confirm that there are unsolved problems in data platforms, and it doesn't get better when we throw agents into the mix.


In the true DevOps mindset aligment, Eric reminds us that whoever is operating the system, knows what is going on, they know their service boundaries, and so it's their choice to make. And the sad reality is that at large enough companies, you will always have independent teams making independent decisions, it's never possible to fully align them, and realistically we get down to why it is even a mistake to try.

         
💡 Notable Links:         
🎯 Picks:         


Download audio: https://dts.podtrac.com/redirect.mp3/api.spreaker.com/download/episode/75287024/download.mp3
Read the whole story
alvinashcraft
3 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Beyond the Build – September 2026

1 Share
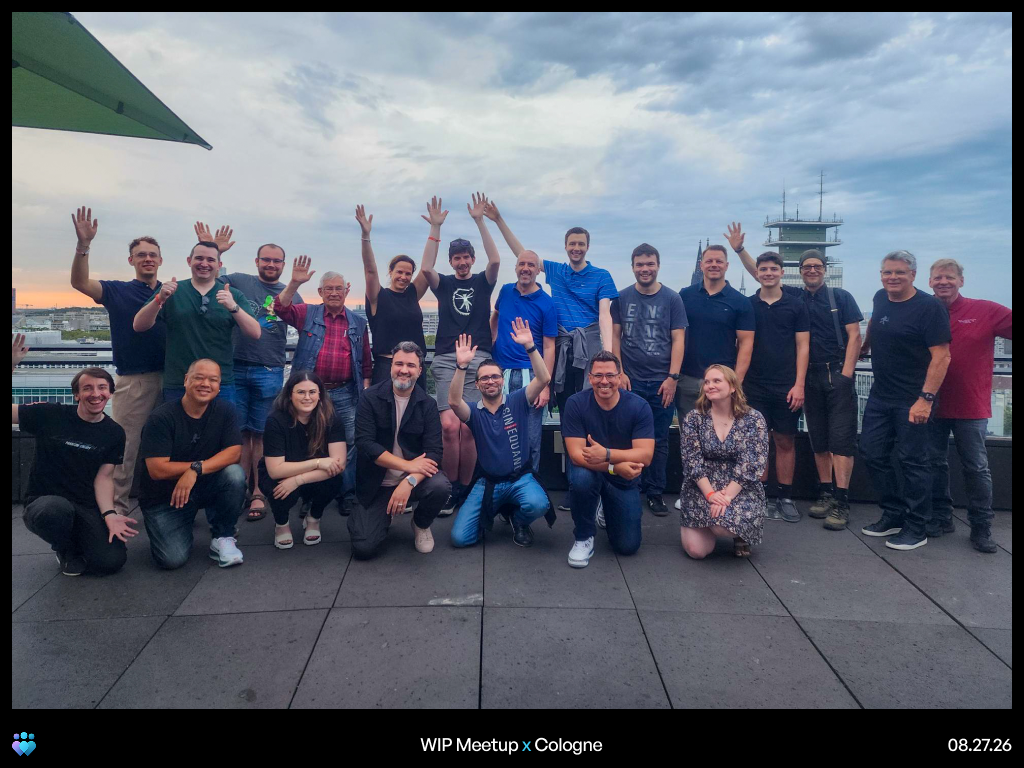
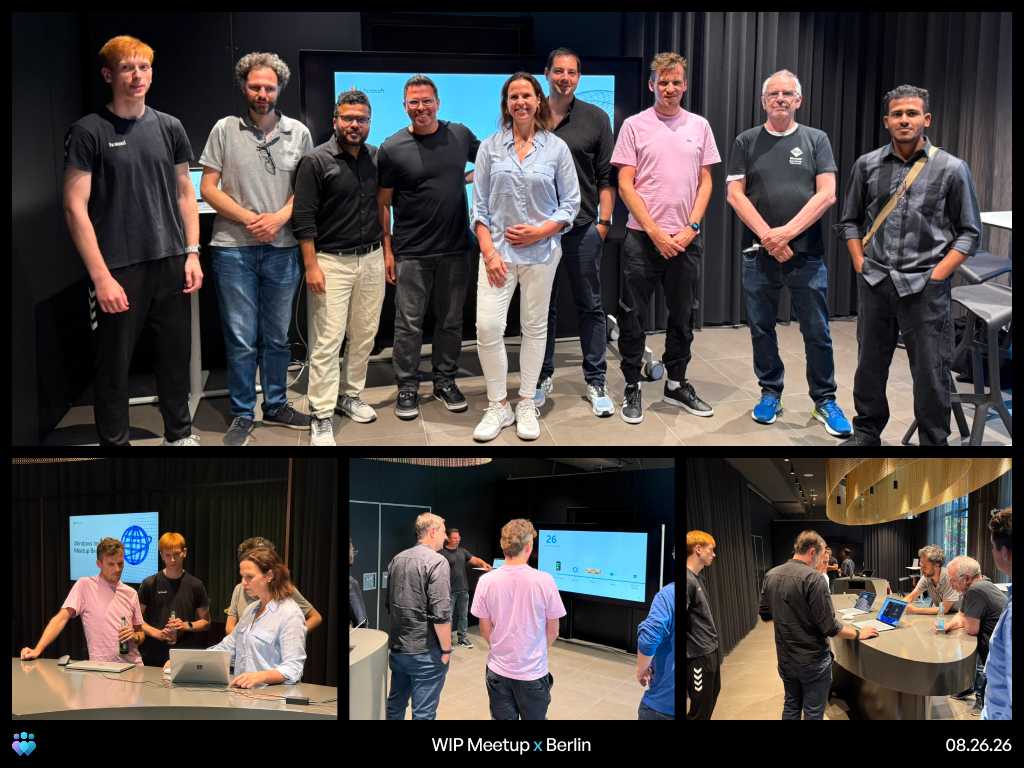
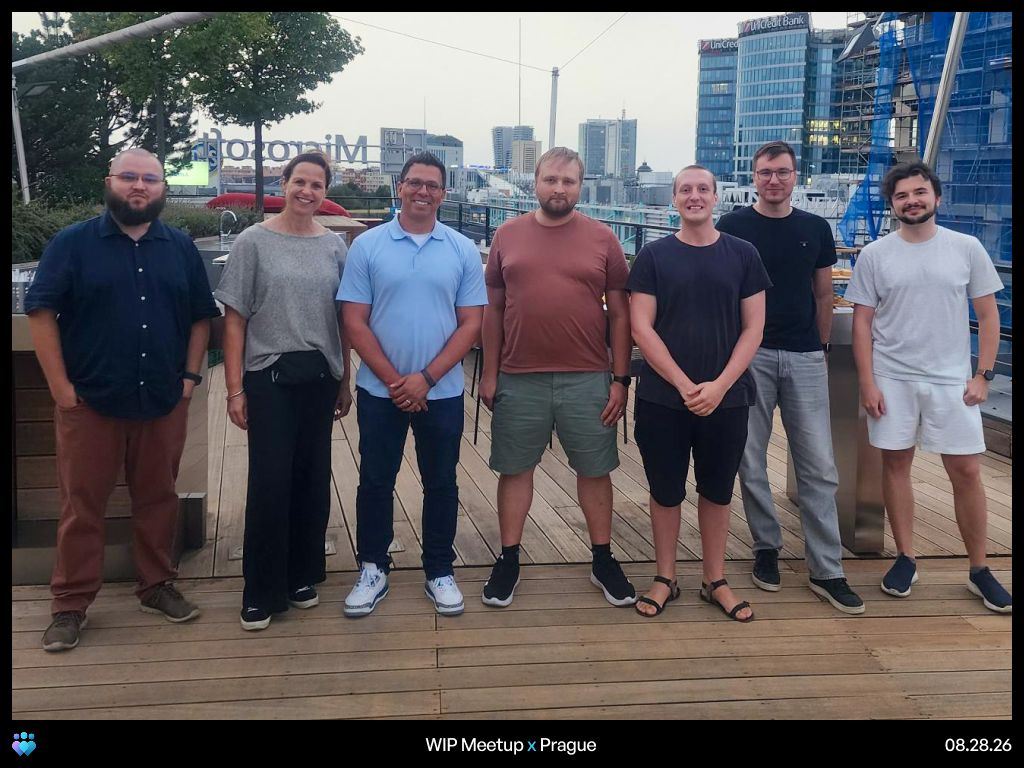
Beyond the Build is a monthly update from Marcus Ash, CVP Design and Research across Windows & Devices, on what’s happening across the Windows Insider Program. Plus, read on to see how you can register to attend our next Windows Insider event on October 15 in Brooklyn, NYC.  Earlier this month, we kicked off the next leg of our Windows Insider meetup tour with stops in Berlin, Cologne, and Prague. [caption id="attachment_179172" align="aligncenter" width="1024"]A group of Windows Insiders from the Windows Insider meetup in Cologne A group of Windows Insiders from the Windows Insider meetup in Cologne[/caption] [caption id="attachment_179173" align="aligncenter" width="1024"]A group of Windows Insiders from the Windows Insider meetup in Berlin A group of Windows Insiders from the Windows Insider meetup in Berlin[/caption] [caption id="attachment_179174" align="aligncenter" width="1024"]A group of Windows Insiders from the Windows Insider meetup in Prague A group of Windows Insiders from the Windows Insider meetup in Prague[/caption] These meetups were smaller by design. That gave us more time for direct conversations, questions, and feedback. Many of you shared that you can feel the improvements in Experimental builds, especially in overall system responsiveness. That feedback came with a clear ask to keep rolling these improvements out to everyone so your friends, family, and other people in your life can experience them too. Some of that is already underway. Start and taskbar improvements have started rolling out broadly, and you can expect more as we head into the fall. You also asked us to explore new ways of sharing our work, including early design concepts and ideas. We recently held a feedback session where we shared the design for the File Explorer context menus that recently shipped to Experimental builds. You can expect more lightweight, early sharing sessions so we can hear your feedback before improvements make their way into Experimental builds. We also heard that it can be difficult to understand what’s happening with the feedback you submit. You want similar feedback grouped together and a clearer view of what we’re considering and actively working on. We’re increasing our investment in this area and will have more to share soon. A consistent theme across the meetups was the strength of the Insider community. Across each stop, attendees reconnected in person, met people they had previously only known online, and shared tips with one another. It was great to be together, swap insights, and spend time with this community. The feedback and energy we feel from Insiders help us shape Windows. We’re looking forward to keeping the conversation going as the tour continues. Marcus Windows Community Connection in Brooklyn, NYC on October 15: Register for a chance to attend an exclusive Windows Insider event on October 15 in Brooklyn: https://www.aka.ms/windowsfans. Hear from Microsoft leaders and the Windows Insider team, share your thoughts on the program, and get a closer look at what's ahead for Windows. Space is limited.
Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Claude Code Remote Control Server

1 Share

Claude Code Remote Control Server

In my last post I talked about using SSH to run Claude Code on one of my desktop machines while I’m traveling with my laptop. It works, but it has problems. The biggest one is that disconnecting kills Claude, and on bad airplane or hotel wifi, disconnecting happens a lot.

At the end of that post I said I’d write about Claude Code’s Remote Control feature, and then about running a Remote Control server. It turns out the first part is pretty short, so this post covers both.

Remote Control with /rc

Remote Control lets you start Claude Code on one machine and interact with that same session from somewhere else: the Claude mobile app, the Claude desktop app, or a browser at claude.ai/code. In a running Claude Code session you just type /rc (short for /remote-control), and the session shows up on your other devices.

This solves the biggest SSH problem. The session is running on the desktop machine, not inside an SSH connection, so if my laptop goes to sleep or the wifi drops, nothing happens to Claude. It keeps working, and when I reconnect I see whatever it did while I was gone.

I was happily using /rc for a while. I’d start a few sessions on devbox1 before leaving the office, run /rc in each one, and then work with them from wherever I happened to be.

Then Patch Tuesday came around.

Windows Update rebooted the machine overnight, and every one of those sessions went away. They were running in terminal windows on the desktop, and when the machine rebooted, the terminal windows were gone and so were the sessions. From my hotel room there was no way to start new ones, because /rc only works on a session that is already running. To start a session in the first place, someone has to be at the machine (or connected to it with SSH or a remote desktop tool) to run claude.

Remote Control Server

That’s when I discovered that Claude Code can also run as a Remote Control server:

claude remote-control

Instead of exposing one existing session, this runs a long-lived server process that my other devices can ask to create new sessions. From my phone or from the Claude desktop app, I pick the machine and start a session, and the server spawns a new Claude Code session in the directory where the server is running. By default a server allows up to 32 concurrent sessions.

This changes things a lot. The desktop machine is no longer something I need to set up before I leave. As long as the server is running, I can start whatever work I need, whenever I need it, from wherever I am.

Running It Without Logging In

For this to survive Patch Tuesday, the server has to start when the machine boots, without anyone logging in. You might expect that to mean a Windows service, but it doesn’t. A Windows scheduled task can do it, and that’s what I use.

There are two one-time steps to do first, while you’re logged into the desktop:

  1. Log into Claude Code. The server uses the login stored in your user profile.
  2. Run claude once in the directory where the server will run (for me that’s S:\src) and accept the workspace trust prompt. The server can’t show you that prompt later, because there is nobody to show it to.

Then create the scheduled task. The important settings are:

  • Run whether user is logged on or not, with Do not store password checked. Behind the scenes this is an “S4U” logon type. The task runs as you, but in a background logon with no desktop, and without Windows having to store your password.
  • A startup trigger with a one minute delay, so the server starts after every reboot.
  • A second trigger that repeats every 15 minutes, which acts as a self-heal if the script ever stops running.
  • If the task is already running, do not start a new instance, and no time limit on how long the task can run. My script keeps running for as long as the server does (more on that below), so these settings matter.

Here’s the PowerShell to create that task. Run it from an elevated prompt, and adjust the path to wherever you put the script:

$script = "$env:USERPROFILE\.local\bin\start-claude-remote-control.ps1"

$action = New-ScheduledTaskAction -Execute 'pwsh.exe' `
    -Argument "-NoProfile -NonInteractive -ExecutionPolicy Bypass -File `"$script`""

$boot = New-ScheduledTaskTrigger -AtStartup
$boot.Delay = 'PT1M'
$heal = New-ScheduledTaskTrigger -Once -At (Get-Date) -RepetitionInterval (New-TimeSpan -Minutes 15)

$principal = New-ScheduledTaskPrincipal -UserId $env:USERNAME -LogonType S4U -RunLevel Limited

$settings = New-ScheduledTaskSettingsSet -MultipleInstances IgnoreNew `
    -ExecutionTimeLimit ([TimeSpan]::Zero) -StartWhenAvailable -RunOnlyIfNetworkAvailable `
    -AllowStartIfOnBatteries -DontStopIfGoingOnBatteries `
    -RestartCount 3 -RestartInterval (New-TimeSpan -Minutes 5)

Register-ScheduledTask -TaskName 'Claude Code Remote Control' `
    -Action $action -Trigger $boot, $heal -Principal $principal -Settings $settings

⚠️ A background S4U logon can’t use Windows Credential Manager. That’s the same “nobody is logged in” problem I ran into with SSH. Claude Code itself was fine for me, but any tool that keeps its secrets in the credential store will have trouble.

With that in place, Patch Tuesday can reboot the machine all it wants, and a minute or so later the server is back and ready for new sessions.

ℹ️ If you stop the server and start it again in the same directory within about four hours, it brings back the sessions it was serving. So a reboot or restart is not the end of the world for work that was in progress.

Some SSH Problems Don’t Go Away

The Remote Control server solves the problem of sessions dying, but it doesn’t change the fact that Claude is running on a machine where nobody is logged into the desktop. So a couple of the problems from my SSH post still apply, and the solutions are the same.

After a reboot, Docker Desktop still isn’t running until someone logs in, because it is a per-user app that starts at login. Just like with SSH, my answer is to connect with a GUI remote desktop tool, log in so Docker (and anything else that starts at login) comes up, and then go back to working through Remote Control.

Git and the gh CLI also still need credentials that work without prompting. Nothing can pop up a login dialog or browser for a session started from my phone, any more than it could for an SSH session. Everything I described in the SSH post still applies: SSH keys for GitHub instead of Git Credential Manager, and a gh token that doesn’t depend on the desktop login session.

Phone or Desktop?

I’ve been using both the Claude mobile app and the Claude desktop app (on my laptop) to work with these sessions, and they each have their strengths.

The phone experience is more polished. The UI is clean and just works, and it is really nice to be able to check on a session, answer a question Claude has for me, or kick off a new task from my phone, wherever I am.

The desktop app, on the other hand, gives me a lot more screen real estate. When I’m reviewing what Claude did or having a longer back-and-forth about a design, a bigger screen matters, and the desktop app is nicer to work with for that.

So I tend to use the phone for quick check-ins and the desktop app when I’m actually sitting down to work.

My Environment, Not a Cloud Sandbox

It is worth pointing out how this is different from the cloud sessions you get with Claude Code on the web. Those run in a standard cloud environment that Anthropic provides. That’s fine for many things, but it isn’t my environment.

With the Remote Control server, the sessions run on my desktop machines, with all my tools: Docker, kubectl with access to my Kubernetes cluster, multiple .NET SDKs, my database tools, my MCP servers, and all my repos checked out where they belong. Claude isn’t limited by what a generic cloud environment happens to have installed. It has everything I have.

And I get all of that from my phone or laptop.

The Airplane Test

Over the past couple weeks I’ve been using this setup a lot, including from airplanes during flights and from hotel wifi.

As I discussed in the previous post, Claude Code uses a lot of bandwidth, especially upload bandwidth, because it keeps sending the conversation context to the model. With the Remote Control server, all of that traffic goes over my office internet connection. The only thing going over the airplane wifi is the conversation I’m having with Claude.

The result is that I really don’t worry about bandwidth anymore. Performance is good, and the overall experience is good. Airplane wifi is still airplane wifi, but it is no longer the thing standing between me and getting work done.

It’s been good enough that I set up the server on both of my desktop machines, devbox1 and devbox2. In theory that means I could have 64 sessions going at once! In reality I usually have somewhere between one and five sessions running at any given time, but it is nice to know the capacity is there.

Keeping It Running and Updated

There are two operational details worth knowing if you run a server like this for long periods of time.

First, if the network is down for an extended time (around 10 minutes), the server gives up and exits. So something needs to restart it. My script checks on the server every 5 minutes, and if it isn’t running it starts it again.

Second, Claude Code updates itself automatically (if you used the native installer), but an update doesn’t take effect until Claude Code restarts. A server that runs for weeks will happily keep running an old version the whole time, even though new versions have been downloaded.

I didn’t want to restart the server on a fixed schedule, because I travel across time zones and there isn’t a time of day when I’m reliably not using it. So my startup script now watches for two conditions: a newer version has been downloaded, and none of the sessions have done anything for an hour. When both are true, it restarts the server, which picks up the new version and brings the existing sessions back.

There were two surprises while building that.

The server’s own status display shows something like Capacity: 1/32, and my first thought was to restart when that says zero. It never does. The server always keeps one pre-created session, and the number counts sessions that exist, not sessions that are doing something. What works better is to look at the session transcripts Claude Code writes under ~\.claude\projects. If none of them have changed in an hour, nobody is using the server.

The other surprise was that the script couldn’t restart a server it hadn’t started itself. Every run of the scheduled task is a separate background logon, and one logon isn’t allowed to stop a process that belongs to another. So instead of starting the server and exiting, the script stays running as a supervisor for as long as the server runs. Because it started the server, it’s allowed to stop it. The “do not start a new instance” setting on the task means the 15-minute trigger does nothing while the supervisor is alive, and starts a new one if it ever dies.

The Script

I’ve put the whole script in a GitHub gist for reference. It assumes Claude Code was installed with the native installer (so claude.exe is in ~\.local\bin and downloaded versions are in ~\.local\share\claude\versions), and it takes parameters for the working directory, idle time, and so on. It logs to ~\.claude\remote-control-boot.log, which is the first place to look if something isn’t working.

ℹ️ The idle check has one blind spot. If Claude is running a single command that takes more than an hour without writing anything to the transcript, the server looks idle and could be restarted in the middle of it. That hasn’t been a problem for me, but if it is for you, raise -IdleMinutes.

Conclusion

Here’s where I’ve ended up:

  1. /rc is great for making an existing session available from your phone or another computer, and it solves the “disconnecting kills Claude” problem I had with SSH.
  2. /rc can’t help you if the session is gone, which is exactly what happens when Windows reboots the machine.
  3. claude remote-control runs a server that lets you start new sessions from your phone or the Claude desktop app, so you don’t need to set anything up before you leave.
  4. Start the server when the machine boots, restart it when it exits, and give it a way to pick up updates.
  5. The “nobody is logged in” problems from SSH still apply. Docker Desktop needs a login, and Git and gh need credentials that don’t prompt.

For me, this is the setup I was looking for when I started down this path with SSH. Claude runs on a well-equipped desktop machine with all my tools, and I can start and work with sessions from anywhere, over just about any network connection.

This post was authored with the assistance of AI.

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Code it with AI

1 Share

Code it with AI

For the past couple of months I’ve been co-hosting Code it with AI, a YouTube series with Carl Franklin (yes, that Carl, from .NET Rocks!). I haven’t mentioned it here yet, and that’s an oversight I should fix.

What Is It?

Code it with AI is a series of short videos aimed at .NET developers who want to get real value out of AI tools. Carl started the show with Jeff Fritz from Microsoft, and it’s presented by DevExpress.

Each episode is usually around 20 minutes long and focuses on one topic. We don’t spend a lot of time talking about AI in the abstract. Instead, we show the tools actually doing things: GitHub Copilot, Claude Code, local models running in Ollama, MCP servers, agents, and whatever else is new and interesting that week. As the site says, the show is safe for work: “We’re here to have fun and learn things.”

My Episodes So Far

Carl welcomed me as his new co-host in Episode 39, and since then we’ve covered a pretty wide range of topics. Several of them are things I’ve written about here on the blog, so if you prefer reading to watching (or want both), here’s how they line up:

Our next episode (not released yet) covers the Claude Code side of remote control, based on my recent posts SSH Is Not a Desktop and Claude Code Remote Control Server.

The earlier episodes with Carl and Jeff are worth a look too. They cover a lot of GitHub Copilot features, skills, agents, local models, and more.

Check It Out

New episodes come out regularly. You can find all of them at codeitwithai.com, with links to each video on YouTube.

If there’s a topic you’d like to see us cover, let me know!

This post was authored with the assistance of AI.

Read the whole story
alvinashcraft
4 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

PostgreSQL to SQL Field Notes: Date & Time

1 Share

Welcome to SQL

First, welcome to SQL! You’re going to like this.

Upgrading from PostgreSQL is real work, and depending on your old PostgreSQL, that process can vary widely in complexity. You’re going to love the mindful and modern features of SQL. Take your time, make the most of the resources built to help you in Microsoft Learn, and know there is a huge community of SQL developers ready to help along the way.

pg to sql datetime image

This blog is for the PG developer.

The SQL standard has helped align the shape of the two engines, and that familiarity will help you get up to speed quickly. However, there are differences, and there aren’t always equivalents. To help fast-track your learning, this series will highlight some differences worth knowing. Although some may surprise you, I believe most will be a delight.

Handling date and time

Let’s start with an everyday feature: handling date and time. In PostgreSQL, you have the timestamp and timestamptz types.

PostgreSQL timestamp

In PG, you use the timestamp type to store date and time values without any time zone information.

PostgreSQL has had a type named timestamp since well before PostgreSQL 7.0, but its meaning evolved. PostgreSQL 7.0 replaced the older datetime type with timestamp, and PostgreSQL 7.2 introduced the modern distinction between timestamp without time zone and timestamp with time zone. Today, a bare timestamp means timestamp without time zone.

Using timestamp

SELECT TIMESTAMP '2026-09-21 10:30:00';

The value of timestamp in this case is stored exactly as provided. No time zone information is provided, and none is stored.

SELECT TIMESTAMP '2026-09-21 10:30:00-06:00';

If you include a time zone offset, timestamp simply ignores it. Even though you provided the -06:00 offset from UTC, that information is discarded. This behavior remains documented in PostgreSQL today.

If your application needed to preserve the original time zone or offset, you had to store that information separately.

CREATE TABLE events (
    event_id SERIAL PRIMARY KEY,
    event_name TEXT NOT NULL,
    event_timestamp TIMESTAMP NOT NULL,
    event_timezone TEXT NOT NULL
);

This works, but now two values describe one event. Your application is responsible for keeping them together and interpreting them correctly.

SQL’s closest equivalent: datetime2

SQL’s closest equivalent to PostgreSQL timestamp is datetime2. SQL’s datetime2 is the modern replacement for SQL Server’s legacy datetime type. Microsoft recommends datetime2 for new development.

Incredible precision

datetime2 supports variable fractional-second precision from 0 to 7 digits and defaults to datetime2(7). At the default, it can represent time in 100 ns increments. PostgreSQL timestamp supports 6 fractional-second digits, or 1 μs increments. This gives SQL Server 10× finer representational precision over PostgreSQL.

If your use case demands higher precision for scientific instruments, streaming data, or financial applications, SQL’s datetime2 means you no longer need to compromise on precision.

PostgreSQL timestamptz

PostgreSQL 7.2 established the modern distinction between timestamp without time zone and timestamp with time zone, commonly written today using PostgreSQL’s timestamptz shorthand.

SELECT TIMESTAMPTZ '2026-09-21 10:30:00-06:00';

This time, the offset matters. PostgreSQL uses it to determine the actual instant in time and stores that instant internally in UTC.

Unfortunately, you already know the caveat

PostgreSQL does not retain the original time zone or offset. When the value is retrieved, PostgreSQL converts it to the session’s current TimeZone.

So PostgreSQL cannot answer, “What offset did the application originally supply?” And the session TimeZone does not inherently know the user’s or application’s local time zone. The application must set the session TimeZone appropriately or perform the conversion itself.

So the same stored value can look different depending on who asks for it:

SET TIME ZONE 'America/Denver';

SELECT TIMESTAMPTZ '2026-09-21 10:30:00-06:00';
-- 2026-09-21 10:30:00-06

SET TIME ZONE 'America/New_York';

SELECT TIMESTAMPTZ '2026-09-21 10:30:00-06:00';
-- 2026-09-21 12:30:00-04

Both results represent exactly the same instant. That’s intentional PostgreSQL behavior. But if your application needs to know that the original value was 10:30 -06:00timestamptz cannot tell you. That information is lost during the insert.

It can be frustrating. Application developers who need the original offset are left to handle it manually. The offset has to be stored separately rather than embedded in the value itself. The value of timestamptz is that PostgreSQL normalizes timestamps to a common instant and automatically converts them to the session’s configured time zone when retrieved.

Good news! You’re using SQL now.

Introducing SQL’s datetimeoffset type. When time zone information is important, datetimeoffset allows you to store both the local date and time as well as the offset from UTC, preserving the original context of the timestamp.

DECLARE @dt DATETIMEOFFSET = '2026-09-21 10:30:00-06:00';

This advanced type has been around since SQL Server 2008. Ubiquitous in modern SQL Server applications, it provides a flexible way to handle time zone information.

Here’s how it works

The datetimeoffset type stores both the local date and time as well as the offset from UTC. This means that when you insert a value like '2026-09-21 10:30:00-06:00', SQL Server retains the -06:00 offset along with the date and time, preserving the original context of the timestamp.

Do you want to show it as UTC? You have two easy options:

SELECT @dt AT TIME ZONE 'UTC';

SELECT SWITCHOFFSET(@dt, '+00:00');

Both return the same instant at UTC.

Both return the same instant at UTC. AT TIME ZONE is useful when working with named time zones and their conversion rules. SWITCHOFFSET is simpler when you already have a datetimeoffset and just want to change its displayed offset to UTC.

By the way, that same ultra-high precision you enjoy with SQL’s datetime2 is available with datetimeoffset, but with the added benefit of time zone awareness.

-- Example showing high precision with datetimeoffset

DECLARE @dtHighPrecision DATETIMEOFFSET(7) =
    '2026-09-21 10:30:00.1234567-06:00';

SELECT @dtHighPrecision;

Storage differences

datetimeoffset requires 8 to 10 bytes of storage, depending on fractional-second precision. This is slightly more than datetime2, which requires 6 to 8 bytes. The additional 2 bytes store the time zone offset.

Consider the impact of this additional storage across a billion rows. Attending to storage doesn’t just save disk space; it can also reduce I/O, memory pressure, and index size.

Rows datetimeoffset datetime2
1 B 8–10 GB 6–8 GB

That’s a 2 GB difference in storage for a billion rows. Since dates are so common in many applications, this difference can have a significant impact on overall storage requirements and performance.

Your default type for dates

Because of this storage difference, your default should not always be datetimeoffset, especially when your app doesn’t care about the time zone. In many cases, datetime2 remains an excellent choice.

Having said that, since precision is variable, you can also balance storage requirements with the need for time zone awareness by carefully choosing the appropriate precision for your application.

Rows datetimeoffset(0) datetimeoffset(7)
1 B 8 GB 10 GB

That’s a 2 GB difference in storage for a billion rows when choosing between the lowest and highest precision for datetimeoffset. What’s more, you still have time zone support when you need it.

Congratulations

Let me welcome you again to SQL! I hope it’s clear that you’ve joined a rich and thoughtful ecosystem. Choosing the right date and time type for your application is important, and SQL helps make that easier, simpler, and better.

Happy querying!

The post PostgreSQL to SQL Field Notes: Date & Time appeared first on Azure SQL Dev Corner.

Read the whole story
alvinashcraft
5 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Daily Reading List – September 21, 2026 (#871)

1 Share

How’s your workweek starting off? I slogged through a full inbox while navigating an array of meetings. Not sure about you, but I also find myself firing off various “explore this” questions to my AI agent, and then reading the answers in batches during free moments. That happened a couple times today.

[blog] What I believe about the future of software development. Buckle up. I can’t see many flaws in this position. But it likely represents a radical change to how you’re doing technology and software now.

[article] Runtime: Jev is an LLM without the LL. Wow, Jev was everywhere this past weekend. It doesn’t code or reason. Jev is for fast, structured decision making. More here too, and here.

[blog] The agents are coming for the web and the web isn’t ready. I’d imagine this isn’t just crawlers. It’s all of us using personal agents that helpfully go out (async) and try to get answers.

[article] Popular isn’t a business model. “Open source” isn’t a business model. You have to do something with it. Ben lists out six proven options here.

[blog] Scaling Golang CI by Replacing actions/setup-go. If you’re doing continuous integration with Go on GitHub Actions, there’s a smarter way.

[article] Navigating the Modern Data Lexicon: A Working Vocabulary for the Semantic Era. It’s easy to pick up tech jargon, and then realize you barely know what that term means. Hill climbing, anyone? Here are seven data-related terms that you might want to understand better.

[blog] Accelerating the borderless Lakehouse: Announcing preview of cross-cloud caching. All that cross-cloud data movement isn’t cheap. We just added some smart caching that dramatically reduces how much data leaves each source.

[article] Meta’s AI agent has been blocked from using Amazon.com. And Shopify responded with an integration into this personal agent. Those who embrace the agentic consumer will quickly surpass those who do not.

[blog] Scale your AI workloads faster and more efficiently with GKE Pod snapshots. Wow, this makes a massive difference. In the examples provided, inference start-up time is down by nearly 90%.

[blog] SaaS platforms are surging despite the SaaSpocalypse. Looks like SaaS is doing fine? Platforms can differentiate well, even better, in the AI era.

[article] Do engineers still need to understand how LLMs work? Can you skip the effort to learn the plumbing of LLMs? Just call the API and get back to work? Sebastian Raschka thinks it’s still worth a deeper look.

Want to get this update sent to you every day? Subscribe to my RSS feed or subscribe via email below:


Read the whole story
alvinashcraft
6 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories