Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
164480 stories
·
33 followers

Catch Microsoft Entra at Ignite 2026

1 Share

Join us at Microsoft Ignite 2026, November 17–20, 2026, at Moscone Center in San Francisco and online. Explore Microsoft Entra and learn how to secure access for users and AI agents. From stopping identity attacks to simplifying access policies and securing agents, our sessions bring practical guidance and demos to your toughest access challenges.

Use this guide to plan your sessions, connect with our team, and enter the Microsoft Entra prize draw!

Enter the Microsoft Entra prize draw

Registered for Ignite? Check in at any of the five eligible Microsoft Entra sessions in this post for a chance to win. These are the live-streamed breakouts, which you can join in person or online.

How to enter

Scan the QR code shown during an eligible session and complete the short entry form. Each session you check in to earns one entry.

Entry period

12:00 AM PT on Tuesday, November 17, through 11:59 PM PT on Friday, November 20, 2026.

Prizes

One grand prize: an Xbox plus a 30-minute chat with a Microsoft Entra identity architect.
Two Microsoft Entra swag bags: one for a decision-maker and one for a practitioner.

Drawing

Winners are selected by random drawing on December 1, 2026. Swag bag winners come from decision-maker and practitioner entries, and the grand prize winner from all entries.

NO PURCHASE NECESSARY. Open to legal residents of the United States, including the District of Columbia and Puerto Rico, who are 18 or older and registered for Microsoft Ignite 2026. Entry period: November 17, 2026, 12:00 AM PT, to November 20, 2026, 11:59 PM PT. See the Official Rules for full details. 

Don't miss the Microsoft Entra news session

All breakout sessions will stream live, stay available on demand, and count toward the prize draw. Join them in San Francisco or online. 
For onsite locations, please visit the linked session details.

Wednesday, November 20

If you only catch one Microsoft Entra session, make it this one. Here, we will dive into what’s new in Microsoft Entra!

⭐AI is changing access. See how Microsoft Entra helps you stay ahead.

10:15–11:00 AM PT · Breakout · Session code: BRK343

Speakers: Yina Arenas, Chief Product Officer – Microsoft Identity and Network Access; John Savill, Chief Technology Officer, Americas Markets and Industries; Nichole Peterson, Senior Product Marketing Manager

Get the identity and network access roadmap to help your organization get ready for AI, scale AI responsibly with Microsoft Agent 365, and leverage AI to detect and disrupt attacks. See what's new in securing access for people and agents, reducing risk, and enabling productivity without weakening protection. This team delivers top-ranked, standing-room-only sessions every year, so don't miss it!

Session details & RSVP

Thursday, November 19

A single policy for humans and AI agents? Here's how to make it work

1:30–2:15 PM PT · Breakout · Session code: BRK331

Speakers: Danielle Augustin, Product Marketing Manager; Sharon Chahal, Principal PM Manager; Etan Basseri, Principal Product Manager - Security

Dozens of policies become hundreds, and changing one can break something downstream. See how a unified policy engine brings identity, network, device, and risk signals together to make access decisions without forcing teams to untangle dependencies. Learn how to scale adaptive access with confidence and control.

Session details & RSVP

Local agents are here. Can you find and secure them?

4:00–4:45 PM PT · Breakout · Session code: BRK339

Speakers: Swaroop Krishnamurthy, Principal Product Lead; Dareen Radwan, Principal Software Engineering Architect; Erica Toelle, Sr. Product Marketing Manager

Local agents can unlock major productivity, but unmanaged adoption introduces risk leaders cannot ignore. Learn how to close the visibility gap, reduce risk, and enable trusted agent adoption without slowing innovation.

Session details & RSVP

Friday, November 20

Identity knows what your SOC doesn't: Stop threats faster together

9:00–9:45 AM PT · Breakout · Session code: BRK332

Speakers: Yair Tor, Partner Product Management; Etan Basseri, Principal Product Manager - Security; Martin Schvartzman, Principal Product Manager Lead

Identity attacks move fast. Your teams need to move faster. See how Microsoft Entra and Microsoft Defender bring identity context and risk signals into SOC investigations, helping IAM and security teams detect, investigate, and disrupt threats faster with unified visibility and automation.

Session details & RSVP

Modern phishing doesn't end at the click

11:30 AM–12:15 PM PT · Breakout · Session code: BRK334

Speakers: Ankur Patel, Partner Group Product Manager; Cristian Craioveanu, Principal Security Research Manager; Sangeeta Ranjit, Principal Manager Product Management

Attackers don't need to steal your password to compromise your identity or account. See how AI-powered phishing, impersonation, compromised accounts, and identity-based attacks are changing the game, and how identity, email, and collaboration security help defenders detect and disrupt threats before they spread.

Session details & RSVP

Additional sessions if you're attending in person

If you're in San Francisco, add these sessions to your schedule too. These sessions don't count toward the prize draw. Labs require an RSVP and fill fast.

And don’t forget to stop by the Microsoft Security booth to meet the team!

When (PT)

Session

Format

Code

Tue, Nov 17, 4:05–4:30 PM

AI agents: access granted. Trust not included

Theater*

THR877

Tue, Nov 17, 6:15–7:30 PM

Can't secure what you can't see. Find every AI agent in your org

Lab

LAB682

Wed, Nov 18, 9:50–10:05 AM

AI agents need access. Your network needs controls.

Lightning talk

LTG1242

Wed, Nov 18, 10:05–10:50 AM

Is Powerful Access Your Biggest Risk? Get Privileged Access Right

Table talk

TT2528

Wed, Nov 18, 10:15–11:30 AM

AI Agents Are Sending Signals. Make Access Respond.

Lab

LAB680

Wed, Nov 18, 12:15–1:00 PM

AI Agents Are Scaling. Are Your Access Controls Ready?

Table talk

TT2530

Wed, Nov 18, 4:00–5:15 PM

Can't secure what you can't see. Find every AI agent in your org

Lab

LAB682

Wed, Nov 18, 4:00–5:15 PM

AI Agents Are Sending Signals. Make Access Respond.

Lab

LAB680

Thu, Nov 19, 9:00–9:15 AM

Oops! Someone Deleted a Critical Identity. Can You Get It Back?

Lightning talk

LTG1236

Thu, Nov 19, 9:00–10:15 AM

AI Agents Are Sending Signals. Make Access Respond.

Lab

LAB680

Thu, Nov 19, 10:00–‍10:20 AM

Strengthen Security Across Your Multitenant Estate

Community Theater

COMM13

Thu, Nov 19, 10:45 AM–12:00 PM

Can't secure what you can't see. Find every AI agent in your org

Lab

LAB682

Thu, Nov 19, 2:00–‍2:20 PM

Meet the Entra Agent ID Product Team and Get Your Questions Answered

Community Theater

COMM17

Thu, Nov 19, 2:35–2:50 PM

Customers Expect a Frictionless Login. Attackers Do Too.

Lightning talk

LTG1235

Thu, Nov 19, 2:45–4:00 PM

AI Agents Are Sending Signals. Make Access Respond.

Lab

LAB680

*This session is recorded for on-demand viewing after the event.

Can’t be at Ignite in person?  Join our live expert AMA!

AMA: Ask Microsoft Entra anything – Ignite 2026 edition

Wednesday, December 2, 2026, 11:00 AM Pacific Time

Yina Arenas, Chief Product Officer – Microsoft Identity and Network Access, Led by Nichole Peterson, Senior Product Marketing Manager

Bring your questions from Microsoft Ignite to a live AMA with Microsoft Entra experts. Go deeper on securing access for users and AI agents, simplifying adaptive access, protecting against modern identity attacks, and bringing identity context into security operations. Our experts will unpack the Ignite announcements and help you turn what’s new into practical next steps for your organization.

Register now and post your questions in the comments! 

Don’t miss our Microsoft Entra December webinar series

From December 15–17, the Microsoft Entra webinar series goes further into the Ignite announcements with new demos and practical guidance. Get the dates and register.


Excited to see you all at Ignite -- whether you are in person, or attending virtually! 

- Ngozi Nwoko, Director of Product Marketing, Microsoft Entra


Learn more about Microsoft Entra

Prevent identity attacks, ensure least privilege access, unify access controls, and improve the experience for users with comprehensive identity and network access solutions across on-premises and clouds.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

Issue 775

1 Share

Comment

The past couple of weeks have been quite eventful for the Apple Developer community, with multiple notable announcements from Apple that I’d like to discuss today.

First, let’s touch (pun intended) on the subject of the new MacBook with Touch and the increasingly blurry boundaries between macOS and iPadOS. After rewatching the accompanying tech talks, Bring Touch to your Mac app in particular, I noticed two important details that eluded me on the first viewing.

For one, gesture recognizers have become a shared input language across SwiftUI, Mac Catalyst, and now AppKit. This means that iPadOS and macOS apps can handle interactions through a common high-level abstraction.

Second, we can directly touch macOS apps on an iPad connected via Sidecar. For all intents and purposes, the experience of using Mac apps on an iPad is now blessed by Apple, even if only for testing purposes.

All this reinforces the idea that macOS and iPadOS are on a collision course, and revives the age-old question: when will we finally see native Mac apps running on iPads?

Then there’s the announcement that’s making waves in the dev community right now. Apple has opened Siri AI to all developers and published the (uncharacteristically well-documented) Siri AI Developer Preview.

I always struggled to get excited about using App Intents to integrate with Siri, and not only because of Siri’s subpar performance. There was something else. Jordan Morgan’s post, Finally, Apple Frees us from Domains, helped me find the right words to express my reservations. My apps never neatly fit into the predefined schemas and domains Siri understood. The new paradigm, in which apps can expose arbitrary functionality as tools using the @AppIntent(.tool) macro and bundle App Skills to help Siri understand how to use them, should finally lift those subtle constraints.

That said, I doubt that businesses that rely on people spending time in their apps will be too keen on opening up to this more capable Siri performing tasks on users’ behalf. I suspect we’ll see a significant split in Siri AI adoption across different app categories.

– Alex Ozun

More Swift. More builds. Less waiting.

More AI-assisted commits mean more builds to pay for. WarpBuild runs your Xcode jobs on M5 Pro Macs, with up to 3x faster builds and pricing from $0.08 per minute. Get feedback sooner as your build volume grows. Try one GitHub Actions workflow with $50 in free credits using code iosdev2026.

News

WebKit.org | Introducing Adaptive Dark Mode

Another notable announcement came from the WebKit team: Introducing Adaptive Dark Mode. While not too relevant to native app development, I think it’s fantastic news nevertheless, and I wish this capability had been around when I agonized over dark-mode CSS for my blog (time I will never get back). As a Safari user, I’m hoping to also see the opposite feature, Adaptive Light Mode, that inverts dark-only websites that unfortunately are trendy these days (is AI to blame here?).


Good bye to Swift

NASA confirmed that the Swift observatory spacecraft re-entered Earth’s atmosphere and mostly burned up during re-entry. RIP, aged 22.

Code

The simulator is crackling again: what changed with Device Hub and how to fix it

Somehow, the simulator bug that messes up your audio returned!

Karolina Samorek explains why the workaround of redirecting the simulator’s audio into the BlackHole no longer works in Device Hub, and proposes two alternative fixes. Thank you for your service!


iPhone Duo collection | Nil Coalescing

Nil Coalescing have been publishing high-quality articles on adapting apps for iPhone Duo over the past few weeks, so having them neatly assembled in a collection is helpful indeed! It’s a great place to start if you’re just getting into iPhone Duo adoption.


Interesting ways of using Swift optionals

What’s the best way to prevent AI-induced deskilling? To regularly go back to basics! John Sundell’s latest article offers just that, and maybe even more! Optionals have been Swift’s workhorses since day one, but you may still be surprised by some lesser-known uses for the humble Optional.

Tools

PictureWriter | a Mac video editor

Pasi Salenius just announced the launch of PictureWriter, a small, native Mac video editor. The app is another testament to just how optimized unapologetically native Mac apps can be. It’s faaast and lightweight at ~25MB, with lots of effects and presets that will be particularly interesting to app developers working on App Store listings and promo materials.


Stream for Mac | A Feed Reader

What, another blazing-fast and lightweight Mac-assed app in the same issue? Is the holiday season approaching? Oh yeah, I guess it is!

Rob Fahrni just released Stream for Mac, a unified feed reader for news and RSS subscriptions. I like how you can just drop in a website URL and it’ll find a way to subscribe without me needing to hunt down the exact RSS feed page. Cheers, Rob!


DeviceMCP | MCP for your iPhone

Noah Tran, the developer behind the popular Proxyman app, just launched a new tool that allows AI agents to connect to physical iPhones and iPads via an MCP server. This lets agents control devices with actions like tapping, swiping, and opening apps. Something similar was already possible with DeviceHub, but the new MCP-based approach promises better token efficiency and control accuracy.

Business and Marketing

App Store 2026 in numbers

Obelisk Club analyzed 178,637 apps that appeared in the App Store top charts across 173 countries and presented some interesting insights. About 10% of these apps mention AI in their App Store listings. Meanwhile, about ~20% haven’t been updated for a year or more, and ~10% for three years or more. Wow, that’s a lot of abandonware in the top charts. Granted, not every app needs regular updates, but the number is still higher than I expected. I know that Apple’s been sending out delisting notices for abandoned apps lately. I wonder how many of those charting apps will be affected.

Videos

Apple Intelligence Group Lab | 11/4/26 | Meet with Apple

Hot on the heels of the Siri AI Developer Preview, we got an Apple Intelligence Group Lab session.

Anton Gubarenko created a helpful timestamped Q&A summary, which is increasingly becoming my preferred way to catch up on these labs without sitting through the entire session.

And finally...

Swift programmers love static typing. But what about duck typing?

Read the whole story
alvinashcraft
18 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Claude in Copilot is coming into the EU Data Boundary

1 Share

European organizations have had to make a trade-off with Claude models in Microsoft Copilot. They could use Claude, or they could keep the Microsoft regional data-processing commitments they rely on. Many chose the commitments and kept Claude switched off.

That trade-off is going away. That trade-off is going away. Microsoft has announced that Claude models in Copilot will move into the EU Data Boundary by the end of 2026. That covers Copilot Cowork too.

What was announced

On November 5, 2026, Charles Lamanna announced in Bringing Claude models in Microsoft Copilot into the EU Data Boundary that Claude models by Anthropic in Microsoft Copilot are coming into the EU Data Boundary.

The key points:

  • Timing: by the end of 2026.
  • Who: organizations in the European Union (EU) and the European Free Trade Association (EFTA).
  • Where: across Copilot experiences, including Copilot Cowork. Data is processed inside the EU Data Boundary, where it’s already stored.
  • Why it matters: organizations won’t need to choose between Claude models and Microsoft’s regional data-processing commitments any more.

The last point is the important one. For many organizations in Europe, that has been a real choice. Now it won’t be.

Remember that is a model is in Frontier / preview, it very likely runs outside of EUDB!

Why this matters – no more either-or

The EU Data Boundary is Microsoft’s commitment to store and process data for Microsoft 365 and other online services inside the EU and EFTA. A few things worth remembering:

Claude models already run work across many Copilot experiences: Chat, Copilot in Microsoft 365 apps, Copilot Cowork and Copilot Code. But for organizations that rely on the EU Data Boundary, using Claude meant stepping outside the commitments their compliance work is built on.

For a lot of organizations, especially in the public sector and regulated industries, that was enough to say no. Or at least “not yet”.

Once Claude is inside the boundary, it joins the other leading models already processing data there, including Microsoft-operated models. Claude becomes one more option in the Copilot model line-up, with the same data commitments as the rest. Organizations can then scale the latest AI across the organization without making an exception for one model provider.

Model choice with the same protections

Copilot brings models from Anthropic and other providers into one governed experience that is grounded in your work. The idea is simple: people can pick the right model for the task at hand.

Claude in Copilot comes with the same protections as the rest of Copilot:

This is what makes model choice work at enterprise scale. Security, compliance and governance stay the same whichever model does the work. For how Microsoft protects and limits access to customer data, see Microsoft Data Access on the Microsoft Trust Center.

What admins need to know

The admin side is easy to follow:

  • Already using Claude in Copilot? You don’t need to do anything. Once processing is available inside the EU Data Boundary, it moves there automatically.
  • Not enabled yet? You can turn Claude on at any time. Processing moves into the EU Data Boundary once it’s available.
  • Default setting: In the EU and EFTA, the setting is disabled by default.
  • Who gets access: Admins can enable Claude for all users or for selected users and groups in the Microsoft 365 admin center.

The setup details are on Microsoft Learn: Anthropic models in Microsoft Online Services. Microsoft has said it will share more details as availability gets closer.

A practical tip: don’t wait until the end of the year to start the discussion. If your organization kept Claude off because of data processing location, now is a good time to revisit that decision. You can also plan which users or groups should get it first.

Model choice becomes a governance question

AI is moving fast, and the best model for a task can change. Copilot’s approach is to give organizations one governed experience for adopting leading models as they evolve. Security, compliance and admin controls stay the same throughout. See Understanding AI functionality and models in Microsoft Online Services for the bigger picture.

For that to work in Europe, every model needs to have the same data commitments. Otherwise model choice is only real in some regions. Bringing Claude into the EU Data Boundary closes one of the biggest gaps.

Model choice in Copilot is turning into an admin and governance decision more than a technology one. Is your organization ready to make that call when Claude moves inside the boundary?

Learn more


Read the whole story
alvinashcraft
32 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

The Real MVP of GitHub Universe 2026: Context

1 Share

Last week, I gave a talk at GitHub Universe 2026 about context. The question behind it: when a coding agent changes one API, how does it know what else that change breaks?

The demo answers it with two agents building on a healthcare app, each in its own session with no shared memory. Agent A uses the Postman Context Graph to find which services supply the data for a claims-review API, builds a simulation of those dependencies, and publishes it to a Postman workspace. Agent B pulls that simulation, runs the existing tests, and extends the API. The checks go from 10 passing assertions to 14, and Agent B never has to rediscover a dependency.

The part nobody talks about

My talk was called “Agentic SDLC with Context Graph and API Simulations.” The premise: all of us use coding agents to do engineering work, and it’s rare for that work to have no downstream dependencies that also need updating. The agent writes the code, silently breaks a bunch of other things, and you get paged for an incident tied to your change. That’s the part nobody talks about. The agent does the engineering work, but I’m the one keeping track of everything around it: the context, the dependencies, what’s been verified, and what else needs to be updated. The talk was about handing more of that tracking to the agent, using the Postman plugin.

The endpoint is the fast part

An agent can write an endpoint quickly. The work around the endpoint is what takes longer. I framed it with four items:

What takes longer What it means for an agent
Contract Understanding what the API promises
Dependencies Finding every service the change touches
Tests Checking the behavior, not only whether it compiles
Handoff Leaving the next person or agent a setup they can use

The Postman plugin gives an agent skills for API engineering. Each skill holds instructions the agent can read for a task: which tools to use, which files to work with, and how to check the result. The full plugin covers development, testing, documentation, CI, and monitoring, so it reaches every phase of the SDLC. For this talk I picked two skills:

  • api-discovery, which includes the Context Graph, helps the agent understand the APIs and relationships involved.
  • api-simulation gives the agent an environment where it can develop against those dependencies.

Then I added a constraint to make the demo honest: two agents working on consecutive tasks, in separate sessions, with a Postman workspace as the only thing carrying work between them.

A librarian, a catalog, and a lot of shelves

To explain why the Context Graph comes first, I used a library.

Imagine you walk in and ask the librarian to find everything about chess. There’s no computer catalog, so the only way to answer is on foot. The librarian walks the building, searches every shelf, and inspects individual books. A more experienced librarian might do that faster and notice more, but they’re still searching the entire building from scratch.

Now give the librarian the catalog. Instead of starting at the first shelf and working aisle by aisle, book by book, page by page, they search once and get a list of relevant books with exact shelf locations. The catalog tells them where to begin, which books to pull, and which sections deserve a closer look. It can also point to a chapter inside a book with an unrelated title, a book stored at another location, or a resource that isn’t on a physical shelf at all, like an audiobook. The librarian then opens the books and verifies they contain what you need.

In the analogy In the agent workflow
The librarian The model
The shelves The checked-out repositories
The catalog The Context Graph

The Context Graph tells the model which services, APIs, endpoints, and relationships are likely to matter and where to focus its search. Instead of exploring hundreds of repositories one by one and burning countless tokens, the model starts with a specific set of candidates and verifies those leads in the code wherever it can. Postman’s own writing on why AI coding agents need context graphs makes the same argument with more depth.

The analogy also answers the question I get most about model quality. A better model is a faster, more experienced librarian. It searches the shelves more efficiently, but it still can’t find something that isn’t on those shelves. The Context Graph gives the agent a starting point: which APIs are relevant to the task, where to find them, and which relationships to verify.

Develop against dependencies you can’t run

Knowing where an API lives doesn’t mean its service is available to run on your laptop. That’s the gap api-simulation fills.

Say my service calls four other APIs. To develop it locally, I need to exercise those calls, including their responses and failures, without bringing up all four real services. A Postman simulation groups the dependency mocks into one runnable setup. Each mock represents an API, and the simulation defines how to reach them together. My real service runs locally and sends its dependency calls to that setup, and I can add delays, errors, and rate limits to see how the service behaves when a dependency has a bad day.

Then comes the handoff. I save the requests and assertions as a Postman Collection and publish the simulation and the collection to a workspace. Another agent can retrieve both, start the same dependency setup, and rerun the existing checks before it changes anything.

The demo: two agents, one workspace

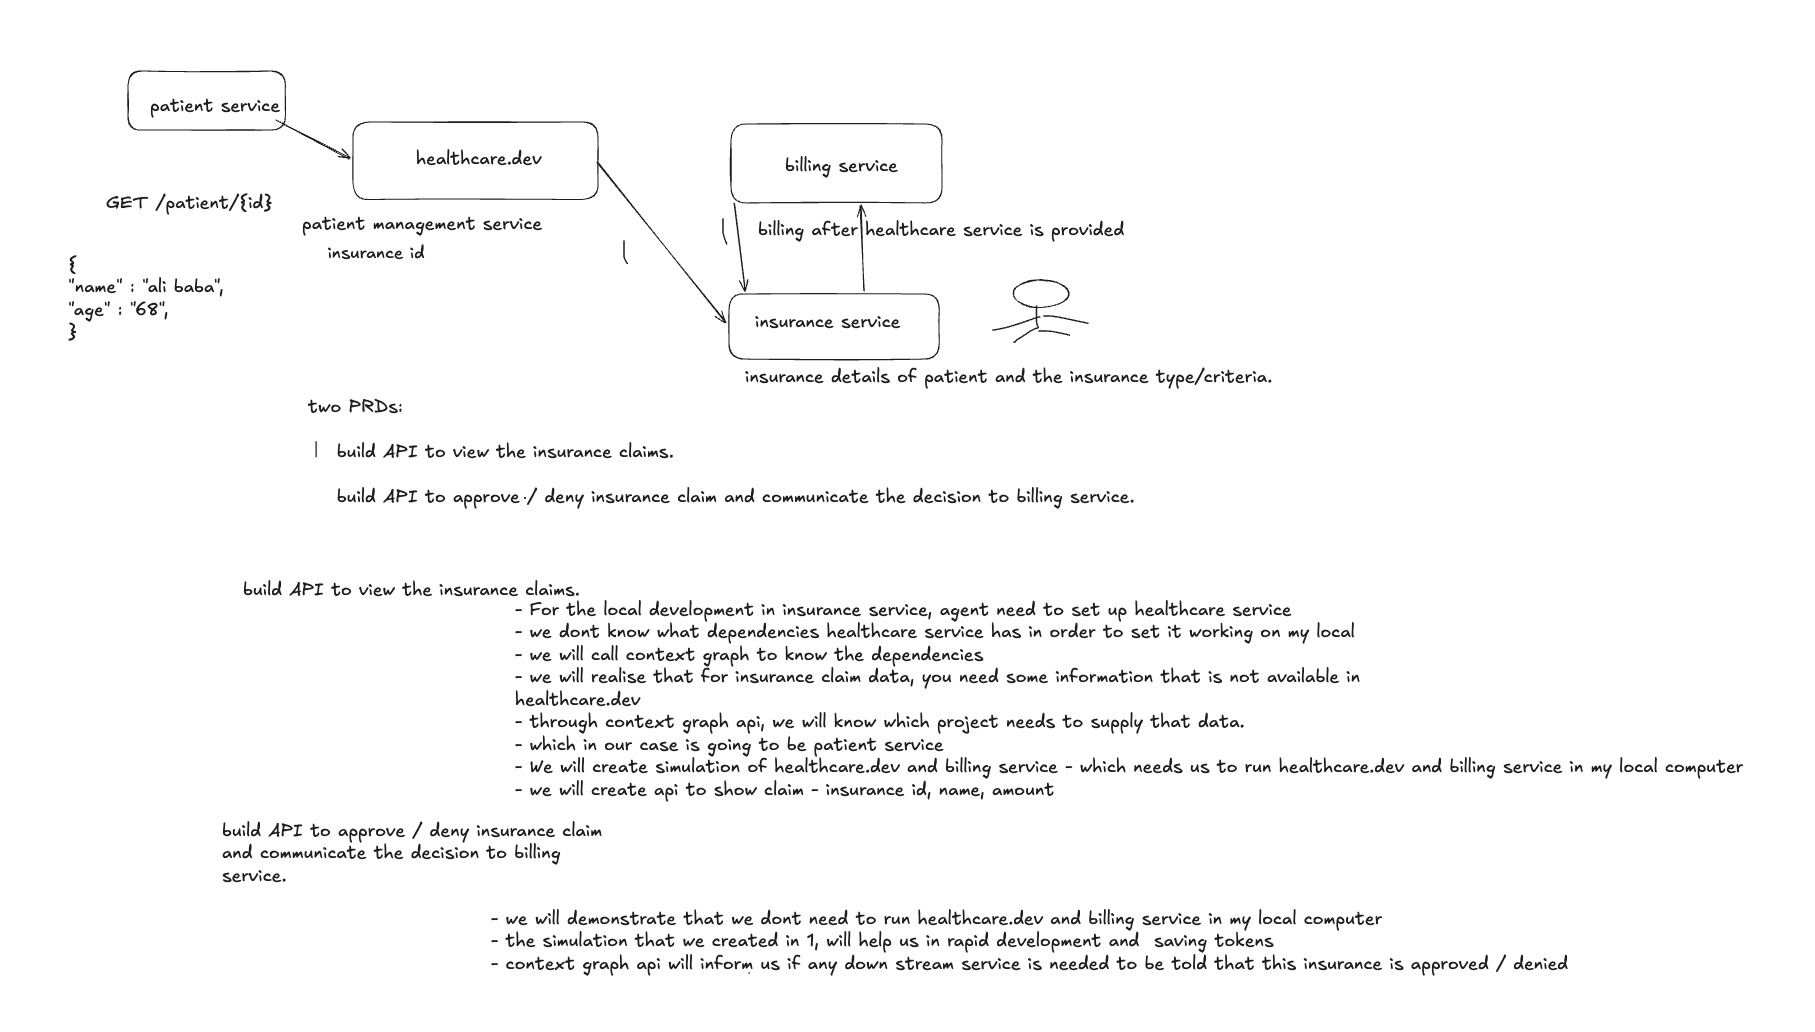
The demo used a hospital app, myhealthcare.dev, with services that manage patients and billing. The goal was to add an insurance service so a user can view claims and approve or deny them. I split the work between two agents and drew the whole thing on a whiteboard first.

A hand-drawn architecture sketch showing the patient service, healthcare.dev, the billing service, and the insurance service, with notes on two product requirement documents for viewing claims and approving or denying them
The whiteboard sketch from the talk. Claim data is spread across services, so Agent A has to find out which ones supply it.

Agent A builds the API for viewing claims. Each claim needs an insurance ID, a patient’s name, and a billing amount, and that information lives in different services. The patient’s name comes from the patient service. Agent A asks the Context Graph where to get each piece and which dependencies it needs.

Here’s the start of the prompt I gave it:

Prompt

I’m adding a claims-review feature to claims-status-service: look up a claim with its patient’s name, and approve or deny it, which notifies billing. Ask the Context Graph which services supply the claim and patient data and what relationships to account for, then build a local simulation of those dependencies from the repo’s existing mocks. Implement the feature against the simulation and create a Postman collection with checks for it.

You can watch the whole run in the recording below.

The demo from my GitHub Universe session: two agents in separate sessions, a Context Graph query, a shared simulation, and a Postman workspace in the middle.

Here’s what happens in the video:

  1. Agent A uses the api-discovery skill to ask the Context Graph which services supply the claim and patient data, and how billing connects to the decision.
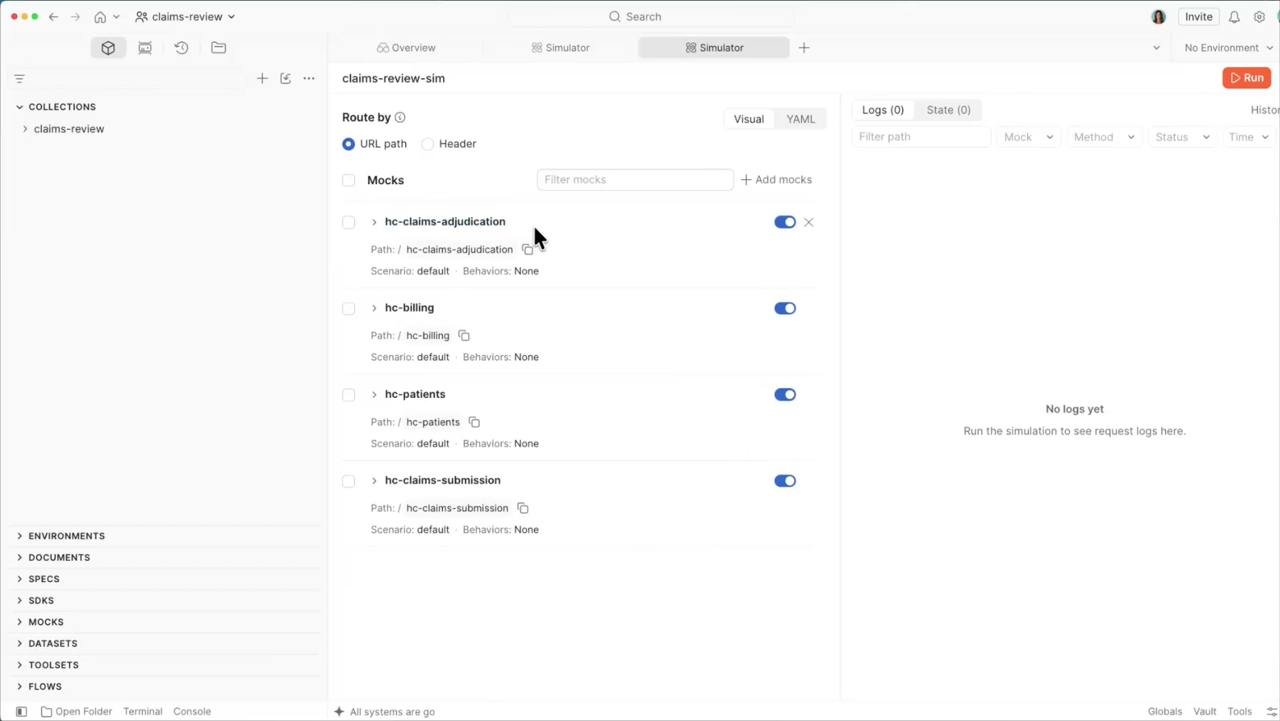
  2. It uses api-simulation to simulate those dependencies locally, so it can build and test without running every service on my machine. The Postman skills guide it through creating a collection and adding tests.
  3. All 10 assertions pass, and all four dependencies take traffic. Agent A publishes the simulation and the collection to a shared Postman workspace.
  4. I switch to Agent B in a separate session. It has no memory of Agent A’s work, so it pulls the shared assets from Postman and runs the existing tests before making any changes.
  5. Agent B’s task is an endpoint that lists claims by payer. It checks the Context Graph for the relevant APIs, then develops against the simulation Agent A already created.
  6. Agent B adds tests for the new endpoint and reruns the collection. There are now 14 passing assertions, and it pushes the updated assets back to the workspace.

In the original plan on the whiteboard, Agent B approves or denies claims and has to tell billing about each decision. The recorded run uses a smaller task, but the principle holds: Agent B asks the Context Graph which downstream service needs to know about a change, then uses the simulation to check that the right update reaches it.

The Postman Simulator showing the claims-review-sim simulation with four mocks: hc-claims-adjudication, hc-billing, hc-patients, and hc-claims-submission
The shared simulation in the Postman workspace. Four mocks stand in for the services the claims API depends on.

The moment I care about most is step 4. Agent B doesn’t have to figure out those dependencies or set them up again. The Context Graph helps each agent understand what its change touches, and the shared simulation lets the second agent build on the first agent’s work. That’s the agentic SDLC I wanted to show: discover dependencies, simulate them, build, test, and share the result so the next agent can keep going.

Try it yourself

You can run the same loop on your own services. I ran the demo in GitHub Copilot, but the Postman plugin installs into other coding agents too, so use whichever one you already have. One command installs it:

npx @postman/postman-plugin

The installer adds the plugin to each supported agent it detects on your machine, including GitHub Copilot and Claude Code. To install into a single agent, pass its ID, and check where the plugin is installed with status:

npx @postman/postman-plugin install --agent copilot
npx @postman/postman-plugin status

The plugin install guide covers the per-agent options if you’d rather use an agent’s own marketplace. Next, connect your repository to a Postman workspace:

postman init

Then sign in and ask the Context Graph a question about a service you own:

postman login
postman context-graph ask "What depends on billing-api?" --wait

Swap billing-api for one of your services. The --wait flag prints the answer inline, and without it the command returns an ask ID you can check later with postman context-graph status. From there, try this prompt in your agent, adapted from the demo:

Prompt

I’m changing the response of the orders API. Ask the Context Graph which services consume it and what relationships to account for, then build a local simulation of those dependencies. Implement the change against the simulation and create a Postman collection with checks for it.

Run the collection, publish the simulation and collection to a workspace, and start a second agent session. Ask it to pull the shared assets and run the existing checks before it changes anything. If it can do that without you explaining the dependencies again, the handoff works.

Resources

The post The Real MVP of GitHub Universe 2026: Context appeared first on Postman Blog.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Core Vitals Optimization, SSR Deployments, and Signal-First Architecture ⚡

1 Share
This week in the angular community nov 6, 2026

The Angular community is firing on all cylinders! From shaving milliseconds off your Core Web Vitals to deploying server-side rendered apps in production, mastering professional form submissions, and architecting enterprise Nx monorepos, this week’s lineup is packed with practical engineering gems.

Dive into these expert-led resources to level up your workflow:

Web Core Vitals in Angular (Spanish)

Kevin Dávila breaks down how to optimize your Angular applications for Core Web Vitals (LCP, INP, and CLS). Learn tactical patterns to enhance real-world user experience and skyrocket your performance scores.

Angular SSR Deployment (Spanish with English Subtitles)

Alejandro Cuba Ruiz, Antonio Cárdenas, and Ricardo Chavarría join forces to break down the complexities of taking Server-Side Rendering to production. Discover hosting options, pipeline setups, and critical deployment pitfalls to avoid.

Submit Like a Pro with Angular Signal Forms

Fanis Prodromou walks through how to handle form submission flows cleanly using the modern Signal Forms API. Learn how to manage loading flags, submission states, and error feedback with pure reactive ergonomics.

Beyond Clean Code: Scalable Architecture with Nx Monorepos

Fanis Prodromou also delivers a must-read architectural deep dive on Angular.love. Discover how to structure large-scale enterprise frontends using Nx monorepos, establishing domain boundaries, shared libraries, and maintainable module graphs.

Road to Angular 22: Debounce Signal

Davide Passafaro previews what’s coming on the horizon with native Debounce Signals. See how built-in reactive debouncing primitives streamline state management without relying on third-party utilities or complex operator chains.

How are you tuning your Core Web Vitals and SSR pipelines this year? Have you already started structuring your Signal Form submissions with these modern primitives?

Keep the knowledge moving. Use #AngularSparkles to share your favorite tips, benchmarks, and architectural setups with the community 👇


Core Vitals Optimization, SSR Deployments, and Signal-First Architecture ⚡🚀📊 was originally published in Angular Blog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Announcing new builds for 6 November 2026

1 Share
Hello Windows Insiders, Today, we’re releasing new Windows 11 Insider Preview builds to the Beta and Experimental channels. New builds this week Select your channel below to view its release notes: For those on other specific Windows build versions, here are today’s new builds and release notes: Experimental (Future Platforms) synthetic payload releases Insiders in the Experimental (Future Platforms) channel will begin to notice in the coming weeks that we will be releasing a new build version on a weekly basis, in-between our usual weekly Insider preview builds. These in between releases are just synthetic latest cumulative updates (LCU's), and do not contain any new features or payload. They are helping us test backend flighting and updating services. As such, we will not publish weekly release notes or blogs for these updates, but will keep track of versions in Flight Hub. 

Notable new features:

[Windows Hello]

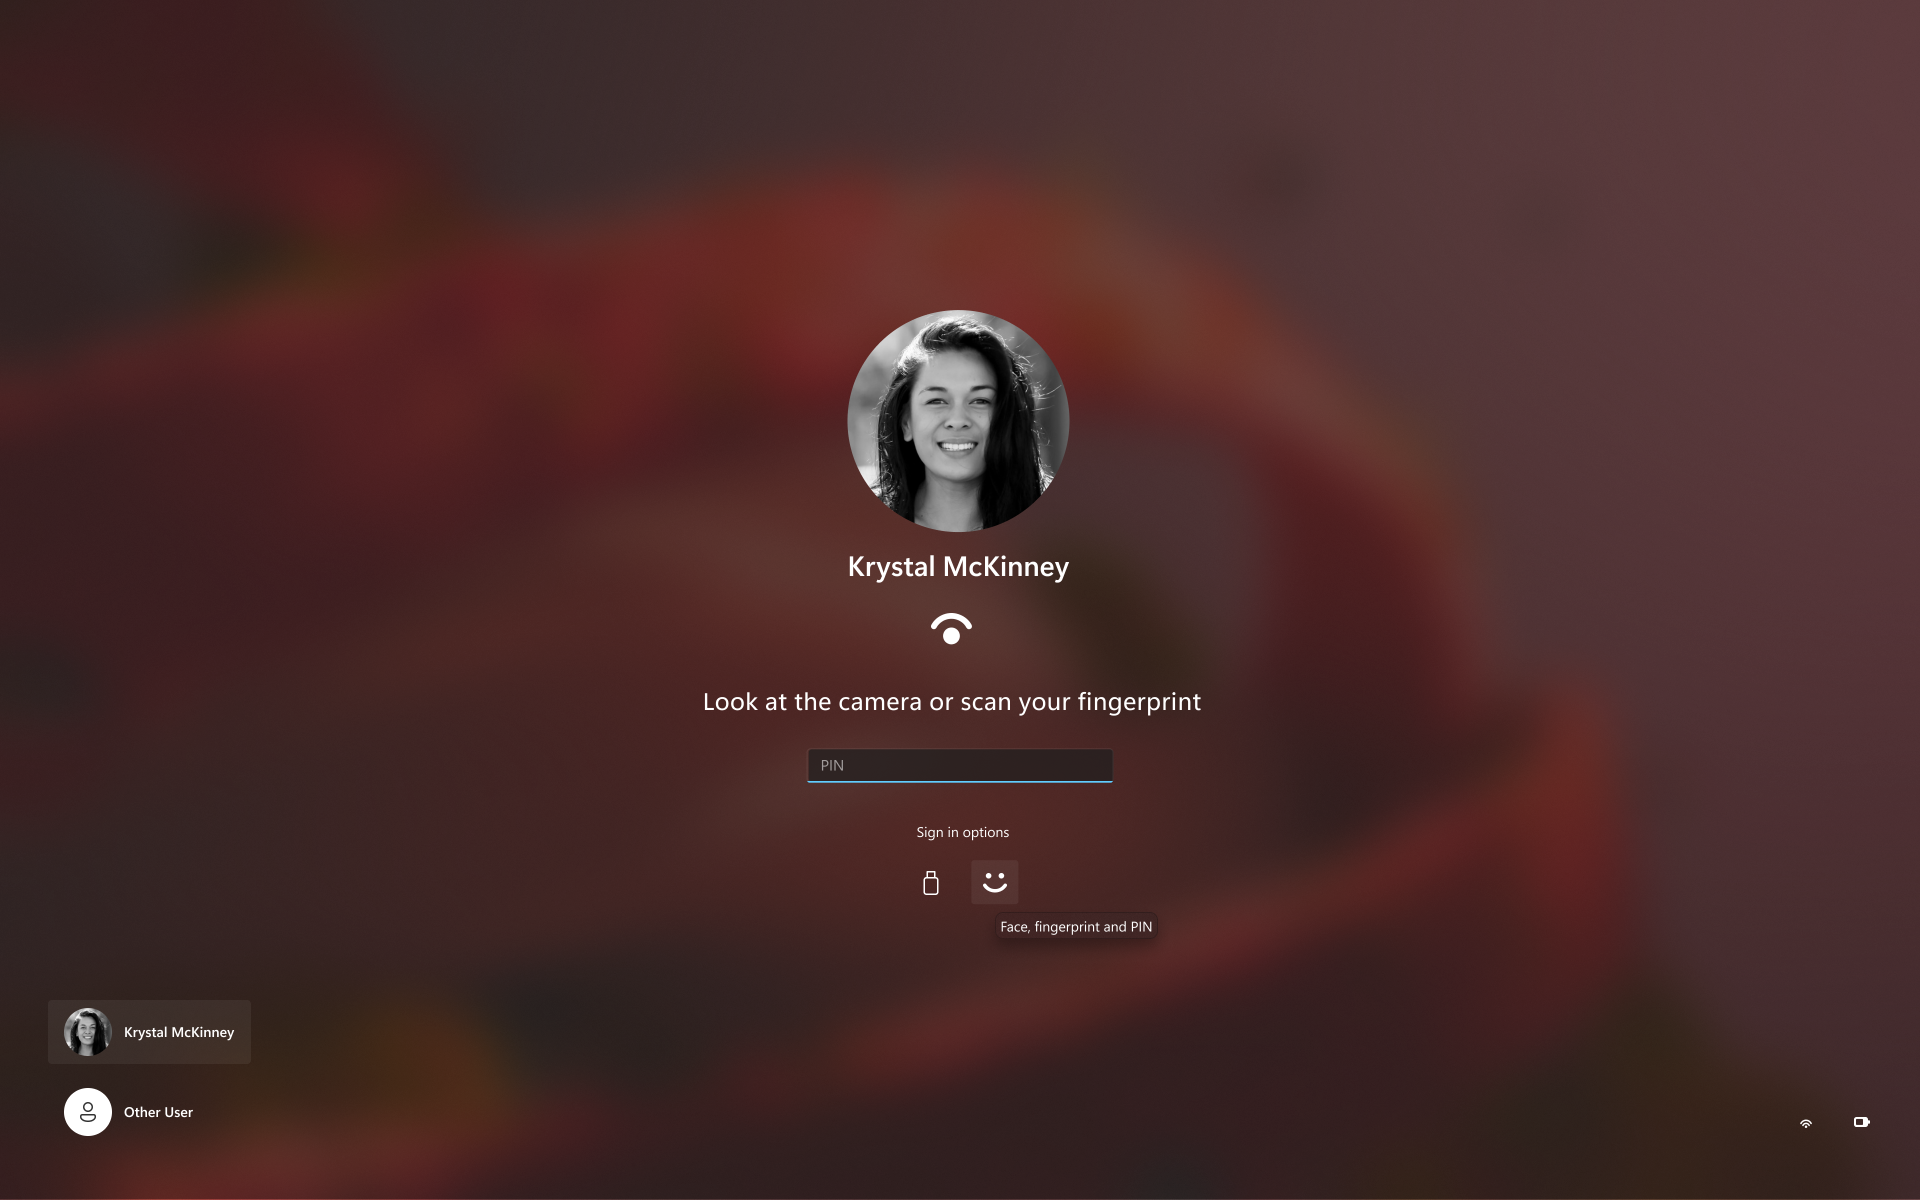
Release channel: Experimental Windows Hello sign-in improvement
  • Sign-in and unlock now behave more consistently and give clearer guidance. You no longer have to wait for face or fingerprint recognition to finish before entering your PIN. Use whichever method works first. At certain times, such as after a restart, you'll need your PIN first. After that, biometrics work as usual.
[caption id="attachment_179264" align="aligncenter" width="1920"]Sign in with face, fingerprint, or PIN, whichever works first. Sign in with face, fingerprint, or PIN, whichever works first.[/caption] Thanks, Stephen and the Windows Insider Program team
Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories