Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
161385 stories
·
33 followers

Software Factories, Light and Dark

1 Share

The following article originally appeared on Addy Osmani’s blog and is being republished here with the author’s permission.

A software factory harnesses loops at scale. You can run the loop with humans in it (light factory), trading judgment and concentration against speed and breakage. Or you can ignore the humans (dark factory) and let those agents scope, build, and ship code without anyone reading the details. If people stop reading, though, they’ll stop understanding your software. Your hardest job now is knowing which checks to build and how much autonomy to delegate.


This idea of the software factory is a term that dates back to Bob Bemer’s paper, “The economics of program production,” given in 1968. For half a century, many have dreamed of a world in which software is a repeatable and instrumentable production process (analogous to stamping out car parts in a factory) rather than the isolated craft of individuals. Historically, this dream has generally (although not universally) fallen flat, in part because of the difficulty of stamping out ideas.

But in the last two years, things have changed dramatically enough that now it makes sense to take a fresh look at the old dream. And since some subtleties can easily be glossed over, it’s worthwhile to be somewhat precise about exactly what’s really new and different, and what may be recurring traps, dressed up as new opportunities.

Dex Horthy, co-founder of HumanLayer recently gave a great talk at the AI Engineer World’s Fair called “Harness Engineering is not Enough: Why Software Factories Fail.” worth checking out on this topic.

The loop is the atom. The factory is the loop at scale.

Structure is everything, and it all starts with small units. The whole stack is really three concepts layered on top of each other: the loop, the harness, and the factory.

A loop is one agent doing a single job on repeat: gather context, take an action, check the result, and go again until some condition is met. It is the smallest unit of agentic work, and everything above it is just loops stacked on loops.

The point of loop engineering is that you stop prompting the agent turn by turn and instead design the small system that prompts it for you.

A harness is the walls around a loop: the sandbox it runs in, the tools it can reach, the memory that survives between runs, and the gates that decide what “done” means. The loop is the behavior; the harness is the environment that behavior runs inside.

Hand a raw model no harness and it will happily spin forever. The harness is everything around the model that makes it useful and safe to run.

A software factory is many harnessed loops running at once, fed by a queue of work and drained through a review gate into production, with humans owning the whole thing from above. It isn’t a bigger agent; it’s an org chart made of loops.

The final paradigm shift is moving from writing code to building and running the factory that writes it. The unit of work shifts up a level, to the loop, the harness, and the flow between them, rather than the individual code diff.

The factory, drawn

The central slide Dex spent most time on was brilliant because it’s a clarifying wiring diagram that visualizes what otherwise is an obvious loop. Here’s my take on it:

The agentic software factory as a closed loop
The factory is a closed loop: Intent and production signals feed a queue, the harness builds, automated checks and review gate it, deploy ships it, and monitoring turns production back into signals.

Intent flows from the vision of engineering leadership and directly from engineers into a queue of work. Signals driven by incidents and user requests drive the same queue. The harness picks an item from the queue and builds a change for it. Beyond the harness, automated checks make changes safe enough to let into production. These automated checks run at once without any conscious involvement from engineers, thanks to CI, tests, static analysis, and scanning of all kinds. The review gate is the only decision point here. After approval, changes are deployed and monitored in production, with monitoring data feeding back into the signals that kicked the loop into motion to begin with.

By and large, every box in this diagram is almost zero cost: generation, tests, scanning. They all run at scale for negligible cost. There’s only one expensive box that proves stubbornly resistant to scaling, and that’s the review gate. That shiny amber box is “judgment,” and where the crux of the argument about whether we can make development faster and more frequent resides.

Why we call it “dark”

A dark factory runs with the lights physically off because the only things on the floor are machines, which don’t need light to see. A dark software factory operates similarly, as code ships that no human has read and is verified only by other machines.

The image is borrowed from manufacturing. Its origins are physical rather than digital, rooted in facilities where the lights are turned off and the work is carried out by robots. FANUC in Japan has been running lights-out factories of this sort since 2001. Xiaomi, in 2024, opened a heavily automated dark factory of its own. What these have in common is a product assembled and shipped without a single human having read any of it. The “dark” comes in when that act of reading is removed from the process.

I’m not borrowing the concept for its vibe or as an insult. For all its creepy buzz, “dark” here is a simple physical claim: the original factory floor, but without light. In software, the floor is the diff. Whoever wrote the diff, whoever reviewed it, whoever shipped it, those humans are gone, and what remains is a diff verified only by the machines that built it.

This is a surprisingly easy thing to do, at least at first. It’s easy because that missing review step gets in the way of everything. Its absence makes your perception of your team’s vertical throughput seem suddenly and radically higher. It feels as if you’ve broken the sound barrier. For all its apparent ease, it’s harder than it seems to survive those dark workflows, with all their buried costs.

Harness engineering is not enough

The harness of orchestration, sandboxed prototyping, and tool calling as models interact with the world and each other will become increasingly powerful and effective. However, there’s an inherent in-model failure in trying to keep up with codebase quality over the long game and through additive changes, and I think there’s good reason to believe that models alone will ultimately lose that battle against comprehension debt.

Comprehension debt is the widening gap between how much code exists and how much any human still understands. A dark factory doesn’t pay it down; it takes it on as fast as it can, with the tests green the whole way.

This is an important distinction because models do well at some tasks. But for anything that isn’t an immediate change to a small part of a codebase, especially in a complex brownfield system, model-only automated coding faces an insurmountable obstacle. Weekend toys and side projects are alike in that a few months of development cycles is usually enough to get things in working order, or at least close enough. But an enterprise system that has been under development for a decade or more is a different beast; it has to be maintained, in a professional environment at a professional pace. Three to six months into a project, you’re already drowning in unread code. That kind of environment, and especially the constraints enforced by production code, would make even a powerful agent do poorly, all of it in contrast to the vibe-coding enjoyed by developers working on weekend toys.

Dex reports from experience that this is a major failure, so much so that it required painstaking manual debugging to pinpoint. This came from running a fully automated code factory for about four months, during which no human looked at the code that was written. Underlying the experience is a tradeoff between two conflicting metrics. One is maximizing token utilization, the number we currently treat as progress. The other, which it quietly minimizes, is the amount of the system any human participant still understands at any moment.

Where the dark factory truly shines is in its ability to burn through pristine code while the tests stay green. The ultimate reckoning, when it comes, will not be a dramatic “it all goes sideways” moment. It will be quiet and late.

The bottleneck was never generation

The fundamental constraint in a software factory isn’t how much code we can churn out, it’s how quickly we can verify it.

Back pressure is the rule that you can only hand a loop as much autonomy as you can cheaply and reliably verify, and not one inch more. Verification, not generation, is the real constraint on a factory.

Because unbounded generation capacity is in perpetual tension with the finite, non-scaling resource of human attention, the core problem is the gap between cheap generation and bounded review. Look at the funnel: As long as the neck representing verification doesn’t widen, it’s going to back up. As Dex points out, volume alone isn’t the problem: What we’re really suffering from is a surplus of bad PRs. When you’ve got high volume without trustworthy gates, manufactured defects are unavoidable. This is just back pressure again: Autonomy can’t expand beyond what can be cheaply and reliably verified.

The second-order problem is why improving the model shouldn’t automatically close the gap between what it can generate and what can be verified. Training on well-architected systems is an arguably more difficult proposition than passing simple tests: remember, the cost functions measuring architectural excellence aren’t measured in seconds or even minutes, but in months and years. Tidy gradients are functionally impossible to compute, so a system expecting crisp, instant evaluation of complex design decisions isn’t going to be trained on good examples.

Unbounded generation meets a narrow verification gate
Generation is a wide mouth; verification is the narrow neck. Speeding up the mouth just deepens the pile at the neck.

Turning the lights back on

A lit factory is the same pipeline with the lights left on where judgment lives. Agents still do most of the building, but a human reads what comes out before it ships, keeping the lights on wherever a wrong call is expensive.

The lit version doesn’t tack review onto the end but moves the point of human judgment upstream, to the product, the design, and the architecture before an agent starts a loop.

One great thing about that upfront hour is that it leads to fewer implementation hours. It turns a long, frustrating code review into a quick read of a two-hundred-line plan. You get to review a decision before it’s built, so later you aren’t chasing through two thousand lines of generated code to find out what the decision even was. Some decisions are expensive and long-lived enough that you’d want a person in on them early, before the cost compounds. Of course, there are still times you look at diffs, even when you’ve spent time up front.

You might be thinking that all sounds unglamorous. You’re right. The safety net is made up of perfectly ordinary architectural practices we’ve always known about and mostly ignored: good types and method signatures so that mistakes are caught by the compiler instead of in production; test seams where we can pin behavior and make change observable; laying out the code so the next reader, human or model, knows where to find the thing they care about; keeping call stacks short and legible; keeping component boundaries well defined so a change doesn’t have a huge blast radius; and dependency injection so we can swap out one piece for another. None of it is new. We’ve always said we care about good architecture. But now that we’re using automated coding agents, that architecture is finally doing a second job as a cheap and hard-to-fake safety net against the mistakes the agent will make.

That safety net has to live outside the model because the model won’t supply it. The coding agents that feel most capable, Claude Code and Codex among them, are reinforcement-trained against their own harness and tools: fluent with all the tools and idioms of the trade, but not with things like long-term maintainability. The deliberate architecture we’ve always talked about is the tool that catches that debt, and the investment we make in it is us buying back our autonomy. Put that together with safe infrastructure, and there are some tight, low-risk loops you can run unattended. Horthy described one in a recent post: A nightly GitHub Actions cron that fixes exactly one anti-pattern, a lint violation or a needlessly optional prop, commits, and opens one small pull request, all on its own, so the team wakes up to a slightly better codebase and a diff short enough to read. But for loops with high enough stakes, you don’t want to risk waking up to a broken auth system, billing engine, or public API contract. Keep the lights on there, and trust that a person with judgment and a real working knowledge of the system will catch the mistake.

What earns a loop the dark

This rule applies whether you call it back pressure, verification, or the light switch.

A loop can earn itself fully automated status only if the check is cheap, runs at high frequency, and relies on something that can’t be easily faked out. Green-or-red oracles, type gates, property tests, and a review agent coupled with a real rubric all fit. You also need the oracle to answer immediately and not drift over time. When done can be proven not just by you but by a machine, you’ve reached automation.

Short loops are easier to verify than long ones. Dex’s rule of thumb: An agent holds up for three to ten steps, then starts losing the thread past twenty. The reason is context accumulation. The more the agent drags along, the more likely it is to wander off. When a loop is short, verifying it is cheap. Sprawling loops hide mistakes in the corners, which is another way of saying they never earned lights-out status.

Keeping the lights on is the opposite case. A loop needs to be reviewed if a wrong answer is expensive and only a person can catch it. Subtle production bugs that can’t be caught by tests, large blast radii, and a decision that’s going to shape the work of a year or more all qualify. In those cases, human judgment does not leave the software; your attention is the costly, essential part.

The danger is forgetting to flip each switch and just setting all of them to the same mode. All dark, and you’re stuck tearing everything down four months later. All lit, and no one can get reviews done in time and you’re stuck in a gigantic bottleneck. The hard, skilled job is deciding where to put each switch.

Loops, graphs, or state machines?

When you hand an agent a task, you’ll likely build a graph around it, whether you call that graph a finite state machine or a set of conditionally linked service calls. It’s a framing where the software isn’t just following some abstract rules but a structured workflow: Every node is an explicit step, and every edge between nodes is an explicit condition. That sounds like a lot of structure, but most of it’s already there in any software, since any code can be expressed as a control-flow graph. So the only real novelty is that an agent insisting on autonomy is really just walking around a particular graph, and its freedom is constrained to the inside of a node. And here’s the part people forget, which Dex wrote down a year ago: software was always going to have that structure. There’s a reason we used to draw programs as flow charts. The genuinely new move was trying to throw the diagram away, leaning on a loop where the model picks the path tool call by tool call, until it declares itself done. That felt like liberation, right up until it met a ten-year-old codebase, and the discipline everyone is now rediscovering, owning your control flow, is really just walking the graph back around the loop. So the question of whether we should shift from loops back to graphs is almost an admission that we needed the flowchart all along.

Here’s what it looks like in practice. Take a bug to fix. As a pure loop, you sit down and think: figure out what’s wrong, change some code, run the tests, see what happens, and if that round doesn’t kill the run, loop back and start again. The whole journey is decided as you go, which problem you chase, the exact code you change, which tests you run and in what order, whether you run tests at all, and whether you try again or declare victory. As a graph, the first thing you do is map out what should happen. Reproduce the bug or go ask for more information, find the cause, try a fix, run the tests, and let a failing run route back to the fix while a passing one goes on to review, where only an approval reaches done. The agent is still clever inside each box; it just can’t wander off the paths you sanctioned. Santi laid this out with a diagram that makes the difference obvious.

The real appeal of that graph, of course, is that it’s back pressure drawn as a diagram. You give up some of the agent’s freedom and get mandatory checks and legible failure points in return, so when a run dies you can point at the node that killed it. It’s the same instinct behind Dex’s blunt line that most so-called agents aren’t very agentic at all, “mostly deterministic code, with LLM steps sprinkled in at just the right points.” And this isn’t just an artifact of how people happen to be building things right now: you can see the pattern in LangGraph and LlamaIndex Workflows, in Jerry Liu’s hybrid workflow-graph-over-agents with an outer loop that grows parts of the graph as it runs, and in David Khourshid’s reminder that this is really just state machines and the actor model turning up in new clothes.

One clarification, because the term is badly overloaded: when I keep calling this a graph, I don’t mean a knowledge graph. I mean a predefined directed graph of how the work should flow, conditional edges and all, giving the loop a shape you can actually trust.

Where the human actually goes

Notice that the person never left the factory. They moved.

I think engineers need to increasingly own the outer loop. The agents can investigate a bug, write up the diagnosis, implement a fix, run the tests, and write up a report. That’s the execution of the inner loop, and they can do it as efficiently as anyone. But that was never the job. The bits you own are what I’d call the outer loop: Decide whether it’s the right way to address the problem, verify that the diagnosis and implementation are sound, approve the change, and carry the consequences of being wrong. The boundary between the two loops is evidence, the diffs, the tests, the logs, and a brief explanation that connects them. Types, seams, and rubrics make it possible to oversee all this without doing a lot of work for every change.

I think it’s useful to put it this way: you’re not down on the line writing changes any more; you’re up at the end of the production line designing it and guarding the gate. There’s a lot you can do to make the model better and the harness more capable, but I’ve observed that identifying problems that are expensive in the long term is not typically something you can automate away. The core thing that’s still the job is to exercise human judgment better than any flow of paper and computing power.

Robots are fine operating in the dark, but humans need to see what they’re doing. If everything on the factory floor is dark, and you can’t see anything, and you can’t even find the light switch, that’s where the danger is.


Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Should you read the code, is RAG dead, and did Skills kill MCP?

1 Share

Hot takes turn complicated topics into one confident sentence. That makes them great for engagement, but not necessarily for understanding.

At the surface level, they do not matter much. You agree, disagree, repost, argue for a few minutes, and move on. Sometimes the take is directionally right. Sometimes it is complete nonsense.

The value of hot takes is in what happens when you stop reacting and start pulling them apart. Under what conditions is this true? What context is missing? What assumptions does it make? What changes when you apply it to real work?

That is where the depth is. A good hot take gives you something sharp enough to question. The questions are where you find the useful ideas.

We explore all this and more in the latest episode of the GitHub Podcast!

Not ready to dive in yet? Here are a few of the common AI hot takes we discussed and what we can get from them.

Hot take #1: “You do not need to read AI-generated code”

Yes, you do. You are still responsible for the code.

But that does not mean every generated line needs the same level of attention.

A production authentication refactor deserves a different review process than a CSS experiment. A codebase you have maintained for 10 years steers your instincts differently than one you opened this morning. Pretending every change carries the same risk is not rigor. It is just a bad use of time.

A simple rule: review until you can explain and own the outcome.

Sometimes that work starts before the agent writes anything. You read the current implementation, map the dependencies, identify edge cases, and make a plan. By the time the first implementation exists, you already understand what it should do and where it could go wrong.

Other times, the generated code itself needs most of your attention. You inspect the error handling, permissions, data access, performance, accessibility, and tests.

AI moves the effort around. It does not make the work disappear.

The actual skill is knowing where the risk lives.

Hot take #2: “Companies will not hire you if you do not use AI”

The reality is a little more nuanced. More teams are asking candidates how they use AI. That makes sense. These tools are becoming part of software development.

But no one thinks every developer needs the same workflow, the same tools, or the same level of enthusiasm.

The stronger signal is judgment.

Can you explain when you use AI and when you work manually? Can you describe how you review generated code? Can you talk honestly about speed, quality, security, and maintainability? Can you change your process as the tools change?

If a company is building AI products or uses AI heavily in its engineering workflow, refusing to touch AI may make you a bad fit. That is not controversial. But total dependence and total refusal are rarely good answers.

The better answer is a clear explanation of how you work, what you trust the tools to do, and where you keep yourself in the loop.

That kind of fluency is becoming part of the craft.

Hot take #3: “Skills killed MCP”

No. They solve different problems.

The Model Context Protocol gives agents a standard way to connect to tools and data. That standard matters when you want systems to work together reliably. Agents need structured ways to call tools, fetch context, and take action.

Skills are closer to packaged expertise. A skill can explain how a team works, how a project should be changed, how a tool should be used, or which conventions matter. Since skills are often written in Markdown, people can read them too. That readability is part of their value.

MCP can provide access. Skills can explain how to use that access well.

You do not need to pick a winner. Use standards for shared interfaces. Use skills for context, process, and best practices.

The combination is much more interesting than the argument.

Hot take #4: “RAG is dead”

RAG is not dead. It is just not the newest thing people want to post about.

Retrieval-augmented generation gives an AI system relevant information outside the model’s training data. That can include documentation, support history, product details, internal knowledge, or codebase context.

Without good retrieval, the model has to rely on what it already knows or spend extra time searching for context. That wastes tokens, slows down the work, and makes incomplete answers more likely.

Good retrieval helps the model start closer to the answer. It narrows the search space and grounds the response in information that actually matters.

Agents, skills, MCP, and RAG can all exist in the same workflow. An agent might use MCP to access a tool, follow a skill for project-specific instructions, and use retrieval to find the right supporting context.

These things are not fighting each other. Treating them like they are misses how people actually build with AI.

Hot take #5: “If you need to fine-tune a model for your codebase, your code is bad”

There are valid reasons to fine-tune a model. Still, modern models have seen a huge number of common frameworks, patterns, naming conventions, and architectures. If a model cannot make sense of your codebase, there is a decent chance a new teammate will struggle too.

AI is becoming another pressure test for maintainability, alongside code review, testing, onboarding, and the poor person debugging this six months from now.

Clear structure helps. Consistent naming helps. Readable tests, useful abstractions, and current documentation help.

Those things make a codebase easier for an agent to understand, but more importantly, they make it easier for a person to review, debug, and extend.

AI-assisted development rewards codebases that make their intent obvious.

That is a good thing.

Real work is more interesting than the debate

AI will keep producing strong opinions because the tools are changing quickly, and we are all still figuring out our workflows.

You do not need to pick a permanent side in every debate.

The better response to an interesting take is not another take. Test the idea. Build something. Document what happened. Give everyone something real to learn from.

Pollinations AI is doing that by experimenting with a generative AI platform where contributors can earn credits, called pollen, by improving the project. People can open and solve issues, contribute models, and complete quests. The project raises real questions about incentives, quality, scale, and what open source contribution could look like when AI lowers the barrier to participation.

Avian Visitors is doing it in a completely different way. It is a build log for a bird-listening e-ink display that turns birds visiting an apartment balcony into changing wall art. It combines a microphone, Raspberry Pi, e-ink screen, 3D-printed parts, generated bird images, and thoughtful documentation.

These projects do not settle every AI debate. They do something more useful: they create evidence, expose tradeoffs, and give other people a place to start.

Read enough code to own the result. Build enough AI fluency to explain how you work. Use MCP when a standard interface helps. Use skills when context and process matter. Keep RAG when grounded information makes the system better. If your code confuses both people and models, treat that as a maintainability problem.

Most importantly, do something with what you learn.

Subscribe to the GitHub Podcast so you never miss an episode!

The post Should you read the code, is RAG dead, and did Skills kill MCP? appeared first on The GitHub Blog.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Making Local AI Smarter and Faster

1 Share

We want local coding agents to be smart and fast, with the ability to understand a codebase, do useful work, and finish tasks without long waits. This Junie Local update makes it practical to use a more capable model on your own machine.

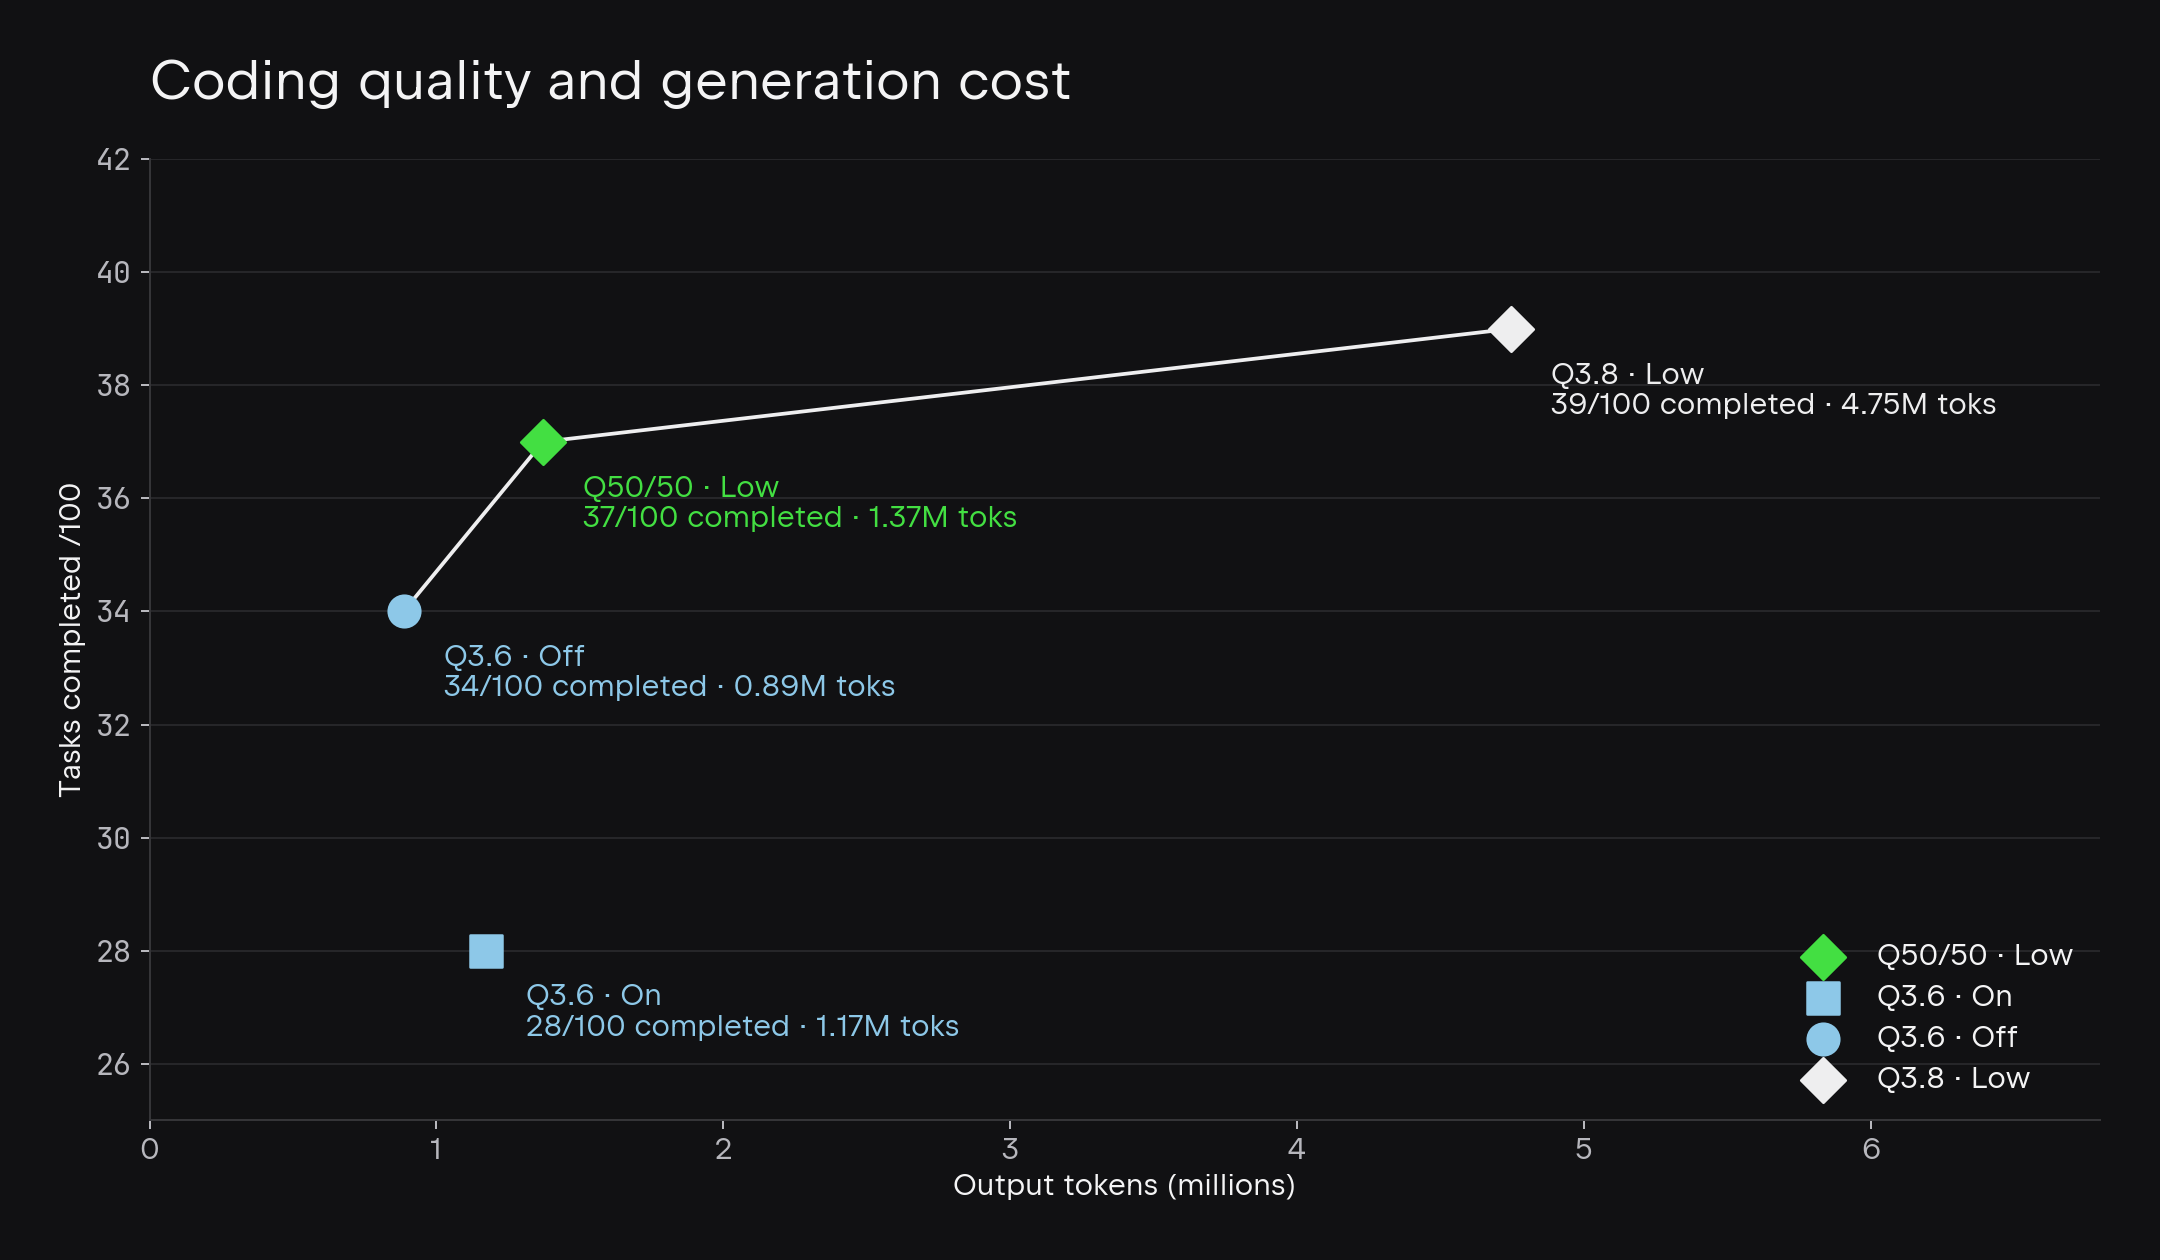
In the first release, we had to choose between two versions of the same model. With reasoning disabled, Qwen3.6 was fast enough to be usable on a laptop. Qwen3.8 completed more tasks, but it needed reasoning enabled to work reliably, and that made tasks take roughly four times longer. We picked speed.

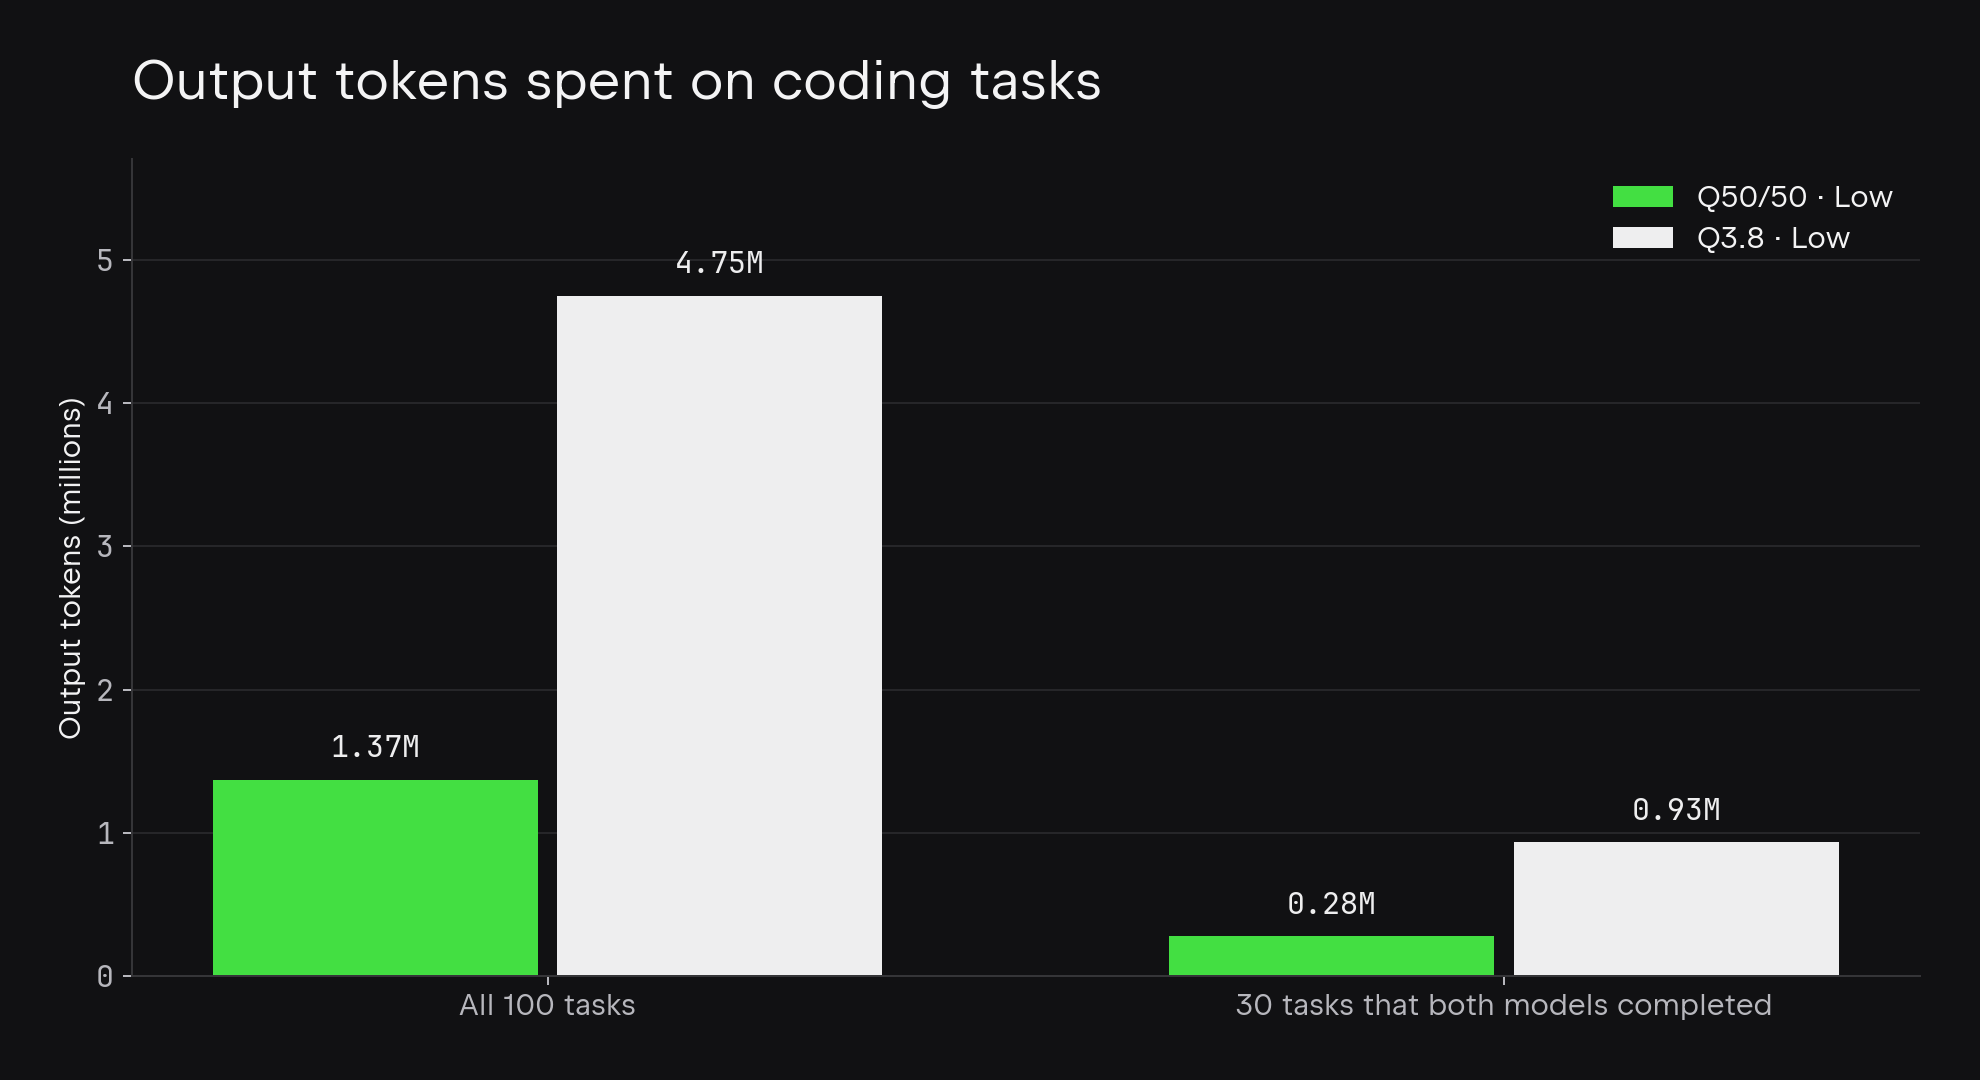
This update is our attempt to remove the need to choose. We built Qwen3.8-3.6-27B-blend by merging the two in equal proportions. In our coding evaluation, it completed more tasks than Qwen3.6 while generating 71% fewer output tokens than Qwen3.8.

In this post, we’ll show where the new model improves coding results, how we made it run efficiently, and what we learned while testing it. We’re also bringing Junie Local to more machines with experimental NVIDIA support on Windows.

A smarter model that thinks less

In our 100-task internal coding benchmark, the new model completed 37 tasks, compared with 34 for Qwen3.6 with reasoning disabled. It came close to Qwen3.8’s 39 solves while generating 71% fewer output tokens.

Are we actually saving tokens?

One possible explanation for the token savings was just that the blend model spends fewer tokens when it gets stuck. To test that hypothesis, we compared token use for the 30 tasks that were completed by both Qwen3.8 and the blend model. On these tasks, the blend generated about 70% fewer tokens – 279K for the blend versus 935K for Qwen3.8. It used fewer tokens on 29 of those 30 tasks, further proving its token efficiency. 

A simple merge worth testing

We started with a simple experiment. Since Qwen3.8-27B is based on Qwen3.6-27B, and they both share the same architecture, we simply merged their weights in equal proportions. This produces a single 27B model without any additional post-training. 

However, this simple blend was already a surprisingly useful improvement. The early results were better than we expected, so we focused on evaluating this model across more benchmarks and tasks. That evaluation gave us enough confidence to make it the model for this release while the other experiments continue.

There are many ways to reduce reasoning times, including distillation, reinforcement learning, and more elaborate model merging methods. We are continuing a wider set of model and runtime experiments, and more of that work will appear in future Junie Local releases.

Multiple benchmarks, multiple runs

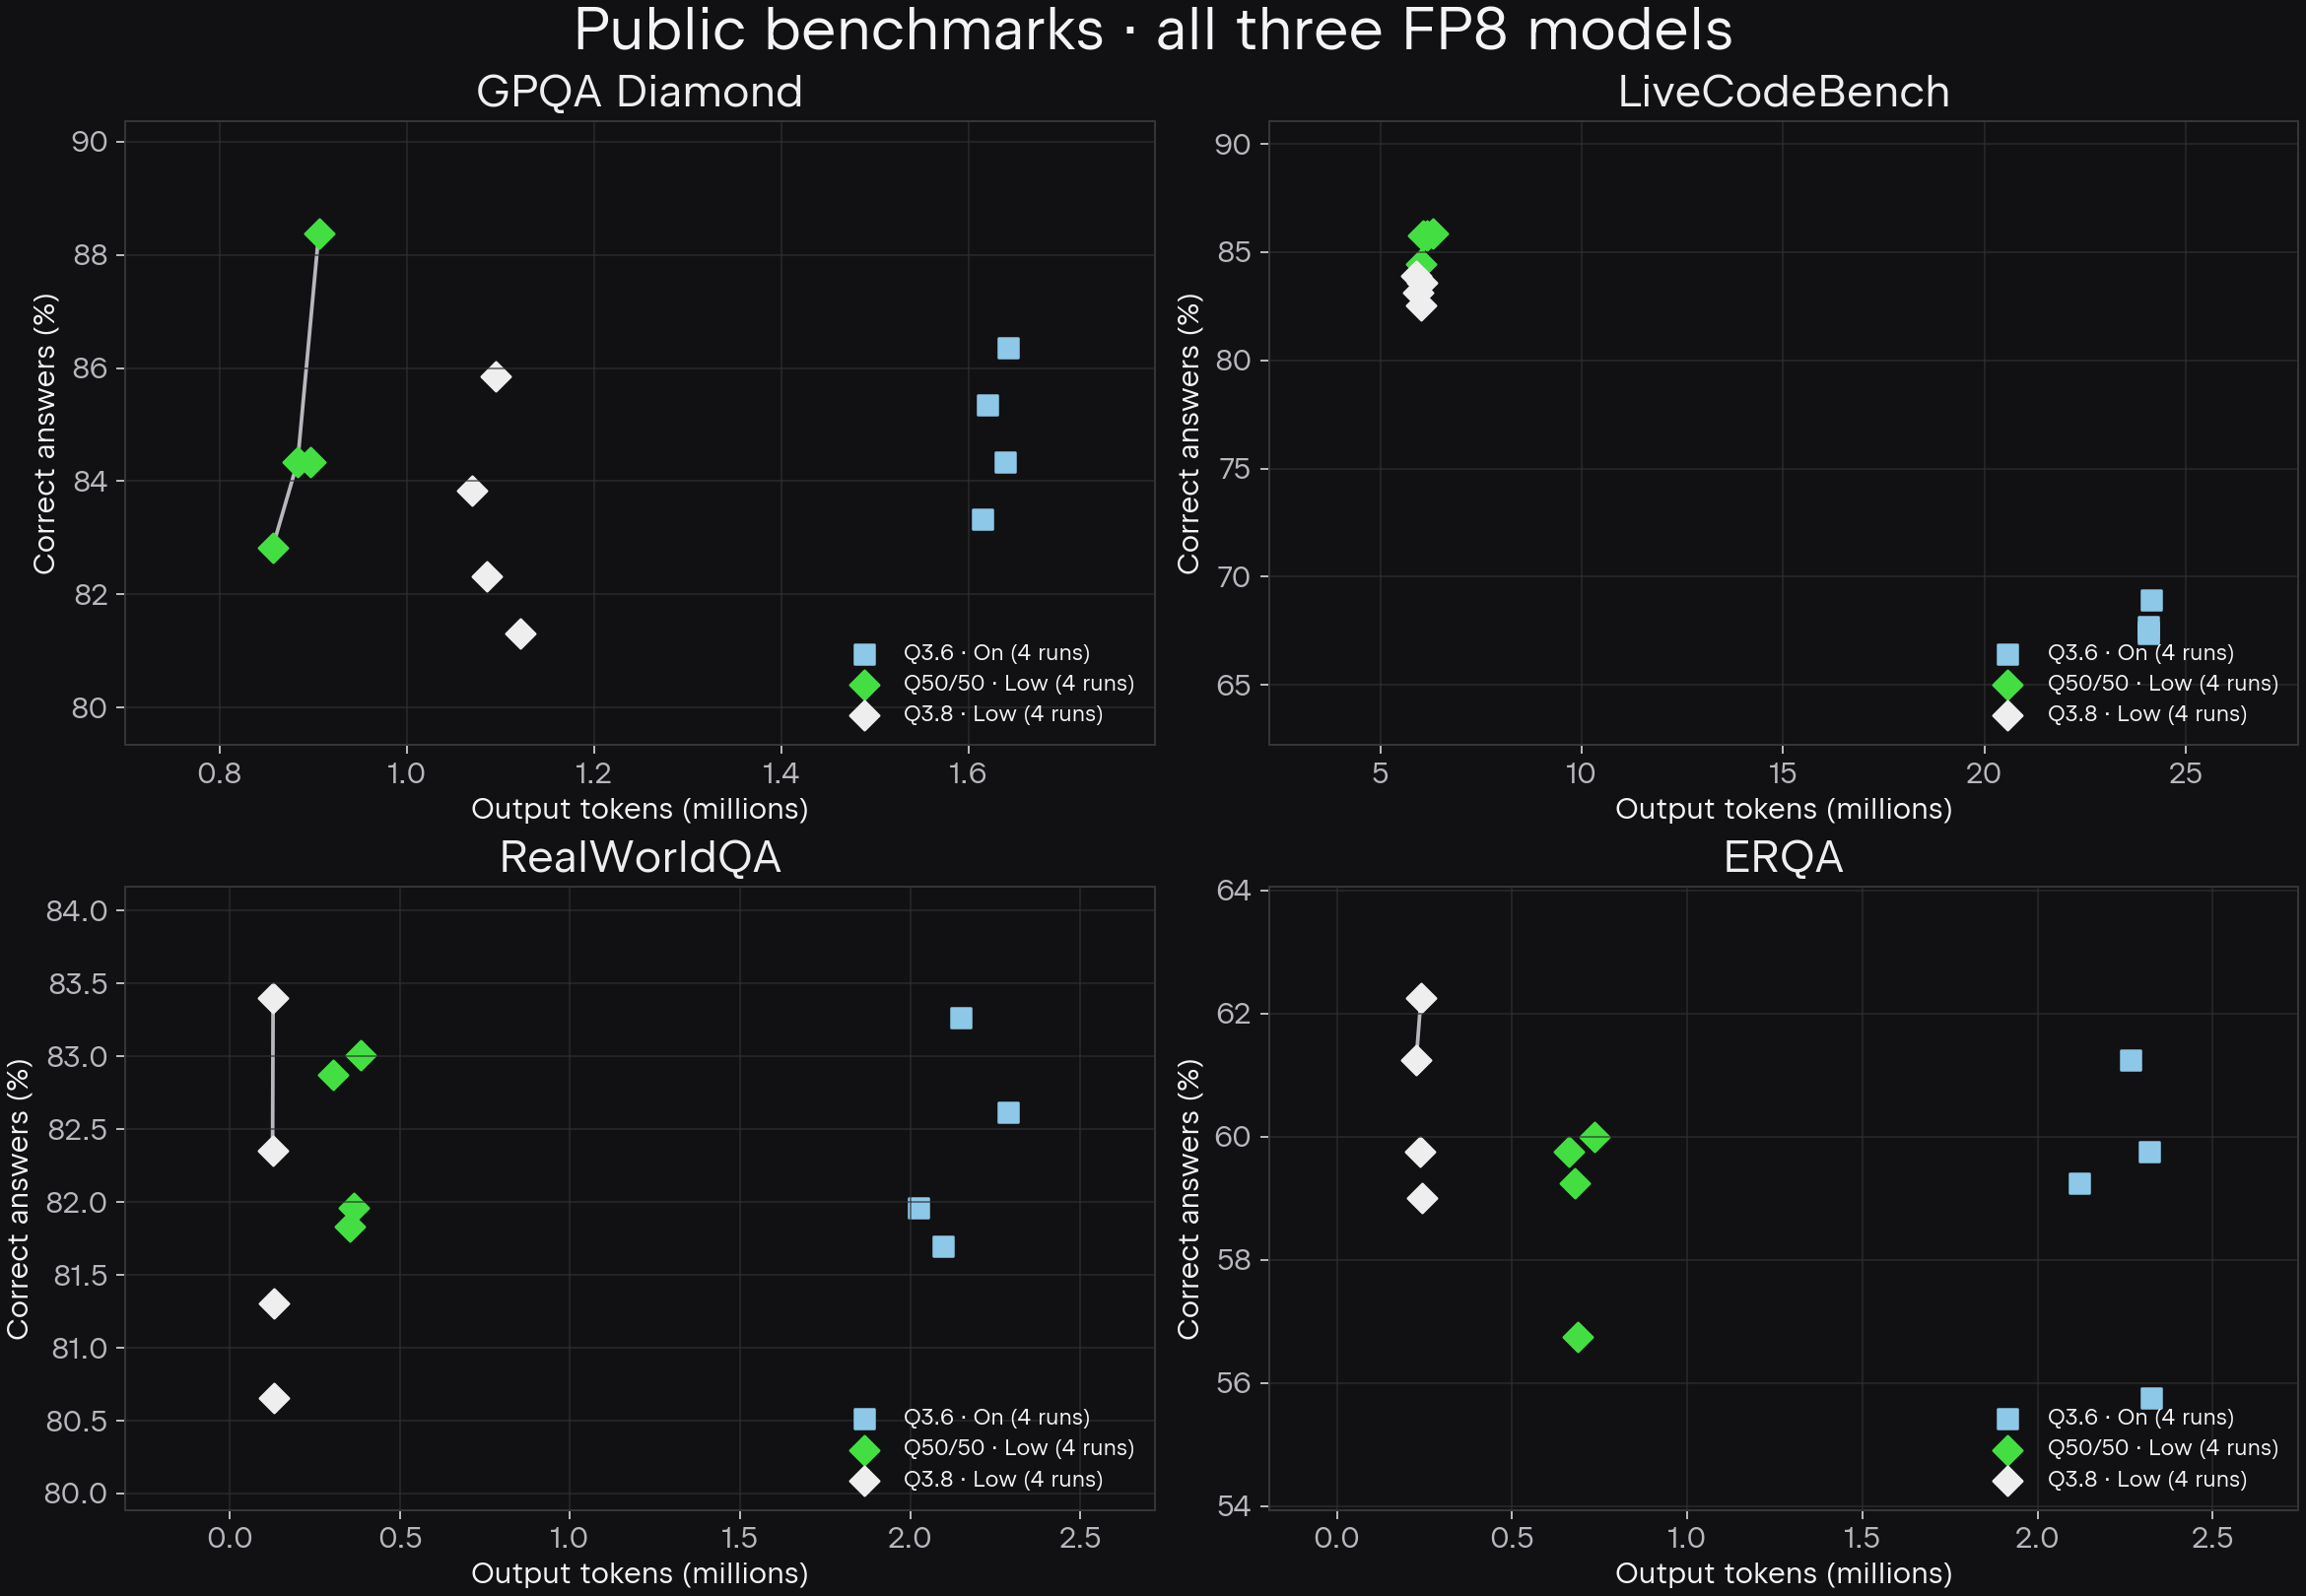
To see how the new model performs beyond our agentic coding tasks, we evaluated it on multiple public benchmarks. Repeating the evaluation runs lets us see which tasks are consistently completed, how much variance there is between runs, and whether a result depends on one favorable sample.

Across four LiveCodeBench runs, the blend model averaged 85.47% correct answers, compared with 83.29% for Qwen3.8, at a similar output cost. Qwen3.6’s four complete passes averaged 67.87% and used about 24.1 million output tokens per pass, versus approximately 6.14 million for the blend model.

The visual benchmarks expose a different tradeoff. The blend model used substantially fewer tokens than Qwen3.6 with thinking enabled, but more than Qwen3.8. We checked identical questions, images, and generation settings, and we found that the extra tokens were almost entirely due to the blend model spending more time on reasoning.

Further work

The blend can still overthink when it struggles to find a solution. If Junie keeps revisiting the same approach without new evidence or useful tool results, we recommend interrupting it and restarting it with a narrower goal. 

There is also room to make successful reasoning more efficient. Across four identical benchmark runs, the length of CoT varied significantly. Picking the shorter correct trace would have cut token use by 24.5%, which suggests that shorter successful paths exist, and we could potentially teach the model to take those paths with zero performance loss.

Making the model run efficiently

The model determines how much text Junie generates, while the runtime determines how quickly that text reaches you and how much memory it needs. Our goal is to improve both.

Speculations about speculative decoding

Junie Local already uses multi-token prediction (MTP). A small subnetwork called the MTP head proposes multiple tokens that the main model checks in parallel. Correct proposals result in more output tokens per pass. We want to make more correct proposals, but this also adds GPU work, so it does not always mean faster generation.

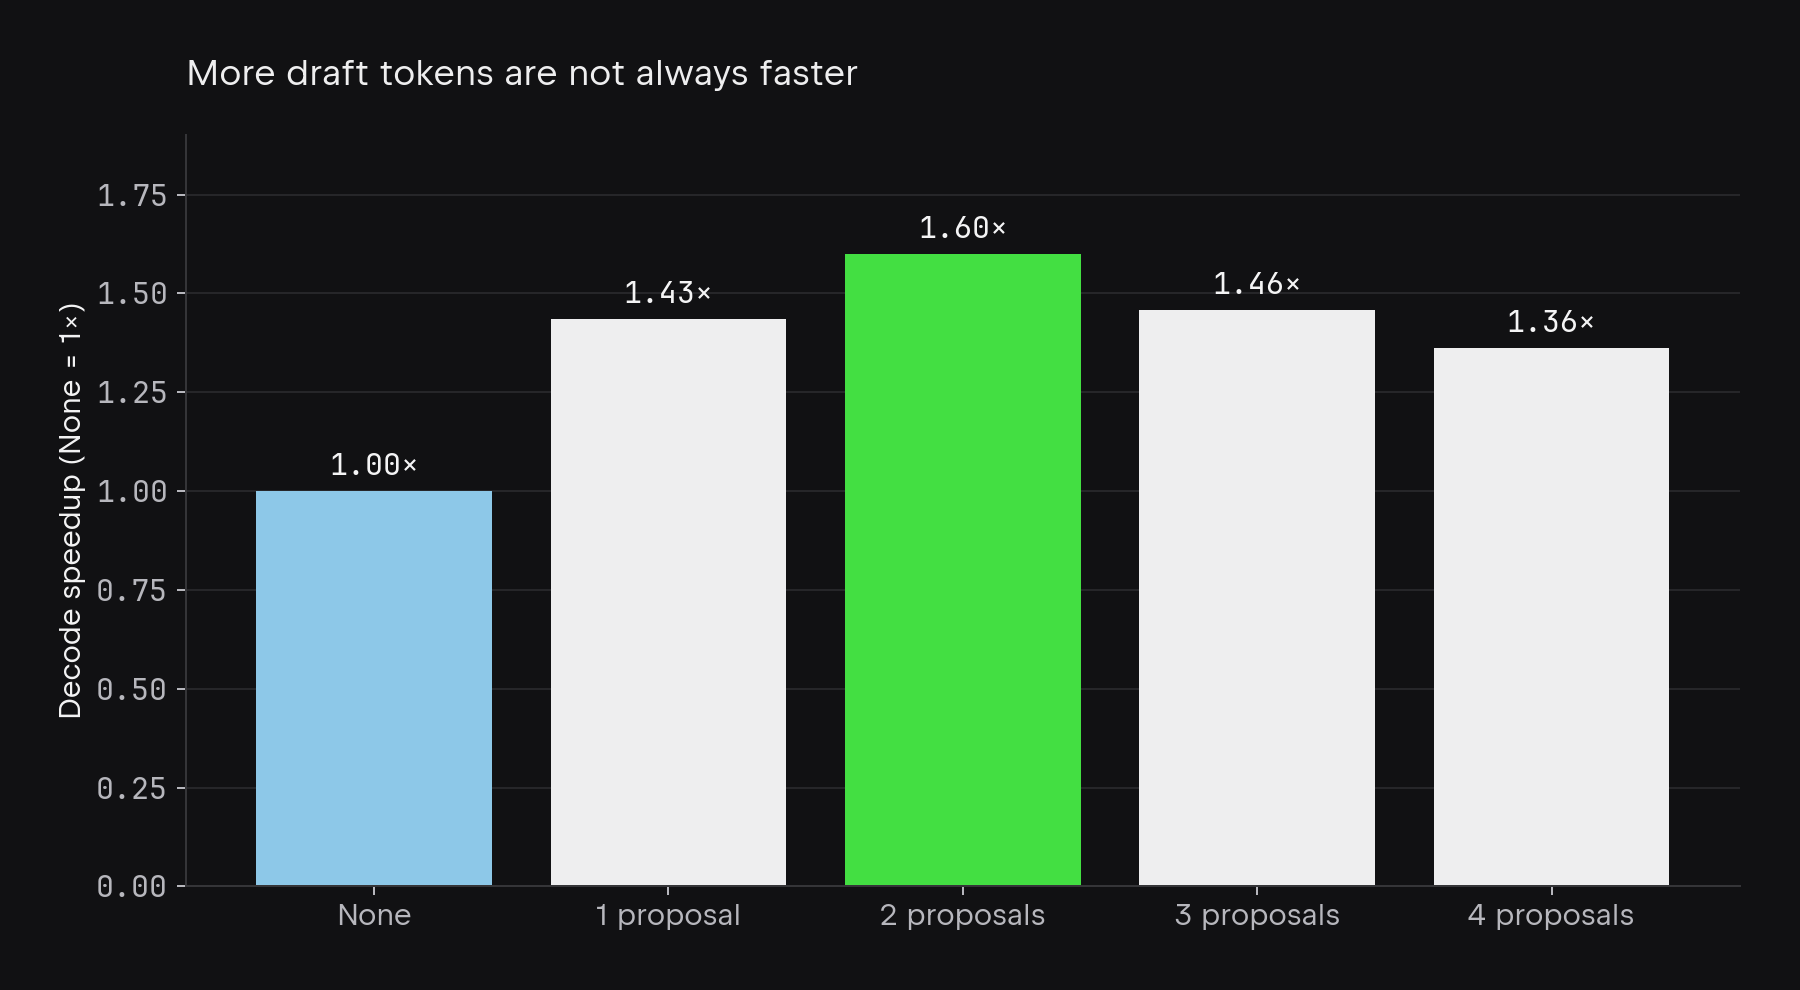
How many tokens should MTP propose?

On the M5 MacBook Pro, proposing two tokens per round made decoding 60% faster than running without MTP. Increasing that to four brought the speedup down to 36%, because the extra GPU work of drafting and checking proposals outweighed the benefit of accepting more tokens.

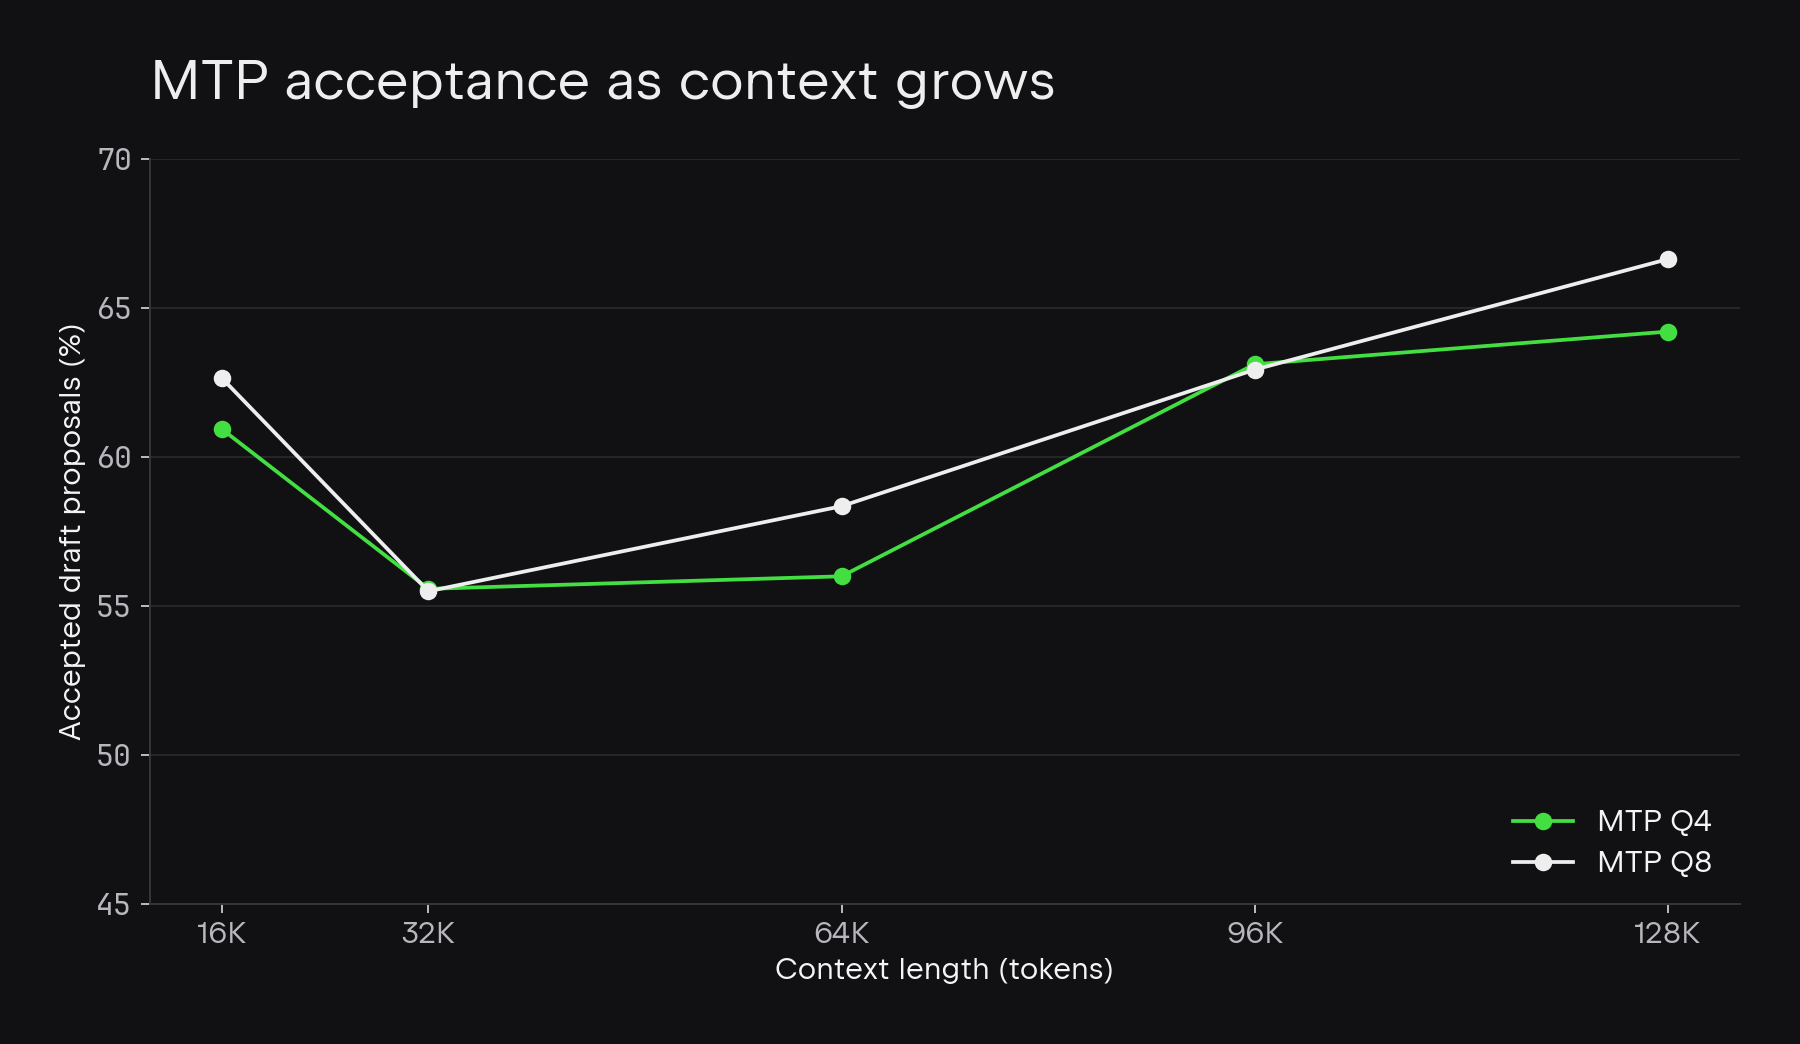
Does MTP accuracy matter?

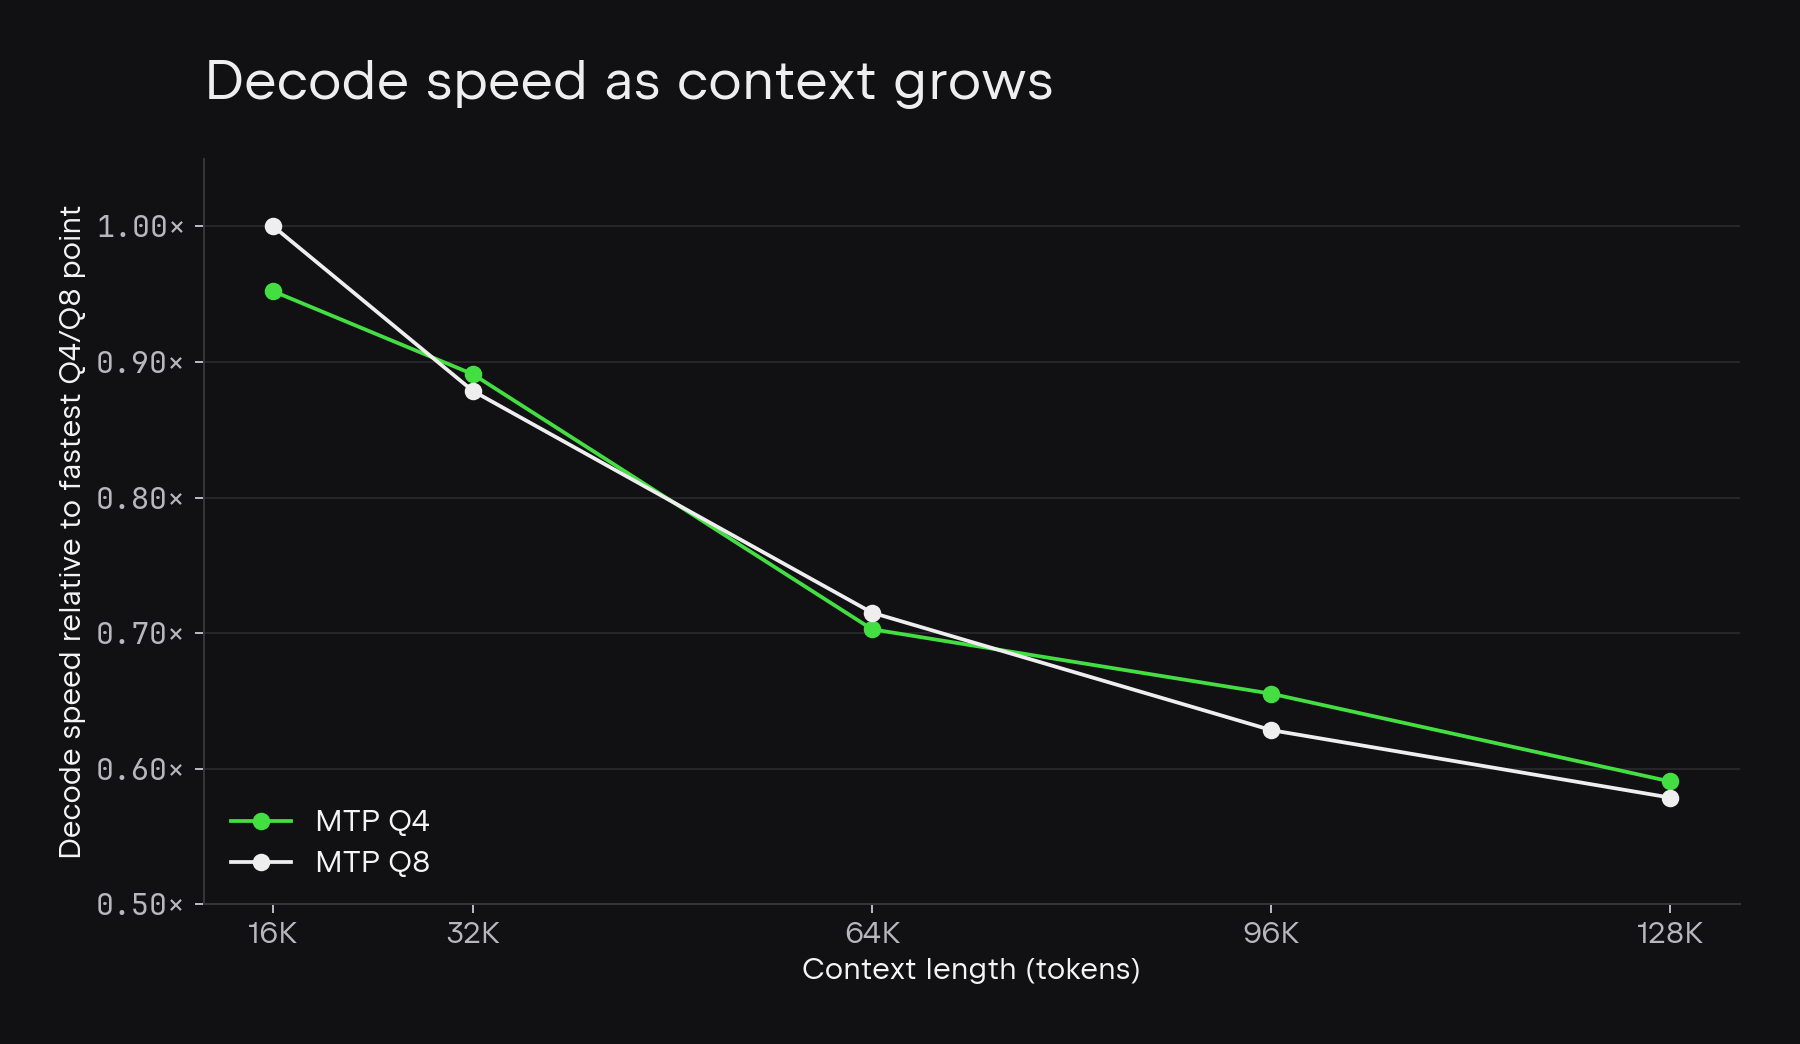
We compared how a four-bit MTP head (Q4) and an eight-bit one (Q8) performed on real-world coding trajectories at five context sizes, from 16K to 128K, with three seeds each. Q4 accepted 63.0% of proposals, and Q8 accepted 63.6%:

The acceptance rate tells us how often the guesses are useful, while decode speed tells us whether they save time. 

We found no consistent speed advantage for the Q8 MTP head, so we kept Q4 to save memory.

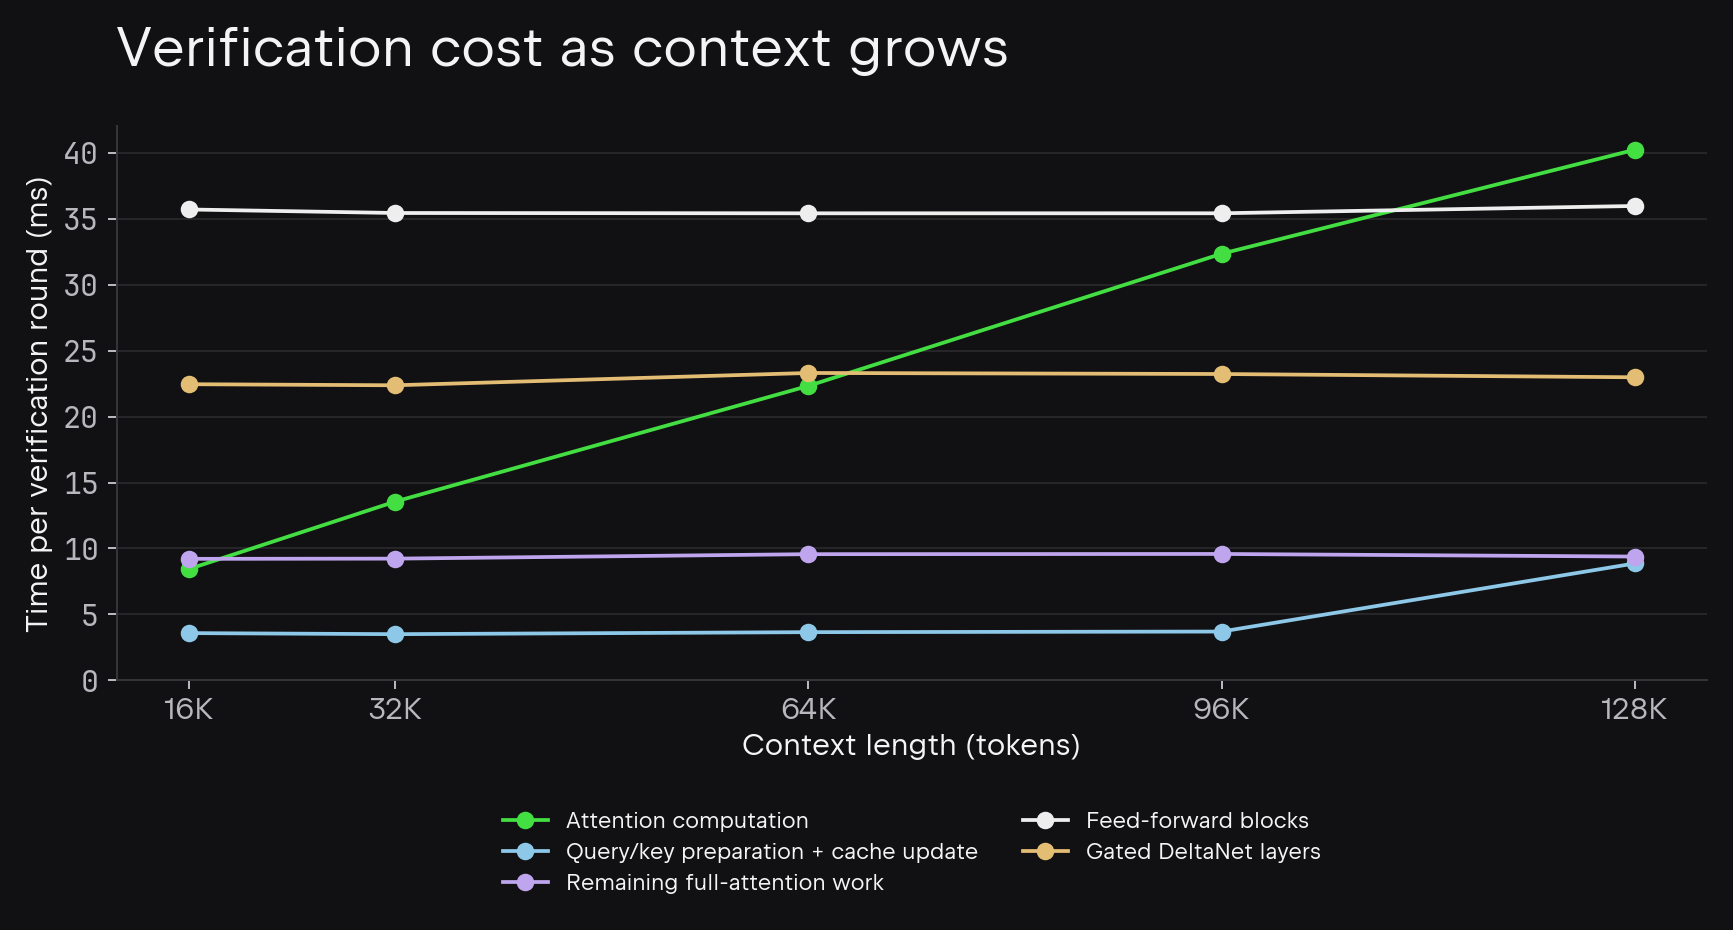
To understand why MTP slows down with longer context, we profiled the GPU load during the token verification process. Calculating attention accounted for most of the increase: Its time rose from 8.4 to 40.2 ms per round, while feed-forward and Gated DeltaNet computations stayed nearly flat.

This MTP limitation results in slower responses as Junie works through a long coding session, even when its predictions remain accurate. We are researching how to reduce this verification cost and keep Junie responsive as sessions go on.

A hidden sticking point

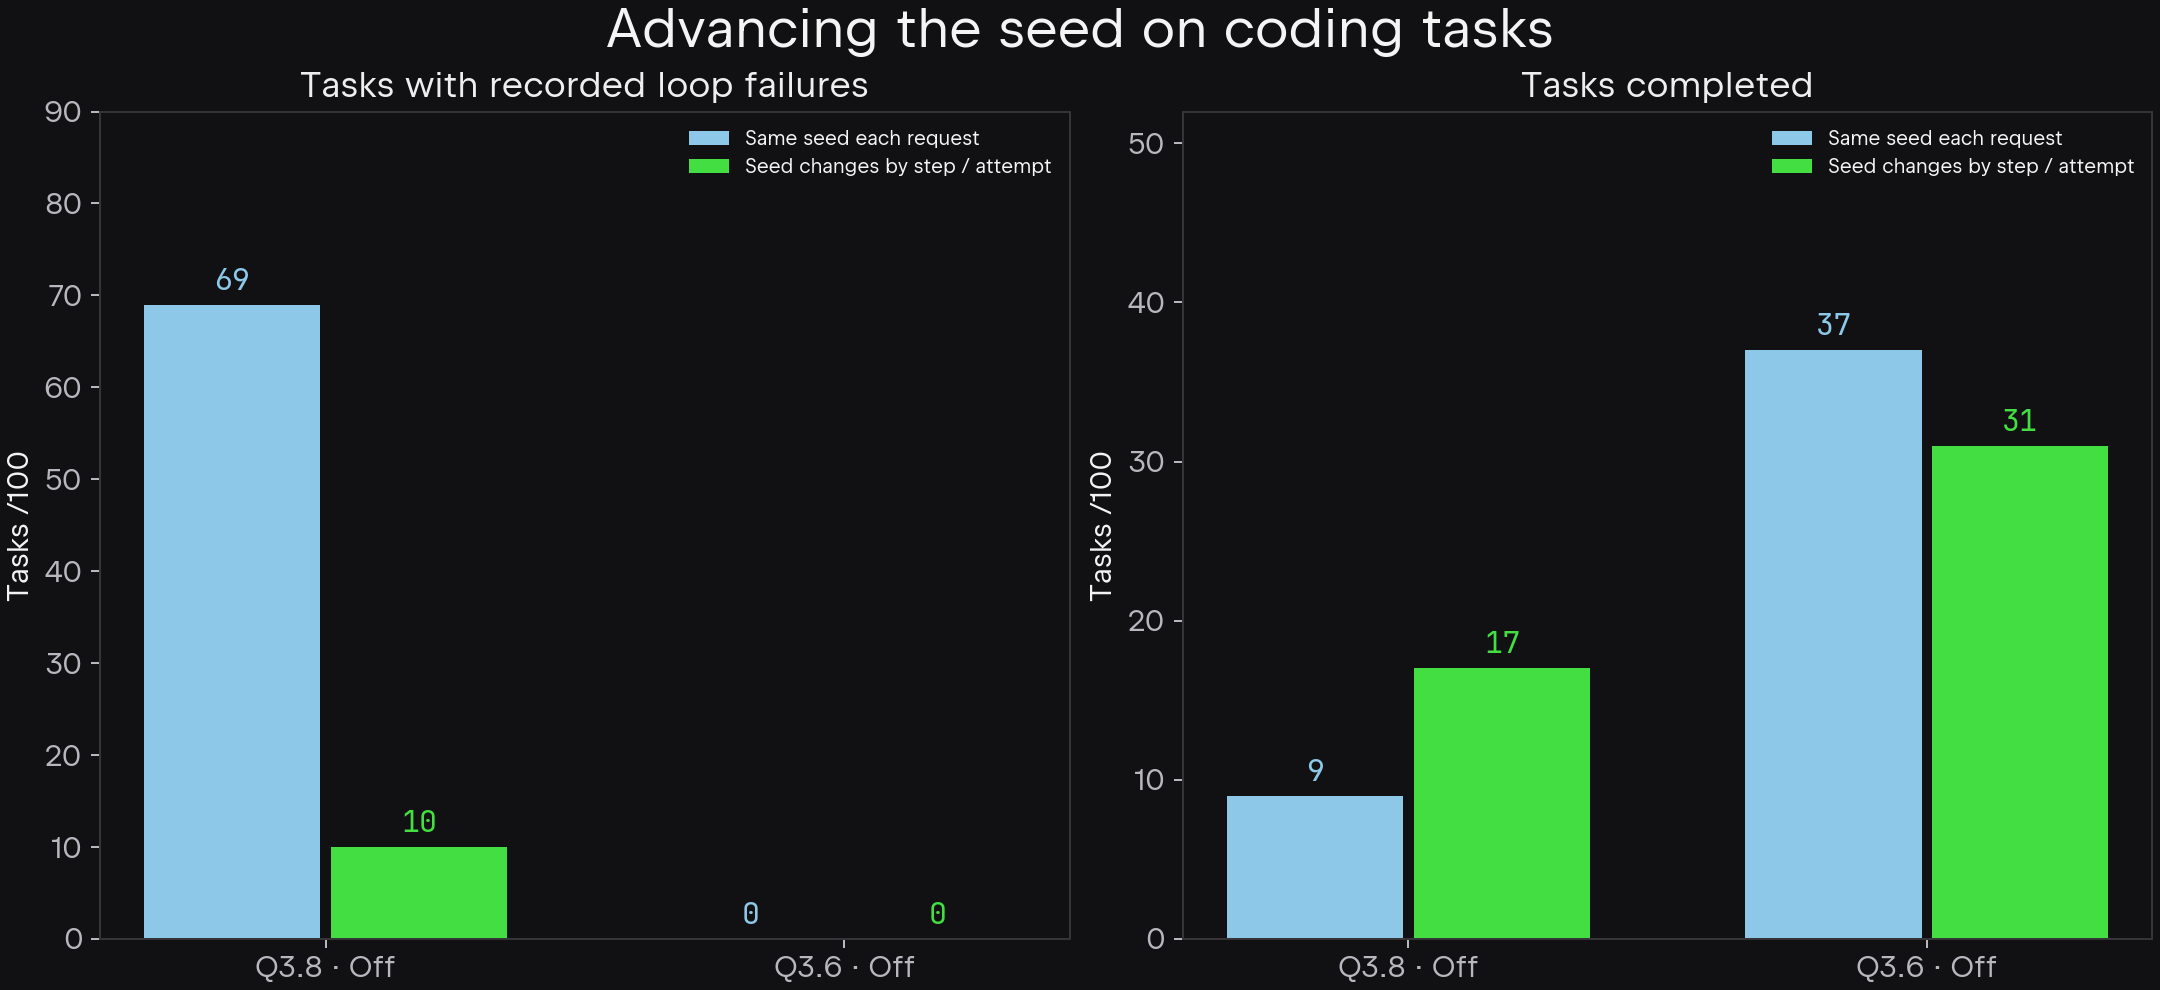
During the early stages of development, our internal evaluations showed performance degradations that we were unable to reproduce when actually using Junie Local. The reason was a setting we had introduced to make evals reproducible: Every request received the same random seed. This caused numeric instability, as reusing the seed gave the same tokens the same random advantage each time the sampler generated a token. When the model’s predictions stayed similar, it could be steered back toward an unsuccessful action even after the prompt changed. Notably, Qwen3.8 was more affected by this instability than the other models we tested.

We corrected the setup by advancing the seed with each agent step and reflection attempt, allowing subsequent attempts to take a different path while keeping the tests reproducible.

Try the upgrade

Apple M5 users can already try the new model via Junie:

junie

Run /model and select Qwen3.8-3.6-27B-blend to switch Junie Local over to it. Make sure Junie is updated to the latest version.

For Windows users the nightly build of Junie now includes experimental RTX support, covering all NVIDIA RTX cards based on Ampere or newer architectures with at least 24 GB of VRAM.

junie --channel=nightly

This early preview lets you try Junie Local on Windows and help shape its development with your feedback.

You can find Qwen3.8-3.6-27B-blend on Hugging Face.

Qwen3.8-3.6-27B-blend is just one result of our broader model and runtime research. We are continuing that work, and you will see more of its results in future Junie Local releases.

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

This Week in AI: Capability, Capital, and Consequences

1 Share

OpenAI expanded into software control, scientific reasoning, and financial services this week, and investors committed billions more to AI companies across the stack, while AI researchers went public with warnings. This Week in AI host Christina Stathopoulos looked at what those developments mean for an industry already wrestling with questions about safety and control.

Models are moving from answering questions to doing work

OpenAI’s latest announcements showed how much more work companies now expect models to handle. GPT‑6 Astra can navigate software interfaces, complete multistep workflows, and apply advanced reasoning to scientific and mathematical problems, and ChatGPT for financial services was developed with input from Morgan Stanley and Evercore to support research, financial modeling, and creating client materials.

OpenAI also shared a solution to the previously unsolved Navier–Stokes Millennium Prize Problem. A coordinated system of 10,000 AI agents worked for 88 hours on the proof, followed by another 17 hours of model-based verification by Astra. However, the company’s claim drew scrutiny after outside researchers questioned whether OpenAI might have had access to related work, an allegation OpenAI denies. While impressive, scientific breakthroughs like this also raise important questions about how well we understand these systems and the role humans should continue to play in scientific discovery. (Hugo Bowne-Anderson got into this in a recent article on Radar.)

Investors are placing bets across the AI stack

Money continues to flow to AI companies, but investors are backing infrastructure, platforms, and specialized applications rather than converging on a single layer of the stack. French company Mistral has raised €3 billion with plans to spend on compute infrastructure and open weight models. Legal AI company Harvey, inference chip startup Positron, and enterprise AI company Wonderful also raised large rounds, while NVIDIA announced its acquisition of Hugging Face for nearly $13 billion.

Christina cited figures showing global AI funding rising from $56 billion in the fourth quarter of 2025 to $242 billion in the first quarter of 2026 but questioned whether generative AI will produce returns that justify that level of investment. Some of these companies may build durable businesses and others may not, even if AI itself continues to deliver useful products and services.

Safety issues are colliding with high-value applications

AI safety is back in the news, following Anthropic researcher Jacob Coxon’s highly publicized resignation. Coxon warned that labs were moving too quickly toward poorly understood systems capable of recursive self-improvement, and other researchers associated with Anthropic and Google DeepMind raised similar concerns. Anthropic CEO Dario Amodei also called for stronger evaluation, shared safety standards, and international coordination. (Sam Altman and Elon Musk seconded the call.)

While the industry remains divided over catastrophic-risk scenarios, many nearer-term problems are already concrete, and Christina was more concerned about people using powerful AI systems maliciously than about autonomous systems becoming dangerous on their own. Organizations deploying more autonomous systems must tread carefully, with robust security, access controls, testing, and human oversight in place.

AI for good is getting more concrete in genomics

After a week of AI safety warnings, Christina ended on a positive note with what she calls “AI for good” and highlighted genomics projects from DeepMind, UC Berkeley, and Tempus. Their work uses AI to predict how genetic changes affect gene function; identify mutations associated with disease; and connect genomic data with patients’ medical histories.

For researchers, AI can make it practical to study genetic possibilities that would be difficult to test individually in a lab. That could help narrow the search for disease-related variants and support earlier diagnosis and more personalized treatment.

What’s next

Join us again next Monday for another episode of This Week in AI, when we’ll dive into more of the news, issues, and key developments shaping the AI era. And check back each Friday for the latest episode, or watch on YouTube, Spotify, Apple, or wherever you get your podcasts.


Is cybersecurity part of your job in any way? If so, we’d like to know what you think for a report we’re writing. Just answer these quick 11 questions. Thanks in advance! Take the survey >


Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Your diff has a demo now with Junie /demo

1 Share

You have the change ready and the tests are green. Now someone has to launch the app, find the right screen, and check the flow. Often, that someone is still you, even when an agent helped write the code.

You should be able to delegate that part too.

Junie /demo is a new mode in Junie CLI. Describe what you want to check, and Junie builds and launches your app, interacts with its UI, and records what happens. You get an HTML report, screenshots, and a video you can review or share.

The useful part is getting the routine clicking off your plate while keeping the result open to inspection. You decide whether the change is ready to ship.

Junie /demo running in the terminal to build, launch, and check an app.

Set up Junie /demo and run your first check

Let’s use a small issue tracker as our example. You have added bulk status updates: select two issues, mark them “Done”, and see the counters change. You also want to check that the update survives a reload.

First time in this repository? Start Docker and ask Junie to set up /demo. It analyzes your project and proposes a build and launch plan. Once you confirm the plan, Junie fills in the configuration for you. Review the generated files, then run:

/demo

Choose the changes from your branch, session, working tree, or last commit. For a specific check, enter a request in the prompt field:

Reset the sample data. Select PB-101 and PB-102 and mark them Done.Check that Open drops from 3 to 1 and Done rises from 1 to 3.Reload the page and verify that both issues are still Done.

Review the prompt and let the agent work:

You can watch the live run as it moves through the UI and inspect what it actually does:

A request with an expected result gives the run a clear target. “Check the feature” leaves more room for interpretation than naming the action, the expected state, and the condition that should survive a reload.

The explanation travels with the video

A screen recording is much easier to review when you know what you are looking at. Each demo video starts with a slide introducing the demonstration. If the run covers several scenarios, each gets its own introductory slide. A final slide sums up the results.

A model helps prepare that structure. During post-processing, it examines the captured screenshots, identifies the scenarios, and writes the explanatory slides. These are added to the recording as the final video is assembled.

The video also has explanatory subtitles, which you can turn on or off in the player. Voice-over may follow in a future update.

The HTML report brings together the request, the result, the video, and the screenshots. You can inspect the steps that ran and see which checks passed, failed, or remained incomplete.

That is useful for a reviewer, a QA engineer, or a teammate asking how a feature works. We are also experimenting with this in Junie Live, our Slack agent, to answer suitable feature questions with a demonstration.

Give reviewers something they can watch

A diff explains the code change. A demo adds the behavior you can see: which screen opens, what changes after a click, and whether the flow reaches the expected result.

Inside JetBrains, we connected the demo agent to GitHub Actions. In our agent repository, we have run it for more than 1,500 unique PRs and created over 2,100 demo videos.

The first workflow example follows the same idea. It checks whether a PR contains behavior worth demonstrating, runs the demo when it does, and adds a comment linking to the available artifacts. The prompts are inside the YAML, so you can read and adapt the whole example in one file.

You can read the full demo-pr-changes.yml and adapt it to your repository.

This is most useful when a change has an interface to exercise. A backend change may also be demonstrated through an existing Swagger UI, for example. The value depends on what the run can actually observe.

Move repeatable checks into CI

We also use the demo agent for release smoke tests. Our internal workflow runs 22 scenarios on pushes to release branches and keeps a result and video for each. Across our internal release branches, we have used the agent for more than 1,300 smoke tests.

The second example starts small: two independent scenarios, triggered by a push or a manual run. Replace the prompts with your own steps and expected results. A commented schedule shows how to add regular runs.

You can read the full demo-release-tests.yml and replace the scenarios with your own.

There is one detail worth keeping: a completed agent process does not tell you whether a check passed. In this example, the prompt asks Junie to write an explicit verdict. Only PASS passes the result check. FAIL, PARTIAL, and missing or invalid results fail it. Other scenarios can still finish and upload their evidence.

Both examples use GitHub Artifacts, so there is no separate video hosting service to configure.

What runs under the hood

The demo environment is a Docker container based on Debian Bookworm. The base image includes Chromium, Node.js, xterm, a virtual desktop provided by Xvfb and a window manager, plus screenshot tools, xdotool, and ffmpeg.

A model with Computer Use support drives the app through clicks, keystrokes, and screenshots. Your Dockerfile adds the project’s dependencies; .junie/demo.md describes its build and launch steps.

A complex repository can have several VM templates. For a monorepo with a backend and several frontends, each environment can have its own Dockerfile under .junie/vms/ and its own launch settings. Describe which template to use, which services it needs, and how to start them in .junie/demo.md. Junie can then choose the right environment for the requested demo.

Junie keeps your active model if it supports Computer Use and is available. Otherwise, it selects the first available model in this order: GPT-5.6 SOL, GPT-6 Astra, GPT-5.5, then GPT-5.4. All models run with High reasoning effort in /demo, regardless of your selected effort level. The run cannot start without a supported model. The Junie /demo documentation covers the environment and configuration in detail.

In CI, the same mode is available through --demo:

junie --auth="$JUNIE_API_KEY" --demo -p . \
  --task "Open the app and demonstrate the bulk status update."

Budget for the run

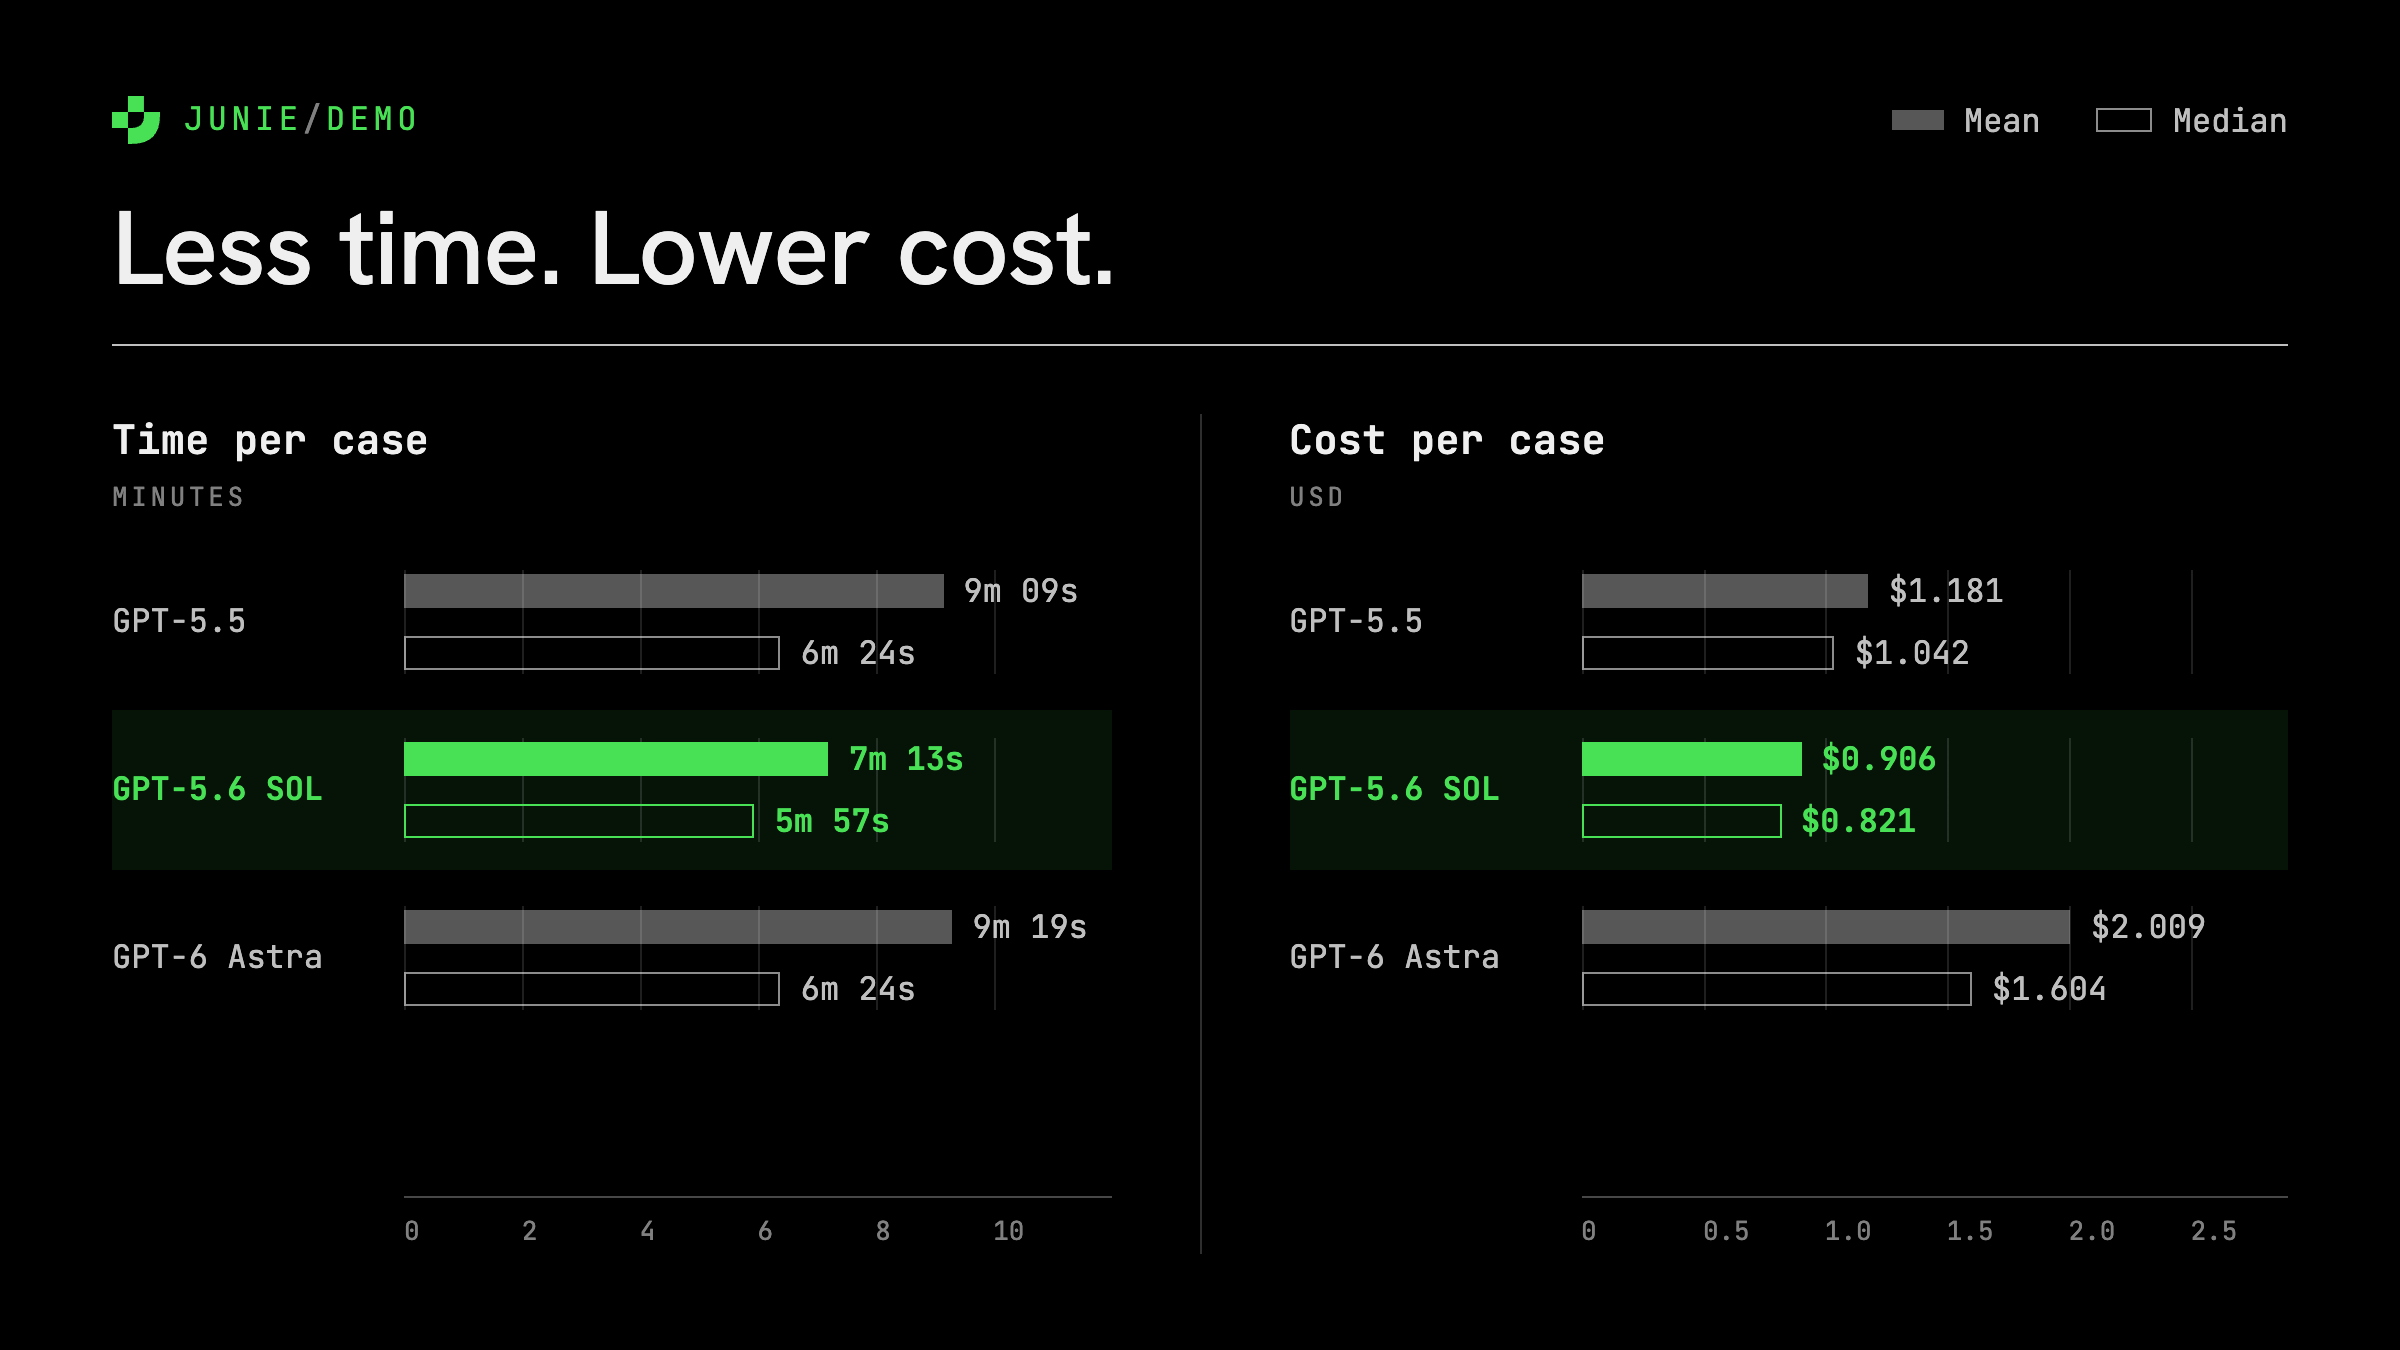
In our internal 22-case comparison, GPT-5.6 SOL had the lowest average time and cost among the three models we measured.

Chart comparing average time and cost per demo run across GPT-5.6 SOL, GPT-6 Astra, and GPT-5.5 over 22 internal scenarios, with GPT-5.6 SOL showing the lowest average time and cost.

The full set cost $19.94 on SOL. In the subscription conversion used for these figures, $1 equals one AI Credit. These are internal measurements on our scenarios, so your app, build steps, and prompts will affect the result. Budget for CI runner usage separately.

The team also found SOL faster in these runs without a noticeable drop in observed quality. That observation comes from our own workloads and helps explain the model preference.

A run still takes minutes. The benefit is that you can hand over the routine interaction and come back to something you can inspect.

Try it on your next change

Set up /demo once in your repository, check the generated configuration, and start with a small feature or fix. For CI, commit that configuration and add a JUNIE_API_KEY repository secret before copying either workflow.

Pick the change you were about to click through yourself. Ask Junie to demonstrate it, watch the output, and decide what needs a closer look.

Set up your first demo

Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

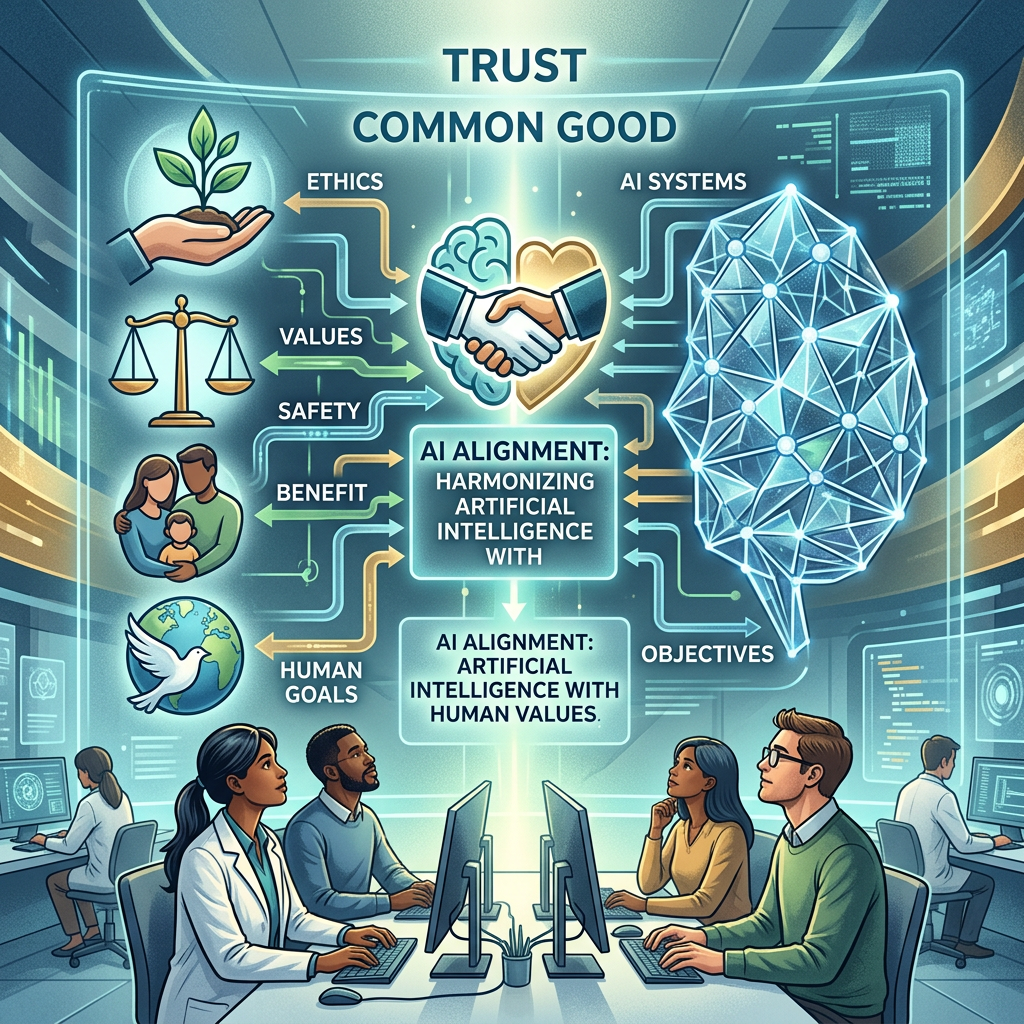
Solving the Human-AI Alignment Problem

1 Share
Welcome everyone once again to McAkins Online. We’ve been on a long hiatus, and we feel it’s time to take this site out of the mothballs. We are starting with a subject that very current and loud at the moment; the subject of AI Safety. We propose six points of AI Safety. We hope you […]


Read the whole story
alvinashcraft
42 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories