 Log in

|
Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
|


Pennsylvania, USA

Microsoft’s FORGE Lab found several memory safety issues in Rust’s standard library (std and core), including cases where code written entirely in safe Rust can trigger undefined behavior. The research used Hyenas, FORGE’s frontier research version of codename MDASH, an AI-powered vulnerability-scanning system. The findings reveal three recurring patterns of misplaced trust in unsafe code: trusting code not to panic, trusting user-provided implementations to be correct, and trusting the underlying system.
Rust’s safety guarantees are precisely what make these findings interesting. Its rich type system and ownership model rule out whole classes of memory-safety issues, but much of the standard library relies on unsafe code underneath its safe APIs. When that code breaks its safety contract, even safe Rust can encounter behavior the language is designed to prevent.
Rust’s memory-safety guarantees are increasingly important as the language becomes part of software that billions of people rely on every day. Billions of people are estimated to interact with Rust-based software or operating systems daily, often without knowing it. Microsoft made Rust a Tier-1 internal language alongside C++, C#, and TypeScript, GitHub rewrote the Copilot agent runtime in Rust, and Bun, Android, the Linux kernel, and Cloudflare are moving code to it as well. Much of this software relies on Rust’s foundational libraries, core and std, and the safety guarantees of the APIs they provide. Bugs in those libraries can have consequences well beyond the code where they originate.
Unsafe Rust has been a long-running interest for us. Our team includes the people behind Rudra, a static analyzer that looked for memory-safety bugs across the Rust ecosystem in 2021. We also write many of our own tools in Rust, so its safety is more than a research topic for us. This year, we took a closer look at the standard library to see what kinds of mistakes still show up in its unsafe code today.
In this post, we share some of the bugs we reported to the Rust issue tracker. We use them to discuss what Rust does and doesn’t guarantee, why writing correct unsafe Rust is so difficult, and why Rust’s safety model still matters even though its memory safety isn’t perfect.
How we found and validated the bugs
At Microsoft FORGE Lab, we study vulnerabilities in complex software, including the Rust standard library. Our team combines years of experience in vulnerability research with AI-assisted tools that help us investigate code and find bugs that are difficult to uncover through traditional analysis alone.
Some of the bugs in this post were found with help from Hyenas, our research version of codename MDASH. Our researchers investigated the underlying code, reproduced the bugs, assessed their potential security impact, and worked with Rust maintainers to report and fix them.
This post focuses on soundness bugs in the standard library’s unsafe code. Bugs in the compiler itself, such as miscompilations and holes in the type system, are a different topic that we don’t cover here.
A note on open issues
At publication, two of the issues reported by our team remain open. The article also references related issues reported by others and fixes that are still under review. The Rust maintainers triaged and responded to our reports quickly, and we believe maintainers and the contributors working on these issues are doing their best and making the right tradeoffs among the many bugs they handle.
If you’re interested in an open issue, please comment only when you have something genuinely new to contribute, such as new information or an affected real-world use case.
Patterns of Rust’s Safety Bugs
At the lowest level, Rust uses unsafe blocks to work with raw pointers and interact directly with the operating system. Much of the standard library, including Vec and String, is built from small unsafe pieces wrapped in safe APIs. Inside an unsafe block, the programmer takes responsibility for the guarantees the compiler can’t check, and that responsibility extends to the safe API built around it. That API must be sound: no matter how safe code uses it, it must be impossible to trigger undefined behavior.
Upholding that promise is harder than it looks. Consider a function that returns the byte at idx from any type that can be viewed as a byte slice, skipping the redundant bounds check after doing its own:
pub fn get<[u8]>>(s: &S, idx: usize) -> Option {
    if idx < s.as_ref().len() {
        // SAFETY: we just checked that `idx` is in bounds.
        Some(unsafe { *s.as_ref().get_unchecked(idx) })
    } else {
        None
    }
}
The hard part of unsafe Rust is knowing what you can trust. The function above looks correct, but it assumes that two calls to as_ref return the same slice. Because S is chosen by the caller, a safe AsRef implementation can return a long slice the first time and an empty one the second, and get reads out of bounds. Unsafe code must be careful with every call it makes, and the bugs we found fall into three patterns of misplaced trust: trusting code not to panic, trusting user-provided implementations to be correct, and trusting the underlying system.
Pattern 1: Trusting code not to panic
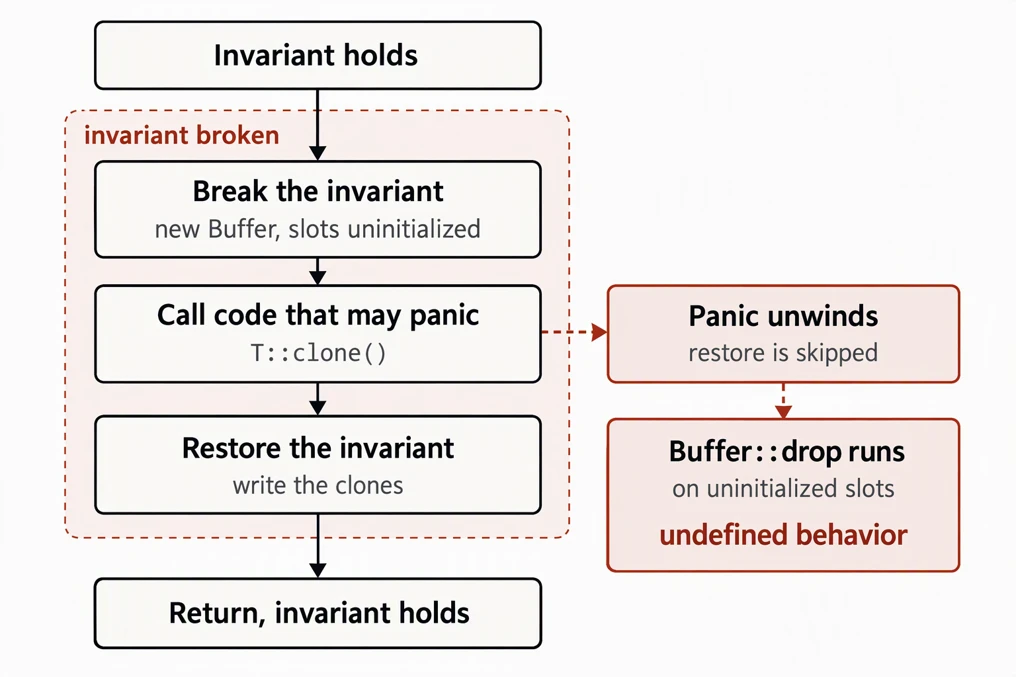
Unsafe code often breaks an invariant for a moment and restores it afterward; for example, it may allocate an uninitialized buffer and fill it directly, avoiding redundant writes to zero the memory first. That’s fine as long as the function runs to the end. But many operations in Rust can panic, from out-of-bounds indexing to calls into user-provided code, and by default a panic unwinds: it leaves the function early while still running destructors. Unwinding inside that window becomes an invisible exit that exposes the broken invariant to code that trusts it. Bugs of this kind are called panic safety bugs.
MapWindows::clone (issue #156501)
We identified a panic safety issue in MapWindows::clone. The nightly API Iterator::map_windows yields overlapping windows of N items. It keeps the current window in a Buffer whose destructor drops the N items starting at start. In Rust 1.97.0, library/core/src/iter/adapters/map_windows.rs defines it as:
struct Buffer {
    // Invariant: `self.buffer[self.start..self.start + N]` is initialized,
    // with all other elements being uninitialized. This also
    // implies that `self.start <= N`.
    buffer: [[MaybeUninit; N]; 2],
    start: usize,
}
Buffer::clone, in the same file, built the new buffer first and filled it afterward:
impl Clone for Buffer {
    fn clone(&self) -> Self {
        let mut buffer = Buffer {
            buffer: [[const { MaybeUninit::uninit() }; N], [const { MaybeUninit::uninit() }; N]],
            start: self.start,
        };
        buffer.as_uninit_array_mut().write(self.as_array_ref().clone());
        buffer
    }
}
After buffer is constructed, it breaks its own invariant: its slots are uninitialized, but its destructor is already armed. The self.as_array_ref().clone() call runs the user's T::clone before the slots are written. If that call panics, unwinding drops buffer and runs drop_in_place on N uninitialized values. Our proof of concept uses only safe code: an element type whose clone always panics, which causes a crash when the destructor accesses uninitialized memory. The fix holds the new buffer in ManuallyDrop until it is fully written, so unwinding leaks the half-built buffer instead of dropping it.
The general lesson is to treat every call to code you don’t control, such as clone, drop, comparisons, closures, and iterator methods, as a possible early exit. Either finish the work that may panic before breaking an invariant, or make the broken state safe to unwind through: hold it in ManuallyDrop, or use a guard whose destructor restores the invariant, like Vec’s internal SetLenOnDrop. The Rustonomicon covers this under exception safety.
Allocators must not unwind
The recently stabilized Allocator API shows how hard panic safety is to get right. With std, an allocation failure aborts the process by default instead of unwinding, so much of the standard library's unsafe code assumes allocation never unwinds. Custom allocators can break that assumption. While the API was being stabilized, we reported one place in BTreeMap::insert that becomes unsound when an allocator unwinds, and others reported more (#159334, #159368, #159370). Fixing them one by one would mean auditing everything that allocates, so the stabilization, shipping in Rust 1.100 on November 12, instead requires implementors never to unwind from the trait's methods or from drop. The proposal notes that "unwinding out of many allocation-related methods was found to be a pervasive source of unsoundness."
Pattern 2: Trusting user-provided implementations to be correct
Unsafe code often calls into code its caller provides: a comparator, a trait implementation, a closure. That code is safe, but safe doesn’t mean correct, and it can return inconsistent or plainly wrong answers. The question is who is responsible when it does. In C++, it’s the caller. std::sort requires its comparator to be a strict weak ordering, and breaking that rule is undefined behavior. With libstdc++, sorting equal elements with <= reads past the end of the vector:
std::vector v(100, 42);
// Bug: `<=` is not a strict weak ordering, since cmp(a, a) is true.
std::sort(v.begin(), v.end(), [](int a, int b) { return a <= b; });
// AddressSanitizer: heap-buffer-overflow in std::__introsort_loop
The same comparator passed to Rust's sort_by is only a logic error. The sort may panic or leave the slice in an unspecified order, but it never causes undefined behavior. The responsibility sits with the unsafe code. The comparator is safe code supplied by the caller, so the unsafe code inside the sort must stay sound no matter what it returns. The same goes for every safe trait a user can implement: comparisons can be inconsistent, an ExactSizeIterator can report a length that doesn't match the items it yields, and Borrow can return a different value on each call.
str::replace with a custom Pattern (#156491)
Another of our bug reports shows how easy this trust is to miss: str::replace with a custom Pattern can create a non-UTF-8 String. String search APIs accept any type that implements the nightly Pattern trait, and a pattern can describe itself through as_utf8_pattern. str::replace uses that description to take a fast path when replacing one ASCII byte with another. In Rust 1.96.0, the fast path in library/alloc/src/str.rs looked like this:
pub fn replace(&self, from: P, to: &str) -> String {
    // Fast path for replacing a single ASCII character with another.
    if let Some(from_byte) = match from.as_utf8_pattern() {
        Some(Utf8Pattern::StringPattern([from_byte])) => Some(*from_byte),
        Some(Utf8Pattern::CharPattern(c)) => c.as_ascii().map(|ascii_char| ascii_char.to_u8()),
        _ => None,
    } {
        if let [to_byte] = to.as_bytes() {
            return unsafe { replace_ascii(self.as_bytes(), from_byte, *to_byte) };
        }
    }
replace_ascii, in the same file, then rewrites the bytes:
unsafe fn replace_ascii(utf8_bytes: &[u8], from: u8, to: u8) -> String {
    let result: Vec = utf8_bytes.iter().map(|b| if *b == from { to } else { *b }).collect();
    // SAFETY: We replaced ascii with ascii on valid utf8 strings.
    unsafe { String::from_utf8_unchecked(result) }
}
The CharPattern branch checks that the character is ASCII, but the StringPattern branch assumes a one-byte string pattern must be ASCII. That holds for &str patterns, but StringPattern stored &[u8], and as_utf8_pattern is a safe method any Pattern can implement. In our proof of concept, a custom pattern reports the single byte 0x80, which only appears inside multibyte UTF-8 sequences:
impl Pattern for NonAsciiBytePattern {
    // ...
    fn as_utf8_pattern(&self) -> Option<'_>> {
        static NEEDLE: [u8; 1] = [0x80];
        Some(Utf8Pattern::StringPattern(&NEEDLE))
    }
}

// "\u{d000}" is [ed, 80, 80]; the result is [ed, 3f, 3f], which is not UTF-8.
let corrupted = "\u{d000}".replace(NonAsciiBytePattern, "?");
str::replace rewrites the continuation bytes and returns a String that isn't valid UTF-8, and later string operations that rely on UTF-8 reach undefined behavior. The fix changed StringPattern to hold &str instead of &[u8], so the type itself now guarantees UTF-8.
When unsafe code depends on a property of a user-provided implementation, don’t take it on faith. Call the implementation once and keep the result, validate what it returns, or encode the property in a type that safe code can’t forge, as this fix did. If none of those work, make the trait unsafe so implementors explicitly promise to uphold it.
More examples
join shows how easy it is to fix this kind of bug only partway. In 2020, we reported that it trusted Borrow::borrow to return the same string on each call (CVE-2020-36323), and the fix handled strings that shrink between calls. In April 2026, the same function needed another fix: join borrows the first element twice, and if it grows on the second call, the remaining-length calculation underflows into a heap overflow. The earlier fix had never covered that path.
Others reported similar problems in the Pattern API this year. A safe Pattern can hand back a valid searcher built for a different string, and consumers such as strip_prefix_of apply its ranges to the original string unchecked, reading out of bounds (#158265). The same problem turned up in split_once (#165076) after a report that the Searcher contract doesn't spell out what str::split relies on (#164904). Both bugs are still open.
Pattern 3: Trusting the underlying system
The first two patterns stay inside Rust code. The third sits at the boundary with the operating system, where unsafe code trusts process-wide state such as signal stacks, memory mappings, and the environment, which other threads, C libraries, or the kernel can touch at any time. These bugs have been hard to find automatically, because a static analyzer would need to model all of that surrounding behavior. AI agents change the picture: they understand enough about the environment the code runs in to make this area practical to search. We started exploring it and found some interesting bugs.
process::exit and the main thread’s signal stack (#161018)
When a thread overflows its stack, Rust prints a clear message and aborts instead of crashing with a bare segmentation fault:
thread 'main' (3307186) has overflowed its stack
fatal runtime error: stack overflow, aborting
This relies on a few pieces of process-wide state. Each thread’s stack ends in a guard page, an inaccessible region just past the stack’s limit: pthread reserves one for every spawned thread, and on Linux the kernel’s own stack guard plays that role for the main thread. Touching it raises SIGSEGV, and Rust registers a handler for that signal. The handler can’t run on the stack that just overflowed, so Rust also gives each thread an alternate signal stack, a small separate mapping with a guard page of its own, which the kernel switches to when it delivers the signal. The handler checks that the faulting address is inside the guard page, prints the message, and aborts.
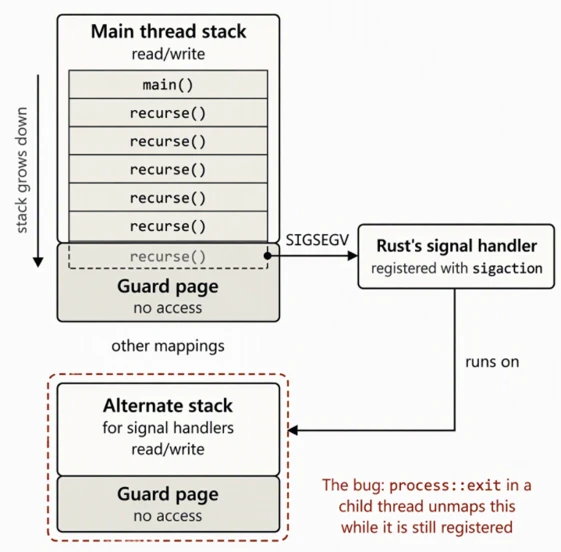
We found that calling process::exit from a child thread tears down the main thread’s alternate stack while the main thread is still running. process::exit runs the runtime’s cleanup before calling libc’s exit, and in Rust 1.98.0 that cleanup ends in library/std/src/sys/pal/unix/stack_overflow.rs:
pub unsafe fn cleanup() {
    if cfg!(panic = "immediate-abort") {
        return;
    }
    // FIXME: I probably cause more bugs than I'm worth!
    // see https://github.com/rust-lang/rust/issues/111272
    unsafe { drop_handler(MAIN_ALTSTACK.load(Ordering::Relaxed)) };
}
The cleanup function passes MAIN_ALTSTACK, the main thread’s alternate stack, to drop_handler:
// SAFETY: we warned the caller this disables the alternate signal stack!
unsafe { sigaltstack(&disabling_stack, ptr::null_mut()) };
// SAFETY: We know from `get_stackp` that the alternate stack we installed is part of
// a mapping that started one page earlier, so walk back a page and unmap from there.
unsafe { munmap(data.sub(page_size), sigstack_size + page_size) };
The call to sigaltstack disables the alternate stack of the calling thread, but the subsequent call to munmap unmaps the main thread’s. The code assumes it runs on the main thread, which isn’t true when a child thread calls process::exit. The main thread keeps running until libc’s exit finishes, with its signal stack registration still pointing at unmapped memory. If it overflows its stack in that window, the kernel can’t deliver the signal, and our proof of concept dies with a plain segmentation fault instead of Rust’s message. The bug dates back to 2015, and the fix stops cleaning up the main thread’s alternate stack altogether.
We also checked whether this could become a security issue. In theory, it could lead to code execution: if a writable mapping landed at the old alternate stack’s address, the kernel would deliver the main thread’s next signal onto it, and another thread could overwrite the handler’s frame, such as its return address, while it runs. In practice, the conditions are very tight. Everything has to happen in the brief window before libc’s exit finishes, the new mapping must have exactly the right size to reuse that address, and overwriting the frame takes a second race inside a short handler. For issue #161018, our testing found no reliable exploitation path under the conditions examined, and we assessed practical exploitation as unlikely. This assessment does not automatically apply to the other issues discussed. The issue has more details in its security impact analysis.
CommandExt::exec and the global environment (#156951)
Our other report involves the process environment. On Unix, CommandExt::exec replaces the current process with a new program. When the command has its own environment variables, exec points the process-global environ at a new array, calls execvp, and restores environ if execvp fails. In Rust 1.99.0, Command::exec takes the environment lock in library/std/src/sys/process/unix/unix.rs:
let _lock = sys::env::env_read_lock();

let Err(e) = self.do_exec(theirs, envp.as_ref());
Command::do_exec, in the same file, then swaps the environment:
    _reset = Some(Reset(*sys::env::environ()));
    *sys::env::environ() = envp.as_ptr();
}

libc::execvp(self.get_program_cstr().as_ptr(), self.get_argv().as_ptr());
Err(io::Error::last_os_error())
Command::exec takes only the read side of the environment lock, yet do_exec writes the process-global environ. Before the write, do_exec saves the old value so it can be restored if execvp fails. Writing environ under a read lock lets other threads in. A thread calling env::var takes the same read lock and can see variables meant only for the new program, and two failed exec calls racing each other can leave environ pointing at a freed array that a later env::vars_os() reads. Both proofs of concept use only safe Rust. A 2018 fix held an exclusive lock here, but when the environment lock became a read-write lock in 2021, exec kept the read side. A fix that avoids touching environ by calling execve directly is in review.
The environment has caused trouble before. After a discussion that began in 2015, the 2024 edition marked env::set_var as unsafe, because C functions on most Unix platforms read the environment without going through Rust's lock.
process::exit and thread-local destructors (#164243)
Getting this boundary right is hard, and more problems are still open. While exploring this area, we independently ran into a double free in safe code that process::exit can cause through thread-local destructors. It was reported by someone else (#164243), but it’s worth mentioning here. libc’s exit first runs the calling thread’s thread-local destructors, as C++ requires, and Rust registers its destructors the same way. If a destructor calls process::exit while a thread local is being replaced, libc drops that thread local a second time. A proposed fix switches process::exit to POSIX _exit, which ends the process without running these handlers.
Why Rust still matters and advancing vulnerability discovery with AI
Every unsafe block rests on assumptions about the code around it. The bugs in this post came from three kinds of misplaced trust:
- that code won't panic at the wrong moment,
- that a caller-provided implementation behaves correctly, and
- that the process-wide state Rust shares with the operating system and the C library stays the way the code expects.
Familiar patterns are still difficult (Patterns 1 and 2)
The first two patterns are well studied. Rudra looked for both in 2021, and the standard library was already fixing panic safety bugs in 2015 (CVE-2015-20001). They remain challenging to avoid because any call inside unsafe code might unwind or run code the caller supplied.
What we saw this year was mixed. On the positive side, the nightly process is working. Many reports were caught while the affected APIs were still unstable, and several were fixed by changing the design before stabilization. StringPattern now holds &str instead of &[u8], and Allocator was stabilized with a rule that implementors must not unwind. At the same time, bugs in these patterns still reach stable releases, and their fixes aren't always complete. join was fixed in 2020 and needed another fix in 2026 for a path the first fix had missed.
System boundary bugs are now within reach (Pattern 3)
The third pattern is different. Its bugs live where Rust meets the layers below it: the kernel, through system calls such as sigaltstack and munmap, and the C library, through process-wide state such as environ and the cleanup that libc's exit runs. Getting them right takes knowledge that lives outside Rust's type system, which has made these bugs difficult to find with traditional static analysis. That may also be why they last so long. The process::exit signal stack bug was in the standard library for nearly 11 years, and exec has written environ under a read lock since 2021. Unlike our reports in the first two patterns, both affect stable Rust.
Language models already know a great deal about how these interfaces behave, so agentic scanners can check unsafe code against the system it runs on, not just the language. We think this boundary is one of the most promising places for agentic security research, in Rust and beyond.
Rust's high bar is hard to meet but worth keeping
Rust holds its safe APIs to a stricter standard than C and C++. Safe code must never be able to cause undefined behavior, no matter how it uses an API. In C++, a comparator that breaks std::sort's ordering requirement causes undefined behavior, while Rust's sort must stay memory-safe with any Ord implementation. POSIX doesn't guarantee that setenv is safe to call while another thread reads the environment. That makes memory safety bugs in Rust hard to compare one-to-one with bugs in other languages.
For the same reason, a soundness bug in the standard library isn't automatically a vulnerability in the programs that use it. Each bug in this post needs an unusual setup to trigger, such as a panic at exactly the wrong moment, a deliberately misbehaving implementation, or calling process::exit from a child thread. It becomes a serious vulnerability only if a real program reaches the API in that way.
Rust's safety standard is strict and difficult to meet, but it's also useful. It gives an unambiguous answer to what counts as a soundness bug, so problems can be fixed and prevented once in the library, instead of in every program that uses it. Rust's safety model strikes the right balance between control, safety, and performance for systems programming, which is why so many projects choose it.
Beyond the lab
At Microsoft FORGE Lab, we're exploring how technology such as codename MDASH can help researchers find bugs like the ones in this post at greater scale. Rust's standard library is one of several foundational open source projects where we're applying this approach.
This research also extends beyond the lab. It helps inform the development of codename MDASH, which brings agentic vulnerability discovery into Microsoft Defender. These findings can also serve as inputs to Microsoft Perception, our new multi-agent security system, where specialized agents work together across broader security workflows. For example, the Web App Pen Test Agent can use codename MDASH findings to help prioritize testing, validate exploitability against live applications, and produce actionable vulnerabilities that downstream agents can use to prioritize and support remediation. This connects AI-powered code analysis with real-world security validation and response, helping security teams move from identifying potential vulnerabilities to understanding and addressing actual risk.
Our goal isn’t to simply find more bugs, it's to identify meaningful issues, turn those findings into actionable research, and improve the safety of foundational software that developers and organizations depend on.
The post FORGE Lab uses agentic tools to identify memory safety issues in Rust appeared first on Microsoft Security Blog.
Pennsylvania, USA
Windows Server powers the workloads and services organizations rely on every day. As those environments evolve, so do the priorities behind them—from strengthening security and improving resiliency to making operations more consistent across on-premises, cloud, and edge deployments. Every organization brings a different perspective shaped by its people, workloads, and operating needs.
We want to learn from those experiences and build lasting connections with the customers who rely on Windows Server. The Windows Server Technology Adoption Program (TAP) brings customers and the Windows Server product team together to validate preview capabilities and releases before they ship. Through the Windows Server TAP, customers can share their perspectives directly with the Windows Server team, explore areas of mutual interest, and help inform how we build and improve the product. We see TAP as an ongoing conversation: listening to your needs, learning from your feedback, and working together to make Windows Server better for the organizations that depend on it.
What is Windows Server TAP?
TAP is a structured partnership focused on testing and feedback. Participating customers validate defined scenarios in a test or lab environment isolated from production, share their findings, and work with the product team to identify issues and assess readiness.
Depending on the engagement, validation may focus on a particular capability or on broader release-readiness scenarios, such as upgrades and workload compatibility.
TAP is a two-way partnership: your team can explore upcoming capabilities in a test environment, share what you learn, and engage directly with the Windows Server product team. Your real-world perspective helps us understand how Windows Server is used across different environments and focus validation on the scenarios that matter to customers.
Is your organization a good fit for Windows Server TAP?
We're interested in hearing from Windows Server customers who can dedicate technical resources to hands-on validation and regular feedback. You must have a non-production environment where your team can deploy preview builds and run test scenarios from Windows Server features.
TAP engagements are focused and selective. The team matches customer interests and environments to available validation opportunities, then discusses participation requirements and next steps. Expressing interest does not enroll your organization or guarantee a place in the program.
Learn more about Windows Server TAP
Attending Microsoft Ignite? Meet the team at the Windows Server Booth in the Hub (open November 17th – 19th) to learn more about TAP and discuss whether it could be a fit for your organization.
Prefer to connect virtually? Fill out the Windows Server TAP interest form and let's chat over Microsoft Teams about your organization's interests and whether TAP could be a fit.
Questions? Feel free to reach out to the TAP team at windowsserver-engage@microsoft.com.
Pennsylvania, USA
Foundry Toolbox Lifecycle: Deploy and Promote
For developers looking to manage Microsoft Foundry tools across agents, this article presents one recommended pattern: define each Toolbox in its own azure.yaml , deploy it separately from project infrastructure and agents, and pass environment-specific Bicep outputs through GitHub Actions.
Why Manage a Foundry Toolbox Separately?
Organizations are integrating agent development into established software development lifecycles, raising questions about how teams govern and reuse tools. In this post, a “tool” means an external capability an agent invokes such as web search, a tool exposed by a Model Context Protocol (MCP) server, or a third-party application. Tools let agents retrieve live data or take actions in external systems.
How can teams avoid rebuilding the same integrations? Microsoft Foundry Toolbox offers a shared way to manage tools. This post explores how to structure Toolbox ownership and deployment so a reusable collection doesn’t become a Toolshed.
What Is a Microsoft Foundry Toolbox?
A Toolbox in Foundry is a versioned collection of tools exposed through a single MCP-compatible endpoint. It is created in the context of a Foundry Project, and agents connect to that endpoint to use its tools.
Microsoft’s Toolbox overview describes a way to define shared tools once and expose them through a single MCP-compatible endpoint. It centralizes tool access, credentials, governance, and versioning so teams can reuse approved tools across agents without rebuilding each integration.
Instead of embedding a separate Web IQ integration in every Finance agent, teams can configure Web IQ once in a shared Toolbox. Each agent then connects to the Toolbox’s MCP endpoint and invokes the tools it exposes. The Toolbox and its project connections provide the shared configuration and credentials.
Should a Toolbox Be Deployed with an Agent?
Foundry examples show toolboxes created through SDKs and consumed by agents. The key design decision is which deployment lifecycle owns toolbox version changes. When multiple agents share a toolbox, manage its versions separately from any one agent’s deployment.
- A Foundry Project can contain zero or more agents.
- Agent deployments should be idempotent and managed independently.
- An agent’s availability should not depend on another agent.
- A Toolbox has its own lifecycle and versioning.
- A Toolbox lives outside any single agent, within a Foundry Project.
Creating a toolbox with the Python SDK does not, by itself, make the toolbox part of an agent; the SDK call creates a version in the Foundry Project. The coupling arises when the agent’s deployment pipeline also owns and publishes that toolbox. To keep the lifecycles independent, manage toolbox versions through a project-level pipeline and have agents consume the toolbox endpoint. This avoids redeploying an unrelated agent for toolbox changes and avoids making shared tool availability depend on one agent’s lifecycle.
Provision the Project, Then Deploy the Toolbox
A Foundry project is provisioned as an Azure resource (`Microsoft.CognitiveServices/accounts/projects`), while toolbox versions are created through the Foundry project API. In this deployment pattern, we need to provision the project and any required connections first, then create and deploy the toolbox using the project endpoint. See the toolbox version API reference for details.
The Foundry project and its project-level role-based access control (RBAC) and connections are infrastructure prerequisites that can be managed with infrastructure as code (IaC). The toolbox version is then created in a separate deployment step using the project endpoint, with environment-specific values supplied as Bicep outputs. This keeps the Toolbox alongside the project’s lifecycle without coupling it to any one agent.
Where to Store the Toolbox Configuration
Like the Foundry Project, a Toolbox is shared across agents and should follow the project’s lifecycle rather than an individual agent’s lifecycle. Store its definition alongside the project’s IaC and include its deployment in the project-level infrastructure workflow.
Create a separate folder and `azure.yaml` for each Toolbox. This gives each Toolbox its own deployment step and `azd` environment, so teams can deploy, update, and version Toolboxes independently without coupling their release cycles. This post uses that structure to make each Toolbox’s lifecycle explicit.
Foundry Toolbox Versioning and Promotion
Foundry stores each Toolbox version as an immutable snapshot of its configuration. Changes create a new version rather than modifying an existing one. The first version becomes the default automatically; subsequent versions must be promoted explicitly. See Foundry Toolbox version managementfor details.
Agents using the Toolbox’s stable consumer endpoint receive the default version. Developers can use a version specific endpoint to validate changes before promotion. Promoting a version changes what the consumer endpoint serves without requiring a rebuild and deploy of the agents code. To roll back, promote a previously retained version.
Foundry provides these versioning and promotion capabilities, but the team still decides how changes are tested, approved, retained, and retired. A version captures Toolbox configuration not a frozen copy of the external services it calls—so rolling back the Toolbox does not necessarily reverse downstream service changes. i.e. changes that were made to tools of a custom downstream MCP server.
Teams can remove older or unwanted versions after confirming they aren’t needed for rollback or used through version specific endpoints. If multiple versions exist, promote another version before deleting the current default. When using `azd`, deleting the only remaining version also removes the Toolbox.
One important connection to our example: its `postdeploy` hook promotes immediately. We should distinguish that sample behavior from a production process that validates a candidate version before promotion.
Deploy a Foundry Toolbox with GitHub Actions
In this example, the Toolbox is deployed as a separate step in the same GitHub Actions workflow, after the Bicep deployment provisions the Foundry Project. This lets the workflow populate the Toolbox’s `azd` environment with the infrastructure outputs before deployment. You can also split the deployments across jobs or workflows, provided the Toolbox step receives the required outputs and runs after its prerequisites are ready.
Prerequisites
- Foundry Project and region: Create the Foundry Project and any project connections required by the Toolbox before deployment. Confirm that the target region supports the Toolbox’s tool types and models using the tool support by region and model table
- Identity and access: Configure GitHub Actions to authenticate to Azure using OpenID Connect (OIDC), as in the linked sample. The identity that creates or updates Toolbox versions needs the Foundry User role on the project (Toolbox prerequisites). If the same workflow deploys Bicep, that identity also needs permission to deploy the template’s resources and create its role assignments at the applicable scopes.
- Tooling: Install Azure Developer CLI 1.37.0+, as required by the unified `microsoft.foundry` extension. Install the extension with `azd ext install microsoft.foundry`, following the Foundry extension installation guidance. The linked sample pins `azd` 1.37.1 and installs `azure.ai.toolboxes` separately.
Configuration
Provide the project endpoint, environment name, location, and every downstream endpoint or connection name referenced by the Toolbox’s `azure.yaml`. Create the required Foundry project connections before deploying the Toolbox. Configure credentials on those connections or in an approved secret store, not in Bicep outputs; see Toolbox authentication.
- name: Deploy and promote the toolbox working-directory: foundation/toolboxes/fibey-toolbox env: AZURE_ENV_NAME: ${{ steps.infrastructure.outputs.AZURE_ENV_NAME }} FOUNDRY_PROJECT_ENDPOINT: ${{ steps.infrastructure.outputs.FOUNDRY_PROJECT_ENDPOINT }} AZURE_AI_PROJECT_ENDPOINT: ${{ steps.infrastructure.outputs.AZURE_AI_PROJECT_ENDPOINT }} run: | azd deploy fibey-toolbox --no-prompt
The infrastructure deployment should expose the values the Toolbox needs as outputs—in this case, Bicep outputs. The linked sample uses `AZURE_ENV_NAME`, `AZURE_LOCATION`, `FOUNDRY_PROJECT_ENDPOINT`, and `AZURE_AI_PROJECT_ENDPOINT` for the deployment context. Its Toolbox configuration also consumes `INVENTORY_MCP_URL`, `WORK_ORDERS_API_URL`, `KB_MCP_URL`, and `KB_CONNECTION_NAME`. Expose the corresponding values for each target environment and region.
The Toolbox’s `azure.yaml` references the imported values, so the same definition can be reused across environments and regions. For each target, provide that target’s infrastructure outputs instead of manually changing endpoint values, and confirm that the required services and tools are supported in the target region.
The example references `steps.infrastructure.outputs` because the infrastructure and Toolbox deployment steps run in the same GitHub Actions job. If they run in separate jobs, expose the required values as job outputs and consume them through `needs`.
This keeps the deployments connected without tying their release cycles together: infrastructure provides the deployment context, and the Toolbox consumes it. Keep credentials in managed identities or approved secret stores rather than ordinary deployment outputs.
The complete workflow demonstrates authentication, infrastructure outputs, and environment initialization. Its extension-install step currently uses `azure.ai.toolboxes`; replace that step with `azd ext install microsoft.foundry` when following the current Learn guidance above. Version promotion is handled by the `postdeploy` hook in the Toolbox’s `azure.yaml`.
Verify Toolbox Deployment and Promotion
The sample’s `postdeploy` hook promotes the deployed version to the default and checks that promotion succeeded. Redeploying an unchanged Toolbox definition does not create a new version. To inspect the versions and confirm which one is default, run:
azd ai toolbox versions list fibey-toolbox
The default version is marked with `*`.
This confirms which version is default, but not that its tools work. For runtime verification, follow the Toolbox verification guidance to initialize MCP and list tools using the version-specific endpoint. Test a tool call only with a safe, read-only operation. The developer needs the Foundry User role on the project; prompt-agent and OAuth scenarios can require additional permissions for the agent identity or end user.
Troubleshooting
If deployment or promotion fails, check that the deployment identity has the required project role, that the project endpoint and Toolbox configuration values were supplied, and that the required project connections and tools are available in the target region.
Conclusion
Toolbox provides a shared way to manage tools across agents without tying their lifecycle to any one agent. Keeping toolbox definitions alongside your Foundry Project infrastructure, while deploying them as a separate step, lets teams update and version tools independently while retaining a clear dependency on the project.
As your organization adopts this pattern, consider who owns each toolbox, how changes are tested and promoted, and who can access its tools. That governance will help keep a useful Toolbox from becoming a Toolshed.
Pennsylvania, USA
We're introducing Claude Fable 5.2, Claude Fable 5.2 Fast, Claude Mythos 5.2, Claude Mythos 5.2 in Microsoft Foundry, expanding what teams can tackle with AI across software engineering, scientific research, and finance.
These are fields where the hardest work starts with an open question. An engineering team needs to find a root cause across several repositories. A researcher needs to test an approach and determine whether the results hold up. A financial analyst needs to uncover an edge case that changes the conclusion. Fable 5.2 and Mythos 5.2 bring new capabilities to work that depends on judgment, sustained investigation, and careful verification.
Fable 5.2 takes on bigger technical challenges
Claude Fable 5.2 and Fable 5.2 Fast are Anthropic's most capable generally available models for technical fields. It can take on large, loosely defined software projects, work across repositories and mono repos, and apply architectural judgment while testing its changes. Its willingness to revisit assumptions helps it find root causes that previous Claude models missed.
That ability extends to leading longer agent workflows. In Anthropic's testing, Fable 5.2 worked through ambiguous engineering problems for hours and up to days, coordinating subagents and flagging results that could not be reproduced. For developers, this opens up more ambitious tasks to delegate, with the model carrying work through successive rounds of implementation and verification.
The same approach supports scientific and financial work. Fable 5.2 can help formalize mathematical proofs, develop methods for difficult physics computations, and investigate subtle edge cases in quantitative financial analysis.
Mythos 5.2 brings specialized capabilities to cybersecurity and life sciences
Claude Mythos 5.2 and Mythos 5.2 Fast are Anthropic's most capable models for security engineering and life sciences. For authorized security teams, it supports challenging work such as hardening systems and understanding undocumented software. In Anthropic's testing, it improved on previous Claude models in building defenses and analyzing undocumented binaries for potential vulnerabilities.
For life sciences teams, Mythos 5.2 can help synthesize literature, orchestrate analyses, and support basic and translational research, with particular strength in biomolecular design. Access is limited to authorized customers through Anthropic's verification programs.
Pricing
|
Model |
Deployment Type |
Input/M Tokens |
Output/M Tokens |
Cache Read |
Cache write |
Batch I/P |
Batch O/P |
Availability |
|
Claude Fable 5.2
|
Global Standard, US DataZone |
$8 |
$40 |
$0.20 |
$10 |
$4 |
$20 |
GA, Hosted on Anthropic |
|
Claude Fable 5.2 Fast |
Global Standard, US DataZone |
$16 |
$80 |
$0.40 |
$20 |
NA |
NA |
GA, Hosted on Anthropic |
Stronger alignment and safeguards
Anthropic ran its alignment testing on Mythos 5.2, the same underlying model as Fable 5.2 without Fable 5.2's cyber and bio safeguards. Mythos 5.2 scored lower than Opus 5.5, Sonnet 5.5, and Mythos 5.1 on behaviors including hallucinating inputs, falsely claiming to have completed a task, and omitting important information. Anthropic expects Fable 5.2 to behave similarly. Anthropic has also included safeguards intended to reduce misuse in cybersecurity, life sciences, and distillation. Where a cybersecurity or biology query is blocked, customers instead receive a response from Opus 4.8 for cybersecurity and Opus 5 for biology. Fable 5.2 and Mythos 5.2 are covered models, which require data retention for safety monitoring. Until Enterprise Frontier Safeguards is available, eligible customers can use Fable 5.2 with zero data retention.
Explore Claude Fable 5.2 and Claude Fable 5.2 Fast in Microsoft Foundry for your most demanding technical projects. For Claude Mythos 5.2, contact your Microsoft account team to confirm eligibility and access.
Pennsylvania, USA
We're excited to announce the next evolution of Windows settings backup and restore (formerly, Windows Backup for Organizations). It's built to support continuity as organizations refresh hardware, reimage devices, or prepare for recovery scenarios. Now, the experience is evolving into a baseline resilience capability across Windows.
At a glance, the four improvements are:
How it all started
In August 2025, the then-called Windows Backup for Organizations became generally available. It gave your organization a policy-controlled way to back up Windows settings and the list of installed Microsoft Store apps, then restore them on eligible Windows devices. Soon after, first sign-in restore scenarios expanded these capabilities beyond OOBE to support more device types and hybrid-managed environments.
Each milestone served one simple vision: when employees transition to a new, reset, or reimaged PC, their familiar Windows experience should be ready to move with them. This vision now extends beyond protection to making the experience easier to manage, more transparent, and more resilient by design.
The four-phased evolution
A clearer name: Windows settings backup and restore
Windows Backup for Organizations is now Windows settings backup and restore. The updated name more clearly reflects the capability's scope and its role within the broader Windows resilience experience. It's your unified approach to Windows settings continuity that brings backup, restore, and roaming together. Use it to preserve and restore supported Windows settings and Microsoft Store app list during device transitions, while supported settings continue to roam across devices.
What it means for IT: No action. No policy migration or reconfiguration is required. Existing settings, Cloud Solution Providers (CSPs), and Group Policy paths remain unchanged.
Enterprise State Roaming (ESR) management, now unified
You'll now manage Enterprise State Roaming (ESR) through Windows settings backup and restore. This brings roaming alongside backup and restore within the same policy-based management experience.
ESR enables eligible Windows settings to roam across devices associated with a user's Microsoft Entra ID account. The two capabilities address different moments in the continuity journey:
-
Roaming helps supported settings stay consistent across devices.
-
Backup and restore preserve supported Windows settings and Microsoft Store app list through device transitions.
What it means for IT: The set of settings supported by ESR is unchanged. Only the management experience has moved. Following the transition period that ended in June 2026, Windows settings backup and restore policies are now the supported management path for ESR. ESR continues to be subject to applicable licensing requirements.
Windows settings backup becomes the default
Windows backup is becoming a new resilience baseline. Starting with Windows 11, version 26H2, backup is enabled by default on eligible devices. This way, supported Windows settings and Microsoft Store app information are protected before they are needed.
IT remains in control. Any explicitly configured backup policy, whether enabled or disabled, continues to be honored. Importantly, this change applies to backup only. Manage the restore capability separately as it requires explicit administrator configuration. Learn more about the default-on experience.
PowerShell scripts to manage backup profiles
The default-on experience makes it increasingly important for you to have visibility and control over backup profiles. To simplify backup-profile management, Microsoft provides the WindowsBackupAdmin PowerShell module. It gives appropriately permissioned administrators an easier way to manage Windows settings backup data without working directly with the underlying Microsoft Graph beta APIs. Use the PowerShell scripts to:
-
View attributes to understand the backup profiles associated with users. Access to the settings or app data within the backup isn't included.
-
Export backup information when needed for administration and governance.
-
Delete a user's backup data or profiles to support lifecycle-management scenarios, such as cleaning up backup data that is no longer required.
The scripts wrap existing Microsoft Graph beta APIs, providing a simpler management experience. Access them through the PowerShell Gallery or GitHub.
What it means for IT: You're in control. Once you decide the backup default for your environment, use the PowerShell module to manage the backup profiles that accumulate over time. These practical controls for administrators support the stronger backup baseline for users.
Restore becomes visible with restore summary
Starting with Windows 11, version 24H2, Windows settings backup and restore introduces restore summary. Moving to a new PC should feel like picking up where you left off, not starting over. By making restore outcomes visible, restore summary helps make device transitions more transparent and predictable. Users can quickly understand what was restored from their personalization settings and Microsoft Store app list. Then they'll validate their setup and get back to being productive with confidence.
During device setup or at first sign-in, users select a backup profile and complete the restore process.
Then, there are two ways to access restore summary:
-
Restore summary notification: After the restore process, a restore summary notification appears on the new device.
Selecting View takes users to the Settings page, where they can select the Restore summary link. The summary opens in the browser to help users review what was restored.
-
Restore summary settings page: Alternatively, users can access restore summary by going to Settings > Accounts > Windows backup and selecting a link next to Restore Summary. It opens in the browser as shown.
Note: Restore summary becomes available approximately one hour after a successful restore. Access it from the Windows notification or from Settings for a limited period of 7 days following device setup.
What it means for IT: Clarity about what was restored reduces the uncertainty that often follows a device refresh or replacement. Use it for smoother onboarding and recovery, helping reduce avoidable support requests.
The journey continues
New device. Same setup. Less friction.
In just over a year, Windows settings backup and restore developed a clearer identity, a stronger default, a unified policy experience, and a visible restore outcome. This improved experience is simpler for employees, smarter for administrators, and more resilient for organizations.
We've also experienced the value of this approach within Microsoft, where backup policies have been deployed across the organization.
|
"Windows Backup for Organizations is changing how device refresh works. Pressure tested inside Microsoft on a global scale, it enables Microsoft Store apps and user settings to move seamlessly with our people and free IT teams from the heavy lifting of device reimaging. The result is a simpler, more resilient experience." — Brian Fielder, Vice President, Microsoft Digital |
This internal deployment reinforces what we continue to hear from organizations: resilience works best when protection is already in place, recovery operates within organizational policy, and users can return to a familiar experience and productivity with less uncertainty.
Your feedback has been instrumental in shaping these experiences. We look forward to evolving the product based on what matters most to you and your organization.
Learn how Windows settings backup and restore fits into the overall Windows device recovery framework.
Additional resources:
Continue the conversation. Find best practices. Join the Windows Tech Community.
For updates on new releases, tools, and resources, bookmark the Windows IT Pro Blog and follow @WindowsUpdate on X. For the latest on how Windows is evolving for organizations and the people who support them, follow Windows at Work on LinkedIn.
Pennsylvania, USA
Next Page of Stories