Every week, Frank and I record Merge Conflict, and Zencastr hands me a ZIP with a transcript, an MP3, and a video. That part is great! What comes next is about an hour of busywork, by hand, every week: renaming files, making a thumbnail and captions, and uploading everything to YouTube, Patreon, and our podcast host...
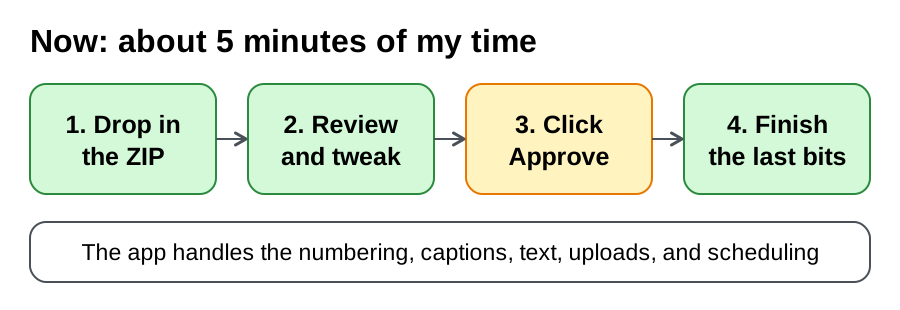
So I sat down with GitHub Copilot in VS Code (specifically the Agents window) and built a little dashboard to do it for me. Now I drop in the ZIP, review what it came up with, and click one button. That's about five minutes of my time.
One thing up front: it isn't all automated (yet). There are still a few steps I do myself, and I'll show you which ones. Want to see it in action first? Here's the full demo:
Now let's take a look at how it all works!
The hour I wanted back
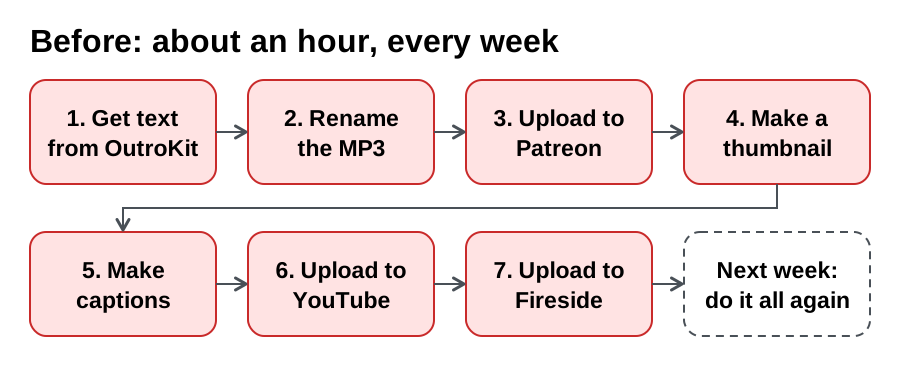
Here's what publishing an episode used to look like:
None of it is hard. It's just a lot of steps, every single week. So I typed that list into Copilot, attached that week's ZIP and our thumbnail overlay, and ended with one question:
What could we build to automate this all for me?
That was at 8:01 AM. I stepped away, and when I came back around 8:24 AM, the app had already imported that real ZIP! Then I took a 12-hour break to enjoy the day, came back, and approved everything within minutes. All told, it took about an hour of hands-on time to go from idea to production, and now I have a repeatable process I can use every week.
What we built
It's a local dashboard that runs on any OS, built with Blazor on .NET 10. Why Blazor? I love .NET, OutroKit is all .NET, and it gives me the most flexibility in my workflow.
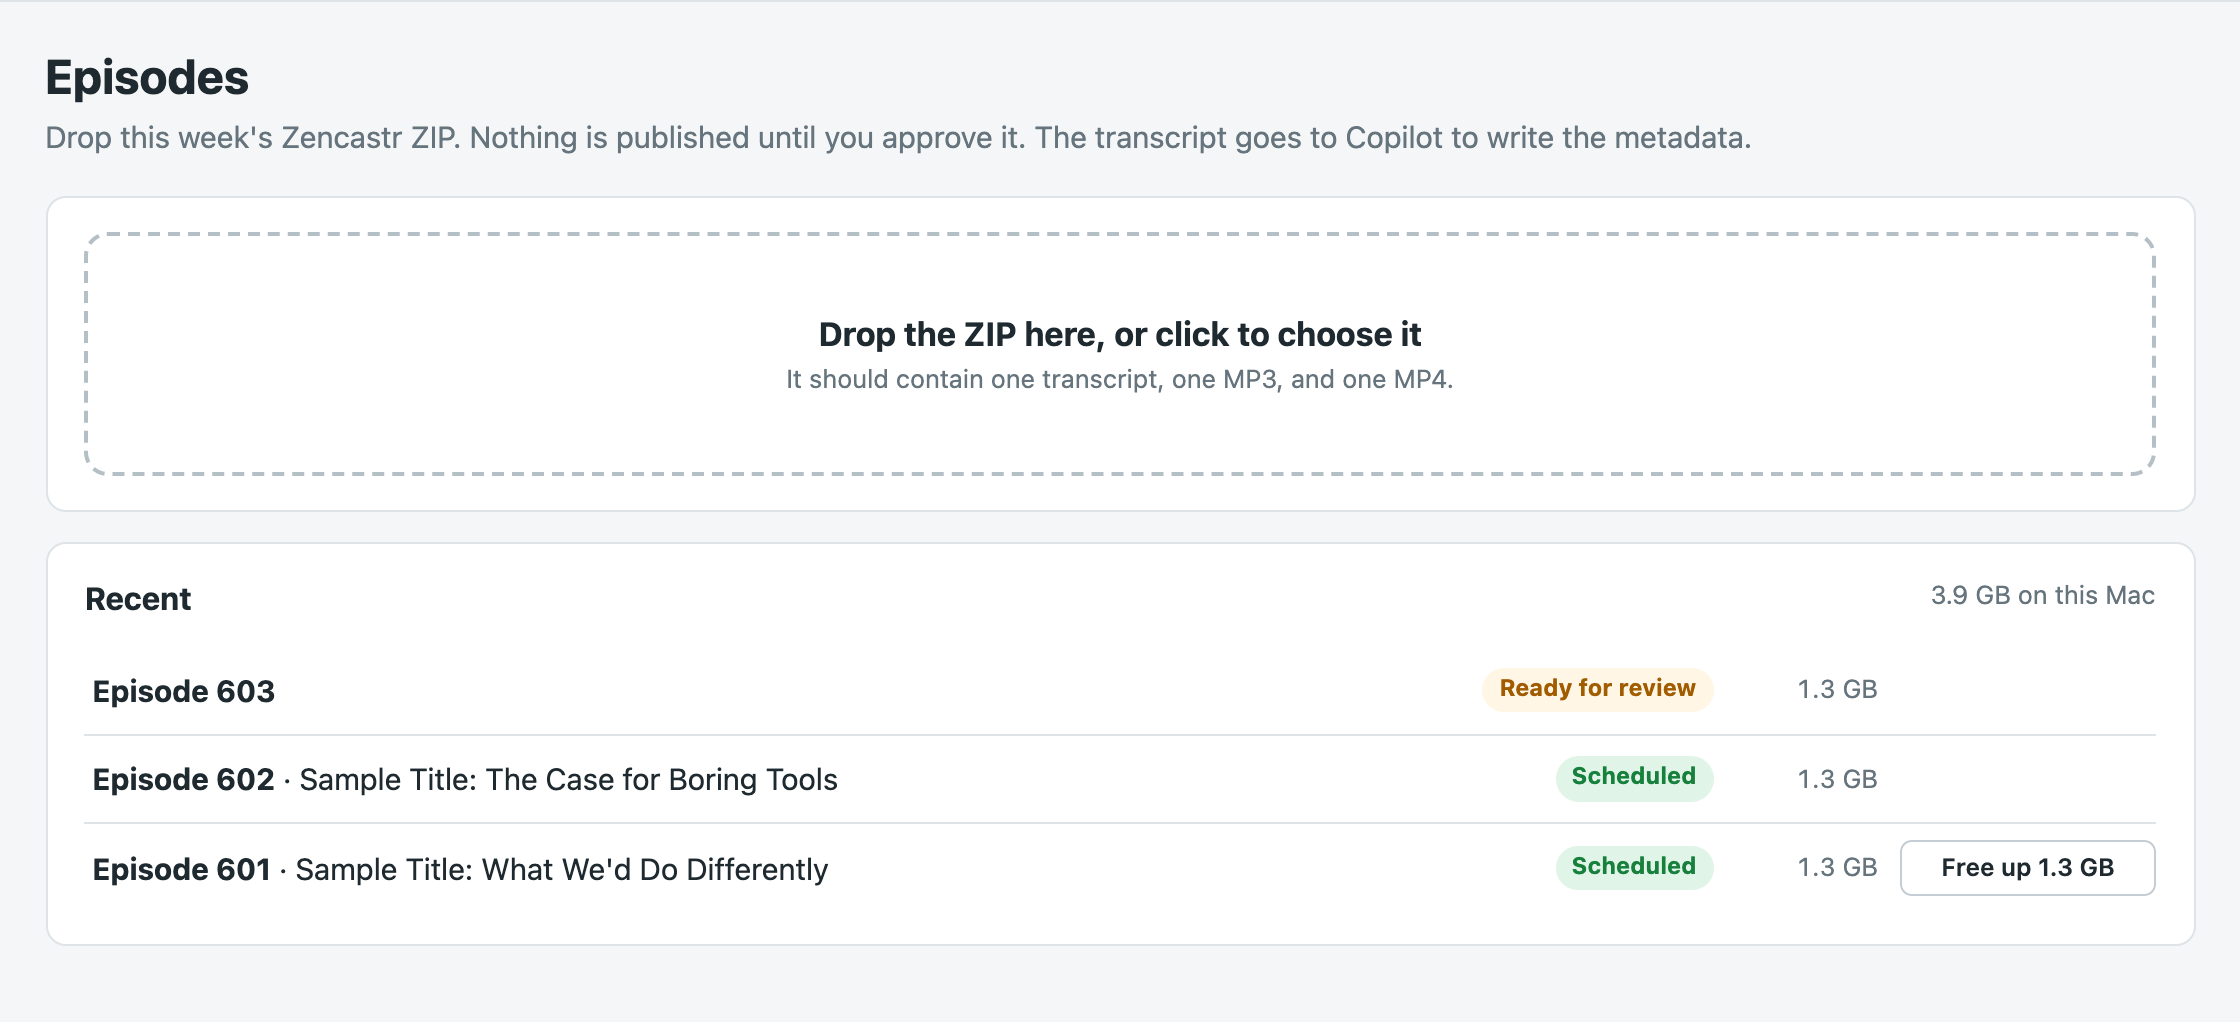
You start by dropping in the ZIP:
The episode list. All of the app screenshots in this post use sample data.
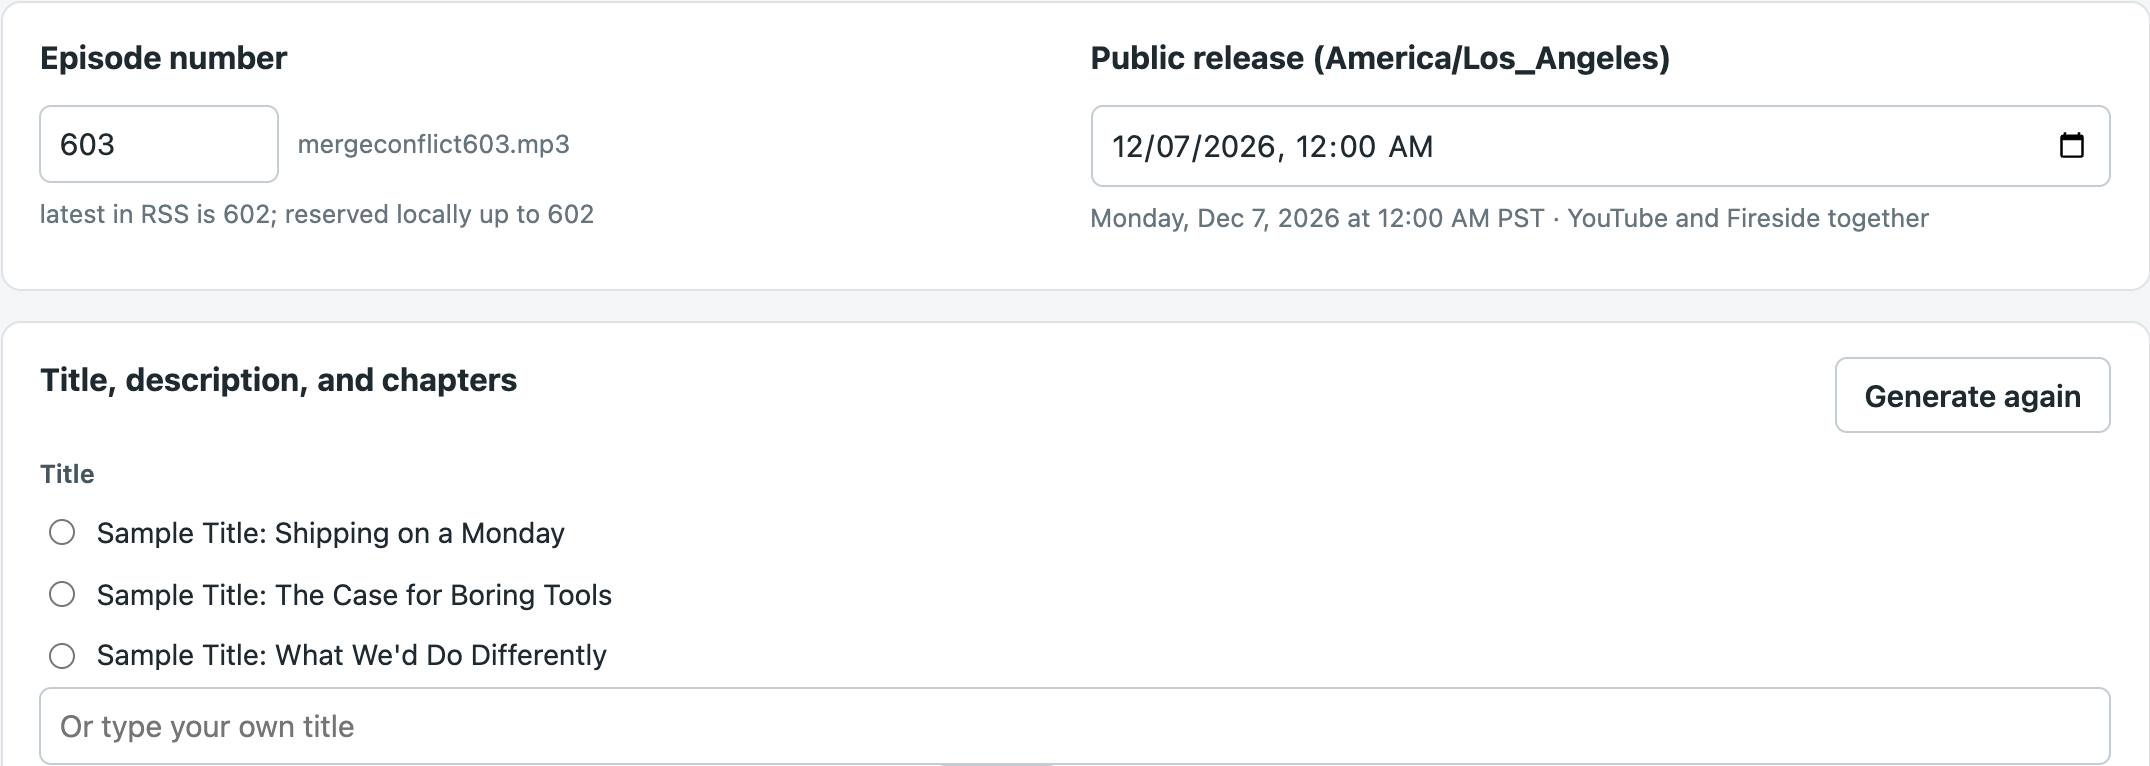
The app then does the prep work. It suggests the next number from the feed and any Fireside drafts, makes the numbered MP3, converts the captions, gets the text from OutroKit, and sets the release to next Monday.
Everything is ready for me to review and change.
Nothing goes public while it does that. I still read it all, pick a title, and make the thumbnail. The transcript does go to Copilot, because that's how OutroKit writes the text.
One click, and what it promises
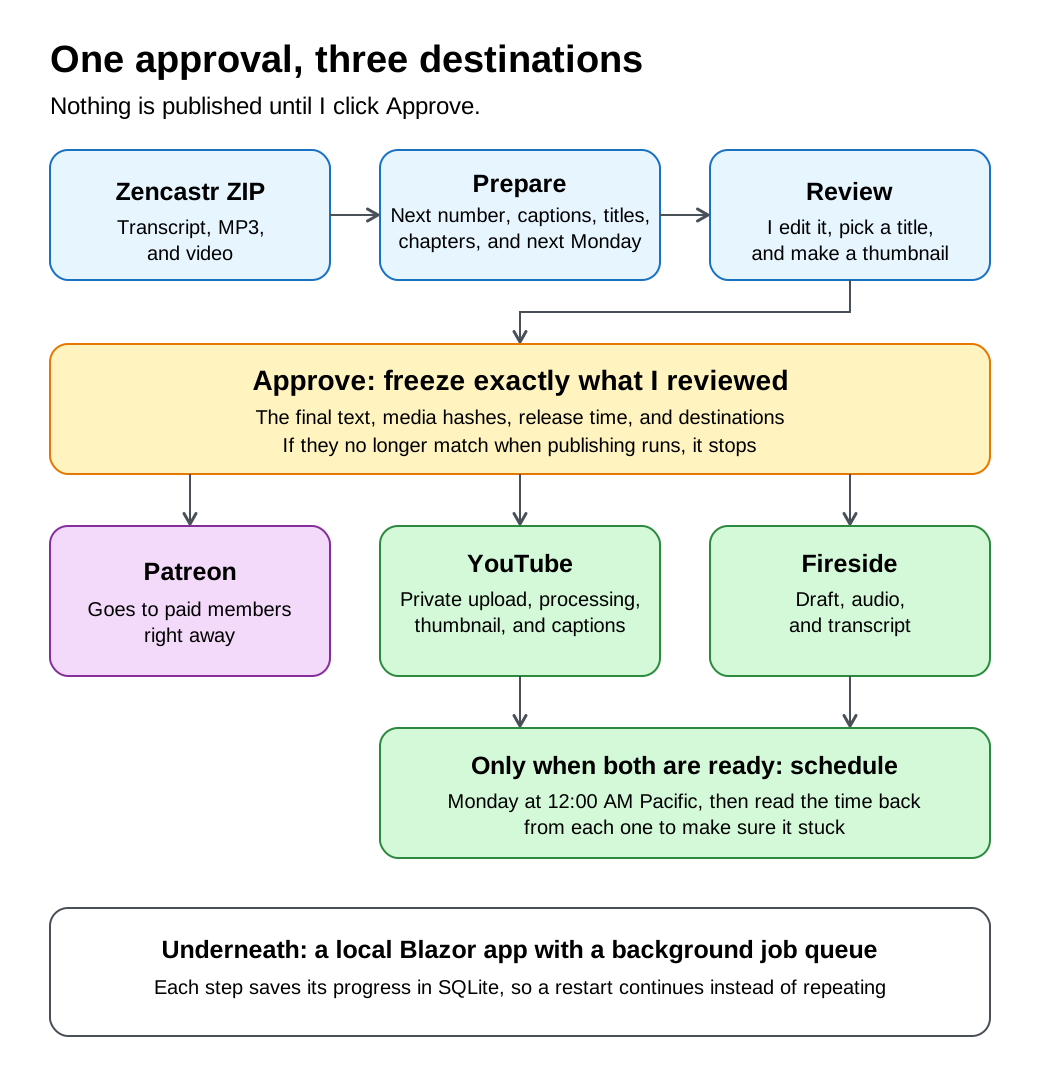
Here's how it all fits together:
The whole flow, from ZIP to release.
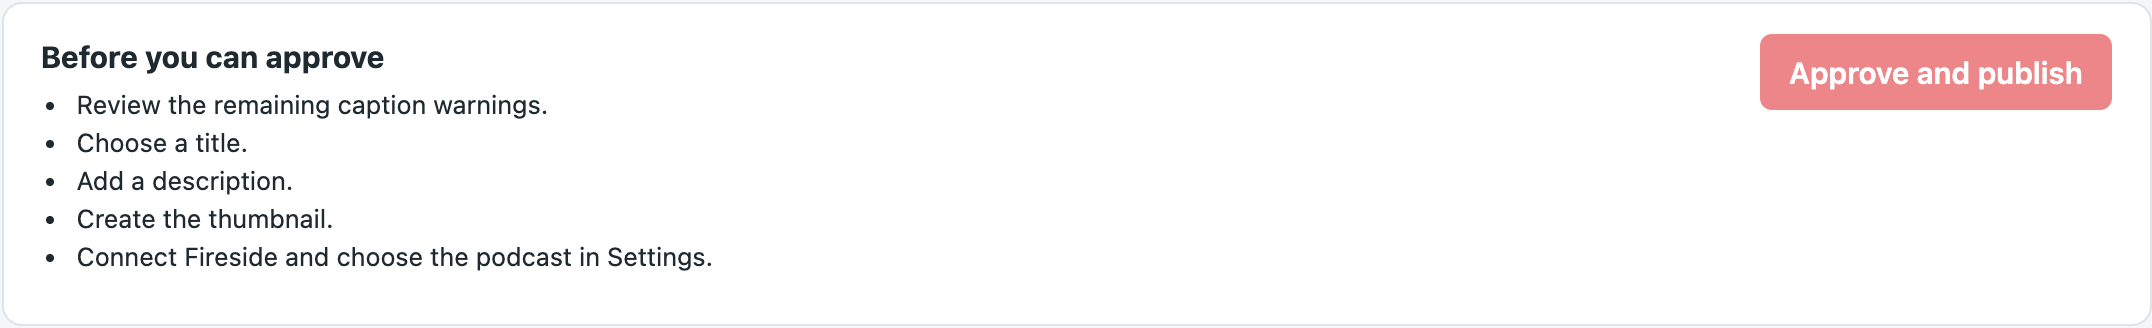
This is the heart of the app. One button is going to send something out to three different places, so that button had better mean something. The approve button stays disabled until the episode is actually ready:
The app tells me exactly what's left.
When I do click it, the app freezes a snapshot of the final text, the media file hashes, the release time, and the destinations. Then, every time a publishing run starts or restarts, it builds that snapshot again and compares:
varcurrent=awaitapprovals.BuildSnapshotAsync(episode,settings,cancellationToken);if(ApprovalService.Hash(current)!=episode.Approval.SnapshotHash){awaitstore.UpdateAsync(id,e=>{e.Approval=null;e.AddLog("Stopped: the episode changed after approval, so nothing further was sent. Review and approve it again.",isError:true);});return;}
So if the text, a media file, or the release time no longer matches what I approved, it stops and asks me again. A few YouTube settings like tags, category, and the playlist sit outside the snapshot, so changing those won't cancel anything.
From there, YouTube and Fireside are both staged privately, and neither gets scheduled until both are ready. Long uploads run in a background job, and each step saves its progress, so a restart picks up where it left off. API keys stay in the operating system's secure storage.
The app also doesn't take "success" for an answer. After it schedules a video, it asks YouTube what it actually saved:
awaityouTube.SchedulePublishAsync(videoId,snapshot.ReleaseAtUtc,settings.YouTubeMadeForKids,cancellationToken);varvideo=awaityouTube.GetVideoAsync(videoId,cancellationToken);if(video?.Privacy!="private"||video.PublishAt?.ToUniversalTime()!=snapshot.ReleaseAtUtc.ToUniversalTime()){thrownewUserFacingException("YouTube accepted the schedule but didn't report it back correctly. Check YouTube Studio.");}
Fireside gets the same treatment. When you're scheduling something that goes out at midnight while you're asleep, you really want that check.
A real episode found two OutroKit bugs
OutroKit is my own open source .NET tool that writes the titles, descriptions, chapters, and subtitles for an episode, using the GitHub Copilot SDK. So hooking it up was the easy part. The app runs a pinned version as a local tool and reads back its JSON:
publicasyncTask<IReadOnlyList<string>>ConvertToSrtAsync(stringtranscript,stringoutput,CancellationTokencancellationToken){varoutcome=awaitRunAsync(["srt","convert",transcript,"--output",output,"--overwrite"],cancellationToken);if(outcome.ExitCode!=0||!outcome.Success){thrownewUserFacingException($"Caption conversion failed: {outcome.ErrorMessage}");}returnoutcome.Result.TryGetProperty("warnings",outvarwarnings)?warnings.EnumerateArray().Select(warning=>warning.GetString()??"").ToList():[];}publicasyncTask<CaptionReport>FixCaptionsAsync(stringinput,stringoutput,CancellationTokencancellationToken){varoutcome=awaitRunAsync(["captions","fix",input,"--output",output,"--overwrite"],cancellationToken);// Exit 4 means the fixed file was saved and readability findings remain for review.if(outcome.ExitCodeisnot(0or4)){thrownewUserFacingException($"Caption check failed: {outcome.ErrorMessage}");}returnParseCaptionReport(outcome);}
Then a real transcript showed up and found two bugs. When Frank and I talk over each other, Zencastr's timestamps land slightly out of order, and that pushed the captions about 3 minutes late by the end of the episode. OutroKit also dropped a line that just said "Like this," because it looked like a speaker's name.
The app worked around both for episode 540, correcting 24 out-of-order turns and saving that one line. I then fixed both in OutroKit itself, which is exactly why you run your tools on real data!
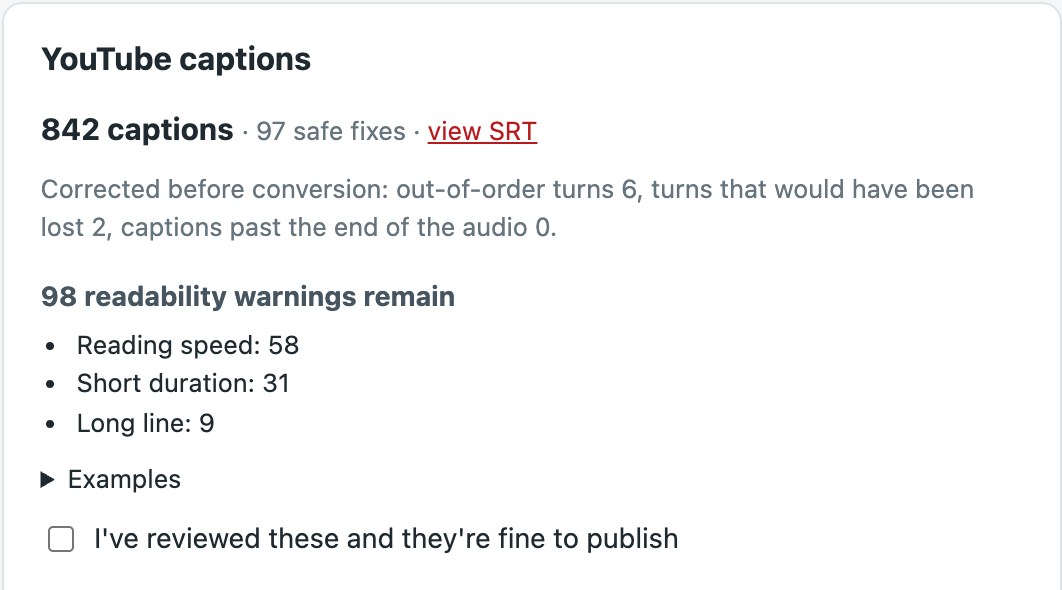
The captions card, with made-up numbers. The real episode came in at 1,016 captions with 276 safe fixes and 411 readability warnings left for me to review.
This is also why the review step matters. OutroKit gave me 10 title options that week, and one of them said ".NET Conf 2024." Close!
AI never touches the logo
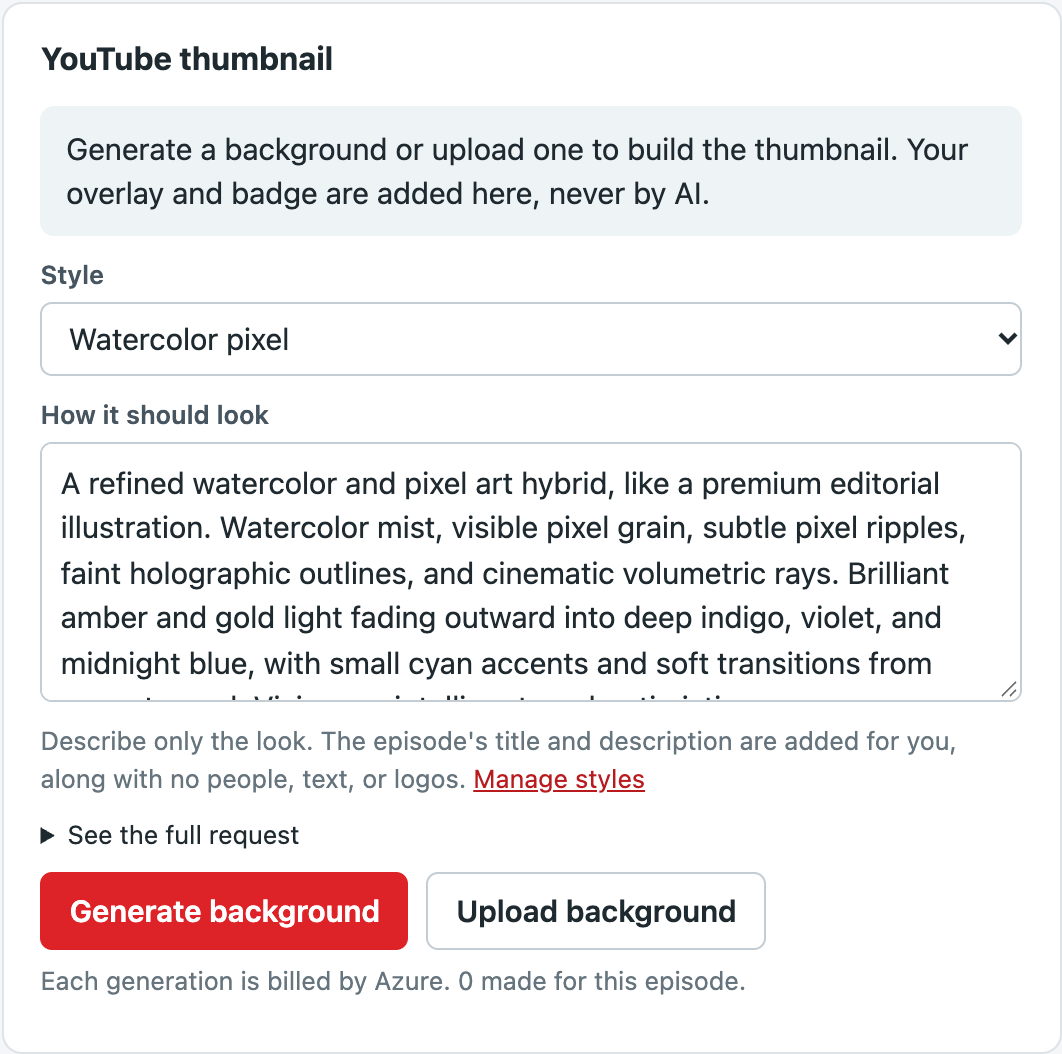
Now for the thumbnails. Here's what I told Copilot: "For the image generation, I never want people and have a specific look." The app uses image generation on Microsoft Foundry to make only the background. It then adds our real overlay and episode badge on top, right on my machine, so the branding is always exactly right.
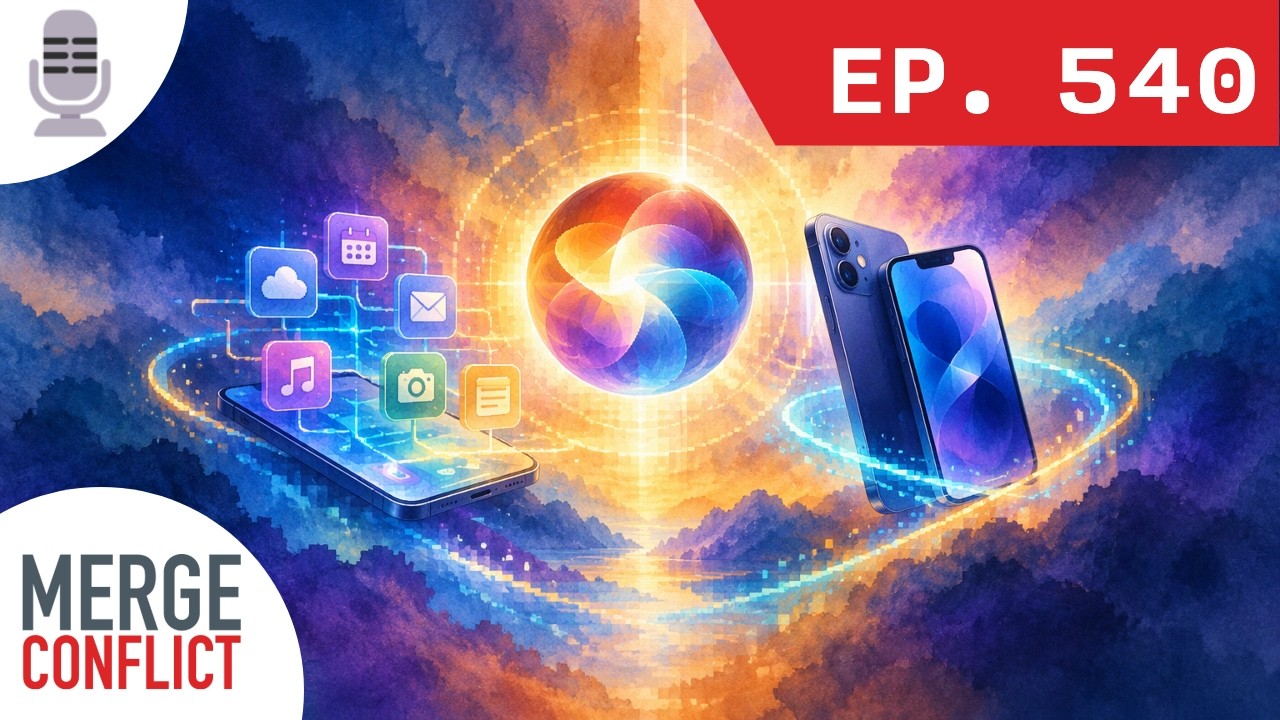
The real episode 540 thumbnail, rendered through the app. The art is AI, and the logo and badge are not.
Every prompt asks for no people, text, or logos. Image models don't always listen, though, so I still check each one.
I also wanted more variety: "We should also include the episode title and description so it is unique." So there are five built-in styles, and each prompt gets that episode's details.
Pick a style, tweak the wording, and generate. I only pay when I click.
The wins, and what's still on me
So what does all of this get me? Here's everything I don't do by hand anymore:
The episode number: the app finds the next one from the feed and Fireside, names the MP3 to match, and stops me if a number is already taken.
The writing: titles, descriptions, and chapters are waiting for me when I open the episode.
The captions: they get converted, cleaned up, and checked for readability.
The thumbnail: fresh art in the style I pick, with the real logo and badge added for me.
YouTube: the video, details, thumbnail, captions, and playlist are all handled, scheduled for Monday at 12:00 AM Pacific, and checked.
Fireside: the draft, details, audio, and transcript are all handled, scheduled for the same time, and checked.
The X post: it's written and ready to go in the composer.
Cleanup: after the release, one click frees up the big video and audio files.
And here's what's still on me:
Reviewing everything and clicking Approve. That one's on purpose!
Publishing the post on Patreon.
Adding header image in Fireside.
Scheduling the post on X.
Episode 540 went out at midnight, right on time. Not bad for a little dashboard!
Wrapping up
An hour down to about five minutes. I'll take it!
The thing I keep coming back to is how much of this came from using it. The first version came together fast, but the best parts showed up when a real episode hit something weird and I could just say so. If you have a chore you do every single week, give it to GitHub Copilot as a real task and see what you build together. Keep a human in the loop for the part that goes out to the world, and make your app check its own work.
Want to see the result? Check out episode 540 of Merge Conflict, and take a look at OutroKit if you make a podcast too. Happy publishing!
It's been a little over a week since I published my game, and I can say now it's a success! Like I've mentioned previously it's up to YOU to define what success means to YOU. It can be just publishing a game, it can be 10 copies or 1 million copies sold, it's up to you to define that.
In my case, for this game I really just needed a demo game so I could make my Steam course therefore I didn't really need the game to sell any copies, so my goal was simply selling 200 which would make about $1000 gross revenue which is a nice fun round number. And right now it's at 323 copies sold! Yay!
More importantly, the Median Play Duration is currently at 2 hours 3 minutes! That means players are really enjoying the game! Awesome!
The one thing I would like is to have it hit 10 reviews, so if you have picked up the game (I hope you enjoyed it!) then please write a reviewMany thanks!
Game Dev: Unity is giving indie devs $500,000, and 2027 looks AWESOME!
Unity is giving indie devs $500,000, and 2027 looks AWESOME!
Unity just had their Unite conference this week and they shared some massive news, there is a lot to be excited about for the future!
First, the Unity Fellowship will give 10 indie teams $50,000 each, alongside expert guidance, industry connections, and marketing support. No recoup, no revenue share, and you keep your IP. That is an awesome opportunity for a small team trying to finish their game!
Applications close on December 18. You need a playable Unity game and should expect to be roughly a year from launch when the program starts in March 2027. If your project fits, I would definitely look into applying. There are no strings attached, it is literally free money! I wonder how many submissions they will get.
Secondly there is Unity acquiring Synty Studios! This is crazy unexpected! I’m a big fan of their low-poly artstyle, so I’m very curious about this. It seems the main reason Unity bought them is to integrate their assets into Unity Spark, their upcoming browser-based game creation platform. They're really investing in that, I'm guessing with the hopes of taking a chunk out of Roblox.
Right now there are no plans to change pricing or anything, but I do wonder if in the future they will start to include some assets in the Unity Pro plan? Or what will happen to Unreal/Godot users of these assets? They said nothing is changing right now, the existing packs will be multi-engine forever, but I assume future packs will be Unity only.
And then there is Unity 7 itself. CoreCLR and ECS for All are major changes to the engine's foundations. The graphics updates are especially exciting. Unity 6.7's URP updates include real-time global illumination, improved ambient occlusion, Screen Space Reflections, and Shader Graph stencil support. Those are some seriously useful additions for making our games look better.
There is also a new Asset Library tool that searches both assets you own and the Asset Store, merging Netcode into one, more improvements to 2D rendering and 2D physics, support for more platforms like Meta VR Glasses, etc, etc.
Personally, I really like the current direction of Unity. Better graphics, easier workflows, stronger technical foundations, and so much more.
Unity 7 is shaping up to be an awesome release. I can’t wait to see what will happen in 2027!
I really can't wait for Unity 7, seems like such a massive leap forward, the future is looking bright for Unity devs! Are you going to apply for the Unity Fellowship? If you're eligible it's hard to say no to free money!
The Unity Asset Store Black Friday Sale is here, with 50% OFF selected assets, including lots of useful tools, 3D art and VFX!
Check out the Flash Deals for discounts of up to 95% OFF. These offers are available for a limited time, with new deals arriving throughout the sale!
Browse the sale HERE. The Publisher of the Week FREE Asset promotion returns on December 10.
My Code Monkey Bundle is BACK to celebrate the End of Summer with 80% OFF!
You’ve got 12 of my courses covering C#, Problem Solving, Multiplayer, DOTS and tons more, plus 9 of my Steam games and 1 month of my Game Dev Practice Lab to put those skills into practice!
Grab the whole bundle 80% OFF with coupon SUMMER2026. Get it HERE!
Tech
Programming legends Are at War Over AI
AI is the current hot topic, it's hard to have rational discourse because so many people are zealots pro-AI or zealots anti-AI. But instead of looking at random commenters or redditors, what do the pros really think?
It turns out the biggest programming legends also don't quite agree on AI. This interesting video brings together perspectives from Linus Torvalds, Bjarne Stroustrup, Jonathan Blow, Uncle Bob and others, with very different conclusions.
Linus is particularly interesting. The video contrasts his earlier frustration with the hype with his more recent defense of AI as a useful tool for Linux development. He acknowledges the problems, but wants the tools to help developers, and doesn't support banning others from using them. Personally, my views have also changed quite a bit similar to his. I was definitely skeptical for the past few years until the latest models released about three months ago, and since then I've been continuously impressed by how capable they've become.
However, I also agree with Bjarne's concerns about safety-critical code. He specifically questions whether these tools are suitable for software where safety and performance are essential. I certainly wouldn't want air traffic control software or bank software to be blindly vibe coded! Although using AI to help torture-test human-written code and look for things the developers missed sounds like a very useful application to explore.
Uncle Bob's approach is especially interesting. He has largely stopped reading generated code, instead relying on extensive tests, quality checks and human oversight to build confidence in the result. The idea is that sufficiently strong guardrails could let you benefit from the speed without inspecting every single line. That's an interesting approach, although passing tests obviously doesn't guarantee you've caught every possible problem.
There are a bunch more quotes in the video, I highly recommend you give it a watch. Thoughts from Skeptics, Converts, and Pragmatists.
I am very curious to see where everyone will stand a year from now. Will the people avoiding AI today still avoid it, or will improvements change their minds? Mine certainly changed as the models have improved, and I assume as they keep improving they will convert more and more people.
Want to get the most out of ChatGPT?
ChatGPT is a superpower if you know how to use it correctly.
Discover how HubSpot's guide to AI can elevate both your productivity and creativity to get more things done.
Learn to automate tasks, enhance decision-making, and foster innovation with the power of AI.
Take-Two said that GTA 6 generated $3.79 billion in worldwide day-one retail sales, calling it the biggest entertainment launch in history. It also reported 32.5 million copies sold BEFORE release. Absolutely insane!
In the indie world, making $1 million can be a massive, life-changing hit. GTA 6 just generated 3,790 TIMES that amount in retail sales. In ONE DAY! Crazy!
And the critical reception is just as impressive. Both Metacritic and OpenCritic currently have it at 99/100, that is basically perfect! After so many years of hype, thankfully it seems the hype was very well deserved.
As I mentioned in the last newsletter, I’ve been really curious to see whether GTA 6 could give the wider industry the boost so many people have been hoping for. This is certainly an enormous start.
The exciting possibility is what happens AFTER people play it. Maybe someone finally bought a new console for GTA, and once they finish, they start looking for something else? Another big release, a smaller game, perhaps an interesting indie they would otherwise never have discovered.
That is what I would love to see: this excitement turning into more opportunities for other developers too!
Are YOU playing it? Is it living up to the hype?
I have been so insanely busy this week that I haven't had time to touch it at all, but I really want to! Have you started playing it? Are you enjoying it? I've loved every GTA I've played so I assume I will enjoy it as well.
Get caught up on the latest technology and startup news from the past week. Here are the most popular stories on GeekWire for the week of Nov. 15, 2026.
Amazon founder Jeff Bezos said Tuesday that Nvidia should promote from within if it doesn’t bring back Jensen Huang as CEO. Nvidia’s board chair said the same day that the board does not intend to reinstate Huang. Read More… Read More
The comedy show’s fake ad has John Mulaney handing care of his agin father off to his sister. Melinda French Gates says it’s funny because it’s true, and she has the data to show it. Read More… Read More
ULA’s Vulcan rocket failed about 10 minutes into flight Sunday, the company’s first total mission failure, losing 40 satellites for Amazon’s Leo internet service and disrupting Amazon’s plans for a second Vulcan launch within weeks. Read More… Read More
United Launch Alliance says preliminary findings show Vulcan’s two BE-4 engines didn’t get enough fuel from the rocket during Sunday’s failed launch, and that the engines’ own performance wasn’t the problem. Blue Origin’s New Glenn uses the same engines. Read More… Read More
Microsoft says the bug behind last week’s global Outlook outage hit only newer servers in a key part of its network, and tests run on older ones missed it. Its final report lists 13 fixes, including steps to keep a failure in one part of the world from spreading. Read More… Read More
Microsoft CEO Satya Nadella opened his Ignite keynote by addressing last week’s global Outlook outage, calling digital infrastructure “the dial tone for the world.” Microsoft’s final report on the outage is due Nov. 20. Read More… Read More
Noeri, an AI startup co-founded by Stanford professors Yejin Choi and Carlos Guestrin, has raised $110 million in a round led by Menlo Ventures. Its software studies a company’s data and workflows and proposes changes to the instructions, tools and models behind its AI systems, with a person reviewing each proposed change. Read More… Read More
A Microsoft Research senior director has left to launch a stealth startup, while two new leaders join; former DoorDash VP is now CEO and president of the Space Needle and Chihuly Garden and Glass; past Huntr CEO leaves Palo Alto Networks to found a startup; and other personnel changes. Read More… Read More
About 60,000 Microsoft employees have until early December to decide on the company’s voluntary exit offer. A former Microsoft general manager and startup founder looks at the job market, startup funding and the question most people skip: what do they want? Read More… Read More
When I compared Anthropic’s Fable 5.2 vs. OpenAI’s GPT-6 Astra last week, Fable 5.2 was slightly more accurate (149 points vs. 145). But it cost 3.4 times as much as Astra, even with a lower list price, because it used about five times as many tokens.
Then, on Tuesday, November 17, OpenAI released GPT-6.2 Astra with a 20% price cut. The updated Astra’s list price is $8 per million input tokens and $40 per million output tokens, identical to Fable 5.2’s, removing Fable 5.2’s list-price advantage. The question now is which model does more with each token.
It’s no surprise that both companies say theirs does. OpenAI says the upgraded Astra beats Fable 5.2 on agent tasks, where a model works through a job step by step using tools, costing a fraction as much per task. Anthropic says Fable 5.2 is the stronger coder, and it scores higher on FrontierCode 2.0, the coding benchmark both companies report.
The launch got mixed reviews, though. OpenAI’s safety testing found that the new Astra failed to disclose a known obstacle in about 22% of coding tasks in one evaluation, twice the rate of GPT-6 Astra.
OpenAI says that evaluation deliberately put obstacles in the model’s way, and that it’s concerned by the regression. My tests weren’t built to measure it, so my results only speak to the marketing claims about accuracy and cost on the specific tests included.
The tests
In the last round of testing I did on these models, the scores were incredibly close. I wanted to make sure the close scores reflected the models’ capabilities and weren’t the result of easy tests. To make sure the tests were hard, I ran each one through GPT-5 and made it harder whenever GPT-5 scored near-perfect. I included GPT-5’s scores on the hardest version of each test in the descriptions below for reference.
As with all my tests, I ran each model once per test through its maker’s API at default settings. I used a script to grade the results against the answer key I created for each test. Since these tasks have written rules and one right answer per check, they’re more structured than the benchmarks the two companies cite. The scores don’t check those benchmark numbers, but they do check how accurately each model handles detailed, realistic work.
Here are the tests:
Month-end close (173 points) – I gave the model a fake software company’s billing system, contracts, payments, outage history, and team chats for 40 customers. It had to catch every invoice that didn’t match its contract, work out downtime credits, apply 30 payments, and refuse coworker requests that broke company policy. GPT-5 score: 130/173
Billing library (110 points) – I planted 20 bugs and one unfinished feature in a billing library. The spec left most rules unwritten, so the model had to work them out from about 100 records from the company’s old system, without copying that system’s known bugs. Three of the library’s own tests are wrong, and the model should report them without editing them. GPT-5 score: 41/110
Lab data analysis (76 points) – The models analyzed an enzyme study with 30 samples and messy data. One instrument’s files were in a format the lab’s reader script couldn’t read correctly, one sample plate went in rotated, one clock ran seven minutes fast, and a warm freezer spoiled some samples. GPT-5 scored 57/76
Month-end close
This was the agent test, where OpenAI’s marketing says Astra leads. Both models scored a perfect 173 out of 173. Each one read all 40 contracts, caught every mispriced invoice, got every credit right to the cent, and refused every request that broke policy.
“For the same score, Fable 5.2 cost four times as much and took about three times as long.”
Similar to the last round of testing, the difference came down to effort. Fable 5.2 spent more than 19,000 tokens on reasoning, and Astra spent 830. For the same score, Fable 5.2 cost four times as much and took about three times as long. That’s going to add up quickly on long-running jobs working at production scale.
The numbers:
Fable 5.2: 12 turns, 671,398 in, 39,235 out (19,442 reasoning), $2.90, 315 s.
Astra: 10 turns, 255,206 in, 7,271 out (830 reasoning), $0.72, 106 s.
Billing library
Anthropic’s marketing says Fable 5.2 excels over GPT-6 Astra on coding tasks like the ones in this test. This claim held, but by a small margin. Fable 5.2 scored 110/110, and Astra scored 108.
Both models fixed all 20 bugs and flagged all three wrong tests. Astra’s only mistake was in the feature it had to finish. Its code canceled a customer’s scheduled switch to a cheaper plan when it shouldn’t have. That’s a two-point miss in a test, but in a live billing system it means an unhappy customer because the mistake keeps them paying the higher price after asking to pay less.
Fable 5.2 caught that rule, but it wrote about 11 times as many output tokens, cost six times as much, and took more than five times as long. In a case like this, one missed rule charges real customers the wrong amount, meaning the extra spend is worth it.
The numbers:
Fable 5.2: 14 turns, 569,395 in, 36,622 out (25,502 reasoning), $2.53, 348 s.
Astra: 12 turns, 143,367 in, 3,238 out (320 reasoning), $0.42, 66 s.
Lab data analysis
This test had the widest cost gap, even though both models scored 76/76. Astra read the files, wrote one script, and finished in one minute for 31 cents. Fable 5.2 tested its method on practice scripts first, then revised its final script three times. It took more than four minutes and cost $2.17, seven times as much.
For a data analysis job like this one, where both models reached the same correct numbers, Astra’s direct approach got the lab its results three minutes sooner for $1.86 less.
Results
Test
Claude Fable 5.2
GPT-6.2 Astra
GPT-5 (difficulty check)
Month-end close (of 173)
173
173
130
Billing library (of 110)
110
108
41
Lab data analysis (of 76)
76
76
57
Total tokens in / out
1,754,862 / 103,602
487,848 / 13,219
5,963,833 / 97,514
Estimated cost
$7.60
$1.45
$2.05
Total time
917 s
232 s
1,283 s
Both models got a perfect score on the agent test, so I didn’t see Astra beat Fable 5.2 the way OpenAI says it does. Fable 5.2 was the better coder, as Anthropic says, but only by two points. OpenAI’s cost-per-task claim matched my results. At the same price per token, Fable 5.2 cost more than five times as much.
“…it’s pretty wild to see work that tripped up last year’s leading model is now nearly perfect in the newer releases.”
Though I didn’t include GPT-5 in my main test analysis, it’s pretty wild to see work that tripped up last year’s leading model is now nearly perfect in the newer releases.
What do I think?
At first glance, I’d recommend Fable 5.2 because it performed perfectly on all tests. But timing and cost tell a different story. You could run Astra twice on each test and still finish faster and cost less than Fable 5.2.
“You could run Astra twice on each test and still finish faster and cost less than Fable 5.2.”
And that’s what I think a better recommendation is. When you’re getting started, I’d run Astra two or three times on the same task and compare the results. If you see errors or differences, run a second model, like Fable 5.2, to double-check. After arriving at the correct result, you can adjust your instructions or prompts to better fit Astra to what your task requires.
Post-release quality is the top concern for 75% of mobile EMs, and it's one of the main areas that causes non-mobile leadership to lose confidence in mobile. See what's at stake for teams like yours in the 2026 State of Mobile Release Management report.
Debugging mobile apps is weird: intermittent connections, mid-onboarding drop-offs, edge cases on devices you've never tested. bitdrift captures 100% of data, unsampled and in real time, so it’s immediately queryable by engineers and agents. Try bitdrift: mobile observability for the real world.
We reach out to more than 80k Android developers around the world, every week, through our email newsletter and social media channels. Advertise your Android development related service or product!
Our long-term take on HomeView, testing the OLED touchscreen MacBook Pro, and the iPhone Duo duo covers our Duo workflows that make the foldable worth it.
This episode of Mac Power Users is sponsored by:
Squarespace: Save 10% off your first purchase of a website or domain using code MPU.
 Log in