Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162994 stories
·
33 followers

Agentic Code Quality

1 Share

The following article originally appeared on Addy Osmani’s Elevate blog and is being republished here with the author’s permission.

For much of human history, we’ve evaluated code quality via code review: Someone reads what you wrote and makes sure it’s clean, thoughtful, fast, understandable, and tests well. For agents, that approach doesn’t scale well; there’s just too much code for anyone to read. As a result, more and more of our quality checks have to happen in the harness, environment, and operating system around the agent. I still read and review code, but am very intentional about where I am comfortable with constraints as the check.

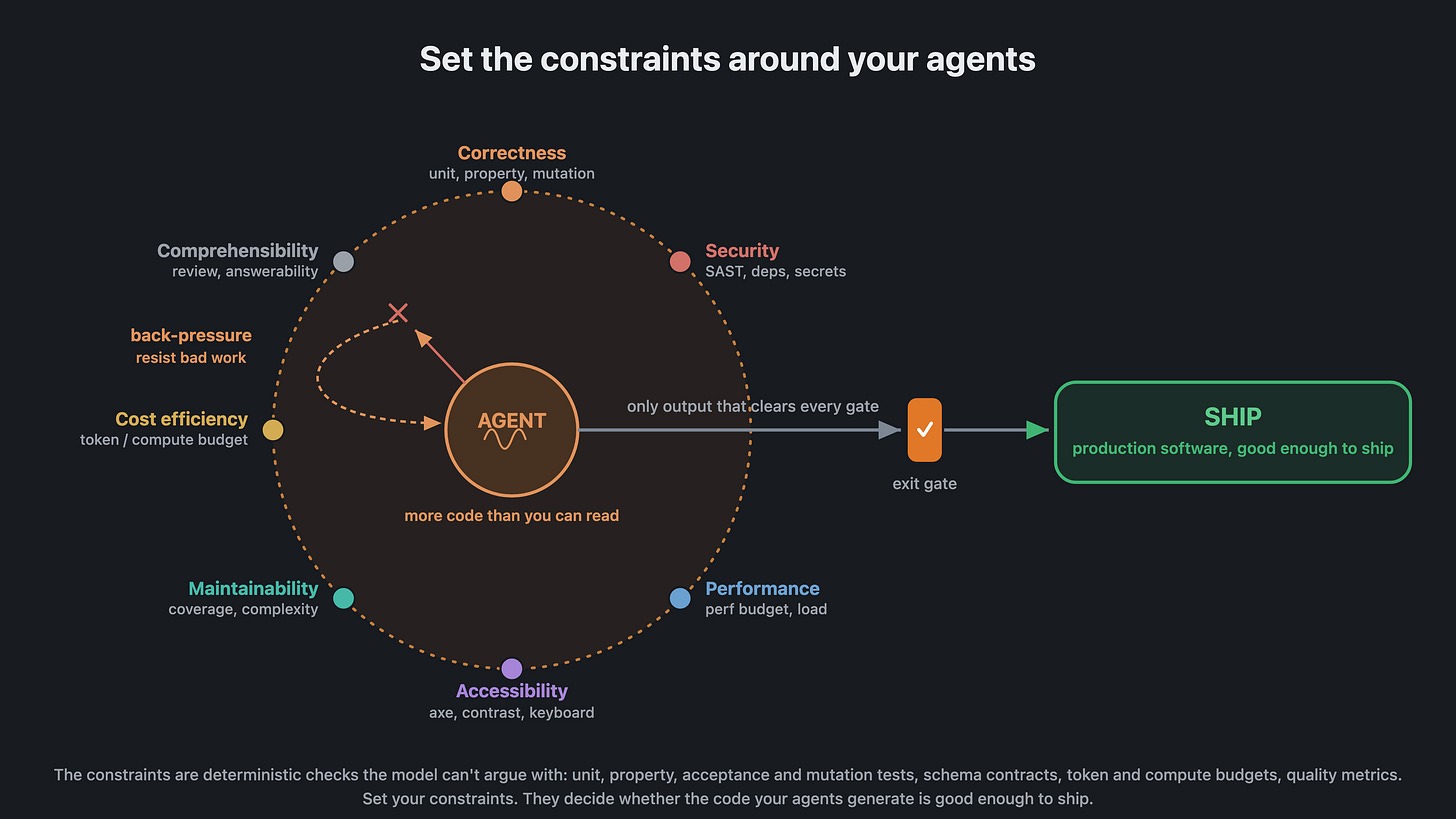
Software quality now depends on the constraints you set around your agents.

Constraints define what the system is allowed to do by throwing tests and deterministic constraints at an agent’s proposals. It’s by setting and maintaining these constraints that we build loops that reliably deliver high-quality production software, even when agents are creating hundreds of thousands or millions of changes every single day.

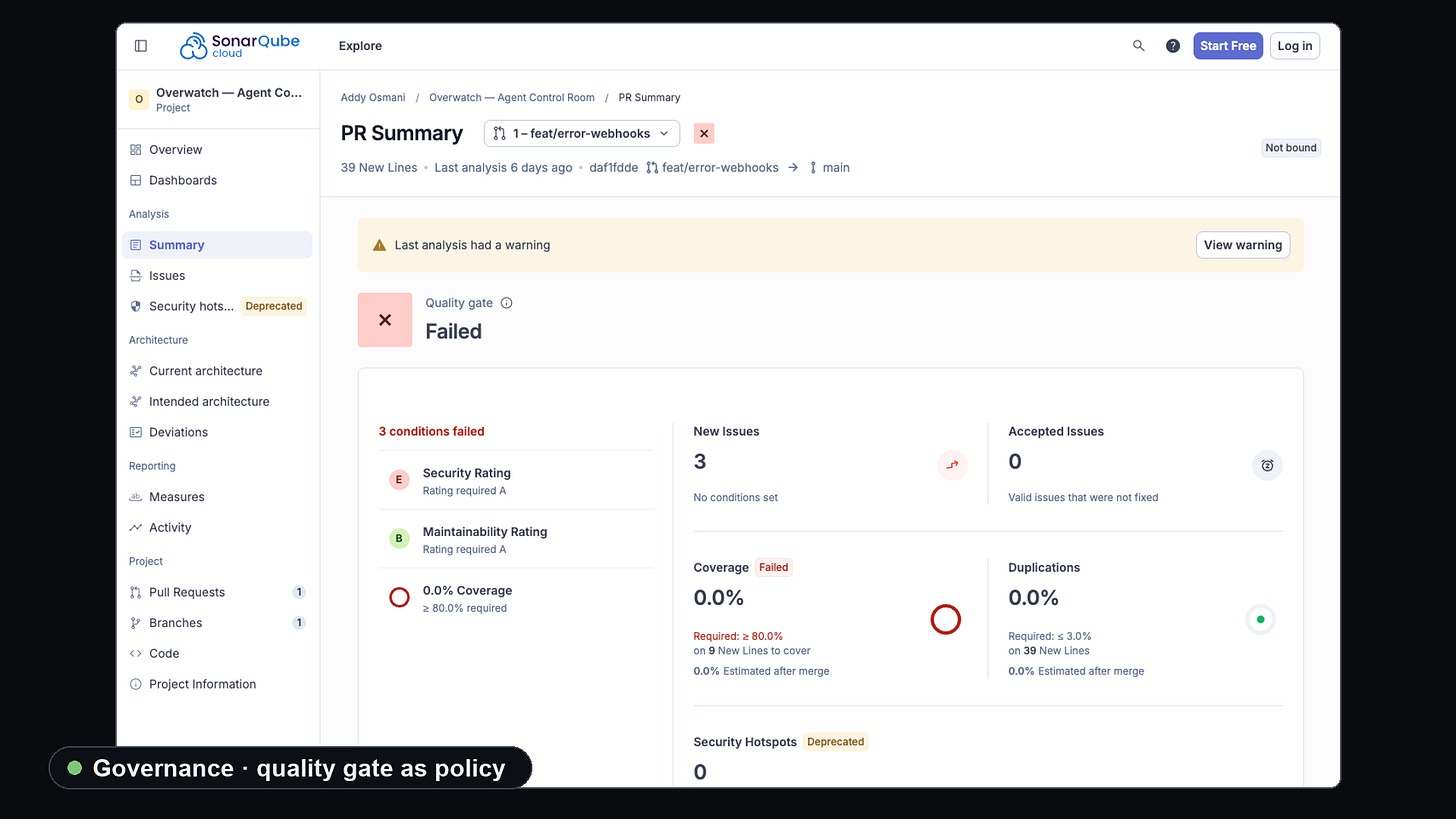
We call these constraints quality gates, and they take many forms. They include conventional unit tests, property tests, and acceptance tests. They include mutation testing, where we generate variations of code, run it against the same tests, and make sure that people aren’t sneaking bugs in that we’re missing. They’re metrics around code quality, such as cyclomatic complexity and line length, that help keep things readable. Constraints also play an important role in what proposals the system will accept and apply as code changes. By the time a change proposal moves from the interpreter running the agent to the agent controller and out to production, we’ve done enough checks on it to be confident that it’s safe to ship and the impact of its change is well within the scope of the agent.

An agent can propose anything. Your constraints decide whether a proposal is safe enough, correct, scoped, and useful, for you and your team to ship.

This model offers a lot but also leaves out many pieces, and those omissions are worth thinking about today. One issue is autonomy; agents might apply their intentions well but may fail when there’s missing information or when what they try to do is ambiguous. That applies both to the task itself and to how it’s parameterized by the harness, environment, and other components. Many of the reasons that humans fail to ship great code are shared with what agents might do: brittle environments that don’t hold up under script-driven stress, nondeterministic builds, missing permissions, and weak tests. This motivates a better environment that gives agents trustworthy feedback, allows for low-damage failure modes, and makes it easier to progressively build up success.

The environment we’re after is one where an agent can do real work, get feedback it can trust, and fail without doing much damage.

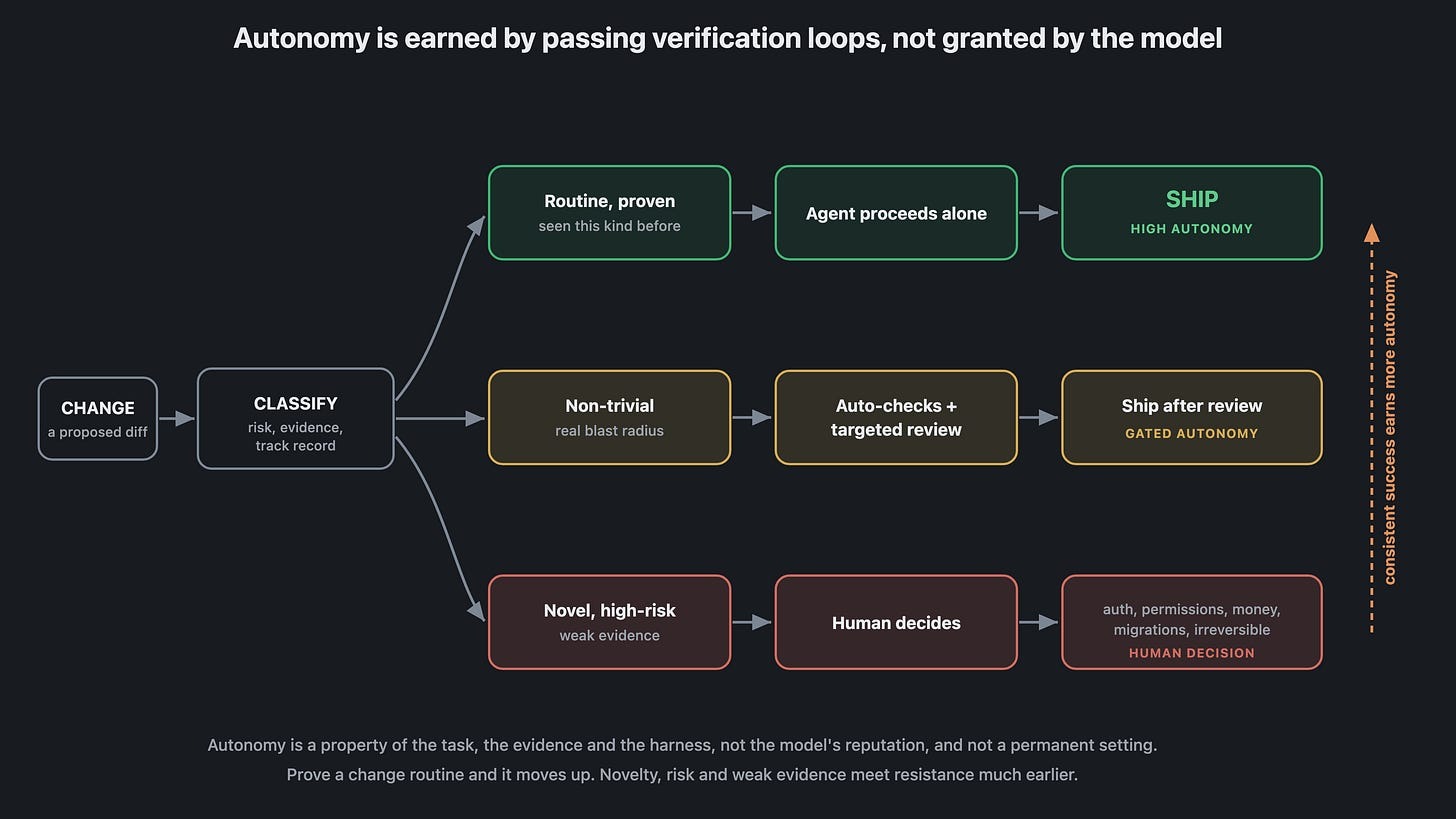
The other important issue is trust. We can’t credulously hand off intent to something even as smart and robust as a modern agent without checking for correctness. We start with trust, but it has to be hard-earned.

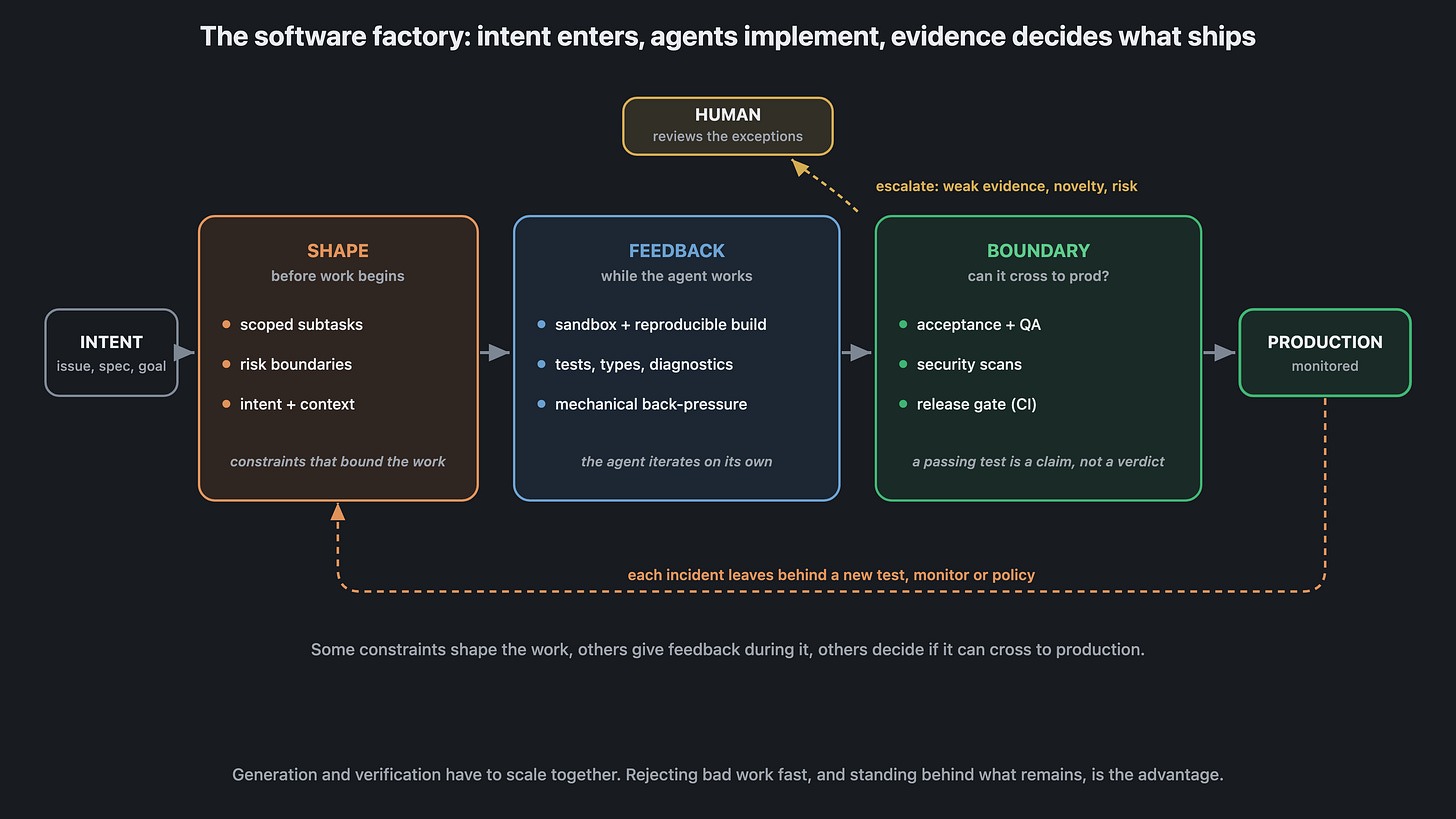
Some constraints shape work before it begins. Others give feedback while the agent is working. Others decide whether its output can cross the production boundary at all.

There are a bunch of ways to model how we put a verification structure around a system.

In my experience it helps to have a broader, but intentionally chosen, set of checks for your constraints instead of relying solely on unit tests. The idea is that each check has a distinct responsibility, and that can range from type safety and performance to late-stage security scanning. Folks can define their own constraints too, including architecture rules that linting tools like ESLint can enforce. Many of these tools have built-in hooks that can be used to pull in agents, or humans, when things break.

For now, much of the difference between useful agent output and slop still comes down to the skill of the team operating the loop.

AI gives us high-volume code generation and velocity, but this can also mean it gets harder for humans to review every single change. You have to instead be intentional with where their attention is going. If you put a human check into a system that otherwise moves at machine speed, don’t be surprised if that impacts productivity. Human attention is scarce and valuable, so we should proactively direct it to those most nuanced problems that require our judgment. Downstream humans should only be pulled in when the automated guardrails for constraints break.

Human “code review” in the future is going to look very different.

Correctness is one important dimension, but you may care about others as well, like maintainability, performance, security, efficiency, and comprehensibility. Just as correctness decomposes into many signal types, so too does the rest of quality. And while it matters how many constraints we have in place, it matters more whether they’re challenging enough to meet our bar for quality and production readiness.

Software quality isn’t a single metric. Think of it as a collection of signals of varying importance to you and your team.

Back-pressure can be implemented through many tools: compilers rejecting invalid code, tests failing, security policies blocking bad practices, CI declining to deploy. Ideally it exists throughout the loop, not as a single review at the very end of all the work.

Constraints and back-pressure let agents catch bad work before it’s a problem.

What happens if we can’t apply the constraint because the volume of changes is higher than our tools can consume? We end up building a queue and relying on a verification system that moves at human speed. To scale, we want to push as much as we can into the verification loop throughout and not wait until the end. If we can scale within our automated checks, we can increase the speed and throughput of our entire delivery system. If we run out of room in the verification loop, we need to do one of several things. First, we can scale our verification system and create more capacity to constrain and push back on changes that come in. Second, we can reduce the rate at which agents generate new changes so that verification can catch up to the volume of work. Third, we can lower our quality bar so that verification doesn’t push back as hard as it otherwise might. From a scaling perspective, we need to be ready to do all of these things. At the same time, we should not stop short of realizing that we could actually get more done by unconstraining in some directions. Maybe we can increase the speed of agent-generated changes by providing swarms of agent developers or automated software factories to create changes without waiting for us to review each of them.

And in some places we might want to give them more freedom as long as we keep tighter constraints in others. By providing tighter constraints where we care the most, we can maximize our throughput without sacrificing quality. Throughout these decisions there are many options. Most obviously, we have to trade between different dimensions of quality. As we’ve emphasized, security is very important, but we’ve also had to trade between delivering security and delivering a product on time. There is a spectrum from innovation-focused at one end to quality-focused at the other. Somewhere along the way, we have to make choices about where we want to be on that spectrum.

We want to send clear feedback from the environment and the system back to our agents or teams, so that people can focus on the more subjective concerns of taste, intent, and architecture. If we can help humans stay inside the safe range of constraints, we can avoid the need for them to work hard trying to figure out where things went wrong.

Software quality includes more than just correctness. Software quality also means maintainability, good performance, security, efficiency, and being easy to understand. All the constraints that help us meet these standards and keep our production flowing create back-pressure in our delivery pipeline.

We need to make deliberate decisions about where to apply strong constraints and where to remove or relax them. Apply strong constraints where they’re serving both of these goals. Don’t support them if they’re not serving one or both. Be ready to raise or lower standards as the case may require. And remember these constraints at different points in the software system are what make software quality enforceable.

We should apply strong constraints where they’ll serve this dual purpose best and consider removing or relaxing constraints that aren’t serving either purpose well. We should also be ready to shift quality bars up or down as needed. In effect, these constraints at various points in our software system are what give quality its teeth. In many cases, we can create more back-pressure and more constraints by deploying new tools or strengthening tools that are already in place. All of these things can be used to push back on most change requests. We want to build them throughout the pipeline. We don’t want to wait until the end of the pipeline when our CI system will simply tell us that we’re not allowed to deploy without fixing problems. We want to use these signals as early as we possibly can, through every possible pathway. The ultimate constraint in this system is the one we place on ourselves to stand behind the decisions and actions we’ve taken to build the system and to operate it. But like all other constraints, we need to make thoughtful trade-offs about how much we want our own judgment to restrain, to back-pressure, and to act as a final check.

Quality is in the constraints that we place around our agents. So as you’re thinking about quality for your own apps, take this problem statement and come up with your own constraint-driven plan.


Read the whole story
alvinashcraft
43 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

How Netflix Made AI Coding Agents More Efficient with JetBrains IDE Intelligence

1 Share

Netflix plugged JetBrains’ headless code-intelligence engine – the same one behind IntelliJ IDEA – into Claude Code and Codex, then benchmarked it against a variety of scenarios. The details and numbers are available below.

At a glance

CompanyNetflix – Application Development Platform (ADP), GenAI Platform, and Agentic SDLC teams
ChallengeCoding agents were struggling to navigate Java/Kotlin code, especially across compiled library (JAR) boundaries
TechnologyJetBrains IDE code intelligence for Java, built on the same code-indexing engine that powers IntelliJ IDEA, run headlessly with no IDE open.
Netflix’s roleBuilt the daemon and CLI needed to make the LSP callable by an agent – infrastructure that JetBrains hadn’t shipped yet
ResultTypically 20–30% more efficient (fewer tokens, less time), and up to about 65% in the best case, on real programming tasks – the size of the gain depends on the model, the agent, and the task, generally larger for stronger models and higher effort settings
Evaluated onTwo real codebases – an internal production service and Netflix’s open-source DGS Framework – across several current coding agents and models, July–August 2026

The goal: Increase agent ROI

JetBrains and Netflix set out to give coding agents accurate, IntelliJ IDEA-grade code understanding in headless environments – with no IntelliJ IDEA instance running.

“Coding agents like Claude Code are slow and unreliable at navigating Java/Kotlin code, especially across library (JAR) boundaries. We integrated a headless JetBrains IDE’s code engine to give agents IntelliJ IDE-grade code intelligence in headless environments, with no IDE running. We created a benchmark with real programming tasks, which shows that with the JetBrains IDE’s code engine, agents are consistently more efficient – using fewer tokens and less time, with the exact gain depending on the model.”

— Paul Bakker, Staff Software Engineer, Netflix

The JAR problem Netflix is trying to solve that Paul describes above: JVM projects typically ship libraries as JAR files only, never as source. Agents have to unzip the JARs (guessing which ones matter), potentially decompile class files, then grep through that incomplete view.

The solution: JetBrains IDE intelligence

JetBrains has spent years building the code intelligence engine behind IntelliJ IDEA. It is based on a deterministic index of your project source files, including all libraries. This intelligence is now exposed via an LSP and available in VS Code-compatible editors. Netflix worked with a headless build of that engine.

The LSP alone isn’t enough for a coding agent to use directly: It’s just a server speaking a protocol, with no easy way for an agent to call it and no built-in process management to reuse a running instance between calls. Netflix closed that gap themselves using the daemon and CLI described in the next section.

Architecture in detail: Keeping the index warm

Building an index for a project takes real time, just as opening a large project in IntelliJ IDEA for the first time does. A coding agent calls the LSP in many small, fine-grained steps, and a realistic task needs several such calls. If each one spun up a fresh LSP server, every single call would incur a multi-second cold-start cost – even on a project whose index had already been built a minute earlier.

A daemon process is required to avoid the overhead of cold-starting the LSP server process on repeated calls. JetBrains is working on delivering a daemon, but no daemon was available by the time of evaluation, so Netflix has built one for their own needs:

  1. Each tool call was short-lived and stateless – it just shelled out to the CLI.
  2. The daemon is the part that stays up: Its session manager routes each call by project root to the matching server process, which holds that project’s index in memory.
  3. A second call against the same project skips indexing entirely and goes straight to a warm server over stdio.
  4. Both the daemon and CLI are developed in Java and distributed as a GraalVM executable, so there is no startup or runtime overhead from the JVM.

How Netflix measured the ROI of JetBrains IDE intelligence

To understand if (and to what extent) JetBrains IDE intelligence improves the performance of a coding agent, a benchmark suite was developed. Same model, same task, same codebase – the only variable was whether the agent could invoke the JetBrains IDE intelligence. Results are reported as the performance difference between runs with JetBrains IDE intelligence versus runs without it.

Evaluation environment and approach:

DatasetsTwo real codebases: An internal service (medium-size project) using Spring Boot 4 and Gradle.
Netflix’s own open-source DGS Framework – a public, mixed Kotlin/Java GraphQL framework.
TasksTwo task types:
Small/focused tasks where the agent attempts to understand specifics in the codebase, e.g. “where is this interface used in the project”, “what implementations exist of this interface”, “what is the structure of this class”.
Full end-to-end tasks, such as implementing a new feature, refactoring a class, or removing code.
ModelsClaude Code with Opus 5 (medium/high effort)
Claude Code with Sonnet 5 (medium/high effort)
Codex with GPT-5.6 Sol (medium/high effort)
ScoringWhile the most important metrics in the experiment were token consumption and time to completion, LLM as a judge was implemented for checking correctness. It works against a reference change set for end-to-end tasks and applies deterministic scoring metric for navigation tasks.
Outlier handlingA task that crashed, hit a budget cap, or thrashed in either arm was excluded from both, so one blow-up couldn’t skew the comparison.

The benchmarks were run multiple times to validate the results and see the effects of changes from new LSP releases.

Results

Across every model, agent, and task type tested, JetBrains IDE intelligence made coding agents more efficient overall – typically 20–30% more efficient, and up to about 65% in the best case, depending on the specific model, agent, and task. The stronger models, with higher effort, saw the largest gains. These models are more expensive, so efficiency improvements matter more, but these models are also better at using indexes effectively.

Efficiency gain per configuration, combining token and time savings. Each comparison runs the same task, model, and codebase twice – once with JetBrains IDE intelligence available, once without it.

~25%
Average gain
20–30%
Typical range
~65%
Best case
Configuration Code navigation End-to-end
Strongest model, high effort ~65% ~24%
Mid model, high effort ~29% ~30%
Mid model, medium effort ~24% ~22%
Lighter configuration, high effort ~17%* ~21%

Efficiency is the average of token and time savings for each configuration. Correctness held steady or improved in every run. *Tokens only: this configuration’s batched search calls made the code-navigation time comparison unrepresentative – see the article text. Figures are a snapshot and will shift with new model releases.

These numbers are a snapshot, not a fixed benchmark result. Every new model release changes how agents search, reason, and use tools, so the exact percentages will keep moving – which is why this write-up reports ranges rather than per-model results. What held up across Netflix’s runs is the general shape: every model and agent tested became more efficient, the largest gains came from the strongest model at a high-effort setting, and the size of the gain differed noticeably from one model to the next.

Code-navigation tasks: More efficient across the board, correctness held or improved

Every model and effort level tested used fewer tokens with JetBrains IDE intelligence – no exceptions there – with savings ranging from roughly 15% to 60%. The size of the gain depended mostly on the model: the strongest model saw by far the largest improvements, while lighter-weight configurations landed at the lower end of both ranges. Correctness held steady in most runs and improved in two – it never dropped.

For the code-navigation tasks specifically, one tool/model combination already batches multiple search calls into a single command, so both with and without JetBrains IDE intelligence, it only makes one tool call there. Calling into JetBrains IDE intelligence is a little slower for that one call than the batched search command – which is what produced the clear lack of time benefit for that combination, not a fair reflection of real-world use. That’s why the broader end-to-end task suite is the more reliable read on time instead, where JetBrains IDE intelligence was faster across every model and agent tested.

End-to-end tasks: Consistently more efficient, correctness unaffected

On the expanded end-to-end run, correctness held steady everywhere across every model and agent tested, so the benefit shows up entirely in efficiency, not in whether the task got done. Every model and agent combination was roughly 10–30% more efficient with JetBrains IDE intelligence, looking at time to completion and token spend. A lot of this is explained by requiring fewer tool calls to come to the same conclusions.

Other evaluated alternatives

Before committing to the described approach, Netflix ruled out two others. The first rejected was a homegrown internal CLI that connected to a running IntelliJ IDEA instance to get access to a project index. The process is similar to what this article describes, but it requires an IDE to be running. This approach didn’t fit headless agents for environments like Otto, Bitbot, distributed refactoring tooling, CI, etc.

Second, an existing Eclipse LSP, which is used for Java in VS Code, was considered. But for Netflix’s build system (Gradle-based), it just didn’t work.

What’s next

Where Netflix goes from here

After the test, Netflix concluded that “the benchmarks show that there is a benefit to having a deterministic intelligence layer alongside your agent”. Of course, it doesn’t cut every coding-agent task by a fixed percentage. But for this specific problem – resolving real structure across JAR boundaries – the benefit is large, holds across models, and doesn’t cost anything in correctness.

Netflix plans to run the same benchmark methodology against Python, TypeScript/JavaScript, and Go. Coding agents for those languages have similar problems. But of course, the ways libraries are downloaded in a project vary by language, so the mechanics of the issues and possible solutions differ. JetBrains plans to continue the collaboration and support this evaluation further.

JetBrains’ take: The LSP is just one step, not the destination

JetBrains IDE intelligence for Java has been tested by Netflix and is now shipped as part of the Java & Kotlin by IntelliJ IDEA extension. JetBrains also continues experiments with the LSP+CLI approach and will report the results once ready.

The LSP’s basic primitive is a position in a text document. The specification defines a position as “between two characters, like an insert cursor in an editor”. That’s a natural primitive for a human working at a keyboard. But agents don’t really think in terms of cursor locations. They ask questions about the program, like “Why is this call inside createUser() unresolved?” and “Which tests are covering this method?”, etc. It’s about understanding relationships between parts of the code rather than looking at cursor positions. And a text position is a fragile identity – inserting one character before any given position causes that position to move.

What an agent needs isn’t a sharper cursor, but a layer that provides answers formulated in the same way as the tasks themselves – i.e. in terms of symbols, diagnostics, test relations, runtime behavior – and returns enough context to reason about the answer, not just locations in a text document.

“That’s what I mean by a code engine: not another protocol that lets an agent imitate editor interaction, but a set of precise operations over program structure and execution – one that returns enough context to actually reason about the result. LSP is useful, but it shouldn’t define the final agent-facing abstraction. Build agent tooling as if the agent were a tiny human at an editor, and you force it to speak in cursor coordinates. Agents need a code engine, not a virtual editor.”

— Aleksey Stukalov, IDE Division Lead, JetBrains

The Netflix numbers prove code intelligence is worth paying for. Deciding what shape that intelligence takes is the challenge that lies ahead.

Read the whole story
alvinashcraft
43 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Amazon’s new AI devices can listen to conversations and suggest things to buy — if you opt in

1 Share
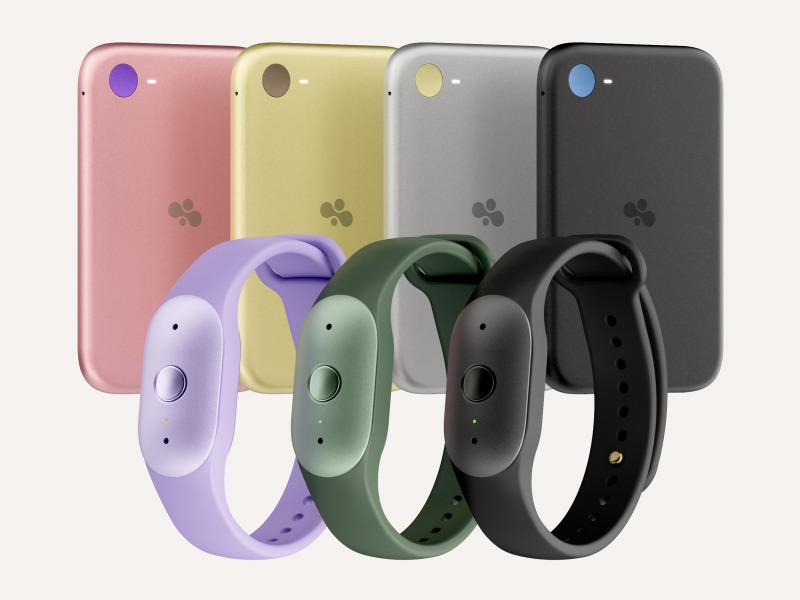
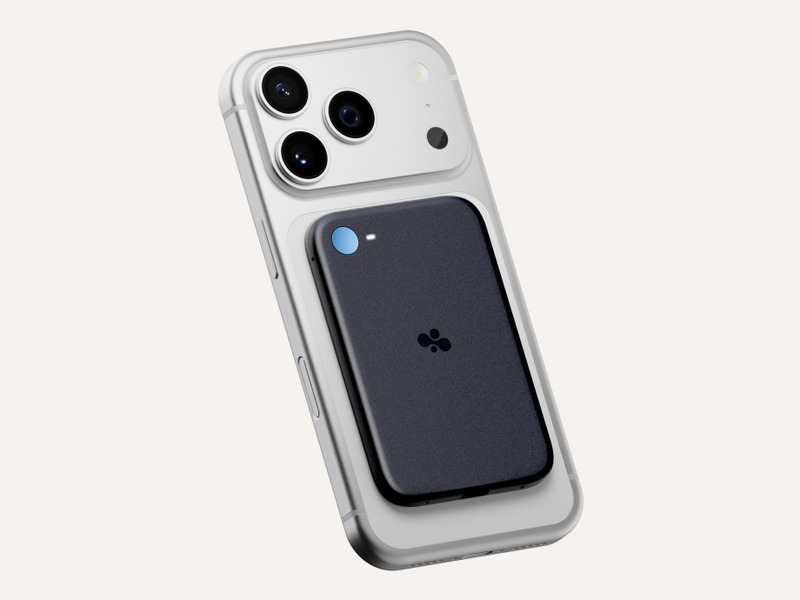
Amazon’s new Bee Frontier wristbands, front, and Bee Eclipse devices, which attach magnetically to the back of a phone. (Amazon Image)

Bee, the AI wearables startup Amazon acquired last year, makes devices that remember what people say in everyday conversations. A new update, announced Thursday morning, includes a feature that turns those passing remarks into shopping suggestions on Amazon.com.

For example, as described by Amazon, someone might mention offhand that they’re out of dish soap, and a product recommendation would show up on Amazon.com and in the Bee mobile and desktop apps. Amazon pitches it as a way for people to remember to buy things they need.

It’s the kind of thing many people have long suspected their phones of doing secretly, listening to conversations and serving up related content or ads. Researchers haven’t found evidence of that. Either way, Amazon’s twist is to do it openly — and to make it voluntary.

The feature is opt-in, meaning it won’t happen unless users choose to connect their Bee accounts to Amazon.com, and Bee says it won’t share data with Amazon without user consent.

The Amazon.com integration requires Bee Pro, a $12 monthly subscription that also includes unlimited conversation summaries and the ability to ask Alexa+ about things Bee has captured.

New hardware: The feature is part of a broader announcement that includes the first new Bee devices under Amazon’s ownership: Bee Frontier, a $74.99 wristband that can also clip onto clothing, and Bee Eclipse, which attaches magnetically to the back of a phone and starts at $99.99.

Bee Eclipse attaches magnetically to the back of a phone and starts at $99.99. Amazon says it will be available soon. (Amazon Image)

Bee Frontier, available now, has dual microphones, up to seven days of battery life and IP67 water resistance. Bee Eclipse, about the size of a credit card, runs more than 21 days on a charge and will be available soon, Amazon says.

Amazon says Bee lets people pay attention to a conversation instead of taking notes, keeping track of details such as when and where they agreed to meet a friend. The devices turn conversations into summaries, to-dos and reminders.

Users can read their summaries in the Bee mobile app or a new desktop app, formatted for different kinds of conversations, such as lectures, care plans and brainstorming sessions. Bee also picks up on recurring themes in conversations and suggests goals and actions.

Bee connects to apps including Gmail, Google Calendar and Microsoft Outlook. After a call or meeting, it can list action items, draft follow-up emails or create calendar invites based on the conversation.

Users can also link Bee to Apple HealthKit and to their photos. Most of those features, including the desktop app and third-party integrations, also require Bee Pro.

Without a subscription, Bee users get conversation summaries and 14 days of memory. New customers get 30 days of Bee Pro free.

How Bee handles privacy: Amazon says Bee runs on a system it calls Bee Private Compute, which processes conversations in an isolated environment where “no one, including Amazon, can access your data.” Audio is deleted after it’s processed, and transcripts are encrypted with keys controlled by the user’s device.

Both new devices turn on and off with a single button and show a light when they’re running. For phone calls, Bee Eclipse prompts users to get permission from the other people on the call each time it starts, according to Amazon.

Bee and Amazon: Amazon acquired Bee in July 2025 for an undisclosed price. At the time, the San Francisco startup, led by co-founders Maria de Lourdes Zollo and Ethan Sutin, had raised $7 million and sold a $49.99 wristband called Bee Pioneer.

Thursday’s update connects Bee to two of Amazon’s biggest consumer businesses: its online store, through the product recommendations; and Alexa+, the new version of its longtime voice assistant, by letting users ask Alexa+ on an Echo device about things Bee has captured.

Amazon isn’t the only tech giant betting on AI devices.

Bee also competes with startups such as Plaud, Omi and Friend, which make AI recorders and pendants that listen to conversations, and with AI notetaking apps such as Granola and Otter that work on a phone, with no extra device required.

On another front, Amazon is fighting to keep other companies’ AI agents out of its store. Last month it blocked Meta’s Muse assistant from shopping on Amazon.com, after earlier moves against shopping agents from Perplexity, Google and OpenAI.

Read the whole story
alvinashcraft
43 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

What Traffic Engineering Taught Us About Building an Azure App

1 Share
An overhead highway gantry with a green guide sign reading Wayfinding, a blue Azure services sign listing Static Web Apps, Azure Functions, Cosmos DB and Application Insights, and a brown sign pointing to the sponsor tables

Every city already knows how to move people. Guide signs tell you where you're going. Warning signs tell you what's ahead. Work zones tell you someone is building and someone else is directing traffic. Traffic engineers call the whole system wayfinding. It's one of the oldest user-experience disciplines local government has.

We borrowed it to build a conference app on Azure. A public-sector association asked us for a digital passport for its annual conference. Attendees visit sponsor tables, collect stamps, and earn a spot in the prize drawing. Underneath, it's a wayfinding problem in two directions: getting people to the right conversations, and getting every request to the right Azure service and back. This post walks the route.


The destination: conversations, not stamps

Sponsors don't come to a conference for a table. They come to talk to people. A paper passport fails at exactly that: walk up, get a stamp, walk off. So before we chose a single service, we set the destination. A stamp has to be earned by a conversation.


Each sponsor table has a question, and the sponsor gives the answer while talking with the attendee. Scanning a table's QR code opens that question rather than awarding points, because a scan alone proves nothing. Points roll up to a live leaderboard and the prize drawing. Every Azure decision that followed traces back to that one sentence.

The route a stamp takes

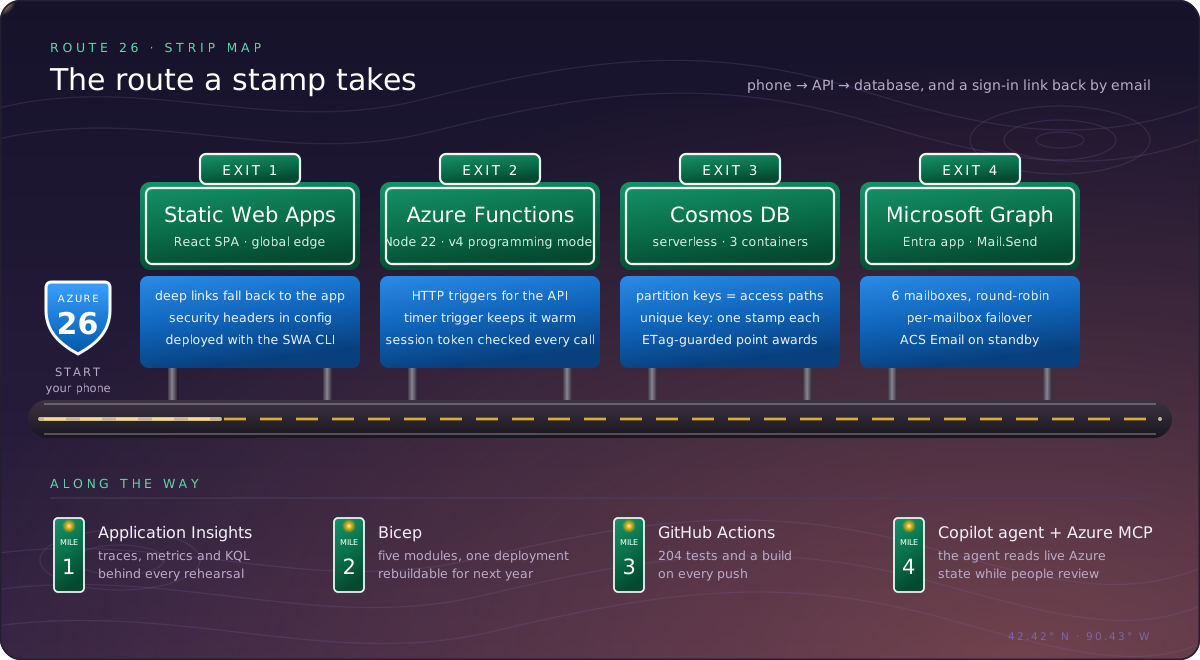
The architecture is four exits on one road, and each service does one job well.


A highway strip map with four exits: Static Web Apps, Azure Functions, Cosmos DB and Microsoft Graph, each with a blue plaque of configuration details, plus mile markers for Application Insights, Bicep, GitHub Actions, and Copilot with Azure MCP
One check-in, end to end. Exits are the request path; mile markers keep the road maintained.

Exit 1: Azure Static Web Apps. The React front end is served from the global edge. A navigation fallback means a deep link printed on a table's QR code opens straight into the app. Security headers live in staticwebapp.config.json, next to the code they protect.

Exit 2: Azure Functions. The API runs on the Node.js v4 programming model. HTTP triggers handle sign-in, check-ins, the leaderboard, and the staff portal. A timer trigger keeps the app warm during conference hours. Shared modules hold the rules that matter, such as how points are awarded, so every endpoint follows them consistently.

Exit 3: Azure Cosmos DB. This is where most of the design thinking went. There are three serverless containers, and each partition key matches how the data is actually read. Attendees are partitioned by email, which is how they sign in. Check-ins are partitioned by attendee, which is how a passport is drawn. The database itself guarantees one stamp per sponsor per attendee:

// checkins container: partitioned by attendee
partitionKey: { paths: ['/attendeeId'], kind: 'Hash', version: 2 }
// one check-in per sponsor within each attendee's partition
uniqueKeyPolicy: { uniqueKeys: [ { paths: ['/sponsorId'] } ] }

Point awards use optimistic concurrency. The function reads the attendee, computes the new total, and writes it back only if the document's _etag hasn't changed. If two taps race, or a staff member grants a manual credit at the same moment, the loser gets a 412, re-reads, and tries again. Nobody's points are double-counted or lost.

Exit 4: Microsoft Graph. Sign-in links are sent through Microsoft 365 mailboxes using an Entra ID app registration with the Mail.Send application permission. Azure Communication Services Email stays configured as a standby route.

Put a sign at every hazard

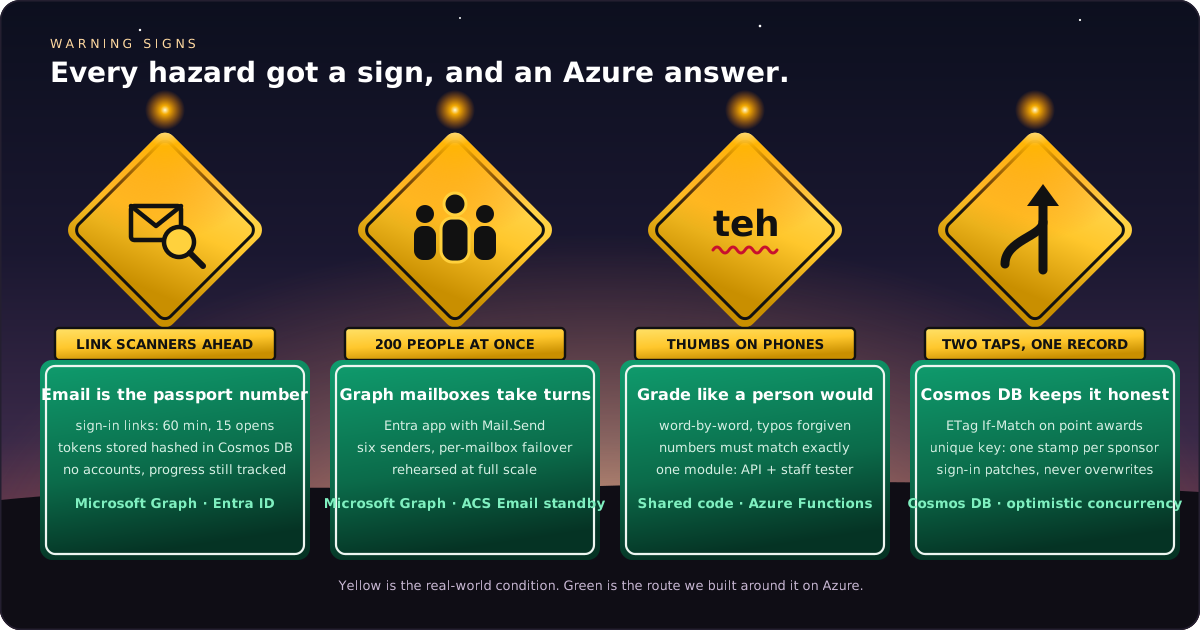
Good roads don't assume perfect drivers. They post a sign wherever conditions change. We did the same: we listed what would really happen when a few hundred people use this on their own phones, in a hotel ballroom, all at once. Then we built an Azure answer for each one.


Four yellow warning diamonds for link scanners, crowds, typing on phones and simultaneous taps, each paired with a green sign describing the Azure design that handles it
Yellow is the real-world condition. Green is the route we built around it.

No accounts, but every stamp tracked. The client didn't want attendees creating accounts or remembering passwords. They still needed each person's passport tracked, through phone switches and closed browsers, all the way to the prize drawing. An attendee's email resolves both: it is their passport number. They type it, tap a link, and they're in. Staff can find them at the help desk, and winners can be contacted. Link tokens are stored only as hashes in Cosmos DB.

Link scanners ahead. Many organizations, especially government, run email security that opens every link before a person does. A single-use link would be spent by the scanner. So a link lasts 60 minutes and up to 15 opens. Asking for another link doesn't cancel the first, and signing in patches only the token fields on the attendee document, so it can never overwrite points.


Everyone at once. Registration is a surge: everyone opens the app and asks for a link in the same few minutes. Six Graph mailboxes take turns sending, and a busy mailbox hands off to the next.

Thumbs on phones. Answers are graded the way a sponsor would grade them: word by word, typos and word order forgiven, numbers exact. The API and the staff "test an answer" tool share one matching module, and a test fails if the two ever drift apart.

Rehearse the rush, then read the telemetry

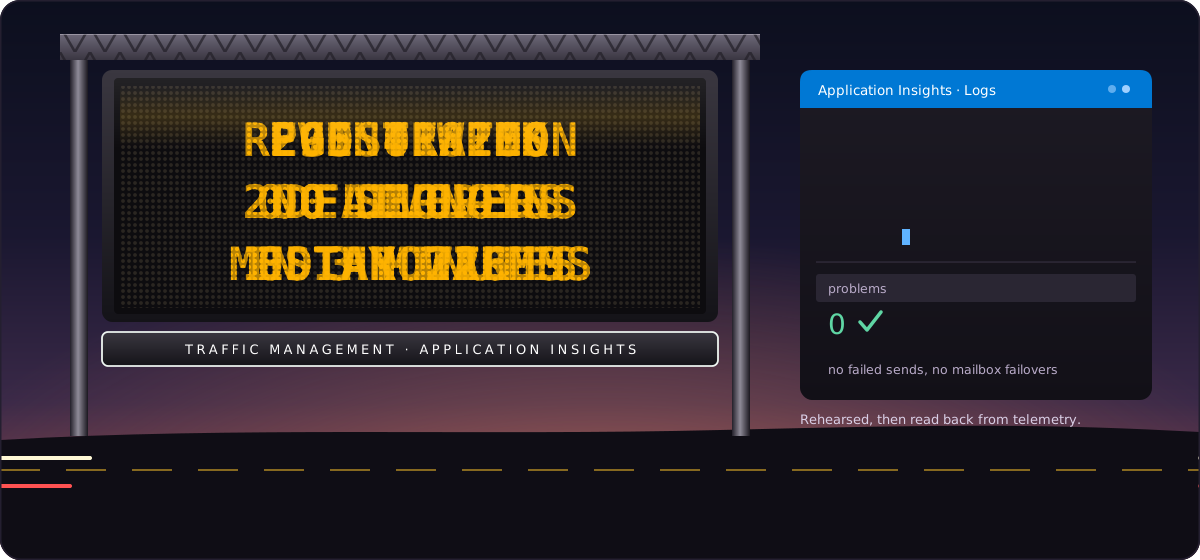
Traffic engineers don't guess at volume; they count it. Before the event, we rehearsed registration at full scale: 200 real sign-ins in three minutes. Then we read the results back from Application Insights rather than trusting the script's console.


An amber LED highway message sign cycling through rehearsal results (200 sign-ins in 3 minutes, 200 of 200 delivered, median 226 ms, p95 418 ms, zero failovers, no deploys during event week) beside an Application Insights Logs query that returns zero problems
The message board is the rehearsal; the Logs blade is the proof. Every send failure or mailbox failover writes a trace, and the count was zero.

All 200 were delivered, with a median send of 226 ms and a 95th percentile of 418 ms. No failovers or throttling occurred. We load-tested the API the same way, with thousands of simultaneous requests. That run produced the most useful rule of the project: Functions perform best after they've been running for a while, so event week is a no-deploy zone. The timer trigger keeps everything warm.

Agents build. People hold the paddle.

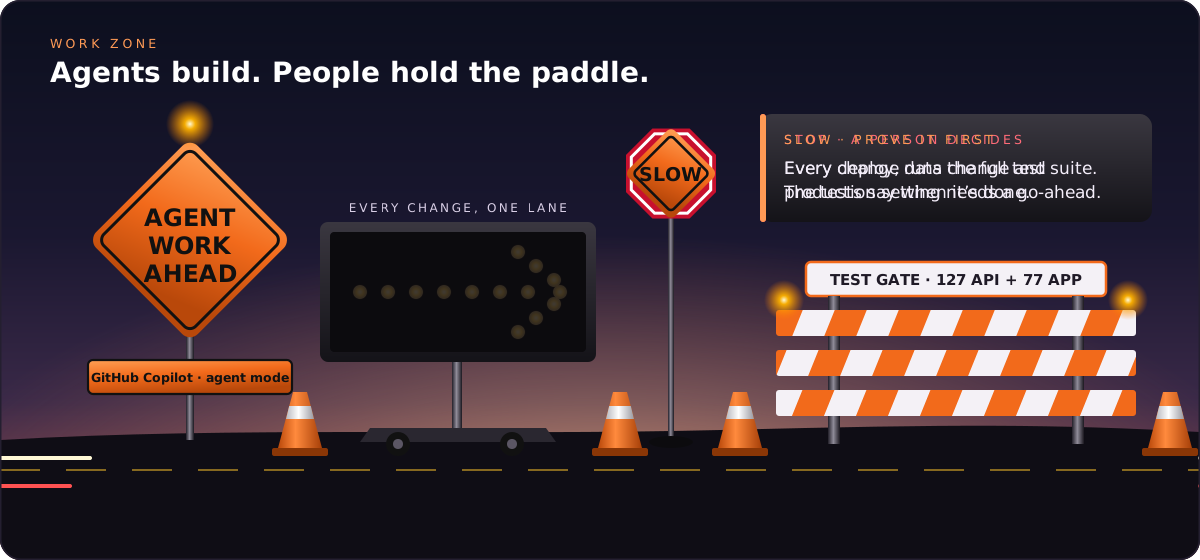
Here's how the work got done. We built this with GitHub Copilot in agent mode in VS Code, using the Azure MCP Server so the agent could read live Azure state instead of guessing. The agent was the work crew. It quickly scaffolded functions, React pages, Bicep modules, and tests.


A work zone: an orange Agent Work Ahead sign for GitHub Copilot in VS Code, a flagger whose paddle alternates between STOP for human approval and SLOW for the test suite, and a striped barricade labeled Test Gate with 127 API and 77 app tests
STOP: a person approves anything irreversible. SLOW: the test suite decides when a change is done.

But a work zone always has a flagger, and that was our job:

  • A decision log. Every significant choice is written down with its reasoning, from the platform to the partition keys. The agent works from it, and next year's team inherits it.
  • A test gate. 327 API tests and 177 front-end tests run in GitHub Actions on every push. A change is done when the tests say so.
  • Infrastructure as code. Five Bicep modules describe the whole environment, so we can review, rebuild, and hand it off.
  • A person approves anything irreversible. That covers every deploy, data change, and production setting.

These are the same rules we'd hold any contractor to. The agent didn't lower the bar; it gave us time to apply it everywhere.


What this means for local government

Local government already thinks in systems that move people safely: roads, transit, permit counters, public meetings. Azure gives small public teams the same kind of building blocks. There's a managed front door, event-driven compute, a database that enforces its own rules, identity and mail that fit the Microsoft 365 tenant most of us already run, and telemetry to prove it all works.

AI agents make those blocks faster to assemble. The craft is the part that hasn't changed: choosing the destination, signing the hazards, rehearsing the rush, and keeping a person at the paddle. That's the same pattern for a conference passport, a 311 intake, or a permit lookup, and it's work local government developers are well placed to lead.

The road is open. Every stamp on it will mean a conversation happened.


A green guide sign listing four takeaways (start with the outcome, put a sign at every real-world hazard, rehearse the rush and read the telemetry, let agents build while people hold the paddle) beside a brown Eagle Ridge destination sign and an orange End Road Work sign

Opening day: what the road actually carried

Rehearsals tell you what should happen. The conference told us what did. We went back to Application Insights and Cosmos DB afterward and counted.

The road held. Throughout the event, the API handled 3,579 sign-in, check-in, leaderboard, and sponsor requests. None failed. The median response time was 89 ms, and the 95th percentile was 502 ms. Our earlier load test had pushed about 3,150 requests per minute through the same functions without a single error, so the real crowd was well within the margin we'd built. Every sign-in link we sent was delivered through the Graph mailboxes, and the one rejected request was malformed.

The hazard signs weren't needed, which is the point. The optimistic-concurrency retry path never had to fire, because no two writes collided on the same attendee. The code was there if it was needed. Signs like that only get tested on the day something goes wrong, and it's still the right place for them.


The stamps were earned. Attendees collected 307 stamps across the three days, and every one came from answering a sponsor's question. We granted no manual credits. Once someone got going, they almost always finished. Completing a passport took a median of about 74 minutes, which is about how long eight real conversations take.

Every table got traffic. Stamps were spread evenly across the eight sponsors, from 24 to 28 each. Each sponsor had at least two dozen conversations, which was the whole reason for the design. The busiest hour was 2 p.m. on the first day, with 64 stamps in 60 minutes.

Attendees came from more than 40 different organizations, including city, village, and county governments across the region.

Read the whole story
alvinashcraft
44 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Enterprise Adoption Guide for Azure SRE Agent, Part 2: From One Team to Enterprise-Wide Adoption

1 Share

In Part 1: From First Use Case to Automated Workflows, we focused on identifying use cases and getting setup with your initial SRE Agent. Teams see the value, and now you need to decide how adoption should expand.

These are the questions we increasingly hear from teams. Who should share an agent? When does another team need its own? How do separate agents collaborate? And how do you deploy and govern all of this without creating unnecessary complexity?

Part 2 shares our recommendations for making those decisions. There is no single topology that fits every organization. Start from the work, context, permissions, and ownership involved, then create boundaries only where they are needed.

This part answers three questions:

  1. How do we share an SRE Agent with more users?
  2. How do we expand from one team to multiple teams, and do we need one SRE Agent or multiple?
  3. How do we codify, deploy, and govern SRE Agents at enterprise scale?

1. How do we share an SRE Agent with more users?

Once the first use case is producing useful results, you will likely want to share the agent with more users who can benefit from it. Sharing is not simply about giving people access to use the agent. It is about determining what each user is allowed to do. Teams must decide who can use the agent, who can change it, who can approve sensitive actions, and which safeguards should apply to everyone.

Azure SRE Agent is a team agent: its connected knowledge, investigation history, memory, skills, custom agents, connectors, and configuration are shared within the agent. It does not create private context or state partitions for different users or teams. 

Once you decide that users can work within the same shared agent, Azure SRE Agent provides controls to define what each person can do, enforce guardrails on agent actions, and audit how the agent is used. The following sections walk through those controls.

1.1 Give each person the role required for their responsibility

SRE Agent provides RBAC roles to control who can view, use, build, approve, or administer the agent. They govern actions within the shared agent; they do not create separate resource or context boundaries. 

Assign built-in SRE Agent roles according to what each person needs to do:

  • use SRE Agent Reader for stakeholders who only need to view investigations and outcomes;
  • use SRE Agent Standard User for team members who need to chat, investigate, and operate the agent;
  • add SRE Agent Author for the smaller group that creates custom agents and response plans; and
  • reserve SRE Agent Administrator for the few people who manage the agent and approve sensitive actions.

A person who creates and tests workflows may need both Standard User and Author because the Author role alone does not provide chat or approval access. Azure Owner and Contributor roles also do not by themselves grant SRE Agent data-plane permissions.

Start with these built-in roles. If none provides the required separation, use the SRE Agent permission matrix to define an Azure custom role containing only the necessary control-plane and data-plane actions.

1.2 Apply guardrails to the shared agent

User roles determine what each person can do. As more people share the agent, its owners also need a consistent way to shape behavior, restrict sensitive operations and validate outputs. The following controls apply those guardrails across the shared agent.

Use tool access policies to control which tools the shared agent may invoke, which operations require approval, and which operations are denied. Enable approval expiration so unreviewed approval and temporary authorization requests expire automatically. Set the timeout to match the expected administrator response window.

Use hooks when inputs, tool calls, or outputs require deterministic validation, cleanup, or policy checks that should not depend on instructions alone.

Choose the appropriate network control mode. For production agents that handle sensitive data or require egress controls, use Azure VNet so non-platform traffic follows enterprise DNS, firewall, NSG, and logging policies. Review the documented traffic exceptions because platform and connector traffic do not follow the same path.

Use custom instructions to add administrator-defined instructions to the main SRE Agent's prompt. These instructions can establish which sources to prioritize, what evidence to include, how to structure an investigation, and when to stop and ask for approval. They augment the agent’s default behavior, so users do not have to repeat the same operating guidance in every request. Common prompts guide behavior; they are not a hard enforcement boundary.

Set a maximum AAU limit as a cost budget for shared-agent usage. Start with a limit appropriate for the expected users and workflows, monitor consumption, and adjust it as adoption grows rather than leaving usage unconstrained.

1.3 Audit how the shared agent is used

As more people use the agent, use its Application Insights audit telemetry to review tool calls, model invocations, agent activity and handoffs, incident activity, Azure CLI commands, and approval decisions. Use thread and call identifiers to follow a specific investigation and correlate related events.

Use the Azure Activity Log to review who created, updated, or deleted the SRE Agent resource and its related managed identity and Application Insights resources.

Together, roles, common prompts, tool access policies, hooks, and usage limits make it safer to share one agent. They do not create separate context boundaries inside it. That distinction leads to the next decision: when to keep expanding one SRE Agent and when to create another. 

2. How do we expand from one team to multiple teams, and do we need one SRE Agent or multiple?

Most enterprises want to transform how operations work across the organization. Once the teams adopt their first SRE Agent and saw their operational toil go down, the questions quickly shift: How do we expand from here? How many SRE Agents do we need? Where should the boundaries sit? And how should teams collaborate when work crosses those boundaries?

When teams first think about this topology, they often start with the size of their environment. They look at the number of subscriptions, resource groups, applications, resources, or teams and assume that a larger environment automatically requires more SRE agents. Azure SRE Agent does not require one agent per subscription, resource group, application, resource, or team, and there is no platform-defined count at which another agent is required. A single agent can work across multiple Azure management groups, subscriptions, resource groups, and Azure regions when it has the required access and context.

The way to think of topology is based on how your organization manages operations today, across the people responsible for the work and the systems they use. Consider the operational problems and workflows the SRE agent will support, the telemetry, source code, data, and knowledge required to perform that work, and the teams with domain expertise in the systems involved. Also consider what each group of users is permitted to see, what actions the agent is permitted to take, and who will create and maintain its workflows. 

The following factors can help you think through which work belongs together and where a separate agent may be useful.

2.1 Factors to help decide when to add a new SRE Agent

Consider each factor separately. Teams may be able to share one aspect of an agent while another requires separation.

Factor and questions

Build on the existing SRE Agent when…

Add a separate SRE Agent when…

Required context

What telemetry, source code, deployment history, operational data, knowledge, and dependency context are needed to investigate, analyze, or perform the task?


The required context can be shared. All teams using the agent are permitted to use the required context.

For example, application, platform, and network teams can share one agent when it can use context from all three layers.

Some context must remain separate. Each team can use its own agent for unique context while each agent continues to use shared context where permitted.


Domain expertise

Who has domain expertise in the operational problems and systems involved? Who provides and reviews the agent's instructions, knowledge, runbooks, skills, tools, and custom agents?


Teams agree on the guidance the agent should follow. They want to collaborate, and their contributions do not give the agent contradictory guidance.

For example, platform and network teams can contribute compatible runbooks to the same investigation workflow.

Teams need autonomy over their domain guidance. Their expertise applies only to their own workflows. Separate agents keep team-specific context and instructions from conflicting with guidance for another team’s workflows.

For example, teams that use different remediation procedures can maintain that guidance in their own agents.

User visibility

Are users already permitted, outside the SRE agent, to see the context and resources the agent makes available?


All users already have access to the context and resources exposed through the agent. This includes its shared context, memory, knowledge, workflows, and resources.

For example, all users can already query the logs across all subscriptions and source code connected to the agent

Some users must not see another group’s context or resources. 

For example, if some users cannot query logs for some applications outside the agent, access to a shared agent should not give them that visibility.


Agent permissions on resources

Which resources is the agent permitted to read or change? Can the same managed identity, credentials, and resource scopes support the required workflows?

One identity and permission model can cover the required resources.

For example, a infrastructure team's agent can use its managed identity to access the subscriptions and shared infrastructure.

Different identities, credentials, or resource scopes are required.

For example, each application team may require an SRE Agent that can access only the resources owned by that team.

Action and approval policies

Which actions may the agent perform autonomously? Which actions require a user to review or approve them? Which users may approve each action?

The required action policies and approvers can be managed together.

For example, multiple teams can align on the same action and governance policies that the agent can follow to perform various workflows.


Teams need independent action policies or approvers.

For example, a platform team may permit its agent to restart shared infrastructure autonomously, while an application team requires the service owner to approve every production change.

Workflow ownership

Who owns the workflows including the triggers, custom subagents, skills and tools that define the workflow? Which teams may view, create, edit, test, and maintain them?


Teams want to co-own and collaborate on the workflows. They are comfortable with other users of the agent viewing or changing them and agree on how changes are reviewed, tested, and deployed.

For example, application, platform, and network teams can jointly maintain a workflow or can add multiple workflows that analyzes issues across their systems.

A team needs independent ownership of its workflows. Other teams must not view or change them, or the team needs to release changes without waiting for another team.


Data residency

Must data or processing remain within a particular tenant, region, or legal boundary?


The same residency and processing requirements apply. 

For example, all connected data and processing can remain within the same approved region.


Different residency or processing requirements apply.

For example, European and US operations may require separate agents so their data remains within the required geography. Review the product’s data-residency and model-processing behavior.


In a nutshell: Build on the same SRE Agent when teams can share the required context, guidance, access model, action policies, and workflow ownership. Applying the factors above, teams generally choose separate agents when they need:

  • Autonomy: A team can configure, test, release, and operate its agent without depending on another team.
  • Visibility and access: Users see only the context, memory, knowledge, workflows, and resources they are permitted to access.
  • Domain expertise: Each team can shape the agent around its own systems, runbooks, skills, tools, and operating practices.
  • Fewer context and guidance conflicts: Instructions or knowledge added by one team do not contradict or change the behavior expected by another team.
  • Less coordination friction: Teams can update workflows, permissions, and policies at their own pace without negotiating every change across multiple groups.
  • Distinct permissions and action policies: Each agent can have the resource access, autonomous actions, review requirements, and approvers appropriate for its team.
  • A non-production testing boundary: Maintain at least one non-production agent to test material changes to instructions, tools, custom agents, permissions, policies, and workflows before introducing them into production.
  • Required organizational boundaries: Residency, tenant, legal, compliance, or production requirements may require separation.

Separate agents can still use permitted shared context and collaborate when work crosses their boundaries.

2.2 How can multiple SRE Agents collaborate?

Once teams operate separate SRE Agents, operational work can still cross the systems those teams own. Collaboration does not require teams to combine their agents or share all of their context. It means passing work, evidence, and ownership to the team responsible for the next step.

Common use cases include:

  • An investigation crosses a team boundary. A team determines that the evidence points to another application, platform, network, identity, database, or data layer. It passes the evidence, what it has already checked, and the requested analysis or action to the team with the required ownership, domain expertise, permissions, or authority.
  • A planned change spans several owners. Each team validates its part of the system before and after the change and records the results in the shared change record.
  • A central team identifies work for a resource owner. A compliance, security, or cost-management team assigns the work with the supporting evidence and required outcome.

Across these use cases, collaboration requires three things: pass enough context for the next team to act, choose how the work will move between agents, and preserve a shared record of the outcome.

Pass the work as a structured handoff. Include the problem or task, its impact, links to the supporting evidence, what has already been checked, the current findings and uncertainty, and the specific analysis or action requested. This prevents the receiving team from repeating the investigation. The receiving team then returns its findings or completed action so the originating team can continue or close the broader task.

Choose the handoff mechanism that fits the existing workflow:

  • Operational tools and automation. One agent can reassign an incident, create a Jira ticket, or post a summary in Teams. Automation on the incident or ticket can invoke the receiving team’s SRE Agent and write the result back. This enables collaboration without requiring one agent to invoke another directly.
  • HTTP triggers. An agent workflow or external automation can invoke a workflow in another SRE Agent and pass the context required for the next step.
  • MCP-compatible clients and orchestrators. They can use the SRE Agent MCP server to ask the appropriate agent to investigate a question or continue work in an existing thread.

2.3 Two common multi-agent scenarios

These examples show how enterprises can configure multiple SRE Agents while preserving the context and authority each team needs.

Scenario 1: A shared platform agent collaborates with team-owned agents

Imagine an organization with a platform team that operates infrastructure, networks, shared data services, and other common dependencies for many application teams. Frontline operations or the service desk routes an incident to the platform team’s SRE Agent first.

The platform agent investigates using centralized infrastructure telemetry, infrastructure-as-code repositories, change history, and platform knowledge. It orchestrates work across its specialized platform capabilities and collaborates laterally with team-owned agents. If the issue is in the shared platform, the platform team continues the investigation and takes the actions within its authority. If the platform is healthy or the evidence points to an application, the agent hands the incident to the appropriate application team’s agent with the evidence already collected and the dependencies already checked.

Application agents can also have permitted read visibility into shared platform dependencies. This helps application teams identify whether a problem originates in their service or the platform, while the platform team retains authority over platform changes.

Scenario 2: Team-owned agents coordinate directly

In another organization, each product or application team operates the services it builds and owns its operational context, telemetry, code, permissions, and workflows. Each team’s SRE Agent is the first responder for its services.

When an investigation points to another service or shared dependency, the initiating agent packages the evidence and hands the work directly to the owning team’s agent. Teams whose operational work does not cross can continue to operate independently. Each agent investigates and acts within its own boundary, while collaborating teams use the same incident or ticket to maintain an end-to-end record.

Shared enterprise standards can provide consistent identity, logging, security, deployment, and governance controls. Teams can also reuse approved skills, tools, and workflow templates without combining their runtime context or agent configuration.

3. How do we codify, deploy, and govern SRE Agents at enterprise scale?

Whether an organization operates one SRE Agent or many, those agents continue to change after deployment. Teams add skills, subagents, tools, prompts, hooks, automations, and policies, while the agents accumulate knowledge and memories through operational use. Because these changes can affect how an agent investigates, analyzes, and acts, manage the agent’s configuration, artifacts, and learnings with the same discipline used for production code.

This becomes especially important when teams move from a proof-of-concept or test agent to a production agent. They may need to create the production agent in the same region or another region while preserving the configuration, knowledge, memories, and operational refinements accumulated during testing. They also need to understand whether changes to a skill, subagent, tool, prompt, or policy changed the agent’s behavior.

Our recommendation is to export an agent that has already been refined through real use, bring the export under version control, and use it as a repeatable baseline. Teams can then preserve its learnings, create production agents in the required environments, track how the configuration changes, and decide which parts should remain agent-specific or be shared with other agents.

3.1 Export the working agent as code

The Azure SRE Agent team maintains the public microsoft/sre-agent repository with templates and scripts for deploying, exporting, cloning, and verifying agents. The repository includes Bash and PowerShell scripts that create a deploy-ready export of a working agent.

The export includes the agent settings, connectors, skills, subagents, tools, hooks, common prompts, repositories, plugin configuration, scheduled tasks, incident filters, HTTP triggers, incident-platform configuration, knowledge, and expected configuration. By default, it also includes synthesized knowledge and workspace memories developed through prior investigations and interactions. Repository instructions can be included when needed.

Review the export for sensitive information and keep connector credentials and other secrets outside the repository. Commit the approved export to Git so teams can preserve the agent’s accumulated knowledge, track configuration changes that may affect its behavior, identify drift, recreate the agent in the same or another region, and use a known agent-as-code baseline for future changes.

3.2 Standardize what should be shared

Decide which parts of the baseline should apply to every agent. Use Bicep or Terraform and Git to define common identity, network, security, logging, audit, and deployment controls, while parameterizing the values that differ by agent or environment.

The public SRE Agent templates provide examples for infrastructure as code, export, deployment, verification, and CI/CD. For reusable operational capabilities, use a private plugin marketplace backed by private GitHub or GitHub Enterprise. Teams can maintain approved skills and MCP integrations once, while agent owners install only the capabilities relevant to their agents. Each installation is pinned to a Git commit so teams can control when updates are adopted.

Together, the version-controlled export, infrastructure as code, shared baseline, and private plugin marketplace provide a repeatable way to expand SRE Agent without making every agent identical.

Share your thoughts

There is no single enterprise topology to copy. The useful pattern is to start by looking inward at the operational toil your team owns, prove value with an initial agent, then share that agent where context and authority can be shared safely, and introduce new agents where organizational or operational boundaries require them.

As you scale SRE Agent beyond a single team, where does sharing, governing, or coordinating agents still feel harder than it should? What could we build or improve to make enterprise-wide adoption easier, safer, or more manageable? What scenarios are you trying to solve next?

We’d love to hear what is working, where you are getting stuck, and what you would like to see next. Share your experience and ideas in the comments below. Your feedback will help us understand where organizations need better guidance, stronger governance, or new capabilities in SRE Agent.

Next steps

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Enterprise Adoption Guide for Azure SRE Agent, Part 1: Deploying Your First Azure SRE Agent

1 Share

We have learned a lot from talking with teams that are bringing Azure SRE Agent into their day-to-day operations. Across those conversations, we have seen a common set of questions emerge as teams move from exploring an initial use case to adopting SRE Agent more broadly.

Some teams are starting with a simple question: “Where should we begin?” Others have already seen value in reducing operational toil and improving incident response and are asking what comes next. How do we expand from one successful use case to more workflows? Can multiple teams share the same agent safely? When should we use one SRE Agent versus multiple agents? How should agents collaborate? And how do we deploy and govern them consistently across the enterprise?

This two-part guide shares the patterns we have seen and our recommendations for navigating that journey, from the first use case to broader enterprise adoption. Our recommendation is to start with one operational problem your team understands, learn what the agent needs to solve it effectively, and expand from there. The goal is not to design your enterprise topology on day one. It is to make each next decision with better evidence.

Part 1: Deploying Your First Azure SRE Agent

  1. Which operational problem should we start with?
  2. How do I run the first use case? Should I use SRE Agent’s built-in capabilities or customize it?
  3. How do we turn a successful first use case into more automated operational workflows?

Part 2: From One Team to Enterprise-Wide Adoption

  1. How do we share an SRE Agent with more users?
  2. How do we expand from one team to multiple teams, and do we need one SRE Agent or multiple?
  3. How do we codify, deploy, and govern SRE Agents at enterprise scale?

Part 1 focuses on proving and expanding the operational value. Part 2 addresses the questions that appear when more users, teams, and agents become involved.

1. Which operational problem should we start with?

A strong first use case is a recurring, bounded problem that the team feels today and understands well enough to judge. Focus on work that affects reliability, consumes engineering time, slows incident response, or creates avoidable cost.

Start with the operational pain your team feels most. Choose one well-bounded problem that matters to the team and is familiar enough to judge.

If you are unsure where to begin, start by asking SRE Agent to investigate an issue or incident your team is already looking at. Give it the observed symptom or question, let it bring together telemetry, dependencies, source code, and recent changes, and see whether it can identify where the problem is likely occurring. That investigation can include root-cause analysis, deployment correlation, Azure resource health, and dependency analysis. The examples below are some of the use cases we have seen customers implement.

  • Alert investigation: correlate alerts with telemetry, dependencies, source code, and recent changes to explain what happened and identify the next step.
  • Incident auto-triage: collect the initial evidence, identify likely ownership and severity, remove known false positives, and prepare the incident for the responding team.
  • Proactive availability: perform proactive health checks, reliability risks, degraded signals, or unhealthy dependencies before they become customer-facing incidents.
  • Deployment correlation: correlate a failure or degradation with recent deployments, configuration changes, feature releases, and infrastructure updates.
  • Production deployment validation: evaluate post-deployment telemetry, logs, dependencies, and service-health criteria to confirm that a production release is healthy.
  • FinOps proactive cost optimization: identify unexpected cost changes, underused resources, and rightsizing opportunities before spend becomes a larger problem.
  • Certificate expiry monitoring: identify certificates approaching expiration, determine the affected services and owners, and initiate the appropriate follow-up.

2. How do I run the first use case? Should I use SRE Agent’s built-in capabilities or customize it?

Once the team has selected the operational pain it wants to address, the next step is to prove that SRE Agent can improve the outcome. Two questions matter at this stage: how should we set up SRE Agent to execute the first use case, and do we need to customize beyond its built-in capabilities?

Keep the first use case deliberately small. Connect only the context required to solve the selected problem. For deployment validation, that may be the relevant telemetry source, code repository, deployment history, and runbook, not every repository, monitoring system, or resource the team may eventually use. For more guidance on setting up the first SRE Agent, see Getting the best out of Azure SRE Agent.

Begin with diagnostic or read-only access. Use the agent’s managed identity and Azure RBAC as the starting point for Azure resource access. Grant only the resource scopes and permissions required for the use case. As the workflow demonstrates a need to perform write actions, add the narrowest permission at the narrowest practical scope rather than granting broad access up front.

Test the agent against a few recent historical incidents the team understands. Use these cases to confirm that the agent can reach the right telemetry, code, deployment history, and operational knowledge, and to expose missing context before a live incident.

Then use SRE Agent alongside the team’s normal response process when a real issue occurs. This is where teams begin to build trust: the agent surfaces the relevant evidence, identifies where the problem is likely occurring, connects it to a dependency or recent change, explains its reasoning, and helps responders reach the diagnosis faster.

Define the outcomes you want to accomplish. Measure the outcome in the system that already records it, for example, mean time to resolution in the incident platform, alert volume or false-positive rate in monitoring, deployment failure or rollback rate in CI/CD. Choose the measure that matches the pain that justified the use case. Establish a baseline, then use an SRE Agent live report or an existing dashboard to track the result.

2.1 When do I customize SRE Agent, and do I need a skill, custom subagent, or tool?

Always start small with SRE Agent’s built-in capabilities. Then add only what the workflow needs.

  1. Start with the expert skills and tools that come with SRE Agent. Out of the box, SRE Agent combines Azure-specific product knowledge and built-in operational capabilities for diagnosing issues and finding probable root causes across Azure. This expertise spans all of Azure, including compute, storage, networking, data, monitoring, and management services. Its native integrations connect Azure Monitor, Application Insights, and Log Analytics, GitHub, and Azure DevOps so the agent can correlate infrastructure state, telemetry, deployments, work items, and source code. General-purpose tools, including Azure CLI, Kusto queries, and code analysis, let it gather deeper evidence within its assigned permissions. For example, it can trace network connectivity, troubleshoot gateway and load-balancing paths, query application telemetry and logs, and correlate a degradation with a recent code or deployment change.
  2. Add a custom skill when SRE Agent needs to understand how your environment or organization works. Before writing a new skill, browse the plugin marketplace and the public Azure SRE Agent Plugins repository to see whether an existing plugin covers the scenario. A skill can teach the agent how to use and interpret a third-party telemetry source such as Dynatrace, which dashboards or signals matter, how your runbooks and escalation processes work, or how your organization performs a workflow such as pull-request validation, release-risk analysis, or compliance review. Even with a native integration, adding your operating instructions as a skill can help the agent find the right evidence faster.
  3. Add a custom tool when part of the workflow must run consistently. Use deterministic code when the agent must perform the same calculation, execute a predefined query, call an external API, or generate a report in an exact format every time. A skill explains when and how your organization performs the task; a tool performs the required action consistently. Prefer an existing built-in or connector tool before adding a custom Python tool, HTTP or Kusto tool, or MCP connector.
  4. Use a skill and tool together when the workflow needs both organizational guidance and deterministic execution. For example, a skill can describe how your organization evaluates deployment risk, while a tool calculates the risk score or generates the required report.

For most workflows, built-in capabilities plus a custom skill are sufficient. Add a custom tool only when the workflow requires repeatable execution, external-system access, or an exact output.

2.2 When do I need a custom subagent?

A custom subagent is a specialist within SRE Agent designed for a focused operational workflow. For most use cases, start with a skill. A skill is enough when the main SRE Agent needs to understand and apply your team’s instructions as part of a broader conversation or investigation.

Create a custom subagent when you want to control the scope of that workflow, package a focused set of instructions, skills, and tools, test or invoke it independently, or connect it to a trigger. The use case itself does not determine the choice. The same deployment-validation guidance can remain a skill when an engineer asks the main agent to apply it during an investigation. Package that skill in a deployment-validation agent when the workflow should stay within a defined scope, use selected tools, and run after a deployment through an incident, schedule, HTTP trigger, or another workflow.

Start with a skill. Use a custom subagent when the workflow needs tighter scope, focused instructions and tools, independent invocation, or trigger-based automation.

3. How do we turn a successful first use case into more automated operational workflows?

Once the first use case proves the value, look at what the team still does manually around it. Where are engineers repeatedly gathering the same evidence, running the same diagnostics, monitoring the same risks, preparing the same updates, or handing off the same follow-up work?

Use live reports to bring together incident, service-health, reliability, and cost signals so recurring patterns and remaining operational toil are easier to see. When the team understands the work and the result is repeatable, it is ready to become an automated workflow.

Begin with the context already connected to the agent. Reuse the same telemetry, repositories, runbooks, resource access, and team knowledge where they apply. Add another source only when the workflow needs evidence the agent cannot currently reach.

There are different ways to start that automation. Use a:

  • Response plan when an incident or alert should start the investigation
  • Scheduled task for recurring health, capacity, compliance, or reporting work
  • HTTP trigger when a pipeline, external monitoring system, or another workflow should invoke the agent

Start these workflows in Review mode, where a person can evaluate the agent’s reasoning and proposed actions. Autonomous mode is a good fit for actions the team has already approved its operators to perform without case-by-case review. Start with a human in the loop, build confidence in the workflow, and move approved actions to Autonomous mode when the team is comfortable allowing the agent to perform them on its own.

Start automating the work the team now understands. Use the right trigger for each workflow, and use live reports to make the next source of operational toil visible.

Continue to Part 2: From One Team to Enterprise-Wide Adoption

Every team has operational work it wishes were faster, more consistent, or less manual. What is the recurring operational problem your team would most like to solve with SRE Agent? And what could we build or improve to make it easier to turn that problem into a trusted workflow?

In part 1, we explored how your organization can go from zero to one with adoption of Azure SRE Agent to address this operational toil in your organization. We'd love for you to share your experience and ideas in the comments below. Your feedback will help us understand where teams need more guidance, better starting points, or new product capabilities.

To continue on to scaling Azure SRE Agent across your enterprise, go on to: Part 2: From One Team to Enterprise-Wide Adoption.

Next steps

Read the whole story
alvinashcraft
45 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories