Sr. Content Developer at Microsoft, working remotely in PA, TechBash conference organizer, former Microsoft MVP, Husband, Dad and Geek.
162046 stories
·
33 followers

More than words

1 Share

While I’ve done a lot of reference documentation writing, my favourite type of work is writing tutorials and “how to” content. I enjoy the challenge of understanding a technology and an audience, then explaining the technology to that audience. AI seems to be particularly bad at creating this kind of content. When people try, they are often confused why it isn’t meeting their goals.

UX designers talk about the first run experience, the experience someone has as they use an app for the first time. For products and features aimed at developers, a getting started tutorial is often the first run experience. I learned this very clearly when I launched Perch, a small CMS product, back in 2009. Billing itself as a simple CMS, many of our customers had never installed a CMS before. Showing them how to go from a static HTML page to something their client could edit in a short tutorial was a huge selling point.

Whether you are selling a product or sharing a new web platform feature, if you can show the reader how to solve a real problem, with a minimum of steps and words, you can hold their interest. After that you can start to unpack things, provide more information and context, and deal with the more complex cases.

The majority of the time I spend writing a tutorial, isn’t spent writing. Before I put words on a page I need to understand the subject—the feature or product—well enough that I can explain it to someone else. Then I need to understand the audience. I’ll ask questions about who the ideal reader is, what they already know, and what problems they have that this product will solve. Understanding how to write is important, but the words are just the final step in creating content that will move people to action.

Knowing what to leave out is as important as understanding what to explain. An experienced writer won’t feel the need to pad their content with extra words, or attempt to show how much they know by describing every detail. They will write just enough to take the reader to the endpoint already defined.

Can you fix this content for me?

Even before AI, writers have long been frustrated by people who don’t understand that the words are just the final stage of our work. We’ve all encountered people who assume we can drop in and make content that hasn’t been written with a real understanding of audience and purpose “good”. Generative AI means that people don’t even need to write the content they are foisting on weary technical writers, so there’s now a deluge of slop heading towards every technical writer with requests to “tidy it up”.

There’s been a lot of focus on AI “tells” in writing. These are very easy to deal with by ensuring your agent refers to a style guide, in particular for technical writing which tends to benefit from a strict adherence to a style guide. What is not easily fixable is when that content has been created without doing the research, without asking the right questions. Your AI tool can churn out words about what your product does, but unless you’ve already done all of the discovery work so you can provide that context to the agent, you’ll get a generic walkthrough.

Using AI in the wrong place

This isn’t an anti-AI post, you can use AI to help streamline many technical writing tasks. However, if you come from a starting point of assuming the job of a writer is to write words, you will ask the agent to write words. You will get words, probably a lot of them, and then you will wonder why you aren’t achieving your goals. You might reach out to a writer, who won’t have time to fix the problem as they will need to go back and do the needed research. Even if they do have time, you probably won’t have time to wait for the solution.

The most frustrating thing is that it’s the first part of the process where AI can be most helpful. It can help you answer questions, do research, and pull together data much faster than has been possible before. The part where I write words is such a small part of what I do, that there’s not huge efficiency gains to be had there. When I do generate content using AI, I find that the requirement to check it for accuracy negates any time saved during the writing part.

I don’t think this is a new problem, I think AI has highlighted it due to the speed that content can now be created. Perhaps we writers need to rebrand ourselves with a new job title. However, if I have any advice to wrap up with, it’s this: if you are lucky enough to work with writers, bring them in early and include them in the conversations about goals for the product. Listen to them when they tell you where AI is most useful in their work, and where it really is not. If you are using AI in your writing, concentrate more on the research and goal defining part of the work, rather than the word-generating part. That way you can ensure what you write, however you write it, works for your reader and what you want them to do or learn.

Read the whole story
alvinashcraft
just a second ago
reply
Pennsylvania, USA
Share this story
Delete

September 2026 Security Release

1 Share
The September 2026 security release for Next.js is now available
Read the whole story
alvinashcraft
15 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

What's new in Astro - September 2026

1 Share
September 2026 - Astro Germany, Evil Martians migration story, and more!
Read the whole story
alvinashcraft
51 seconds ago
reply
Pennsylvania, USA
Share this story
Delete

Are AI agents the new platform engineering customers?

1 Share

Disclaimer: This post was originally published on Azure with AJ and has been reproduced here with permission. You can find the original post here.

Over the past few months, something has shifted. I am spending more time creating agents and skills to handle my day-to-day work than I am writing code.

Actually, that is generous. I am spending almost no time writing code.

Somewhere along the way, I changed jobs without telling myself. I still solve engineering problems, but now I spend more time designing the thing that does the work than doing the work directly.

My first thought used to be, “I need to build something, and AI can help me write it.” Now it is, “Can I create or reuse a skill or agent that delivers the outcome?”

That is not just a developer habit either. I use agents to automate mundane tasks, accelerate Azure and GitHub assessments, support migrations, analyse estates and turn technical evidence into something an executive can actually use.

Which got me thinking about the core idea behind platform engineering: treat your platform as a product and your developers as customers.

If agents discover tools, call APIs, follow paved roads and produce outcomes on our behalf, are AI agents the new platform engineering customers?

I think they are.

They are not the only customers, and they are definitely not accountable ones, but they might be the most demanding consumers our platforms have ever seen. They are faster than any developer, more literal than any documentation writer imagined and completely unable to “just ask Dave” when the documentation stops making sense.

TL;DR

AI agents are becoming platform engineering customers. They consume the same APIs, templates, policies, documentation and deployment workflows as developers, only at machine speed and with a ruthlessly literal interpretation of whatever the platform exposes.

Platform teams need to design for both humans and agents. That means machine-consumable interfaces, explicit constraints, observable actions and approval points based on risk.

Humans still own intent, judgement and accountability. An agent can recommend an answer, but I need to be willing to put my name against it before anyone acts on it.

Why AI agents are platform engineering customers

Microsoft’s guide to platform engineering describes an internal developer platform as a set of secure, scalable and self-service capabilities that reduce cognitive load. Its guidance on  treating developers as customers makes the product mindset clear: build the platform around the needs of the people consuming it.

That model still holds. What has changed is who, or what, is standing at the counter.

A developer might browse a portal, write code and raise a pull request. An agent can make the same journey through a CLI, API, MCP server or repository workflow. It inspects the environment, chooses a paved road, generates the artefacts and puts the result in front of a human.

That sounds like the same customer journey with fewer coffee breaks, but there is an important difference.

Humans compensate for bad platforms. We infer what the author meant, connect to a corporate VPN to deploy to an environment and message support when none of it works.

An agent cannot fill those gaps with tribal knowledge and mild frustration.

AI agents need a different developer experience

We have spent years improving developer experience with portals, documentation and golden paths. Those things still matter. The difference is that an agent needs the same intent exposed in a form it can consume without guessing what we meant.

Agents are brutally honest users of documentation.

A developer can read “deploy using the standard pipeline” and know which pipeline that means. An agent will find three workflows called deploy, one archived wiki page and a YAML example last updated before Bicep had loops. Then it will make a choice with enormous confidence while you watch through your fingers.

Microsoft’s take on how AI coding agents use technology is worth a read. Agents depend on repository instructions, documentation, API descriptions, tools and their environment. If those inputs are vague, stale or contradictory, do not be surprised when the result is too.

For platform teams, four things matter:

1. Machine-consumable interfaces

Capabilities need stable APIs, CLIs, schemas and MCP tools, not knowledge hidden in somebody’s head.

2. Explicit golden paths

Preferred patterns must define when to use them, accepted inputs and good output. Microsoft’s guidance on paving optimal development paths applies equally to agents.

3. Guardrails close to execution

Policy, permissions, budgets and approvals must constrain the action itself. Telling an agent to “be secure” is not a security control.

4. Observable decisions

Show which tools were called, what changed and where human approval occurred.

A beautifully designed portal with an undocumented API works for people and frustrates agents. A powerful API with broad permissions and no audit trail works for agents and terrifies the organisation.

One gives you a droid standing outside the cantina. The other gives it the keys to the Death Star.

Neither is a particularly strong platform strategy.

My shift from writing code to designing capability

This is not abstract for me. It has already changed how I work.

Previously, I would open VS Code and start building. Now I usually stop and ask whether the thing in front of me is a one-off task or the first run of something I will have to do another twenty times.

My focus has moved from producing an artefact once to creating a reusable capability.

Instead of another assessment script, I think about an agent with the right sources, tools, questions and output. Instead of manually gathering migration evidence, I create a skill that collects it consistently and surfaces what needs human judgement. For executive narratives, an agent assembles the evidence into a first draft that I can challenge and refine.

Across Azure and GitHub, an agent can gather repository data, cloud configuration and policy findings in parallel. It gives engineers the detail and executives the decisions that matter.

That changes what platform engineering is actually for.

The platform team is no longer only curating Terraform modules, Bicep templates, pipelines and portals for developers. It is curating capabilities, context and controls for people and agents working side by side.

I explored versioning and governance in Agents as Code, and reusable skills in  Organising GitHub Copilot Customisations. Put those ideas together and the direction is difficult to ignore: agents are no longer visiting the platform, they are moving in.

The complacency trap

There is a part of this shift that does not get enough airtime.

AI makes the easy path dangerously easy. It produces a polished answer, the structure looks right, the language is confident and every instinct says LGTM.

When the result arrives faster than you could have created it yourself, accepting it feels like progress.

It’s a trap!

Human in the loop cannot mean somebody clicks approve at the end. It means actively testing the reasoning, checking the evidence, understanding the risk and deciding whether you are comfortable putting your name to the result.

I have had to ingrain a simple question into my own review process:

Am I willing to put my name against this outcome?

If the answer is no, the work is not done.

This matters even more beyond code. Tests might catch a questionable code change. They will not catch an assessment that misdirects investment or an executive summary that shapes the wrong decision.

The platform needs to make that review possible.

Preserve source links. Show assumptions. Separate evidence from inference. Make confidence visible. Require approval before high-impact actions. Give reviewers enough context to disagree instead of presenting a shiny answer and a green button.

A green tick is useful. It is not absolution.

Design the platform for two customers

The answer is not a second platform built just for agents. Nobody needs another portal or another backlog.

Make the existing platform clearer, safer and easier to compose, and humans benefit too.

Platform capabilityHuman customer needsAgent customer needs
DocumentationClear guidance and examplesStructured, current and discoverable context
Golden pathsLow-friction self-serviceDeterministic inputs, outputs and validation
ToolingHelpful portal and CLI experiencesStable APIs, schemas and scoped tools
GovernanceUnderstandable policies and approvalsEnforced permissions and explicit boundaries
ObservabilityStatus, logs and ownershipTraceable tool calls, context and decisions
FeedbackSupport channels and product researchEvaluation results, failures and correction loops

This is platform engineering doing what it has always promised: reducing cognitive load without removing responsibility.

If a human needs a meeting to learn the hidden process and an agent needs six retries to reverse engineer it, the problem is not either customer.

The paved road has a pothole large enough to lose an Imperial walker in it.

Microsoft’s Platform Engineering Capability Model helps teams assess their current practices and set goals across adoption, governance, provisioning, interfaces and feedback.

Agents raise the bar again.

If a capability cannot be discovered, understood and safely consumed without tribal knowledge, it is not ready for this new customer.

Where platform teams should start

Do not begin with a grand agent platform programme and a 47-slide strategy deck. I have seen how this film ends, and somehow there is always a steering committee in the third act.

Pick one valuable, repeatable journey and make it work end to end.

1. Choose a bounded use case

Evidence collection, repository onboarding and migration readiness are good candidates with definable outputs.

2. Expose the paved road

Provide the templates, APIs, instructions, examples and success criteria.

3. Constrain the tools

Grant only the required permissions and keep production changes behind approval.

4. Evaluate the outcome

Test accuracy, completeness, compliance and usefulness, not simply task completion.

5. Review with intent

Make the accountable human inspect evidence and assumptions.

6. Improve the platform

Treat failures as product feedback and fix the source.

Agents are relentless platform testers. They will find every undocumented dependency, inconsistent naming convention and vague instruction.

They will do it at speed, at scale and usually five minutes after you confidently announce the golden path is production ready.

It will be annoying.

It will also be some of the most honest product feedback your platform team will ever receive.

Conclusion: A new customer, not a new owner

AI agents consume platform capabilities, navigate golden paths and turn intent into action. They are fast, scalable and increasingly useful across Azure, GitHub and the wider business.

But they are not the owner of the outcome.

My mindset has shifted from writing code with AI assistance to designing agents and skills first. That has automated mundane work and improved assessments, migration plans and executive insights. It has also forced me to review more deliberately.

The easier an answer is to accept, the more important it is to ask whether I truly stand behind it.

Build platforms that agents can understand. Give them narrow, observable and well-governed paths.

Then keep humans exactly where they belong: setting intent, exercising judgement and owning the decision.

The droids can use the platform. They do not get a seat on the Jedi Council.

Are your AI agents already consuming your internal platform, and can you trace how they reached their decisions? Share what is working, and where the paved road still has potholes, in the comments.

Read the whole story
alvinashcraft
1 minute ago
reply
Pennsylvania, USA
Share this story
Delete

Assessing Your AI Needs

1 Share

Deciding on an AI solution starts with two factors: where the capability should live and how much freedom it needs while running. Use this guide to assess your needs.

An AI feature may need repeatable instructions or access to internal knowledge, and it may also need tool use or a multi-step workflow. Those requirements describe what the feature must do without settling how we should build and deliver it.

Teams often use skills and plugins interchangeably with hosted AI assistants and systems, and they may call the same AI capability an agent. These terms describe different parts of the design: how we package and deliver the capability as well as how much discretion it has at runtime.

In this article, we’ll evaluate these options by asking where the experience must live and what we want to reuse, then deciding what we would want to control and whether we can define the steps in advance.

Ownership & Runtime Behavior

Our first decision is about packaging and ownership: what we create and how people access it.

  • A skill packages instructions and supporting resources for a repeatable workflow.
  • A plugin packages skills and tools for distribution through a supported AI host.
  • A hosted AI assistant packages a configured conversational experience that people can use directly through an existing AI platform.
  • An AI system places the model inside an application we build and operate, giving us ownership of the interface and backend as well as data access and controls.

Runtime behavior is a separate decision about how much discretion the software needs while completing a task. Because runtime behavior is separate from packaging, these options can overlap within the same solution.

A system can load a skill that an agent follows, and a hosted AI assistant can use uploaded knowledge and tool connections within a product surface we don’t own.

OptionPrimary decision it answersStrong fitWhat we ownMain constraint
SkillHow do we reuse a method?A repeated workflow in an existing AI hostInstructions and supporting resourcesThe host still supplies the interface and runtime
PluginHow do we distribute skills and tools?An installable capability for a supported AI hostInstructions and tool connections; optional UIThe host still supplies the product surface and runtime
Hosted AI AssistantHow do we share a configured experience?An internal assistant or a quick pilot in an existing AI platformConfiguration and uploaded knowledge; conversation starters and connectionsThe host owns the product surface and runtime
SystemHow do we ship an AI capability in our product?A feature tied to product users and permissioned dataExperience and backend; permissions and operationsWe carry the engineering and operating cost
AgentHow should the software choose its next step?Work whose path changes as new information arrivesTools and limits; approval points and the execution loopGreater latency and cost with more failure paths

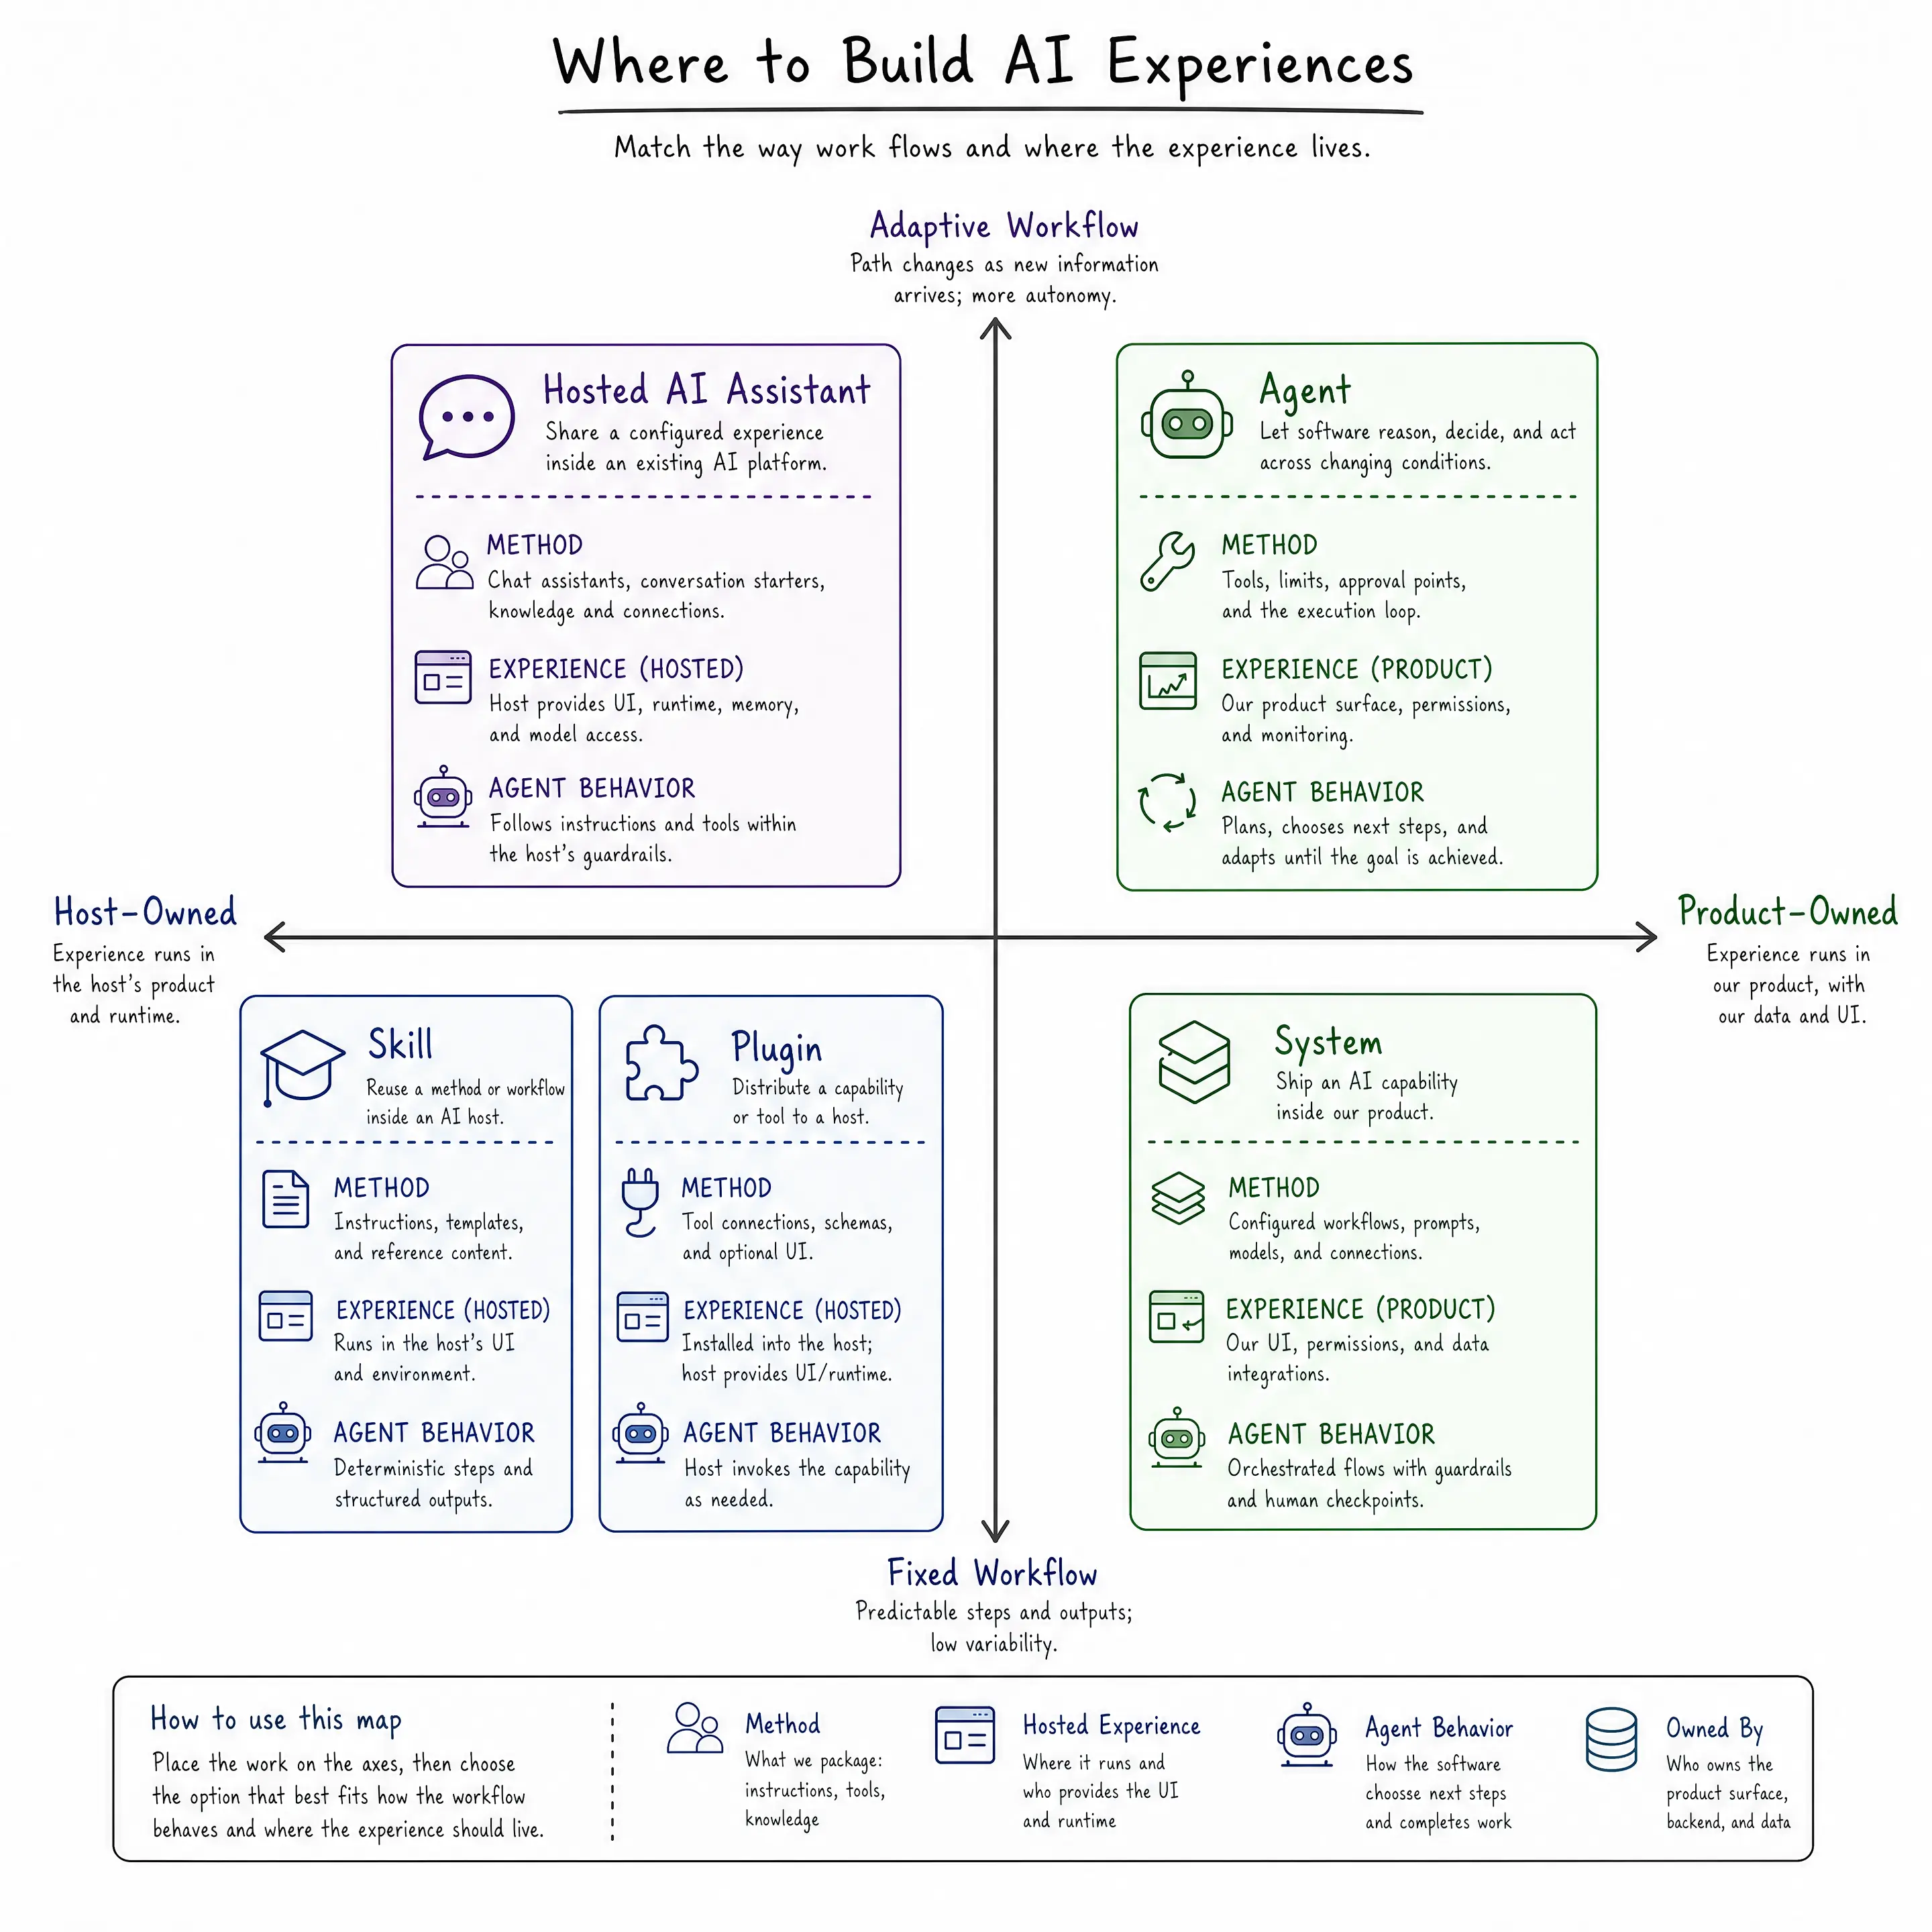
The diagram below maps these options across ownership and runtime behavior, showing where they can overlap within the same solution.

Diagram comparing ownership and runtime behavior across AI solution types

When a Skill Is Enough

A skill fits when the part we need to reuse is the procedure itself, such as a team’s method for summarizing pull requests into release notes or reviewing a component for accessibility. Without a shared procedure, we have to rewrite the instructions for each request, which wastes time and produces uneven results.

Skills can package instructions and references alongside scripts and templates, although the exact structure varies by host. If the workflow needs to be installed in a compatible AI platform, a plugin can distribute the skill with any tool connections required for external services or data.

When a Hosted AI Assistant Fits

A hosted AI assistant is well-suited when people need a shared conversational experience within an existing AI platform. Within that experience, we can configure instructions and reference files alongside capabilities and approved service connections.

For an onboarding assistant, the team can upload a handbook and set the expected tone before sharing the assistant in its workspace, creating a usable pilot without requiring a chat UI or model infrastructure.

The tradeoff is control because the provider runs the experience and its policies govern sharing and service connections. Once the capability becomes part of our application, our authentication model and release process become necessary, along with telemetry and support. Those requirements call for a system we operate.

When We Need a System

We need a system when the AI capability belongs to our product because our backend must authenticate the user and gather permissioned context before calling the model and validating its response. The interface becomes part of that boundary because it handles streaming and source citations alongside approvals and error states.

The surrounding components matter as much as the model call: retrieval keeps answers grounded in current content and guardrails block invalid actions. Evaluation checks whether changes improve the feature while observability records which sources and tools shaped a production response.

A billing assistant may need to explain a charge using account data and current policy. The feature must enforce the billing product’s access rules, and support engineers need a trace they can inspect when an answer is disputed. Even with one model call, a product-owned system keeps those checks and traces in code our team operates.

A system like this can remain deterministic: the billing assistant gathers the relevant policy and charge data before drafting an explanation, and plain application code orchestrates the known path with less variability than an agent loop would introduce.

When to Add Agent Behavior

Agent behavior becomes useful when we cannot specify the full path before the work starts. With agents, a task often has four characteristics:

  • The input describes an outcome for the software to complete.
  • The software must choose among tools or information sources.
  • An intermediate result can change the next step.
  • The workflow continues until it completes the task or reaches a stopping condition such as an approval checkpoint.

An incident investigation has this shape because the first log query may point toward a deployment or a third-party outage. As each result changes what the system should inspect next, an agent can select the next tool and evaluate the result before revising its plan.

This flexibility creates more work around the loop because tools need narrow permissions and validated inputs. Expensive or hard-to-reverse actions need approval checkpoints, and every run needs a decision trace and a stopping condition.

A Decision Sequence

To decide which option fits, we can work through the following questions in order, starting with product ownership and ending with runtime behavior.

  1. Where must the experience live? An existing AI host may already reach the intended users, so a reusable package or hosted AI assistant may be sufficient. An experience that belongs inside our application calls for a system we control.

  2. What are we trying to reuse? A repeatable procedure points to a skill, which can be packaged as a plugin if the procedure needs to be installed with tools. A configured conversational experience points to a hosted AI assistant.

  3. What must we control? A hosted AI assistant’s service connections remain within the host’s product and governance model. Product-owned authentication and permissioned customer data point toward a system, as do audit records and release management.

  4. Can we define the steps ahead of time? A known path belongs in normal application orchestration; a changing path that requires tool choice and recovery may justify agent behavior inside that system.

An AI system can include retrieval and memory as well as tools and evaluation without making every step adaptive. We can add a narrow agent only where an uncertain part of the workflow requires it.

How the Options Combine

A single capability may combine several options: a coding team can store its pull request review method as a skill and package that skill as a plugin when a wider group needs to install the workflow in a compatible AI platform.

A customer support feature can combine a chat interface with retrieval over permissioned documentation; tools can read account state and an evaluation set can cover common requests. Within that system, a skill can hold the support procedure, and agent behavior can handle the narrow investigative portion where each tool result may change the course of the work.

Wrap-up

Choosing an AI solution starts with two decisions: where the capability should live and how much freedom it needs while running.

A skill captures a repeatable method, and a plugin makes that method installable with tools. A hosted AI assistant delivers a configured experience through an existing platform, and a system gives us ownership of the product boundary. Both can support agent behavior when the route cannot be known in advance, allowing the software to choose and revise steps as the work progresses.

For more on building AI-powered applications and agents with Progress, check out the following resources:

Read the whole story
alvinashcraft
2 minutes ago
reply
Pennsylvania, USA
Share this story
Delete

Introducing DxTimingCaptureLibrary

1 Share

Today we released DxTimingCaptureLibrary, an open-source C++ library for DirectX developers. It is available on GitHub under the MIT license, and it works on all versions of Windows 10 and 11.

DxTimingCaptureLibrary makes it easier to understand DirectX ETW events and bring their rich information into tools such as in-engine game profilers.


What is DxTimingCaptureLibrary?

ETW (Event Tracing for Windows) is a Windows feature for collecting detailed system and application events with low overhead. DirectX components such as the D3D12 runtime, DXGI, and the DirectX kernel emit ETW events when important activity occurs.

DxTimingCaptureLibrary helps game developers interpret these events and turn them into actionable insights. It handles the complex work of interpreting and correlating ETW events from multiple sources, and then it makes simple callbacks into application code so that developers can use the information however they need.

The library includes samples that show how to configure ETW sessions and how to use DxTimingCaptureLibrary.

We created DxTimingCaptureLibrary by extracting code from PIX Timing Captures and moving it into a standalone project. All DirectX data shown in the PIX Timing Capture UI is available through DxTimingCaptureLibrary.


What can the library do?

The library exposes information such as:

  • GPU timing data.
    • Includes top-of-pipe and bottom-of-pipe timestamps for each command-list work item.
    • Timestamps are populated by the driver through D3D history buffers.
  • API object creation and destruction.
    • Includes timestamps, object size, parameters, and debug names.
  • Residency and paging events.
    • Shows when the DirectX kernel moves objects between video and system memory due to paging or eviction.
    • It also shows migration failures, for example due to VRAM fragmentation.
  • DirectStorage events.
    • Includes read and status requests.
  • D3D runtime failure logs.
  • Pipeline state compilation events.
  • Monitor VSync events.
  • WinPixEventRuntime events/markers on both the CPU and GPU timelines.
  • PIX custom counter data, via the WinPixEventRuntime counter APIs


How do I get started?

The README in the GitHub repository has the latest getting-started instructions. At a high level, you need to:

  1. Create and configure an ETW session with the appropriate DirectX ETW events.
    • The various samples (below) show how to do this.
  2. Configure the ETW session’s event handler to call DxTimingCaptureLibrary’s event handler.
  3. Implement any DxTimingCaptureLibrary callback interfaces that are relevant to your scenario.
  4. Wait for DxTimingCaptureLibrary to invoke your callbacks when the appropriate events occur.


What are the samples?

The library includes several samples:

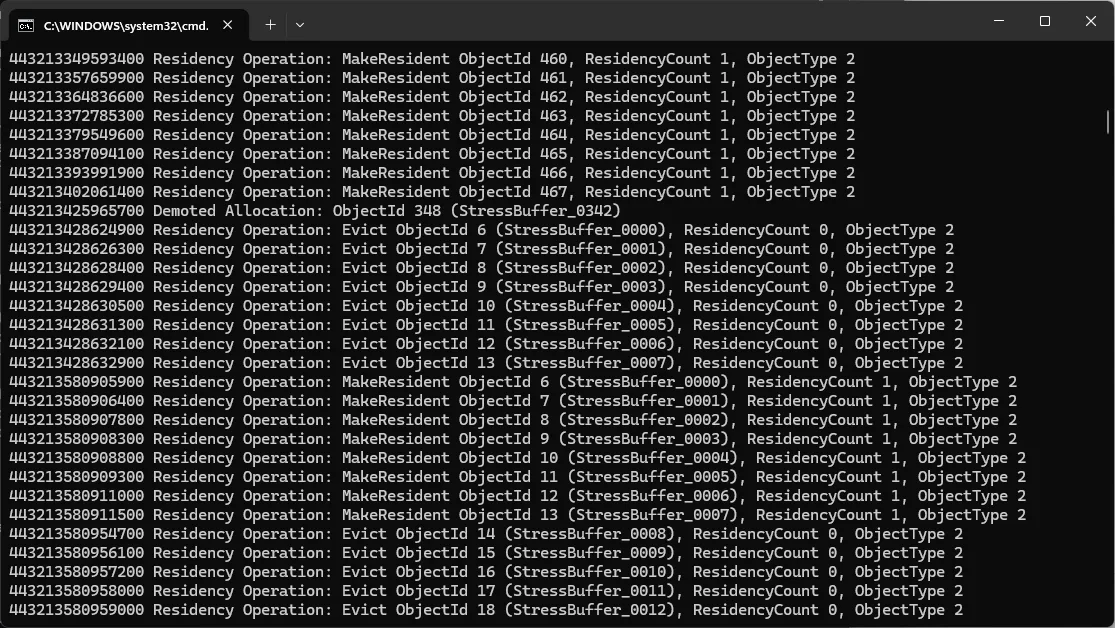
Basic Residency Logging: This barebones sample provides printf-based implementations of each DxTimingCaptureLibrary callback, which log event data to the console output window. It has an optional mode to only log DirectX residency/paging events, including MakeResident/Evict, Paging In/Out, and migration failures. This sample is a good place to get started with the library.

Command prompt window of the DxTimingCaptureLibrary sample


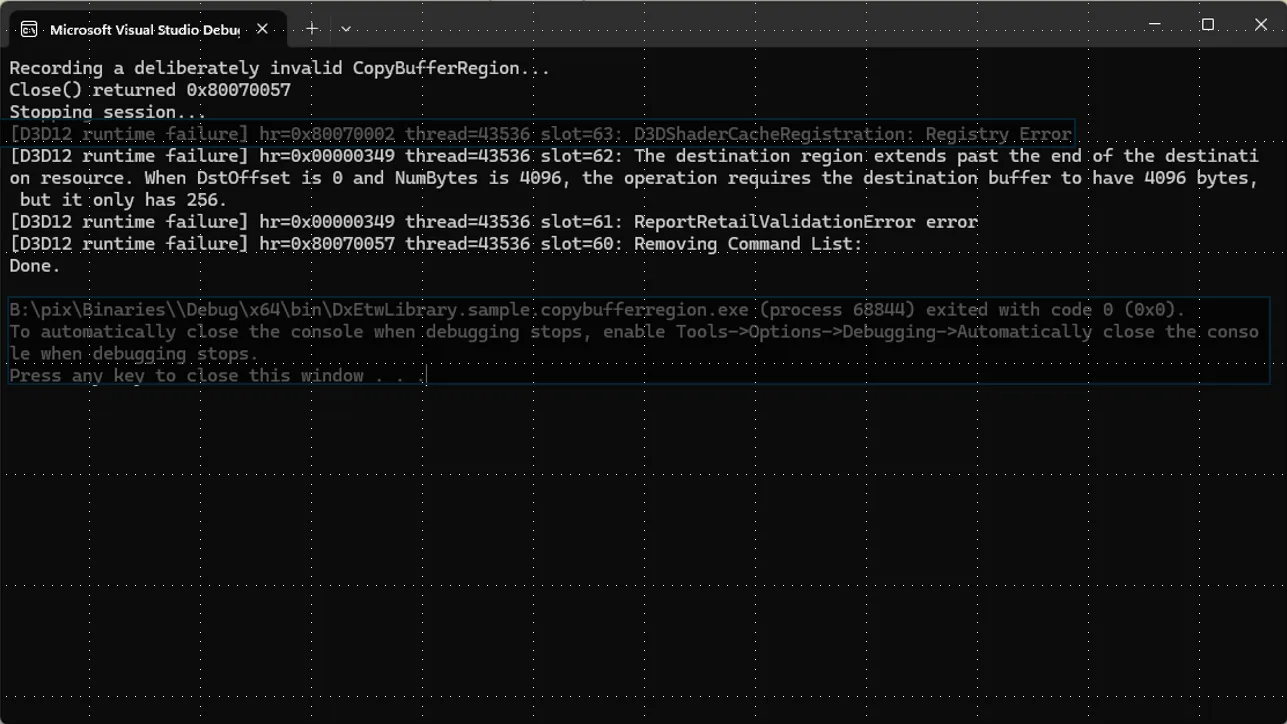
D3D12 Journal Entries: This sample implements the D3D12 Journal callbacks in DxTimingCaptureLibrary to receive a notification when an error occurs in D3D12 code. For example, the sample intentionally makes an invalid D3D12 API call by closing a command list that contains an invalid CopyBufferRegion() call. DxTimingCaptureLibrary reports this through the journal callback. The callback provides less detail than the D3D12 debug layer but it provides more detail than the regular D3D12 APIs – and it works in retail D3D12 environments!

Command prompt window of the DxTimingCaptureLibrary sample


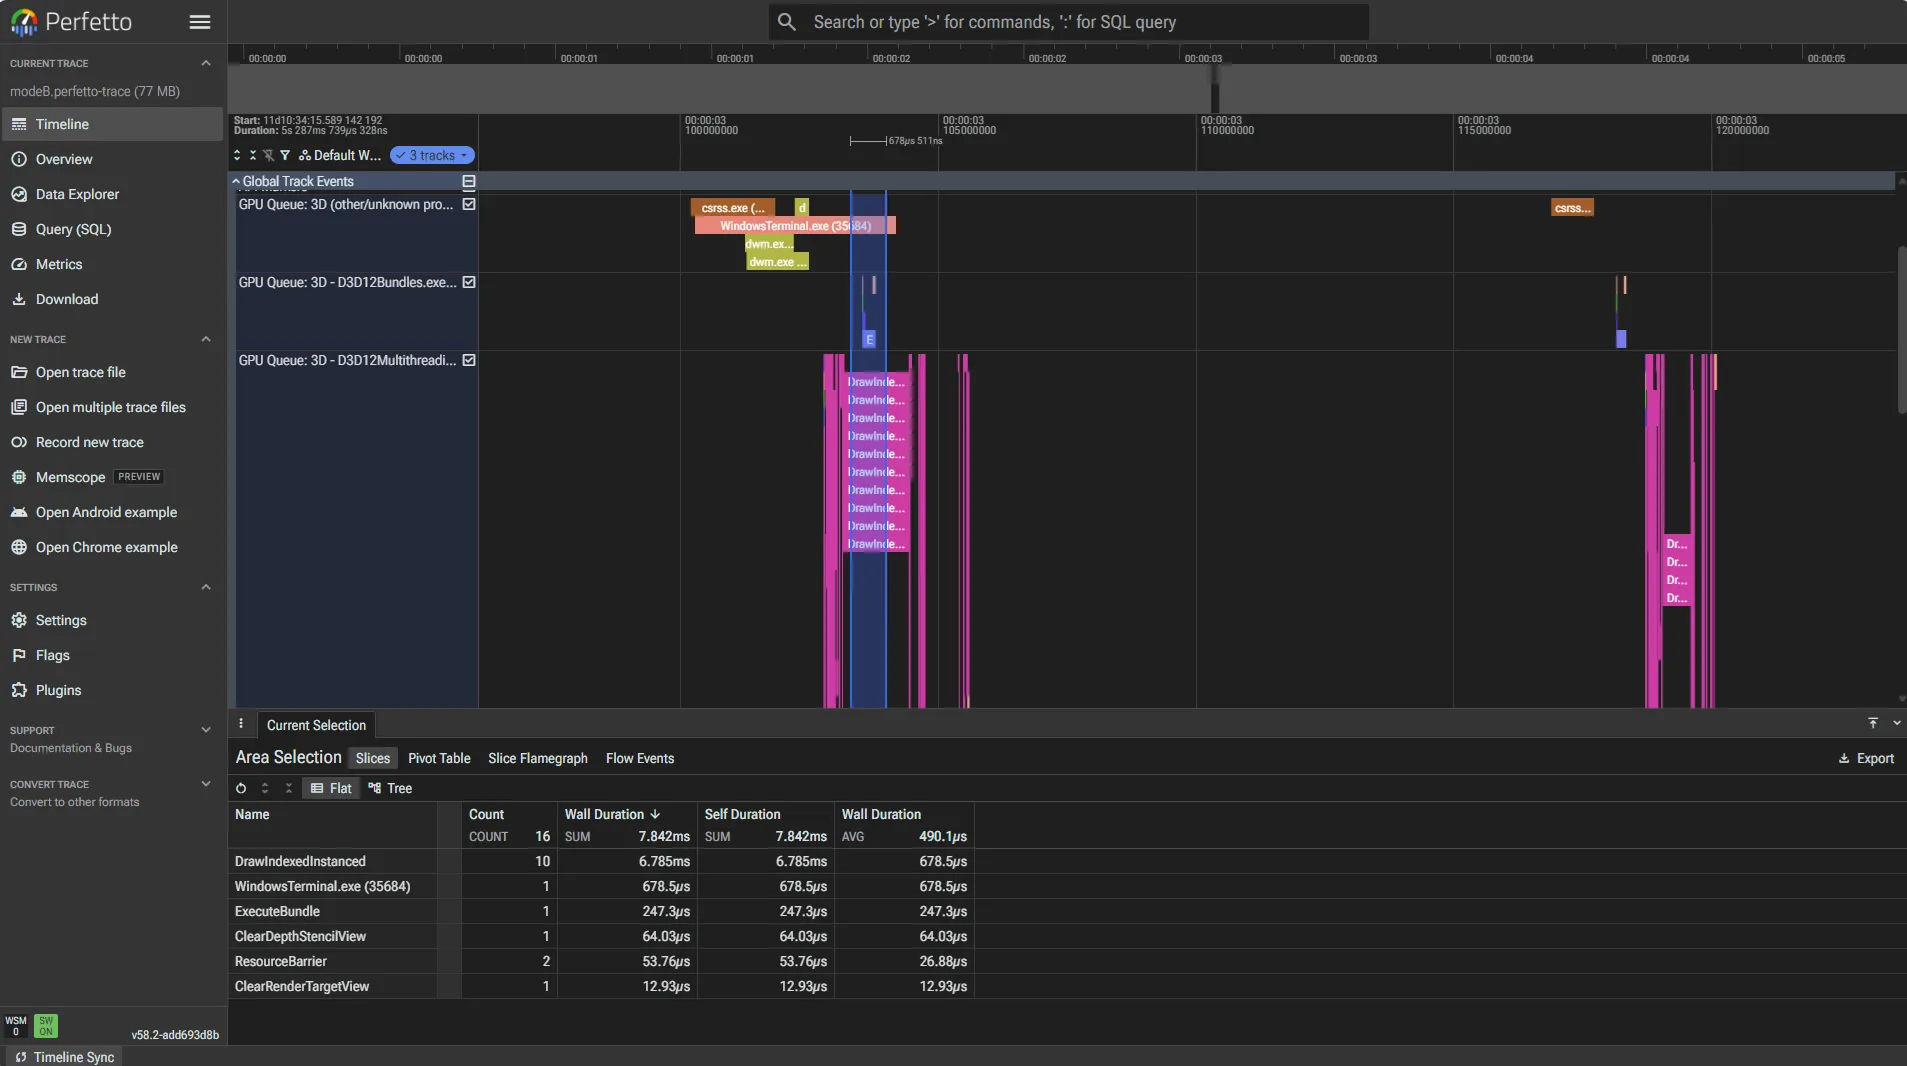
Perfetto: This sample implements the GPU timing data callbacks in DxTimingCaptureLibrary and uses them to generate a Perfetto trace file. The trace shows each command list event’s top-of-pipeline and end-of-pipeline timestamp on the GPU timeline, and it connects the data to a marker on the CPU timeline showing when the command list event was recorded. It also shows you other processes’ GPU work and how they might be interferring with your process.

perfetto sample image
Perfetto Sample Screenshot


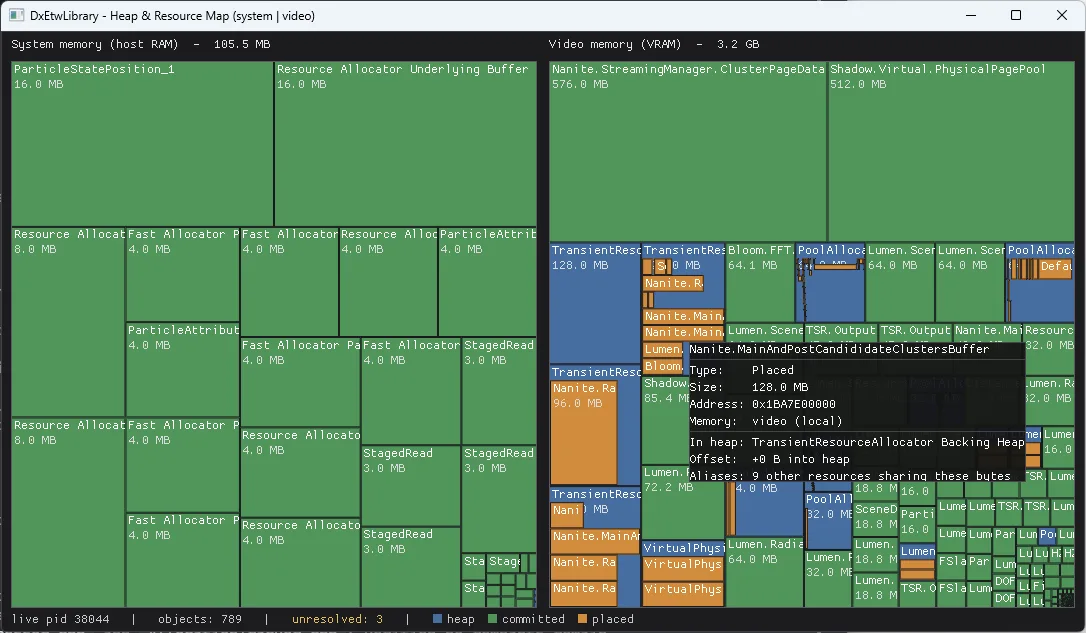
Memory Treemap: (work in progress) This sample listens to the resource creation and residency event callbacks in DxTimingCaptureLibrary. It uses that data to populate two treemaps showing resource and heap usage in system memory and video memory, while taking paging and residency events into account.

Screenshot of the DxTimingCaptureLibrary sample


The post Introducing DxTimingCaptureLibrary appeared first on DirectX Developer Blog.

Read the whole story
alvinashcraft
2 minutes ago
reply
Pennsylvania, USA
Share this story
Delete
Next Page of Stories